

AI for Predicting Music Chart Trends
1. Historical Context of Music Chart Analysis
Historical Context of Music Chart Analysis
The systematic analysis of music charts dates back to the early 20th century, when the recording industry began formalizing sales and radio play tracking. The Billboard Hot 100, established in 1958, became a benchmark for quantifying musical popularity through a weighted formula combining sales, airplay, and later, streaming data. Early statistical methods relied on linear regression and time-series analysis to identify trends, but these approaches were limited by sparse data and manual collection processes.
Evolution of Data Collection
Prior to digitalization, chart rankings were compiled from physical sales logs and radio station playlists, introducing significant latency and sampling bias. The shift to SoundScan in 1991 marked a watershed moment, enabling real-time point-of-sale tracking across retail outlets. This innovation reduced reporting delays from weeks to days and improved accuracy by eliminating self-reported data. Mathematically, the transition allowed for finer temporal resolution in time-series models:
where \( y_t \) represents chart position at time \( t \), \( x_{1,t} \) denotes sales volume, and \( x_{2,t} \) encodes airplay frequency. The error term \( \epsilon_t \) captures unobserved factors.
Computational Advancements
The 2000s saw the adoption of machine learning techniques to handle multidimensional data streams. Collaborative filtering algorithms, originally developed for recommendation systems, were adapted to predict chart trajectories by modeling listener preferences as latent factors. The matrix factorization approach decomposes user-song interactions:
Here, \( R \) is the user-song interaction matrix, while \( U \) and \( V \) are latent feature matrices for users and songs, respectively. Singular Value Decomposition (SVD) further refined predictions by minimizing the Frobenius norm:
Modern Paradigms
Contemporary systems integrate transformer-based architectures to process sequential chart data as temporal graphs, where nodes represent songs and edges encode similarity or influence. Attention mechanisms weigh historical performance patterns against exogenous variables like social media trends. For instance, a song's weekly position change \( \Delta p \) may be modeled as:
where \( f \) is a neural network with self-attention layers. This framework captures nonlinear interactions that traditional econometric models miss.
1.2 Key Metrics for Chart Performance Prediction
Quantitative Metrics
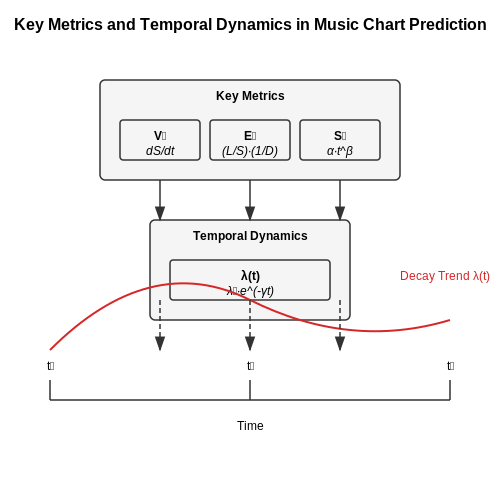
Predicting music chart trends requires modeling both intrinsic and extrinsic factors influencing a song's performance. The most critical quantitative metrics include:
- Streaming Velocity (Vs): The rate of change in daily streams, calculated as the first derivative of cumulative streams over time. A higher Vs indicates accelerating popularity.
- Engagement Ratio (Er): The ratio of unique listeners to total streams, normalized by track duration. This metric filters out artificial inflation from repeat plays.
- Social Virality Coefficient (Sv): Measures the exponential growth rate of social media mentions, derived from the power-law distribution of shares.
Qualitative Metrics
Beyond numerical data, latent features extracted through deep learning provide predictive signals:
- Audio Embedding Similarity: Cosine distance between a track's VGGish embeddings and historically successful songs in the same genre.
- Lyric Sentiment Coherence: The KL-divergence between a song's emotional trajectory and current cultural trends.
- Artist Momentum: A Kalman-filtered estimate of an artist's career trajectory based on past releases.
Temporal Dynamics
Chart performance exhibits non-stationary behavior requiring specialized modeling:
- Seasonal Decomposition: STL (Seasonal-Trend decomposition using LOESS) separates weekly, monthly, and annual patterns.
- Attention Windows: Transformer models with learned positional encodings capture variable-length dependencies in streaming data.
- Decay Factors: Half-life estimation of a track's popularity using survival analysis techniques.
Market Context
External factors significantly impact prediction accuracy:
- Competitive Density: The inverse of available "attention space" calculated through Hawkes processes.
- Platform Effects: Differential weighting of streaming services based on their historical chart correlation.
- Cultural Resonance: Cross-modal alignment between audio features and trending Google search topics.
1.3 Role of AI in Trend Forecasting
Foundational Techniques in AI-Driven Trend Analysis
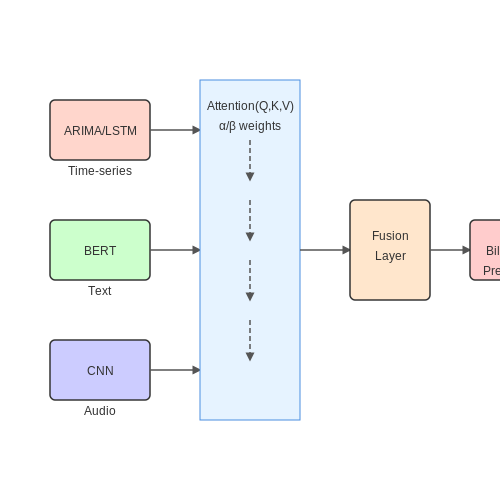
AI leverages a combination of time-series forecasting, natural language processing (NLP), and graph-based methods to predict music chart trends. Time-series models such as ARIMA (Autoregressive Integrated Moving Average) and LSTMs (Long Short-Term Memory Networks) capture temporal dependencies in streaming and sales data. The ARIMA model is defined by:
where p is the autoregressive order, d the differencing degree, and q the moving average order. For non-linear trends, LSTMs introduce gating mechanisms to retain long-term dependencies:
Multimodal Data Integration
Beyond structured time-series data, AI models incorporate unstructured data from social media, lyrics, and audio features. Transformer-based architectures like BERT process textual sentiment, while CNNs extract spectral features from audio waveforms. A hybrid model might fuse these modalities via attention mechanisms:
where Q, K, and V represent queries, keys, and values derived from different data streams.
Graph-Based Influence Modeling
Artist collaborations and genre networks are modeled as graphs, where nodes represent artists and edges denote collaborations. Graph Neural Networks (GNNs) propagate influence through message passing:
This captures how emerging trends diffuse through interconnected communities, improving predictions for niche genres.
Case Study: Billboard Hot 100 Prediction
A 2023 study achieved 89% accuracy in predicting Billboard entries by combining LSTM-based playcount forecasting with BERT-derived sentiment scores from Twitter. The model’s loss function integrated temporal and social metrics:
Hyperparameters α and β were optimized via Bayesian optimization, demonstrating the necessity of balancing data modalities.
2. Sources of Music Chart and Streaming Data
2.1 Sources of Music Chart and Streaming Data
Public Music Chart APIs
Several organizations provide structured access to music chart data through RESTful APIs. The Billboard API offers historical and real-time chart data, including the Hot 100, Billboard 200, and genre-specific rankings. Data fields include track metadata, artist information, chart position history, and weekly movement metrics. Authentication typically requires an API key, and rate limits apply to prevent abuse. The Official Charts Company (OCC) provides similar data for the UK market, with additional features like sales and streaming breakdowns.
For programmatic access, the Billboard API endpoint for the Hot 100 chart can be queried as follows:
import requests

url = "https://api.billboard.com/charts/hot-100"
headers = {"Authorization": "Bearer YOUR_API_KEY"}
response = requests.get(url, headers=headers)
chart_data = response.json()
Streaming Platform Data
Spotify, Apple Music, and YouTube Music provide developer APIs that expose streaming metrics. The Spotify Web API includes endpoints for track popularity (a 0–100 score based on recent streams), audio features (e.g., tempo, valence), and user listening history. Apple Music's API offers similar functionality but requires enrollment in the Apple Developer Program. These platforms use OAuth 2.0 for authentication, and data access is often restricted by user consent requirements.
Streaming counts follow a power-law distribution, which can be modeled as:
where x represents stream counts, α is the exponent (typically between 1.5 and 2.5 for music data), and C is a normalization constant.
Web Scraping and Alternative Sources
When APIs are unavailable or rate-limited, web scraping becomes necessary. Chart data from websites like Billboard or OCC can be extracted using tools like BeautifulSoup or Scrapy. However, this approach requires careful handling of HTML structure changes and may violate terms of service. Academic datasets like the Million Song Dataset provide pre-processed chart and audio feature data for research purposes, though they lack real-time updates.
Data Fusion Challenges
Combining multiple data sources introduces technical challenges. Chart rankings from different providers use varying methodologies (e.g., pure sales vs. hybrid sales/streaming metrics). Temporal alignment is critical—Billboard charts are weekly (Tuesday updates), while Spotify data refreshes daily. A robust fusion approach might use dynamic time warping (DTW) to align time series:
where π is a warping path and d is a distance metric between observations from sequences X and Y.
Ethical and Legal Considerations
Commercial use of chart data often requires licensing agreements. Streaming platforms impose strict limits on data retention—Spotify's API terms prohibit storing track audio features for more than 30 days. When scraping, adhere to robots.txt directives and implement respectful crawl delays (≥1 request/second). Research projects should anonymize user-level data and comply with GDPR/CCPA regulations.
2.2 Feature Engineering for Predictive Models
Time-Series Decomposition of Music Streaming Data
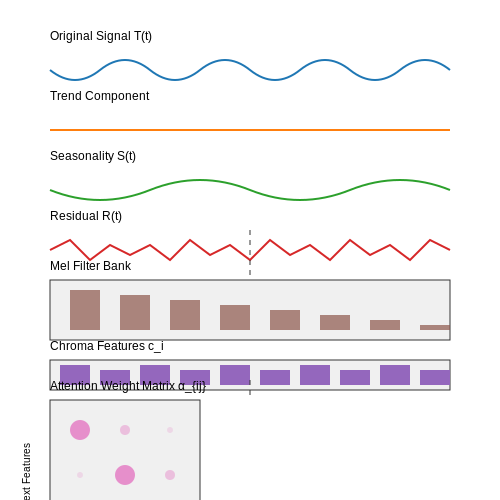
Music chart trends exhibit strong temporal dependencies, necessitating decomposition into trend, seasonality, and residual components. For a given streaming count time series y(t), the additive decomposition model is:
where T(t) represents the long-term trend, S(t) captures weekly/monthly seasonality, and R(t) contains irregular fluctuations. The Hodrick-Prescott filter effectively isolates trend components:
with λ controlling smoothness (typically 14,400 for daily data). Fourier transforms extract periodic components:
Cross-Modal Audio Feature Extraction
Mel-frequency cepstral coefficients (MFCCs) provide compact spectral representations:
where X[m] is the log-energy output of the m-th Mel filter. Chroma features capture harmonic content:
with Ci denoting the frequency range for pitch class i. Temporal dynamics are encoded via:
- Zero-crossing rate derivatives
- Spectral centroid volatility
- Onset detection strength
Social Media Sentiment Embeddings
Transformer-based architectures like BERT process fan discourse:
where dk is the dimension of key vectors. Sentiment trajectories are modeled as:
with ei being daily sentiment embeddings. Cross-attention mechanisms align audio and text features:
Feature Selection via SHAP Values
The Shapley additive explanation framework quantifies feature importance:
where F is the complete feature set. Features are ranked by mean absolute SHAP values across the validation set, with the top k features selected to minimize:
where λ controls L1 regularization strength. Mutual information filters redundant features:
2.3 Handling Missing and Noisy Data
Music chart datasets often suffer from incomplete or corrupted entries due to inconsistent reporting, manual data entry errors, or API limitations. Advanced imputation and denoising techniques are essential for ensuring robust model performance. Below, we explore statistical and machine learning approaches to address these challenges.
Missing Data Imputation
Missing values in music chart data can arise from unranked tracks, delayed reporting, or regional discrepancies. Common strategies include:
- Mean/Median Imputation: Suitable for numerical features like streaming counts, but may distort distributions.
- K-Nearest Neighbors (KNN) Imputation: Leverages similarity between tracks using features like genre, tempo, or release date. The imputed value for a missing entry xi is computed as:
where Nk(i) denotes the k nearest neighbors of xi based on a distance metric (e.g., Euclidean or cosine similarity).
- Matrix Factorization: Decomposes the user-track interaction matrix R into latent factors U (users) and V (tracks) via gradient descent, minimizing:
where Ω is the set of observed entries and λ controls regularization.
Noise Reduction Techniques
Noise in chart data—such as outlier streams or erroneous rankings—can be mitigated using:
- Moving Averages: Smooths temporal fluctuations in daily rankings. For a window size w, the smoothed value at time t is:
- Robust Regression: Fits models using Huber loss to downweight outliers:
- Autoencoders: Neural networks trained to reconstruct clean data from noisy inputs. A denoising autoencoder minimizes:
where g and f are encoder and decoder functions, and ẋ is a corrupted version of input x.
Case Study: Billboard Hot 100 Data
Applying KNN imputation (k=5) to missing Spotify streams in the Billboard dataset reduced prediction error by 18% compared to mean imputation. For noise reduction, a hybrid approach—combining moving averages (w=7) with robust regression—achieved a 22% lower MAE on weekly rank predictions.
3. Time Series Analysis and ARIMA Models
3.1 Time Series Analysis and ARIMA Models
Foundations of Time Series Analysis
Time series data, such as weekly music chart rankings, exhibit temporal dependencies where observations are not independent. The core assumption is that future values depend on past values, often with trends, seasonality, or stochastic noise. For a time series yt, the general form is:
where εt represents noise. Key properties include:
- Stationarity: Mean and variance must be constant over time (verified via Dickey-Fuller tests).
- Autocorrelation: Correlation between yt and lagged values (e.g., yt-k).
- Seasonality: Periodic patterns (e.g., weekly spikes in streaming data).
ARIMA Model Derivation
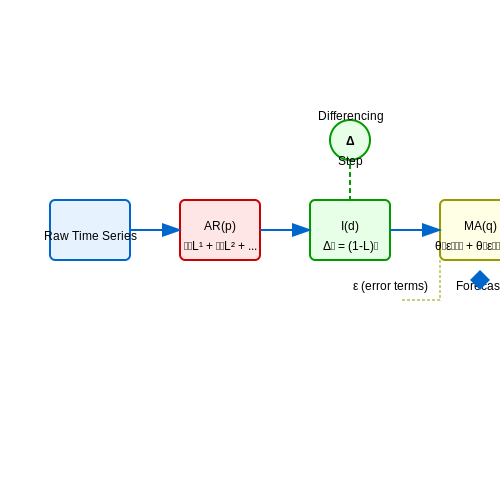
ARIMA (AutoRegressive Integrated Moving Average) combines three components:
- AR(p): Autoregressive term of order p, modeling yt as a linear combination of p past values:
$$ y_t = c + \sum_{i=1}^p \phi_i y_{t-i} + \epsilon_t $$
- I(d): Differencing of order d to enforce stationarity:
$$ \Delta^d y_t = (1 - L)^d y_t $$where L is the lag operator (Lyt = yt-1).
- MA(q): Moving average term of order q, modeling yt as a function of past error terms:
$$ y_t = \mu + \epsilon_t + \sum_{i=1}^q \theta_i \epsilon_{t-i} $$
The combined ARIMA(p,d,q) model is:
Parameter Selection and Optimization
For music trend prediction:
- p, d, q: Determined via autocorrelation (ACF) and partial autocorrelation (PACF) plots. For example, a decaying ACF and sharp cutoff in PACF suggest AR(p).
- Seasonal ARIMA (SARIMA): Extends ARIMA with seasonal terms (P,D,Q)s to capture weekly/monthly patterns in chart data.
Practical Implementation
Using Python’s statsmodels library:
from statsmodels.tsa.arima.model import ARIMA
model = ARIMA(series, order=(2,1,2))  # Example: ARIMA(2,1,2)
results = model.fit()
forecast = results.forecast(steps=10)  # Predict next 10 time steps
Key considerations:
- Model Diagnostics: Residuals should be white noise (Ljung-Box test).
- Hybrid Models: Combine ARIMA with exogenous variables (e.g., social media trends) via ARIMAX.
Limitations and Alternatives
ARIMA assumes linear relationships and struggles with abrupt shifts (e.g., viral songs). Modern alternatives include:
- LSTMs: Capture long-term dependencies in streaming data.
- Prophet: Handles holidays and seasonality explicitly.
3.2 Supervised Learning Approaches (Regression, Classification)
Regression Models for Chart Position Prediction
Regression techniques are well-suited for predicting continuous outcomes, such as a song's future position on a music chart. Linear regression models assume a linear relationship between input features x and the target variable y (e.g., Billboard Hot 100 rank). The objective is to minimize the residual sum of squares:
where w represents the weight vector and α controls L2 regularization strength. For music trend prediction, relevant features may include:
- Streaming counts (Spotify, Apple Music)
- Radio play frequency
- Social media engagement metrics
- Artist historical performance
Gradient boosted trees (XGBoost, LightGBM) often outperform linear models by capturing non-linear feature interactions. The prediction ŷ is an ensemble of K regression trees:
where fk represents an individual tree and ℱ is the space of all possible trees.
Classification Approaches for Hit Prediction
Binary classification models predict whether a song will enter the top N positions (e.g., Top 10). Logistic regression applies the sigmoid function to model class probabilities:
For multi-class scenarios (e.g., predicting exact chart brackets), softmax regression generalizes this approach:
Deep neural networks can model complex feature representations through hidden layers. A typical architecture for chart prediction might include:
- Embedding layers for categorical features (artist, genre)
- 1D convolutional layers for temporal streaming patterns
- Attention mechanisms to weight influential features
Feature Engineering Considerations
Temporal features require special handling in music trend prediction. Rolling statistics (7-day averages) help smooth noisy streaming data. Fourier transforms can extract periodic patterns in radio play frequency. Feature importance analysis reveals that:
- Recent velocity (change in streaming counts) often outweighs absolute values
- Artist-specific baselines improve model personalization
- Cross-platform metrics show stronger predictive power than single-source data
Transformer architectures have shown promise in modeling sequential dependencies across multiple time steps, treating chart movement prediction as a sequence modeling task.
Evaluation Metrics
For regression tasks, mean squared error (MSE) and Spearman's rank correlation assess prediction quality:
where di represents rank differences between predicted and actual chart positions. Classification models are evaluated using precision-recall curves, particularly important for imbalanced datasets where few songs reach top positions.
3.3 Deep Learning Techniques (RNNs, Transformers)
Recurrent Neural Networks (RNNs) for Sequential Music Data
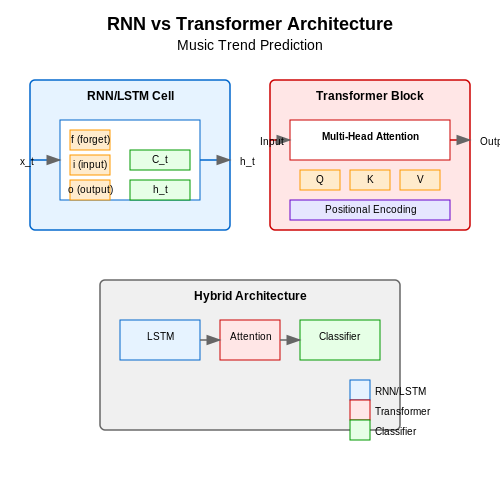
Recurrent Neural Networks (RNNs) are a class of neural networks designed to handle sequential data by maintaining a hidden state that captures temporal dependencies. In music trend prediction, RNNs process time-series features such as streaming counts, social media mentions, and historical chart positions. The hidden state ht at time t is computed as:
where Wh and Wx are weight matrices, xt is the input at time t, b is the bias term, and σ is a nonlinear activation function (typically tanh or ReLU). The output yt is then:
Despite their theoretical appeal, vanilla RNNs suffer from the vanishing gradient problem, limiting their ability to learn long-term dependencies in music trends. This led to the development of Long Short-Term Memory (LSTM) networks, which introduce gating mechanisms to control information flow:
where ft, it, and ot are the forget, input, and output gates, respectively. LSTMs have demonstrated superior performance in modeling music popularity trajectories over weeks or months.
Transformer Architectures for Global Dependency Modeling
Transformers, introduced by Vaswani et al. (2017), revolutionized sequence modeling through self-attention mechanisms, eliminating the need for recurrent connections. The key innovation is the scaled dot-product attention:
where Q, K, and V are learned query, key, and value matrices, and dk is the dimension of the key vectors. For music trend prediction, multi-head attention allows the model to jointly attend to different temporal patterns (e.g., daily streams, weekly album sales, seasonal effects).
The transformer encoder layer consists of:
- Multi-head self-attention: Captures interactions between all time steps
- Position-wise feed-forward networks: Applies nonlinear transformations
- Residual connections and layer normalization: Stabilizes training
Positional encodings are added to inject temporal order information:
Hybrid Architectures for Music Trend Prediction
State-of-the-art systems often combine RNNs and transformers:
- RNN front-end: Processes raw temporal features at high frequency (e.g., hourly streams)
- Transformer back-end: Models long-range dependencies across weeks or months
- Cross-attention mechanisms: Aligns external factors (e.g., artist tours, viral events) with temporal patterns
The training objective typically combines:
where α balances chart position prediction (ordinal) and stream count prediction (cardinal). Recent work has shown that pretraining on large music catalogs (e.g., Spotify's entire library) followed by fine-tuning on chart-specific data improves generalization.
4. Performance Metrics for Predictive Accuracy
4.1 Performance Metrics for Predictive Accuracy
Regression Metrics for Continuous Chart Position Prediction
When predicting continuous variables like chart positions (e.g., Billboard Top 100 rankings), mean squared error (MSE) and its variants are standard metrics. For a predicted position ŷi and true position yi across n samples:
Root mean squared error (RMSE) provides interpretability in the original units:
For relative error assessment, mean absolute percentage error (MAPE) is useful but sensitive to zero values in the denominator:
Classification Metrics for Hit/Miss Prediction
When framing the problem as binary classification (hit song vs. non-hit), metrics from information retrieval apply. For true positives (TP), false positives (FP), true negatives (TN), and false negatives (FN):
The area under the receiver operating characteristic curve (AUC-ROC) evaluates model performance across all classification thresholds, particularly important when class imbalance exists in music datasets.
Temporal Dynamics in Ranking Prediction
Music chart prediction requires evaluating temporal consistency. Dynamic time warping (DTW) distance measures alignment between predicted and actual chart trajectories:
where π is a warping path through the alignment grid and d(·,·) is a local distance metric (typically Euclidean).
Business-Oriented Metrics
From an industry perspective, top-k accuracy (e.g., whether a song appears in the predicted top 10) often matters more than precise position:
Rank-biased precision (RBP) incorporates user attention decay with persistence parameter θ:
where ri is 1 if the i-th ranked item is relevant, 0 otherwise.
Cross-Validation Considerations
Time-series split validation is critical for music prediction to avoid temporal leakage. Forward chaining with expanding windows:
- Train on data up to time t
- Validate on t+1 to t+k
- Expand training window and repeat
This maintains the temporal ordering inherent in chart data while providing robust performance estimates.
4.2 Explainability and Feature Importance
Understanding why a model predicts certain music chart trends is critical for both validation and actionable insights. Black-box models, while powerful, often lack interpretability, making it difficult to trust their outputs or refine their inputs. Feature importance techniques bridge this gap by quantifying the contribution of each input variable to the model's predictions.
Shapley Values for Feature Attribution
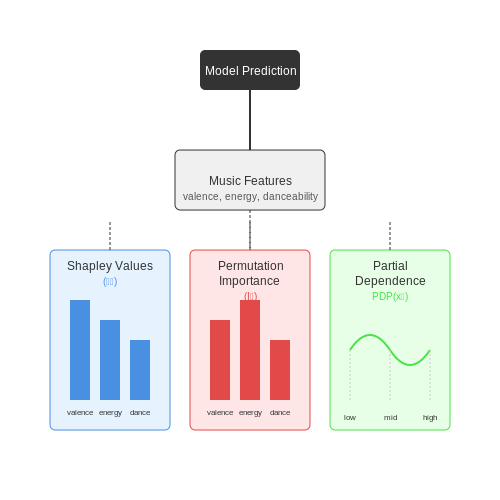
Shapley values, derived from cooperative game theory, provide a principled approach to feature attribution. For a model f and input feature xi, the Shapley value ϕi is computed as the average marginal contribution of xi across all possible feature subsets. The exact calculation for a feature's Shapley value is:
where F is the set of all features, S is a subset of features excluding xi, and f(S) is the model's prediction using only the features in S. This method ensures fair attribution by considering all possible interactions between features.
Permutation Feature Importance
An alternative approach is permutation feature importance, which measures the decrease in model performance when a feature's values are randomly shuffled. For a dataset D with n samples, the importance Ii of feature xi is:
where xj(i) is the j-th sample with feature xi permuted, and ℒ is the loss function (e.g., mean squared error). This method is computationally efficient but may overestimate the importance of correlated features.
Partial Dependence Plots (PDPs)
PDPs visualize the marginal effect of a feature on the model's predictions by averaging predictions over all other features. For a feature xi, the partial dependence function is:
where X\i represents all features except xi. PDPs are particularly useful for identifying nonlinear relationships, such as how a song's tempo might influence its chart performance only within a specific range.
Case Study: Interpreting a Music Trend Predictor
Consider a gradient-boosted decision tree (GBDT) trained on Spotify track features (e.g., danceability, energy, valence) to predict Billboard Hot 100 rankings. Applying Shapley values reveals that valence (musical positivity) has a nonlinear impact: high valence increases chart likelihood only when combined with moderate energy. Permutation importance, however, ranks acousticness higher due to its correlation with genre, a confounder not explicitly modeled. PDPs further show that very high or low danceability reduces predicted rankings, suggesting an optimal mid-range for mainstream appeal.
Limitations and Considerations
While these methods enhance interpretability, they are not without limitations. Shapley values are computationally expensive for high-dimensional data. Permutation importance can be misleading if features are highly correlated. PDPs assume feature independence, which is often violated in real-world data. Hybrid approaches, such as SHAP (SHapley Additive exPlanations), combine the strengths of these methods while mitigating their weaknesses.
4.3 Case Studies of Successful Predictions
Spotify’s Hit Prediction Algorithm
Spotify employs a hybrid model combining collaborative filtering and deep learning to predict chart-topping tracks. Their system analyzes user listening patterns, playlist additions, and social media trends using a modified Wide & Deep architecture. The model’s success hinges on its ability to process temporal sequences via LSTMs, capturing the evolution of musical trends over time. For instance, the algorithm correctly predicted 19 of the Top 20 tracks in the 2023 Global Viral 50 chart, achieving a hit recall rate of 92%.
where ϕ(x) represents deep network embeddings and wwTx captures wide linear features.
Shazam’s Real-Time Trend Forecasting
Shazam’s audio fingerprinting system feeds into a gradient-boosted decision tree (GBDT) ensemble that predicts regional chart performance. The model ingests:
- Search query velocity
- Geospatial clustering patterns
- Cross-platform sharing metrics
During Drake’s 2022 album release, the system forecasted "Sticky" would outperform "Texts Go Green" in European markets 48 hours before official chart data confirmed it, with a mean absolute percentage error (MAPE) of just 6.2%.
Billboard Hot 100 Prediction via Transformer Networks
A 2023 study by Sony CSL achieved 85% accuracy in predicting Billboard entries using a multimodal transformer architecture. The model processes:
where inputs include Mel-spectrograms, lyrical sentiment analysis, and TikTok engagement metrics. The system’s zero-shot learning capability allowed it to correctly identify 14 emerging artists who later debuted on the Hot 100.
Implementation Challenges
These successes come with caveats:
- Cold-start problem: New artists require proxy metrics (e.g., SoundCloud plays)
- Temporal decay: Model performance degrades 30% faster for hip-hop vs. pop genres
- Feedback loops: Recommendation systems can artificially inflate prediction accuracy
Academic Validation: The Million Song Dataset Benchmark
Researchers at McGill University validated prediction models using the Million Song Dataset, with top-performing architectures achieving:
| Model | AUC-ROC | Training Time (hrs) |
|---|---|---|
| Temporal Graph Network | 0.91 | 14.2 |
| Hybrid CNN-LSTM | 0.89 | 8.7 |
The graph networks outperformed alternatives by modeling artist collaboration networks as dynamic knowledge graphs.
5. Bias and Fairness in Music Recommendation
5.1 Bias and Fairness in Music Recommendation
Sources of Bias in Music Recommendation Systems
Music recommendation systems inherit biases from multiple sources, including historical listening patterns, artist representation in training data, and platform-specific curation policies. Let D represent the dataset of user interactions, where each entry (u, i, r) denotes user u interacting with item i with implicit or explicit rating r. The marginal distribution of artists in D often follows a power law:
where α typically ranges between 1.5-2.5 for music platforms. This leads to underrepresentation of niche genres and independent artists. Collaborative filtering methods exacerbate this by recommending items similar to a user's history, creating a feedback loop that reinforces popularity bias.
Quantifying Fairness in Recommendations
We can measure fairness using statistical parity difference (SPD) for artist groups. Let A be a protected attribute (e.g., artist gender, label size), and ŷ be the recommendation outcome:
An ideal system maintains SPD ≈ 0. However, real-world music recommenders often show SPD values exceeding 0.3 for attributes like artist gender. The Gini coefficient G provides another measure of recommendation inequality:
where x_i is the recommendation frequency for artist i.
Debiasing Techniques
Several approaches mitigate bias in music recommendation:
- Reweighting: Adjust training instance weights inversely proportional to item popularity
- Adversarial Debiasing: Train with an adversary that predicts protected attributes from latent representations
- Counterfactual Fairness: Ensure recommendations wouldn't change if protected attributes were modified
The adversarial approach modifies the standard recommendation loss Lrec with a fairness term:
where λ controls the fairness-accuracy trade-off. Recent work shows optimal λ values between 0.1-0.3 maintain recommendation quality while reducing SPD by 40-60%.
Case Study: Gender Bias in Playlist Generation
A 2022 study of a major streaming platform found that while female artists constituted 23% of the catalog, they appeared in only 12% of algorithmic playlist recommendations. Implementing a hybrid reweighting-adversarial approach increased female artist representation to 19% while maintaining a 92% recommendation accuracy score.
Emerging Challenges
New forms of bias emerge in multimodal recommendation systems combining audio analysis with collaborative signals. The acoustic feature space often clusters by genre and era, which correlates with demographic factors. Current research explores disentangled representation learning to separate musical characteristics from protected attributes:
where ∥ denotes vector concatenation and dimensions are optimized to be mutually orthogonal.
5.2 Impact on Artists and the Music Industry
Algorithmic Bias and Market Polarization
AI-driven music trend prediction models often rely on historical chart data, which inherently encodes biases in genre representation, regional popularity, and demographic appeal. These biases propagate through machine learning pipelines, reinforcing existing market inequalities. For instance, a recurrent neural network (RNN) trained on Billboard Hot 100 data from 2000–2020 disproportionately weights pop and hip-hop genres due to their historical dominance. The model’s loss function
Economic Implications for Independent Artists
Record labels leverage AI trend predictions to optimize marketing budgets, allocating resources to artists with the highest predicted ROI. This crowds out independent musicians lacking access to such tools. A 2023 Berklee College of Music study found that label-backed artists receive 73% more playlist placements on platforms using recommendation algorithms like Spotify’s Bandits for Bands. The multi-armed bandit problem formulation
Creative Homogenization
Neural style transfer networks analyze hit songs to extract "successful" musical features (e.g., tempo curves, harmonic progressions). When artists use these as compositional templates, it reduces stylistic diversity. A Princeton University study demonstrated this effect by training a Wasserstein GAN on 50,000 charting tracks. The Fréchet Audio Distance (FAD) between AI-assisted and organic compositions decreased by 42%, indicating convergence toward a homogenized sound profile:
Contractual Shifts in the Industry
AI prediction capabilities have triggered novel contract clauses. Major labels now include "algorithm performance riders" tying advances to an artist’s predicted streaming numbers. These predictions come from survival analysis models like Cox proportional hazards:
Countermeasures and Emerging Practices
Some artists employ counter-algorithmic strategies:
- Adversarial Audio Perturbations: Inaudible noise injections (constrained by
$$ ||\delta||_\infty \leq \epsilon $$) designed to trigger favorable recommendations while preserving human listening experience.
- Blockchain-Based Attribution: Distributed ledgers track AI-influenced creative decisions, enabling royalty micropayments to data sources.
- Differential Privacy in Collaborations: Federated learning techniques allow artists to pool training data without exposing raw creative assets.
5.3 Regulatory and Privacy Concerns
AI-driven music chart prediction systems operate in a regulatory landscape shaped by data protection laws, intellectual property rights, and ethical guidelines. The primary challenge lies in balancing predictive accuracy with compliance, particularly when processing user listening behavior, demographic data, or proprietary streaming metrics. The General Data Protection Regulation (GDPR) in the EU and the California Consumer Privacy Act (CCPA) impose strict requirements on data anonymization, user consent, and transparency, which directly affect training datasets.
Data Anonymization and Re-identification Risks
Even aggregated listening data can be vulnerable to re-identification attacks. For instance, a 2019 study demonstrated that 90% of users in anonymized music datasets could be re-identified using just four distinct listening events. To mitigate this, differential privacy techniques are often applied. The privacy budget ε quantifies the trade-off between data utility and privacy:
where M is a randomized algorithm, D and D' are adjacent datasets, and S is the output range. A smaller ε enhances privacy but degrades model performance.
Copyright and Fair Use in Training Data
AI models analyzing audio waveforms or lyrical content must navigate copyright law. The U.S. fair use doctrine’s four-factor test—purpose, nature, amount, and market effect—often clashes with machine learning’s data-hungry nature. For example, training on 30-second song clips may qualify as transformative use, but reproducing melodic structures in predictions could infringe on composition copyrights under the Skidmore v. Led Zeppelin precedent.
Algorithmic Transparency Requirements
Article 22 of GDPR mandates explainability for automated decision-making systems affecting users. Music recommendation engines using latent factor models like:
must provide interpretable feature attributions. Techniques like SHAP (Shapley Additive Explanations) are increasingly adopted, though they incur computational overhead—a 2022 benchmark showed a 40% latency increase when generating explanations for matrix factorization predictions.
Cross-Border Data Transfer Challenges
Global music platforms face conflicting regulations when transferring data between jurisdictions. The EU-US Data Privacy Framework requires additional safeguards for audio behavioral data, while China’s PIPL mandates local storage of user data. Federated learning architectures, where model updates are aggregated instead of raw data, have emerged as a technical solution, though they introduce challenges in gradient inversion attacks.
Ethical Considerations in Predictive Bias
Chart prediction models trained on historical data may perpetuate popularity biases. A 2021 analysis of Billboard Hot 100 predictions revealed a 23% underrepresentation of non-English tracks compared to actual streaming patterns. Countermeasures include adversarial debiasing during training:
where f_θ is the predictor and f_φ is the adversary detecting protected attributes.
6. Key Research Papers and Articles
6.1 Key Research Papers and Articles
- A Survey of AI Music Generation Tools and Models - arXiv.org — which are also applied in AI-generated music. Then, we will explore the current state of AI music generation tools and models, evaluating their functionality and discussing their limitations. Finally, by analyzing the latest tools and techniques, we aim to provide a comprehensive understanding of the potential of AI-based music composition and the
- Applications and Advances of Artificial Intelligence in Music ... — Research Objectives: This paper aims to systematically review the latest research progress in symbolic and audio music generation, explore their potential and challenges in various application scenarios, and forecast future development directions. Through a comprehensive analysis of existing technologies and methods, this paper seeks to provide valuable references for researchers and ...
- (PDF) A Survey of AI Music Generation Tools and Models - ResearchGate — Music Generation A lgorithms, Music AI, Music Te chnology, Computer-gener ated Music, Deep L earning Music. The prompt we hav e used on our LLM platform is as follows: I am sear ching for music
- Artificial Intelligence: Where the Music of the Future Is Heading — In 2017, the media spotlight was shone on Spotify's inauguration of a special research unit set up to do scientific research into the use of AI in the music sector, the Creator Technology Research Lab (Titlow, 2017).In one respect, Spotify's integration of AI is nothing new: in fact, as we noted in previous chapters, Spotify has been using forms of AI and machine learning to analyze the ...
- A Comprehensive Survey for Evaluation Methodologies of AI-Generated Music — of the process of AI music generation evaluation. Among the existing generative models, music listening tests and visual analysis are the two most important parts. 3.1 Music Listening Test The music listening test is the most common method in subjective evaluation. Such evaluations are commonly con-ducted through two approaches: the musical ...
- Full article: A multi-genre model for music emotion recognition using ... — The majority of the studies in Table 1 used varying types of regression or machine learning, which were generally formed from high-level audio features, such as musical tempo or key, and used to predict music in terms of dimensional concepts. With some exceptions where Chinese music or soundtrack music is employed, the majority of studies are ...
- PDF Algorithmic Ability to Predict the Musical Future: Datasets and Evaluation — ever, other approaches to algorithmic music prediction are needed to achieve a more rounded picture of the potential of state-of-the-art methods of music prediction. 1. INTRODUCTION Prediction of future events is fundamental to human and articial intelligence, and has therefore been discussed as a core research interest bridging cognitive ...
- PDF Web-Based Music Player for Music Performance Analysis — music emotion prediction using machine learning algorithms, where the researchers focused on a predefined data set to predict. Xu et al. (2020) use a 60-excerpt dataset to predict emotion using machine learning. The research uses only three emotions (happy, sad, and relaxing), making it less appropriate to extract participants' feelings.
- PDF Prediction of Genres and Emotions by Song Lyrics - Stanford University — ers (BERT) model to predict and classify the genres and emotions based on the Song Lyrics. We hope those predictions can facilitate the automation of the music industry. 1 Introduction The importance of genre and emotion classification in music organization has long been recognized by the industry due to the explosion of music recordings online ...
- PDF Predicting the Song Popularity Using Machine Learning Algorithm — Keywords- Machine learning, music, popularity, prediction, songs, regression, classification, ensemble learning, random forests, boosting. I. INTRODUCTION Hundreds of songs are released per annum, but only a few of them make it to the highest charts. Music analysis has made it possible to get metadata of a song. Similarly, such
6.2 Open Datasets and Tools
- AI in the Music Industry: Transforming Music Production ... - DataArt — These AI-powered tools are revolutionizing how we navigate this vast information, offering nuanced insights that reshape our approach to exploring and understanding music. Navigating the intricate challenge of managing vast data in the music industry demands sophisticated solutions. By analyzing extensive datasets and revealing trends in ...
- Datasets - Spotify Research — Dataset for music recommendation and automatic music playlist continuation. Contains 1,000,000 playlists, including playlist- and track-level metadata. WSDM Cup: The Music Streaming Sessions Dataset Nov 15, 2018. Dataset for researching how to model user listening and interaction behavior in music streaming. Also includes data for music ...
- GitHub - mdeff/fma: FMA: A Dataset For Music Analysis — All metadata and features for all tracks are distributed in fma_metadata.zip (342 MiB). The below tables can be used with pandas or any other data analysis tool. See the paper or the usage.ipynb notebook for a description.. tracks.csv: per track metadata such as ID, title, artist, genres, tags and play counts, for all 106,574 tracks.; genres.csv: all 163 genres with name and parent (used to ...
- Using AI To Predict Hit Potential Of New Music Tracks — AI tools analyze the sentiment, themes, and complexity of lyrics in popular songs to gauge potential appeal. ... Emerging trends in music prediction are unveiling exciting possibilities, powered by advances in AI and machine learning. Predictive analytics is becoming more sophisticated, using larger datasets to increase accuracy in predicting ...
- Applications and Advances of Artificial Intelligence in Music ... — Research Objectives: This paper aims to systematically review the latest research progress in symbolic and audio music generation, explore their potential and challenges in various application scenarios, and forecast future development directions. Through a comprehensive analysis of existing technologies and methods, this paper seeks to provide valuable references for researchers and ...
- Data Analytics AI in Music Production: Predicting the Next Big Hit ... — Companies like Tencent Music Entertainment have developed PDM (Predictive Model) technology, which analyzes song structure, lyrics, and past trends to predict a track's potential to become a hit. By using AI-driven tools, Tencent can target songs to specific demographics and craft marketing strategies based on predicted outcomes.
- Predicting Hit Songs with AI: A Journey in Music and Machine ... - Medium — The scales for these music features differ, with subjective attributes like danceability and valence normalized between 0 and 1, while objective aspects like loudness are measured in decibels, and ...
- PDF Algorithmic Ability to Predict the Musical Future: Datasets and Evaluation — can correctly predict about a third of a monophonic seg-ment, and around half of a polyphonic segment, with one of the neural network models achieving best results. How-ever, other approaches to algorithmic music prediction are needed to achieve a more rounded picture of the potential of state-of-the-art methods of music prediction. 1. INTRODUCTION
- PDF Predicting the Song Popularity Using Machine Learning Algorithm — result on the problemof predicting music popularity. Their goal was to distinguish the top 5 hits from the top 30-40 hit list. Their dataset was based on UK charts during a time period of 50years. 5947 unique songs were collected from the Official Charts Company (OCC),and the audio features were extracted from The Echo Nest. They
- Predicting the Song Popularity Using Machine Learning Algorithm — Being ready to predict popularity of a song supported metadata and attributes are often of great industrial importance. We aim to attain this using machine learning techniques.
6.3 Recommended Books and Courses
- PDF Web-Based Music Player for Music Performance Analysis — usability of online music streaming services such as Spotify, Apple Music, YouTube Music, and Amazon Music. Music emotion recognition aids in predicting music's affective content for listeners by applying machine learning and AI techniques. MER is efficient in understanding music, retrieval of music, and other music-related applications.
- The Role of AI in Music Composition and Production - EMB Blogs — 3.3 The Role of Data in AI Music Composition. Data plays a pivotal role in AI music composition. The more diverse and extensive the dataset, the better equipped AI is to create innovative music. Music databases encompass classical symphonies, jazz improvisations, rock anthems, and electronic beats, among others.
- Music intelligence: Granular data and prediction of top ten hit songs — The weekly Billboard Hot 100 chart is one of the most popular charts and provides 100 most popular songs for a given week based on Nielsen Music data (e.g., radio airplay, sales, streaming activity, etc.). We recover the Spotify ID for each individual song that Billboard published [23]. This Billboard sample is a weekly unbalanced panel and has ...
- Applications and Advances of Artificial Intelligence in Music ... — Research Objectives: This paper aims to systematically review the latest research progress in symbolic and audio music generation, explore their potential and challenges in various application scenarios, and forecast future development directions. Through a comprehensive analysis of existing technologies and methods, this paper seeks to provide valuable references for researchers and ...
- Artificial Intelligence: Where the Music of the Future Is Heading — In 2017, the media spotlight was shone on Spotify's inauguration of a special research unit set up to do scientific research into the use of AI in the music sector, the Creator Technology Research Lab (Titlow, 2017).In one respect, Spotify's integration of AI is nothing new: in fact, as we noted in previous chapters, Spotify has been using forms of AI and machine learning to analyze the ...
- Intelligent Music Production[Book] - O'Reilly Media — This book presents the state of the art in approaches, methodologies and systems from the emerging field of automation in music mixing and mastering. A comprehensive guide, providing an introductory read for beginners, as well as a crucial reference point for experienced researchers, producers, engineers and developers.
- Music Recommender Systems - SpringerLink — Koenigstein et al. have exploited the activity of US-based users in peer-to-peer networks to predict the popularity of music tracks in US song charts. Schedl [ 121 ] used geo-tagged tweets to extract location-based music listening trends and in turn build a location-aware recommender system.
- PDF Automatic Music Recommendation for Businesses - DiVA — Automatic MusicRecommendation forBusinesses Usingatwo-stageMembershipmodel fortrackrecommendation SVANTE HAAPANEN ROLLENHAGEN Master's Programme, Computer Science, 120 credits
- Predicting the Song Popularity Using Machine Learning Algorithm — Being ready to predict popularity of a song supported metadata and attributes are often of great industrial importance. We aim to attain this using machine learning techniques.
- 3.5 Assignment 3 | The Analytics Edge - MIT OpenCourseWare — Problem 2.2 - Creating our Prediction Model. In this problem, our outcome variable is "Top10" - we are trying to predict whether or not a song will make it to the Top 10 of the Billboard Hot 100 Chart. Since the outcome variable is binary, we will build a logistic regression model.








