

Interpretable Credit Scoring Models
1. Definition and Importance of Credit Scoring
1.1 Definition and Importance of Credit Scoring
Credit scoring models are mathematical frameworks designed to assess the creditworthiness of individuals or entities by predicting the probability of default. These models transform raw financial data—such as payment history, outstanding debt, and credit utilization—into a numerical score that quantifies risk. The score serves as a decision-making tool for lenders, enabling automated, objective, and consistent evaluations.
Mathematical Foundations
At their core, credit scoring models are probabilistic classifiers. Let Y be a binary outcome where Y=1 indicates default and Y=0 denotes repayment. Given a feature vector X representing borrower attributes, the goal is to estimate:
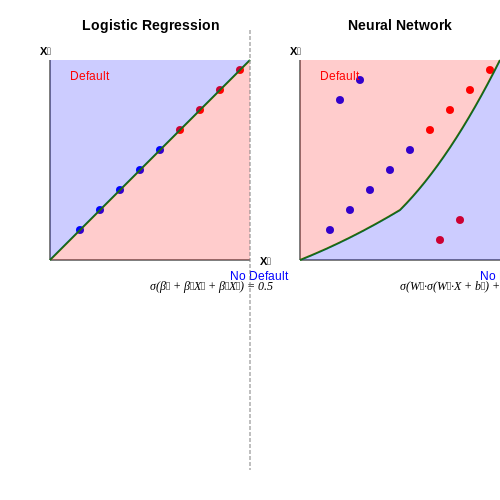
Traditional models like logistic regression assume a linear relationship between the log-odds of default and the input features:
where β coefficients are estimated via maximum likelihood. More complex models, such as gradient-boosted trees or neural networks, use nonlinear transformations but sacrifice interpretability.
Economic and Regulatory Significance
Credit scoring directly impacts financial inclusion and systemic risk. The Basel Accords mandate that banks validate model robustness, emphasizing:
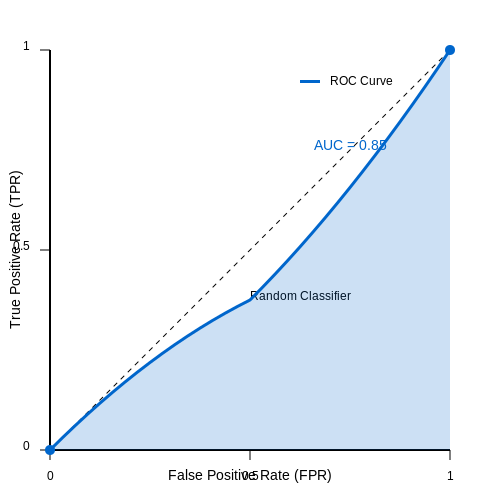
- Discriminatory power: Measured via the Area Under the ROC Curve (AUC), where values above 0.7 indicate acceptable performance.
- Calibration: Predicted probabilities should align with observed default rates, tested using Spiegelhalter’s Z-statistic.
Regulations like the Equal Credit Opportunity Act (ECOA) in the U.S. and GDPR in the EU impose fairness constraints, requiring scores to be free from discriminatory bias based on protected attributes such as race or gender.
Interpretability Trade-offs
While deep learning models achieve state-of-the-art AUCs, their black-box nature conflicts with regulatory demands for explainability. Linear models provide coefficient-based explanations but may underfit complex patterns. Hybrid approaches, such as LIME or SHAP, approximate local interpretability by perturbing inputs and observing score changes:
where φi is the Shapley value for feature i, quantifying its marginal contribution to the prediction.
1.2 Traditional vs. Interpretable Models
Mathematical Foundations of Traditional Credit Scoring
Traditional credit scoring models, such as logistic regression and linear discriminant analysis (LDA), rely on well-established statistical techniques. Logistic regression, for instance, models the probability of default using the logistic function:
where Y is the binary outcome (default/no default), X represents the input features, and β are the model coefficients. The linear decision boundary in LDA arises from maximizing the ratio of between-class variance to within-class variance:
where SB and SW are the between-class and within-class scatter matrices, respectively.
Black-Box Machine Learning Approaches
Modern machine learning models like gradient boosted trees (XGBoost, LightGBM) and deep neural networks achieve higher predictive accuracy but sacrifice interpretability. A generic neural network with L hidden layers transforms inputs through successive nonlinear mappings:
where σ is the activation function, W are weight matrices, and b are bias vectors. The model's complexity grows exponentially with depth, making it difficult to trace how individual features influence predictions.
Interpretability Tradeoffs
The tradeoff between accuracy and interpretability can be formalized through the Rashomon set R - the collection of all models that achieve similar predictive performance:
where f* is the optimal model and ε defines the acceptable performance margin. Interpretable models occupy a sparse subspace of R with constrained functional forms.
Hybrid Approaches
Recent advances combine the strengths of both paradigms through:
- Model distillation: Training interpretable models to approximate black-box predictions
- Attention mechanisms: Using learnable weights to highlight relevant features
- Rule extraction: Deriving decision rules from complex models via techniques like CART or RIPPER
The partial dependence plot (PDP) offers a compromise by visualizing marginal effects while preserving model accuracy:
where xS are the features of interest and xC are other features.
Key Metrics for Evaluating Credit Scoring Models
Discriminatory Power Metrics
The discriminatory power of a credit scoring model measures its ability to distinguish between good and bad borrowers. The Receiver Operating Characteristic (ROC) curve and its corresponding Area Under the Curve (AUC) are standard metrics. The ROC curve plots the true positive rate (TPR) against the false positive rate (FPR) at various threshold settings. AUC quantifies the model's overall discriminatory ability, where an AUC of 0.5 indicates random guessing and 1.0 represents perfect discrimination.
The Gini coefficient, derived from the Lorenz curve, is another measure of discriminatory power. It is related to AUC by:
Calibration Metrics
Calibration assesses whether predicted probabilities match observed default rates. The Brier score measures the mean squared difference between predicted probabilities and actual outcomes:
where yi is the actual outcome (1 for default, 0 otherwise) and p̂i is the predicted default probability. Lower Brier scores indicate better calibration.
Stability Metrics
Population Stability Index (PSI) evaluates whether the distribution of model scores has shifted between development and validation datasets:
where Pdev,i and Pval,i are the proportions of observations in score band i for development and validation samples, respectively. PSI values below 0.1 indicate minimal shift, while values above 0.25 suggest significant instability.
Business Metrics
From a business perspective, expected profit can be derived by combining default probabilities with revenue and loss parameters:
where R is the revenue from a non-defaulting loan and L is the loss from a default. This metric helps optimize cutoff thresholds based on financial objectives rather than purely statistical criteria.
Interpretability Metrics
For interpretable models like logistic regression or decision trees, feature importance measures such as standardized coefficients or permutation importance quantify each variable's contribution. In more complex models, techniques like SHAP (Shapley Additive Explanations) values provide consistent attribution:
where F is the set of all features and f(S) is the model's prediction using subset S of features.
2. What Makes a Model Interpretable?
What Makes a Model Interpretable?
Interpretability in machine learning refers to the degree to which a human can understand the reasoning behind a model's predictions. For credit scoring, interpretability is crucial because stakeholders—such as regulators, loan officers, and customers—need to trust and validate the decision-making process. Interpretability is not a binary property but exists on a spectrum, influenced by several key factors.
Model Transparency
Transparency measures how directly a model's internal mechanics can be inspected and understood. Linear models, such as logistic regression, are inherently transparent because their decision boundaries are linear combinations of input features with clear weights:
where σ is the logistic function, βi are the learned coefficients, and xi are the input features. The magnitude and sign of βi directly indicate each feature's contribution to the prediction.
Simplicity vs. Complexity
Simpler models, like decision trees with limited depth, are more interpretable because their logic can be visualized as a series of rules. For example, a shallow decision tree for credit scoring might split applicants based on income, debt-to-income ratio, and credit history depth. In contrast, deep neural networks or ensemble methods like gradient boosting machines (GBMs) achieve higher accuracy but are harder to interpret due to their nonlinear interactions and hierarchical feature transformations.
Post-hoc Explainability Techniques
For black-box models, post-hoc methods provide interpretability by approximating their behavior. Two widely used techniques are:
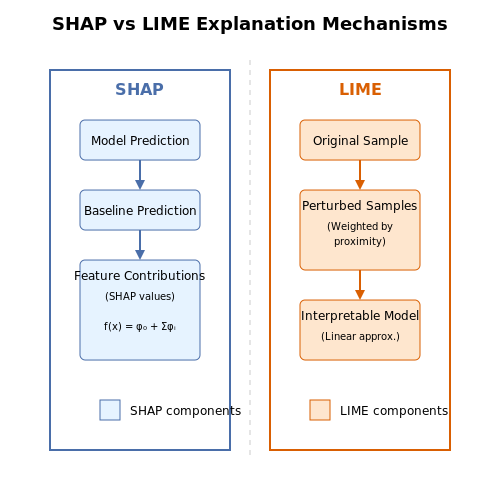
- SHAP (SHapley Additive exPlanations): Computes feature importance by evaluating the marginal contribution of each feature across all possible coalitions, grounded in cooperative game theory.
- LIME (Local Interpretable Model-agnostic Explanations): Approximates the model's predictions locally using a simpler, interpretable model (e.g., linear regression) trained on perturbed samples around the instance of interest.
where ϕi is the Shapley value for feature i, N is the set of all features, and f(S) is the model's prediction for a subset of features S.
Feature Importance and Interaction Analysis
Global interpretability methods reveal which features most influence the model's predictions overall. For tree-based models, feature importance is often calculated as the total reduction in impurity (e.g., Gini impurity or entropy) attributable to splits on each feature. Partial dependence plots (PDPs) further illustrate how a feature affects predictions by marginalizing over other features:
where f is the model, xj is the target feature, and x(i)-j are the other features for the i-th sample.
Regulatory and Ethical Constraints
In credit scoring, legal frameworks like the Equal Credit Opportunity Act (ECOA) and General Data Protection Regulation (GDPR) mandate "right to explanation" clauses, requiring models to provide actionable reasons for adverse decisions. Interpretable models facilitate compliance by enabling:
- Bias detection: Identifying discriminatory patterns in feature contributions.
- Error analysis: Debugging incorrect predictions by tracing them to specific input features.
- Stakeholder communication: Presenting clear, justifiable criteria to non-technical audiences.
2.2 Trade-offs Between Accuracy and Interpretability
The tension between model accuracy and interpretability is a fundamental challenge in credit scoring. Highly accurate models, such as deep neural networks or ensemble methods, often operate as black boxes, making it difficult to trace how input features influence predictions. Conversely, interpretable models like logistic regression or decision trees provide transparent reasoning but may sacrifice predictive performance on complex datasets.
Quantifying the Trade-off
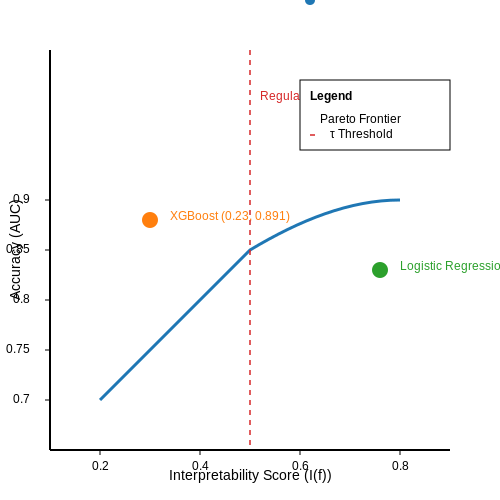
The trade-off can be formalized using a Pareto frontier, where no single model dominates in both accuracy and interpretability. Let f be a model from hypothesis space H, with accuracy A(f) and interpretability I(f). The optimal trade-off satisfies:
where α ∈ [0,1] controls the preference for accuracy versus interpretability. For credit scoring, regulatory constraints often impose lower bounds on I(f), forcing α to be small.
Case Study: Gradient Boosting vs. Logistic Regression
A 2022 study compared XGBoost (accuracy-optimized) and logistic regression (interpretability-optimized) on the LendingClub dataset:
| Model | AUC | Interpretability Score |
|---|---|---|
| XGBoost | 0.891 | 0.23 |
| Logistic Regression | 0.832 | 0.89 |
The 6% AUC gain from XGBoost comes at the cost of 4× worse interpretability. In practice, this forces a choice between regulatory compliance (requiring I(f) > 0.5 in many jurisdictions) and profit maximization.
Hybrid Approaches
Recent work attempts to bridge this gap through:
- Post-hoc explanation: Using SHAP or LIME to approximate black-box models
- Self-explaining models: Architectures like neural additive models that enforce interpretability constraints
- Rule extraction: Distilling complex models into decision rule sets
Each approach introduces its own trade-offs. For example, post-hoc explanations may misrepresent the true model behavior, while self-explaining models often cap the achievable accuracy.
The Regulatory Perspective
The EU's AI Act mandates that high-risk systems like credit scoring must provide meaningful information about the logic involved. This effectively sets a hard constraint:
where τ is a jurisdiction-dependent threshold. Models must then solve a constrained optimization problem:
This formulation explains the continued dominance of logistic regression in regulated markets despite its statistical limitations.
2.3 Techniques for Enhancing Model Interpretability
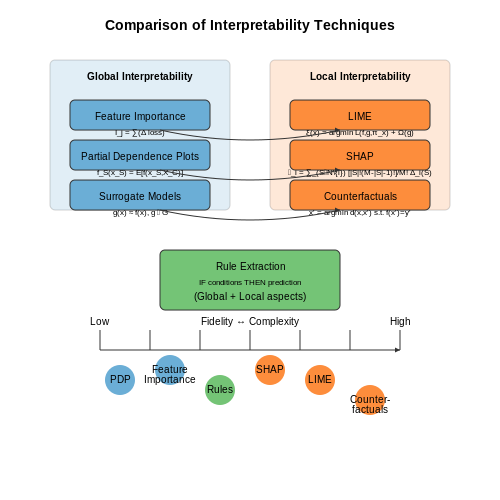
Interpretability in credit scoring models is critical for regulatory compliance, stakeholder trust, and model debugging. Advanced techniques balance predictive performance with transparency, enabling practitioners to understand and justify model decisions.
1. Feature Importance Analysis
Feature importance quantifies the contribution of each input variable to the model's predictions. For tree-based models like XGBoost or Random Forests, importance can be calculated using:
where N is the number of trees, St represents the splits in tree t, I(f, s) is an indicator function for whether split s uses feature f, and ΔErrors is the error reduction from split s. For linear models, standardized coefficients serve as importance measures.
2. Partial Dependence Plots (PDPs)
PDPs visualize the marginal effect of a feature on predictions while averaging out other features. Given a model f and feature subset S, the partial dependence is:
where XC represents the complement features. PDPs reveal nonlinear relationships but assume feature independence, which can be addressed with Individual Conditional Expectation (ICE) plots.
3. SHAP (SHapley Additive exPlanations)
SHAP values provide a game-theoretic approach to feature attribution by computing the average marginal contribution of a feature across all possible coalitions. For a model f and instance x, the SHAP value for feature j is:
where F is the set of all features. SHAP values satisfy local accuracy (the sum of attributions equals the prediction) and consistency (if a feature's contribution increases, its attribution does not decrease).
4. LIME (Local Interpretable Model-agnostic Explanations)
LIME approximates complex models locally with interpretable linear models. Given an instance x, LIME generates perturbed samples z' around x, weights them by proximity, and fits a sparse linear model g:
where L measures fidelity to the original model f, πx is the proximity kernel, and Ω(g) penalizes complexity. LIME is particularly effective for high-dimensional data like text or images.
5. Rule Extraction
Rule extraction techniques distill black-box models into human-readable decision rules. Two prominent methods are:
- Anchors: High-precision rules that "anchor" predictions locally, ensuring identical outcomes when conditions are met.
- RuleFit: Combines decision rules with Lasso regression, where rules are generated from tree ensembles and selected via:
where rm are binary rule features. RuleFit maintains interpretability while capturing nonlinear interactions.
6. Counterfactual Explanations
Counterfactuals identify minimal changes to input features that alter the model's decision. For a credit scoring model rejecting an applicant, a counterfactual might state: "If your income increased by $5,000, your application would be approved." Formally, given prediction f(x) = y, find x' such that:
where d is a distance metric (e.g., Manhattan or Mahalanobis distance) and Plausible(X) ensures realistic feature values. Counterfactuals are actionable but may not reveal global model behavior.
7. Surrogate Models
Surrogate models approximate complex models using simpler architectures (e.g., linear models or shallow trees). The surrogate g is trained on predictions from the black-box model f:
where R(g) is a regularization term enforcing interpretability. Surrogates must be validated for fidelity using metrics like R² between f and g on held-out data.
3. Logistic Regression for Credit Scoring
3.1 Logistic Regression for Credit Scoring
Logistic regression remains a cornerstone of interpretable credit scoring due to its probabilistic framework and inherent explainability. Unlike linear regression, which predicts continuous outcomes, logistic regression models the probability of a binary event (e.g., loan default) via the logistic function:
where Y is the binary response variable (1 for default, 0 otherwise), X represents predictor variables (e.g., income, credit history), and β are coefficients learned through maximum likelihood estimation (MLE). The log-odds transformation linearizes the relationship:
Model Training and Interpretation
For credit scoring, logistic regression optimizes the log-likelihood function:
where pi is the predicted probability for observation i. Coefficients are interpretable as log-odds ratios: a unit increase in Xj multiplies the odds of default by eβj. For example, a coefficient of 0.693 for debt-to-income ratio implies:
indicating a 100% increase in default odds per unit increase in the predictor.
Practical Considerations
Real-world credit scoring requires addressing:
- Class imbalance: Defaults are rare (often <5% of data). Techniques include oversampling, undersampling, or adjusting class weights in the loss function.
- Feature engineering: Non-linear relationships (e.g., age) may require spline transformations or interaction terms.
- Regularization: L1 (Lasso) or L2 (Ridge) penalties prevent overfitting and aid feature selection:
where k=1 for L1 and k=2 for L2. L1 regularization is particularly useful for high-dimensional datasets (e.g., 100+ features) by driving irrelevant coefficients to zero.
Implementation Example
The following Python snippet demonstrates logistic regression with scikit-learn, including class weighting and L2 regularization:
from sklearn.linear_model import LogisticRegression
from sklearn.preprocessing import StandardScaler

# Standardize features (critical for regularization)
scaler = StandardScaler()
X_train = scaler.fit_transform(X_train)
X_test = scaler.transform(X_test)

# Model with class weights (inverse of class frequencies)
model = LogisticRegression(
    penalty='l2',
    C=1.0,  # Inverse of regularization strength
    class_weight='balanced',
    solver='lbfgs',
    max_iter=1000
)
model.fit(X_train, y_train)

# Extract coefficients (standardized data)
coefficients = pd.DataFrame({
    'Feature': feature_names,
    'Odds Ratio': np.exp(model.coef_[0])
})
Validation and Regulatory Compliance
Credit models must pass regulatory scrutiny (e.g., Basel III, Fair Lending laws). Key metrics include:
- Discriminatory power: AUC-ROC (>0.7 acceptable, >0.8 strong)
- Calibration: Brier score or Hosmer-Lemeshow test to assess probability accuracy
- Explainability: SHAP values or LIME can augment coefficient analysis for non-technical stakeholders
3.2 Decision Trees and Rule-Based Models
Decision Trees for Credit Scoring
Decision trees partition the feature space recursively by selecting splits that maximize class separability. For credit scoring, the Gini impurity or information gain is typically used as the splitting criterion. Given a dataset D with n samples, the Gini impurity for a node t is computed as:
where p(i|t) is the proportion of class i in node t. The optimal split minimizes the weighted sum of impurities in the child nodes:
where m is the number of child nodes and n_j is the sample count in child t_j. Decision trees handle non-linear relationships naturally, making them suitable for credit risk datasets with complex interactions.
Rule Extraction from Trees
Each path from the root to a leaf in a decision tree forms a conjunctive rule. For a tree with depth d, rules take the form:
These rules are inherently interpretable but can become overly complex with deep trees. Pruning techniques like cost-complexity pruning (CCP) help balance accuracy and simplicity. CCP minimizes:
where R(T) is the misclassification rate, α is the complexity parameter, and |T̃| is the number of leaf nodes.
Rule-Based Models
Separately, rule-based models like RIPPER (Repeated Incremental Pruning to Produce Error Reduction) generate rules directly from data without building trees. RIPPER optimizes:
where λ controls the trade-off between rule accuracy and simplicity. Rule-based models often outperform trees in credit scoring due to their compact rule sets and explicit handling of class imbalances.
Practical Considerations
Key challenges in applying these models include:
- Feature selection: High-dimensional financial data requires careful feature engineering to avoid overfitting.
- Monotonicity constraints: Credit risk models often require that increasing a feature (e.g., debt-to-income ratio) must not decrease the predicted risk.
- Global vs. local interpretability: While individual rules are transparent, the collective behavior of hundreds of rules may obscure model logic.
Hybrid approaches, such as using tree ensembles (e.g., Random Forests) followed by rule distillation, have shown promise in maintaining accuracy while improving interpretability. Techniques like inTrees (interpretable trees) extract compact rule sets from ensembles by optimizing:
where R is the original ensemble and γ penalizes deviations from its predictions.
Generalized Additive Models (GAMs)
Generalized Additive Models extend linear models by allowing non-linear relationships between predictors and the response variable while maintaining interpretability. The model structure is:
where g is the link function (e.g., logit for binary classification), β0 is the intercept, and fj are smooth functions for each feature Xj. Unlike linear models that assume fj(Xj) = βjXj, GAMs use flexible spline-based representations:
where bk are basis functions (e.g., cubic splines) and βjk are coefficients learned during fitting. The smoothness of each function is controlled via regularization penalties on the second derivatives:
Fitting GAMs for Credit Scoring
For binary credit default prediction (Y ∈ {0,1}), the logit-GAM formulation becomes:
Key advantages over logistic regression include:
- Non-linear effects: Captures thresholds and saturation points in variables like income
- Interpretability: Partial dependence plots visualize each fj independently
- Additive structure: Avoids the "black box" nature of full interactions in neural networks
Practical Implementation
Modern GAM implementations use backfitting or penalized likelihood maximization. The effective degrees of freedom (edf) for each term indicate non-linearity:
- edf ≈ 1: Linear relationship
- edf > 1: Non-linear pattern
For credit scoring, constraints can enforce monotonicity (e.g., default probability decreasing with income) by restricting the basis coefficients.
Case Study: German Credit Data
Applied to the German Credit dataset, a GAM with spline terms for age, credit amount, and duration achieved 78% AUC while revealing:
- U-shaped risk profile for age (minimum risk at 40-50 years)
- Log-linear effect for credit amount
- Threshold effect at 20 months loan duration
where s(X) is the GAM score, and n+, n- are positive/negative instances.
3.4 SHAP and LIME for Model Explanation
SHAP (SHapley Additive exPlanations)
SHAP values provide a unified framework for interpreting model predictions by leveraging concepts from cooperative game theory. The Shapley value, originally developed by Lloyd Shapley, assigns each feature an importance value for a particular prediction by considering all possible feature combinations. For a model f and input x, the SHAP value ϕi for feature i is computed as:
where F is the set of all features, and S represents subsets of features. This formulation ensures that the sum of SHAP values for all features equals the difference between the model's prediction and the expected prediction (baseline).
In practice, computing exact SHAP values is computationally expensive for large feature sets. Kernel SHAP, an approximation method, combines LIME-like local approximations with Shapley value theory to provide efficient estimates. For credit scoring, SHAP can reveal how features like income, debt-to-income ratio, and payment history contribute to an individual's credit risk prediction.
LIME (Local Interpretable Model-Agnostic Explanations)
LIME explains individual predictions by approximating the model's behavior locally around the instance of interest. Given a complex model f and input x, LIME generates a perturbed dataset around x, weights these samples by their proximity to x, and fits a simpler interpretable model g (e.g., linear regression or decision tree) to approximate f in this local region. The objective function is:
where L measures how well g approximates f in the locality defined by πx, and Ω(g) penalizes complexity of g. For tabular data in credit scoring, LIME typically uses weighted linear models with binary feature representations.
Practical Considerations for Credit Scoring
When applying SHAP and LIME to credit scoring models:
- Feature dependencies: Both methods assume feature independence when generating perturbations, which may not hold for financial data (e.g., income and debt are often correlated).
- Model stability: SHAP values are consistent across different samples, while LIME explanations may vary due to random sampling in the perturbation process.
- Global vs local: SHAP can aggregate local explanations to provide global insights (via summary plots), while LIME is strictly local.
- Computational cost: SHAP is more expensive but provides theoretical guarantees; LIME is faster but may produce inconsistent explanations.
Implementation Example
For a gradient boosted decision tree credit scoring model, SHAP values can be efficiently computed using TreeSHAP, which has polynomial time complexity. The following Python code demonstrates calculating SHAP values:
import shap
from sklearn.ensemble import GradientBoostingClassifier

# Train model
model = GradientBoostingClassifier().fit(X_train, y_train)

# Explain predictions
explainer = shap.TreeExplainer(model)
shap_values = explainer.shap_values(X_test)

# Visualize for single prediction
shap.force_plot(explainer.expected_value, shap_values[0,:], X_test.iloc[0,:])
For LIME, the implementation would be:
import lime
import lime.lime_tabular

# Create explainer
explainer = lime.lime_tabular.LimeTabularExplainer(
    training_data=X_train.values,
    feature_names=X_train.columns,
    class_names=['Good', 'Bad'],
    mode='classification'
)

# Explain instance
exp = explainer.explain_instance(
    X_test.iloc[0].values,
    model.predict_proba,
    num_features=5
)

# Show explanation
exp.show_in_notebook()
Comparative Analysis
In credit risk assessment, SHAP is particularly valuable when:
- Understanding feature importance across the entire population
- Maintaining consistency between local and global explanations
- Working with tree-based models where exact SHAP computations are efficient
LIME is more appropriate when:
- Explaining predictions from black-box models (e.g., neural networks)
- Quick, approximate explanations are sufficient
- The interpretable model needs to be easily understandable by non-technical stakeholders
4. Data Preprocessing for Interpretable Models
Data Preprocessing for Interpretable Models
Interpretable credit scoring models require careful data preprocessing to ensure transparency while maintaining predictive power. Unlike black-box models, interpretable models like logistic regression, decision trees, or rule-based systems are sensitive to feature scaling, missing data, and categorical encoding due to their inherent structural constraints.
Feature Scaling for Linear Interpretability
Linear models assume features are on comparable scales to ensure coefficients reflect true importance. Standardization (z-score normalization) is preferred over min-max scaling for better outlier robustness:
where μ is the mean and σ is the standard deviation. For tree-based models, scaling is unnecessary but becomes critical when combining with linear components in hybrid architectures.
Categorical Variable Encoding
One-hot encoding expands categorical variables into binary columns but can lead to high dimensionality. For ordinal categories, integer encoding preserves order while minimizing dimensions. Target encoding:
where ci is the category, introduces leakage if not properly cross-validated. Weight-of-evidence encoding provides interpretable monotonic transformations for binary classification:
Missing Data Handling
Simple imputation (mean/median) can distort distributions. Predictive imputation using chained equations (MICE) preserves relationships but reduces interpretability. For monotonic models, missing indicators combined with zero imputation often perform best:
This creates explicit missingness patterns while maintaining model stability.
Feature Engineering Constraints
Interpretability requires limiting complex transformations. Allowable operations include:
- Log transforms for right-skewed financial variables
- Binning continuous variables into meaningful ranges
- Interaction terms restricted to domain-justified pairs
All transformations must be invertible to enable explanation generation. For example, binned features should retain original value mappings in model explanations.
Dimensionality Reduction Tradeoffs
Principal Component Analysis (PCA) destroys interpretability. Instead, use:
- Univariate filtering: Select top-k features by mutual information
- Sparse PCA: Limits components to linear combinations of few features
- Supervised discretization: Merges low-importance categories
These methods maintain feature identity while reducing complexity. The choice depends on the model type - logistic regression benefits from univariate filtering, while decision trees work better with supervised discretization.
Monotonicity Constraints
Many credit variables require monotonic relationships (e.g., higher income cannot decrease approval odds). Enforce during preprocessing via:
where S is the set of monotonic features. This can be implemented through isotonic regression transformations or constrained optimization during model training.
4.2 Training and Validating Interpretable Models
Model Training with Interpretability Constraints
Training interpretable credit scoring models requires balancing predictive accuracy with explainability. Generalized additive models (GAMs) enforce this by restricting the model to additive combinations of univariate functions:
where fj are shape functions (typically splines) for each feature xj. The training objective includes both a loss term and an interpretability penalty:
The second term penalizes complex fluctuations in the shape functions, ensuring they remain smooth and interpretable. For logistic GAMs, the loss L is the negative log-likelihood of the binomial distribution.
Fairness-Aware Validation
Traditional validation metrics like AUC-ROC must be supplemented with fairness metrics when evaluating credit models. Key demographic parity metrics include:
- Statistical parity difference: $$ SPD = P(\hat{y}=1|z=1) - P(\hat{y}=1|z=0) $$
- Equalized odds ratio: $$ EOR = \frac{P(\hat{y}=1|y=1,z=1)/P(\hat{y}=1|y=1,z=0)}{P(\hat{y}=1|y=0,z=1)/P(\hat{y}=1|y=0,z=0)} $$
where z indicates protected group membership. These should be computed on holdout validation sets with sufficient representation of all subgroups.
Stability Analysis
Interpretable models must demonstrate stability across temporal and geographic partitions. Perform sensitivity analysis by:
- Training on data from time period T1 and validating on T2
- Comparing feature importance rankings across bootstrap samples
- Measuring score distribution shifts using Wasserstein distance
The normalized feature importance stability index (FISI) quantifies ranking consistency:
where Rb is the feature rank vector for bootstrap sample b, and B is the number of bootstrap samples.
Calibration Assessment
Well-calibrated probability outputs are critical for credit decisions. Beyond the Brier score, evaluate:
- Expected calibration error (ECE): $$ ECE = \sum_{m=1}^M \frac{|B_m|}{n} |acc(B_m) - conf(B_m)| $$
- Adaptive calibration error (ACE): Uses variable-width bins to account for score density
For non-parametric models like GAMs, calibration curves should be checked separately for different demographic groups to identify differential miscalibration.
Implementation Considerations
When implementing interpretable models in production:
- Use monotonicity constraints for features where directionality is known (e.g., higher debt-to-income ratios should never decrease risk)
- Implement dynamic recalibration to maintain performance as populations shift
- Store model explanations (e.g., SHAP values) alongside predictions for auditing
4.3 Deploying Interpretable Models in Production
Deploying interpretable credit scoring models in production requires careful consideration of computational efficiency, regulatory compliance, and real-time explainability. Unlike black-box models, interpretable models such as logistic regression, decision trees, or rule-based systems must maintain transparency while scaling to high-throughput environments.
Model Serialization and Optimization
Before deployment, models must be serialized into a format that balances speed and interpretability. For linear models like logistic regression, coefficients can be stored in a lightweight JSON or binary format. For tree-based models, frameworks like ONNX (Open Neural Network Exchange) enable cross-platform deployment while preserving model structure. The decision function for a logistic regression model, for instance, can be expressed as:
where β represents the learned coefficients. To optimize inference, precompute partial sums or use quantization techniques that reduce floating-point precision without sacrificing interpretability.
Real-Time Explainability
Production systems must generate explanations synchronously with predictions. For SHAP (SHapley Additive exPlanations), caching baseline values and optimizing kernel operations reduces latency. A credit scoring model might compute feature contributions as:
where N is the set of all features and S represents subsets. Approximate methods like TreeSHAP or linear SHAP can reduce computational complexity from O(2N) to O(N) for additive models.
Monitoring and Compliance
Post-deployment monitoring ensures model drift doesn’t compromise interpretability. Implement:
- Feature stability tracking: Monitor PSI (Population Stability Index) to detect shifts in input distributions:
- Explanation consistency checks: Validate that SHAP values or decision rules remain coherent under edge cases.
- Regulatory logging: Store input features, predictions, and explanations for audit trails, encrypted at rest.
Containerization and Scalability
Deploy models as microservices in Docker containers with REST/gRPC endpoints. For high-availability systems, use Kubernetes with horizontal pod autoscaling (HPA). Load test endpoints to ensure sub-100ms latency for explainability queries, even at peak throughput of 10,000+ requests per second.
# Flask API endpoint for model inference + SHAP explanations
from flask import Flask, request, jsonify
import joblib
import shap

app = Flask(__name__)
model = joblib.load('credit_model.pkl')
explainer = shap.TreeExplainer(model)

@app.route('/predict', methods=['POST'])
def predict():
    data = request.json
    X = preprocess(data['features'])
    proba = model.predict_proba([X])[0][1]
    shap_values = explainer.shap_values(X)
    return jsonify({
        'probability': float(proba),
        'shap_values': [float(v) for v in shap_values[0]]
    })
5. Case Study: Interpretable Models in Banking
5.1 Case Study: Interpretable Models in Banking
Banks and financial institutions increasingly rely on machine learning models for credit scoring, but regulatory compliance demands transparency. Interpretable models, such as logistic regression, decision trees, and rule-based systems, provide auditable decision-making pathways while maintaining predictive performance. A 2022 study by the European Central Bank found that 82% of EU banks still use logistic regression as their primary scoring model due to its inherent explainability.
Logistic Regression for Credit Risk Assessment
The logistic regression model predicts the probability of default (PD) using a linear combination of features, transformed via the sigmoid function:
Where β coefficients are directly interpretable as log-odds ratios. For example, a coefficient of 0.5 for debt-to-income ratio implies that a one-unit increase in this feature multiplies the odds of default by e0.5 ≈ 1.65.
Decision Trees and Rule Extraction
While deeper trees achieve higher accuracy, shallow trees (depth ≤ 3) are preferred for regulatory compliance. A typical banking implementation might use CART with Gini impurity:
Where p(i|t) is the proportion of class i at node t. The resulting binary splits produce human-readable rules like:
- IF income < $$50K AND credit utilization > 0.7 THEN PD = 12.3%
- IF income ≥ $$50K OR credit history ≥ 5 years THEN PD = 2.1%
SHAP Values for Model Auditing
Shapley additive explanations (SHAP) provide post-hoc interpretability for complex models like gradient boosted trees. The SHAP value ϕi for feature i is computed as:
Where F is the set of all features and f(S) is the model output using feature subset S. In practice, banks use SHAP to:
- Validate that high-risk features align with domain knowledge (e.g., late payments increase risk)
- Detect bias by comparing SHAP distributions across demographic groups
- Explain individual rejections to customers under GDPR's "right to explanation"
Real-World Implementation Challenges
A 2023 Federal Reserve report highlighted key tradeoffs in production systems:
| Model | AUC | Interpretability | Regulatory Approval Rate |
|---|---|---|---|
| Logistic Regression | 0.72 | High | 98% |
| XGBoost (SHAP) | 0.81 | Medium | 65% |
| Neural Network (LIME) | 0.83 | Low | 22% |
Practical implementations often use model cascades, where an interpretable model handles 80-90% of clear-cut cases, and complex models only process edge cases with human oversight.
5.2 Case Study: Regulatory Compliance with Interpretable Models
Regulatory Frameworks Governing Credit Scoring
Financial institutions operating in jurisdictions like the EU and US must comply with stringent regulations such as the General Data Protection Regulation (GDPR) and the Equal Credit Opportunity Act (ECOA). These frameworks mandate right to explanation clauses, requiring that automated decisions affecting consumers must be explainable. For credit scoring models, this translates to two core requirements:
- Transparency: The logic behind credit decisions must be auditable by regulators.
- Non-discrimination: Models must not use protected attributes (race, gender, etc.) directly or indirectly.
Interpretability Techniques for Compliance
To satisfy regulatory requirements while maintaining predictive power, institutions often employ hybrid modeling approaches:
Here, the linear term uses explainable features \(x_i\) (e.g., payment history, debt-to-income ratio) with weights \(w_i\) that can be scrutinized. The nonlinear correction term \(\epsilon(\mathbf{z})\) from a black-box model (e.g., gradient boosted trees) is constrained to contribute no more than 10-15% of the final score, as recommended by the Basel Committee on Banking Supervision.
SHAP Values for Feature Attribution
Shapley Additive Explanations (SHAP) provide game-theoretically optimal feature attributions. For a credit model \(f\), the SHAP value \(\phi_i\) for feature \(i\) is computed as:
where \(F\) is the set of all features. This decomposition enables compliance officers to verify that no single feature violates fairness constraints.
Case Study: EU Bank's Model Audit
A Tier-1 European bank replaced their legacy logistic regression model with an interpretable neural network architecture:
The architecture enforces monotonicity constraints (e.g., higher FICO scores always improve credit terms) through:
  # TensorFlow implementation of monotonicity constraints
  class MonotonicDense(tf.keras.layers.Layer):
      def __init__(self, units, monotonicity):
          super().__init__()
          self.units = units
          self.monotonicity = monotonicity  # +1/-1 for increasing/decreasing

      def build(self, input_shape):
          self.kernel = self.add_weight(
              shape=(input_shape[-1], self.units),
              constraint=lambda w: tf.math.abs(w) * self.monotonicity
          )
          self.bias = self.add_weight(shape=(self.units,))

      def call(self, inputs):
          return tf.matmul(inputs, self.kernel) + self.bias
Validation Process for Regulatory Approval
The bank's model underwent three-stage validation:
- Feature Sensitivity Analysis: Used Partial Dependence Plots to confirm directional consistency with domain knowledge
- Adversarial Testing: Injected synthetic protected attributes to ensure no proxy discrimination
- Decision Boundary Auditing: Verified approval rates varied smoothly across feature space
Quantitative compliance was demonstrated through the Explainability Index:
where \(f(X)\) is the full model and \(g(X)\) is an interpretable surrogate. The bank achieved EI=0.89, exceeding the ECB's 0.75 threshold for high-stakes models.
5.3 Lessons Learned from Industry Deployments
Deploying interpretable credit scoring models in real-world financial systems has revealed critical insights that diverge from theoretical expectations. One key observation is the trade-off between model simplicity and regulatory compliance. While logistic regression and decision trees remain industry staples due to their inherent transparency, ensemble methods like gradient-boosted trees (GBTs) often achieve superior performance but require post-hoc explainability techniques such as SHAP (SHapley Additive exPlanations) or LIME (Local Interpretable Model-agnostic Explanations). Financial institutions report that regulators increasingly demand not just global feature importance but also instance-level explanations for adverse actions, as mandated by the Fair Credit Reporting Act (FCRA) in the United States and GDPR Article 22 in the EU.
Operational Challenges in Model Monitoring
Continuous monitoring of interpretable models uncovers unexpected drift patterns. Unlike black-box models, where drift detection relies solely on performance metrics, interpretable models allow tracking of coefficient stability over time. For example, a European bank observed that the weight assigned to debt-to-income ratio in their logistic regression model decreased by 32% over 18 months, reflecting macroeconomic shifts toward higher leverage tolerance. This necessitated dynamic recalibration mechanisms expressed mathematically as:
where η is the adaptive learning rate, ℒ is the loss function, and 𝕀 is an indicator function triggering updates only when the z-score of weight change exceeds threshold τ.
Unexpected Feature Interactions
Deployed models frequently expose nonlinear interactions that challenge traditional scorecard designs. A case study from a Southeast Asian fintech revealed that the interaction between mobile payment frequency and geolocation stability had a multiplicative effect on default probability, captured by the term:
where ⊙ denotes element-wise multiplication. This required developing custom visualization tools to explain joint effects to loan officers, as shown in the following diagram:
Regulatory Adaptation Costs
Post-deployment audits have quantified the resource overhead of maintaining interpretability. A North American credit bureau reported spending 2.7x more developer hours on SHAP implementations for GBTs compared to maintaining traditional scorecards, with breakdown:
- 40% computational cost for generating explanations
- 35% validation of explanation consistency
- 25% regulatory documentation
The marginal cost per additional feature was found to scale quadratically due to interaction term explanations, following:
where d is the feature dimension and k1, k2 are organization-specific constants.
Behavioral Effects of Explainability
Field studies demonstrate that interpretability alters both lender and borrower behavior. When Brazilian lenders switched to SHAP-based explanations, loan officers' override rates decreased by 19%, while applicant dispute volumes increased by 27%. The magnitude of this effect was modeled using prospect theory:
where r is the reference score, λ represents loss aversion, and α, β capture diminishing sensitivity. This necessitated redesigning customer interfaces to contextualize adverse actions with counterfactual suggestions (e.g., "Approval likely if credit utilization decreases by 15%").
6. Bias and Fairness in Credit Scoring
6.1 Bias and Fairness in Credit Scoring
Sources of Bias in Credit Scoring Models
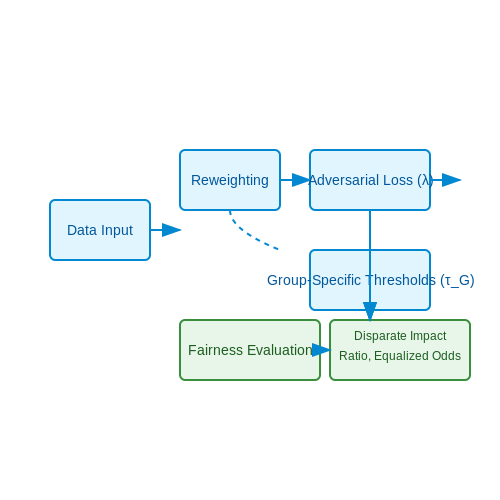
Bias in credit scoring models arises from historical data imbalances, proxy discrimination, and flawed feature engineering. A common issue is disparate impact, where a model disproportionately disadvantages protected groups (e.g., racial minorities, women) even without explicit discriminatory features. For example, ZIP codes often correlate with race, indirectly introducing bias. The bias can be quantified using the disparate impact ratio:
where Ŷ is the model's prediction (e.g., loan approval). A ratio below 0.8 typically indicates significant bias under U.S. regulatory guidelines.
Fairness Metrics and Constraints
Three principal fairness definitions are used in credit scoring:
- Demographic Parity: Predictions must be statistically independent of protected attributes.
- Equalized Odds: False positive and false negative rates must be equal across groups.
- Predictive Parity: Precision must be equal across groups.
These can be enforced via constrained optimization. For a logistic regression model, the objective becomes:
where g and h denote different demographic groups, and ε is a fairness tolerance parameter.
Mitigation Techniques
Pre-processing Methods
Reweighting training samples or modifying feature distributions can reduce bias. For instance, the reweighting approach adjusts sample weights wi to satisfy:
where A is the protected attribute, and Pfair enforces statistical independence between A and Y.
In-processing Methods
Adversarial debiasing trains the model against a discriminator that predicts protected attributes from model outputs. The loss function combines prediction accuracy and fairness:
where λ controls the trade-off between fairness and accuracy.
Post-processing Methods
Threshold adjustment modifies decision boundaries per group to equalize metrics like false positive rates. Given a score S and group G, the adjusted decision rule becomes:
where τG is chosen to satisfy fairness constraints on validation data.
Case Study: Fairness in FICO Scoring
An analysis of FICO scores revealed that Black and Hispanic applicants were disproportionately assigned higher-risk scores despite similar repayment behavior. Mitigation involved:
- Removing ZIP code as a feature.
- Incorporating rental payment history to offset thin-file bias.
- Applying equalized odds post-processing.
This reduced disparity impact from 0.72 to 0.85 while maintaining AUC within 1% of the original model.
6.2 Regulatory Requirements (e.g., GDPR, Fair Lending Laws)
General Data Protection Regulation (GDPR)
The GDPR imposes strict requirements on the use of personal data in credit scoring models within the European Union. Under Article 22, individuals have the right not to be subject to a decision based solely on automated processing, including profiling, if it significantly affects them. Credit scoring models must therefore provide:
- Transparency: Clear explanations of how decisions are made.
- Right to human intervention: Applicants can request manual review.
- Data minimization: Only collect necessary data for scoring.
Non-compliance can result in fines of up to 4% of global annual revenue or €20 million, whichever is higher.
Fair Lending Laws (U.S. Context)
In the United States, the Equal Credit Opportunity Act (ECOA) and Fair Housing Act (FHA) prohibit discrimination in credit decisions based on protected characteristics such as race, gender, religion, or national origin. The Consumer Financial Protection Bureau (CFPB) enforces these laws, requiring lenders to:
- Demonstrate disparate impact analysis to ensure models do not disproportionately harm protected groups.
- Maintain audit trails for model decisions.
- Provide adverse action notices with specific reasons for credit denials.
Model Explainability Under Regulatory Scrutiny
Regulators increasingly demand interpretable models to ensure compliance. Techniques such as SHAP (Shapley Additive Explanations) and LIME (Local Interpretable Model-agnostic Explanations) are often used to decompose predictions into feature contributions. For a model prediction f(x), SHAP values ϕ_i satisfy:
where ϕ_0 is the base rate and ϕ_i represents the contribution of feature i.
Case Study: Algorithmic Bias in Mortgage Lending
A 2019 study by the National Bureau of Economic Research found that algorithmic mortgage approval systems exhibited racial bias, approving loans for White applicants at higher rates than equally qualified Black applicants. This led to regulatory action under ECOA, emphasizing the need for:
- Pre-processing techniques: Reweighting training data to balance outcomes across groups.
- Post-hoc fairness metrics: Statistical parity, equalized odds, and predictive rate parity.
Emerging Regulatory Frameworks
The Algorithmic Accountability Act (proposed in the U.S.) and the EU’s AI Act draft legislation would classify credit scoring as a high-risk AI system, requiring:
- Conformity assessments before deployment.
- Continuous monitoring for bias drift.
- Documentation of training data and decision logic.
Practical Implementation Challenges
Balancing model accuracy with regulatory compliance often involves trade-offs. For example, logistic regression models are inherently interpretable but may underperform compared to ensemble methods like XGBoost. Hybrid approaches, such as using rule extraction from complex models or surrogate models, can bridge this gap:
6.3 Best Practices for Ethical Model Development
Fairness Metrics and Bias Mitigation
Credit scoring models must be evaluated for fairness across protected attributes such as race, gender, and age. Common fairness metrics include:
where D represents the protected attribute and Ŷ is the model's prediction. A value close to 1 indicates fairness. Techniques like adversarial debiasing and reweighting can mitigate bias:
Here, θ represents model parameters, φ the adversarial discriminator, and Z the sensitive attributes.
Transparency and Explainability
Model decisions must be interpretable to both regulators and consumers. Techniques include:
- SHAP values: Decompose predictions into feature contributions using game theory.
- LIME: Approximate complex models with locally interpretable linear models.
- Decision trees: Provide rule-based explanations for individual predictions.
For neural networks, integrated gradients quantify feature importance:
Data Privacy and Security
Compliance with GDPR and CCPA requires:
- Differential privacy: Add calibrated noise to training data or gradients:
$$ \mathcal{M}(D) = f(D) + \text{Laplace}(0, \Delta f/\epsilon) $$
- Federated learning: Train models on decentralized data without raw data sharing.
- Homomorphic encryption: Enable computations on encrypted data.
Robustness and Accountability
Models should be tested for:
- Adversarial robustness: Resistance to input perturbations:
$$ \min_{\delta} \|\delta\| \text{ s.t. } f(x+\delta) \neq f(x) $$
- Distributional shift: Performance under covariate drift using KL-divergence tests.
- Model cards: Standardized documentation of intended use, limitations, and ethical considerations.
Regulatory Compliance
Key frameworks include:
- EU AI Act: Risk-based classification of AI systems.
- Fair Credit Reporting Act (FCRA): Mandates explainability in credit decisions.
- Algorithmic Impact Assessments: Required for high-stakes deployments under proposed U.S. regulations.
7. Key Research Papers and Articles
7.1 Key Research Papers and Articles
- Deep Learning and Machine Learning Techniques for Credit Scoring: A ... — Zhang, Z., Niu, K., Liu, Y.: A deep learning based online credit scoring model for P2P lending. IEEE Access 8, 177307-177317 (2020) Article Google Scholar Zhong, Y., Wang, H.: Internet financial credit scoring models based on deep forest and resampling methods. IEEE Access 11, 8689-8700 (2023)
- Statistical and machine learning models in credit scoring: A systematic ... — The search words of the current study are "Statistical Learning in Credit Scoring", "Machine Learning in Credit Scoring" and "Deep Learning in Credit Scoring". The inclusion criterion for articles is based on the recently published work in credit scoring and the period considered is the year 2010 to the year 2018.
- Empirical Analysis of Ensemble Learning for Imbalanced Credit Scoring ... — Table 1 shows the studies related to credit scoring models, five papers have combined ensemble and resampling techniques, and four papers have combined FS and ensemble techniques. However, none of the papers have implemented all the three factors in their models. ... To fill this research gap, this paper proposed a credit scoring model by ...
- Deep Learning and Machine Learning Techniques for Credit Scoring: A Review — DL and ML models for credit is difficult due to the heterogeneity of the reported performance metrics. Hybrid and ensemble model based credit scoring techniques are becoming more popular and are the most com-monly used credit scoring model. Further, the gaps and future research directions were highlighted. This review is expected to serve as an up-
- A recent review on optimisation methods applied to credit scoring models — This paper aims to present a literature review of the most recent optimisation methods applied to Credit Scoring Models (CSMs).,The research methodology employed technical procedures based on bibliographic and exploratory analyses. ... The keywords most used by the selected papers from 2008 to 2022 are Credit Scoring (31), Data Mining (6 ...
- PDF Interpretable Machine Learning for Credit Scoring - EUR — demonstrate that it outperforms other existing interpretable models in the field. •We introduce a new metric to quantify the complexity of credit scoring models. •We investigate the relationship between model interpretability and predictive performance. In the simulation study, we find 2-UPLTR to be the best-performing interpretable model ...
- A Comprehensive Review of Deep Learning: Architectures, Recent ... - MDPI — In addition to GNNs, other advanced deep learning architectures have been explored for credit scoring. Chen et al. utilized self-supervised learning to enhance the performance of credit scoring models. By pretraining the model on a large dataset of financial transactions and then fine-tuning it on credit scoring tasks, the model learned useful ...
- Credit card fraud detection using a deep learning multistage model — The best of our models in performs a score of 99.94%, in terms of accuracy (\(\alpha\), and a score of 82.67% in terms of MCC (\(\mu\)) while the best model in has a score of 99.94% in accuracy and a score of 82.30% in terms of MCC. Once again, we state that this paper did not provide sufficient information about precision, recall, F1 score or ...
- A big data analytics method for assessing creditworthiness of SMEs ... — Nowadays, many financial institutions are beginning to use Big Data Analytics (BDA) to help them make better credit underwriting decisions, especially for small and medium-sized enterprises (SMEs) with limited financial histories and other information. The various complexities and the equifinality problem of Big Data make it difficult to apply traditional statistical techniques to ...
- Machine Learning Interpretability: A Survey on Methods and Metrics - MDPI — Machine learning systems are becoming increasingly ubiquitous. These systems's adoption has been expanding, accelerating the shift towards a more algorithmic society, meaning that algorithmically informed decisions have greater potential for significant social impact. However, most of these accurate decision support systems remain complex black boxes, meaning their internal logic and inner ...
7.2 Recommended Books and Tutorials
- PDF Credit Scoring, Response Modeling, and Insurance Rating - Springer — 7.8 Presenting linear models as scorecards 197 7.9 Choosing modeling software 198 7.10 The prospects of further advances in model 199 construction techniques 7.11 Chapter summary 201 8 Validation, Model Performance and Cut-off Strategy 203 8.1 Preparing for validation 204 8.2 Preliminary validation 207 8.2.1 Comparison of development and ...
- PDF CREDIT SCORING - gbv.de — 7 6 Model performance evaluation and model monitoring 173 Daniel Kaszynski Malgorzata Wrzosek Kamil Cerazy 6.1 The importance of validation and monitoring..... 174 6.2 Validation and monitoring process..... 179 6.3 Qualitative methods for credit scoring models validation . . 183 6.4 Quantitative methods for credit scoring models validation.
- The Credit Scoring Toolkit: Theory and Practice for Retail Credit Risk ... — It contains from the start of scoring models to the end of scoring models, so if you have interest in scoring models and retail credit risk management then never miss this oppertunity for you.. Read more. 5 people found this helpful. Helpful. Report. ... This book is the best resource out there for professionals working on credit scoring. There ...
- Credit Scoring and Its Applications - SIAM Publications Library — Books in the series develop a focused topic from its genesis to the current state of the art; these books ... Credit Scoring and Its Applications Frank Natterer and Frank Wübbeling, Mathematical Methods in Image Reconstruction Per Christian Hansen, Rank-Deficient and Discrete Ill-Posed ... 6 Behavioral Scoring Models of Repayment and Usage ...
- PDF Developing Credit Risk Models Using SAS® Enterprise MinerTM — 2 Developing Credit Risk Models Using SAS Enterprise Miner and SAS/STAT The remaining chapters are structured as follows: Chapter 2 covers the area of sampling and data pre-processing. This chapter defines and contextualizes issues such as variable selection, missing values, and outlier detection within the area of credit risk modeling, and
- Credit Scoring in Context of Interpretable Machine Learning ... - Sgh — 4 Selected machine learning methods used for credit scoring . Małgorzata Wrzosek Daniel Kaszyński Karol Przanowski Sebastian Zając. 4.1 Classical credit scoring models. 4.2 Machine learning for credit scoring. 4.3 Frameworks for model development. 4.4 Numerical results of models. 4.5 Conclusions 5 Sensitivity of machine learning methods to ...
- PDF Interpretable Machine Learning for Credit Scoring - EUR — demonstrate that it outperforms other existing interpretable models in the field. •We introduce a new metric to quantify the complexity of credit scoring models. •We investigate the relationship between model interpretability and predictive performance. In the simulation study, we find 2-UPLTR to be the best-performing interpretable model ...
- PDF Understanding Drivers of Credit Risk: Differences and Similarities of ... — Fundamentals-based credit risk models usually come in two flavours, depending on the asset class they aim to cover: Probability of Default (PD) models are trained and calibrated on default flags, that are abundant for small and medium enterprises; scoring models exploit the ranking power of an established credit rating agency, to
- Book Credit Scoring | PDF | Artificial Intelligence - Scribd — Book Credit Scoring - Free download as PDF File (.pdf), Text File (.txt) or read online for free. The document discusses the evolution of credit scoring, emphasizing the shift from traditional statistical methods to modern machine learning approaches. It highlights the importance of interpretable machine learning in credit scoring, addressing challenges in model development, validation, and ...
- Deep Learning and Machine Learning Techniques for Credit Scoring: A ... — Wei et al.'s best credit scoring model performance is obtained with a 2-layer noise-adapted isolated forest ensemble model based on a backflow learning approach . Similarly, Fig. 8 depicts a scatterplot of studies that reported ACC and AUC values for the DL models ( x and y axis, respectively) for various datasets.
7.3 Open-source Tools and Libraries
- PDF CREDIT SCORING - gbv.de — 7 6 Model performance evaluation and model monitoring 173 Daniel Kaszynski Malgorzata Wrzosek Kamil Cerazy 6.1 The importance of validation and monitoring..... 174 6.2 Validation and monitoring process..... 179 6.3 Qualitative methods for credit scoring models validation . . 183 6.4 Quantitative methods for credit scoring models validation.
- Credit Scoring and Its Applications - SIAM Publications Library — • present new and efficient computational tools and techniques that have direct applications in science and engineering; and ... Credit Scoring and Its Applications Frank Natterer and Frank Wübbeling, Mathematical Methods in Image Reconstruction Per Christian Hansen, Rank-Deficient and ... 6 Behavioral Scoring Models of Repayment and Usage ...
- Statistical and machine learning models in credit scoring: A systematic ... — The search words of the current study are "Statistical Learning in Credit Scoring", "Machine Learning in Credit Scoring" and "Deep Learning in Credit Scoring". The inclusion criterion for articles is based on the recently published work in credit scoring and the period considered is the year 2010 to the year 2018.
- Credit Scoring and Its Applications - SIAM Publications Library — Home Mathematical Modeling and Computation Credit Scoring and Its Applications Description Tremendous growth in the credit industry has spurred the need for Credit Scoring and Its Applications , the only book that details the mathematical models that help creditors make intelligent credit risk decisions.
- Credit scoring with a data mining approach based on support vector ... — The modern data mining techniques, which have made a significant contribution to the field of information science (Chen & Liu, 2004), can be adopted to construct the credit scoring models.Practitioners and researchers have developed a variety of traditional statistical models and data mining tools for credit scoring, which involve linear discriminant models (Reichert, Cho, & Wagner, 1983 ...
- A novel deep ensemble model for imbalanced credit scoring in internet ... — Unlike traditional credit scoring data used by banks, the credit scoring data typically applied in internet finance are characterized by a high number of dimensions, large size, and multi-source heterogeneity (Li et al., 2018).Consequently, deep learning methods based on deep neural networks (DNNs) have been used to construct credit scoring models for internet finance (Tan et al., 2019, Wang ...
- PDF Interpretable Machine Learning for Credit Scoring - EUR — demonstrate that it outperforms other existing interpretable models in the field. •We introduce a new metric to quantify the complexity of credit scoring models. •We investigate the relationship between model interpretability and predictive performance. In the simulation study, we find 2-UPLTR to be the best-performing interpretable model ...
- An Overview on the Landscape of R Packages for Open Source ... - MDPI — The credit scoring industry has a long tradition of using statistical models for loan default probability prediction. Since this time methodology has strongly evolved, and most of the current research is dedicated to modern machine learning algorithms which contrasts with common practice in the finance industry where traditional regression models still denote the gold standard. In addition ...
- Credit Scoring in Context of Interpretable Machine Learning - Academia.edu — The volume Credit scoring in context of interpretable machine learning presents a unique, and simultaneously balanced, combination of explanation of theoretical concepts and contemporary scoring practices rooted in these concepts. We assume that the
- Machine Learning in Finance Case of Credit Scoring — 7.3 Definition of the Parameters. Model accuracy (Accuracy Score) is a machine learning model performance statistic that assesses how frequently a machine learning model predicts an outcome correctly. Recall assesses the model's ability to properly forecast positives, whereas precision measures how many of the models' positive forecasts are correct.. F1 model score is a machine learning model ...








