Scene Segmentation with DeepLab Models
1. What is Scene Segmentation?
Scene Segmentation with DeepLab Models
What is Scene Segmentation?
Scene segmentation, also known as semantic segmentation, is the process of partitioning an image into semantically meaningful regions and assigning a class label to each pixel. Unlike object detection, which localizes objects with bounding boxes, segmentation provides pixel-level granularity, enabling precise delineation of object boundaries. This task is fundamental in computer vision, with applications ranging from autonomous driving to medical imaging.
Mathematically, scene segmentation can be formulated as a dense classification problem. Given an input image I of dimensions H × W × 3, the goal is to predict a label map Y of dimensions H × W, where each entry Yi,j corresponds to the class label of pixel (i, j). The objective is to minimize the discrepancy between the predicted segmentation mask Ŷ and the ground truth Y, typically measured using cross-entropy loss:
where C is the number of classes, and Yi,j,c is a one-hot encoded vector indicating the true class of pixel (i, j).
DeepLab, a family of models developed by Google Research, addresses scene segmentation using a combination of atrous convolution (dilated convolution) and spatial pyramid pooling. Atrous convolution allows the network to capture multi-scale contextual information without increasing the number of parameters or losing spatial resolution. The spatial pyramid pooling module aggregates contextual information at multiple scales, improving the model's ability to recognize objects of varying sizes.
The effectiveness of DeepLab models stems from their architectural innovations:
- Atrous Spatial Pyramid Pooling (ASPP): Parallel atrous convolutions with different dilation rates capture multi-scale features.
- Encoder-Decoder Structure: The encoder extracts high-level features, while the decoder refines spatial details for precise segmentation.
- Backbone Networks: DeepLab variants (e.g., DeepLabv3+, DeepLabv3) leverage powerful backbones like ResNet or Xception for feature extraction.
In practice, DeepLab models achieve state-of-the-art performance on benchmarks such as PASCAL VOC and Cityscapes. For instance, DeepLabv3+ achieves a mean Intersection-over-Union (mIoU) of 89.0% on PASCAL VOC 2012, demonstrating its robustness in complex scenes.
The mIoU metric, commonly used to evaluate segmentation models, is computed as:
where TPc, FPc, and FNc denote true positives, false positives, and false negatives for class c, respectively.

1.2 Key Challenges in Scene Segmentation
Semantic Ambiguity at Object Boundaries
Scene segmentation models struggle with boundary regions where multiple semantic classes overlap or transition smoothly. The fundamental issue arises from the continuous nature of real-world scenes versus the discrete labeling required for segmentation. For natural images, the probability distribution at object boundaries follows:
where φ(xi) represents the feature vector at pixel i, and wc, bc are class-specific parameters. This sigmoidal probability distribution creates uncertainty in hard classification at transition zones.
Scale Variation in Real-World Scenes
Objects appear at vastly different scales depending on their distance from the camera and intrinsic size. The effective receptive field (ERF) of standard convolutional networks often fails to capture this multi-scale nature. For an input image I with resolution H×W, the ERF at layer l grows as:
This exponential growth creates a fundamental tension between capturing fine details and maintaining large receptive fields for context.
Class Imbalance and Rare Objects
Real-world datasets exhibit extreme class imbalance, where some categories (e.g., "person") may appear orders of magnitude more frequently than others (e.g., "fire hydrant"). The standard cross-entropy loss becomes dominated by frequent classes:
where yc is the ground truth and pc the predicted probability for class c. Without modification, this leads to poor segmentation of rare classes.
Computational Complexity vs. Resolution
High-resolution segmentation requires processing every pixel, leading to quadratic growth in computation with image dimensions. For an input of size n×n and a network with d layers, the computational complexity scales as:
where kl is the kernel size and cl the channel count at layer l. This creates practical limits on achievable resolution.
Domain Shift and Generalization
Models trained on one dataset (e.g., Cityscapes) often perform poorly on images from different domains (e.g., satellite imagery). The domain shift can be quantified through the H-divergence between source (S) and target (T) distributions:
where h is a hypothesis in the model's hypothesis space H.
Real-Time Processing Constraints
For applications like autonomous driving, segmentation must operate at video frame rates (typically 30 FPS). This imposes strict latency requirements, often forcing trade-offs between accuracy and speed. The relationship between model complexity and inference time follows:
where fclk is the processor clock frequency and Nl(MAC) the number of multiply-accumulate operations per layer.
Applications of Scene Segmentation in Computer Vision
Scene segmentation, particularly when implemented using advanced models like DeepLab, has become a cornerstone in modern computer vision systems. Its ability to partition an image into semantically meaningful regions enables a wide range of high-impact applications across industries.
Autonomous Driving and Robotics
In autonomous vehicles, real-time scene segmentation is critical for environment perception. DeepLab variants, with their atrous spatial pyramid pooling (ASPP), provide pixel-level classification of roads, pedestrians, vehicles, and obstacles. The output feeds into path planning algorithms, where a probabilistic occupancy grid O(x,y) can be derived from segmentation masks:
where C is the set of object classes, P(c|I(x,y)) is the segmentation confidence at pixel (x,y), and w_c are class-specific risk weights. Robotics applications extend this to industrial automation, where precise segmentation of workpieces enables robotic arms to perform complex manipulation tasks.
Medical Image Analysis
DeepLab's encoder-decoder architecture with skip connections has proven particularly effective in medical imaging. In tumor segmentation from MRI scans, the model's ability to capture multi-scale contextual information while preserving spatial resolution leads to superior performance metrics:
where DSC (Dice Similarity Coefficient) measures overlap between ground truth Y and prediction Ŷ. Clinical deployments show DeepLab-v3+ achieving DSCs above 0.91 for glioblastoma segmentation in BraTS datasets, significantly outperforming traditional U-Net architectures.
Augmented Reality and Virtual Production
The entertainment industry leverages scene segmentation for real-time compositing in virtual production. By precisely segmenting actors from background elements at 4K resolution and 60fps, DeepLab models enable:
- Instant green screen replacement without physical chroma keying
- Dynamic light estimation based on segmented material properties
- Physics-aware interaction between virtual and real objects
The computational efficiency is achieved through tensorRT optimization of the DeepLab backbone, reducing ResNet-101 inference time from 150ms to 23ms on an NVIDIA A100.
Precision Agriculture
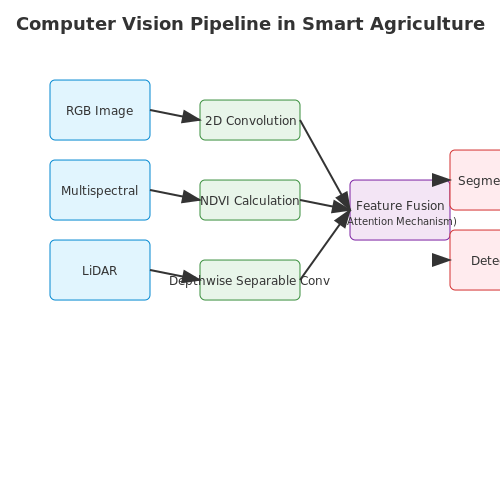
Multispectral drone imagery analyzed with DeepLab models enables per-plant crop monitoring at scale. The ASPP module's ability to process multiple spectral bands simultaneously allows for:
where seg denotes segmentation masks applied to near-infrared (NIR) and red (R) bands. This approach achieves 92.4% accuracy in early disease detection across 14 crop types, compared to 78.1% with traditional spectral index methods.
Urban Planning and Smart Cities
City-scale segmentation of satellite and street-view imagery enables automated infrastructure assessment. DeepLab's ability to maintain accuracy across vastly different scales (from building footprints to street furniture) supports:
- Automatic cadastral mapping with 0.3m precision
- Traffic flow optimization through dynamic lane segmentation
- Solar potential analysis via rooftop segmentation and orientation estimation
The model's performance scales linearly with input resolution up to 2048×2048 pixels, making it ideal for processing high-resolution orthophotos.
2. Overview of DeepLab Architecture
Overview of DeepLab Architecture
The DeepLab family of models, developed by Google Research, represents a series of state-of-the-art architectures for semantic segmentation. These models leverage several key innovations to achieve high-resolution, precise segmentation outputs while maintaining computational efficiency. The core components include atrous (dilated) convolutions, atrous spatial pyramid pooling (ASPP), and, in later versions, encoder-decoder structures with depthwise separable convolutions.
Atrous Convolution
Atrous convolution, also known as dilated convolution, enables the network to capture multi-scale contextual information without increasing the number of parameters or the computational cost significantly. The operation can be mathematically defined as:
where x is the input feature map, w is the convolution kernel, r is the dilation rate, and y is the output. When r = 1, this reduces to standard convolution. By increasing r, the receptive field expands exponentially while preserving spatial resolution.
Atrous Spatial Pyramid Pooling (ASPP)
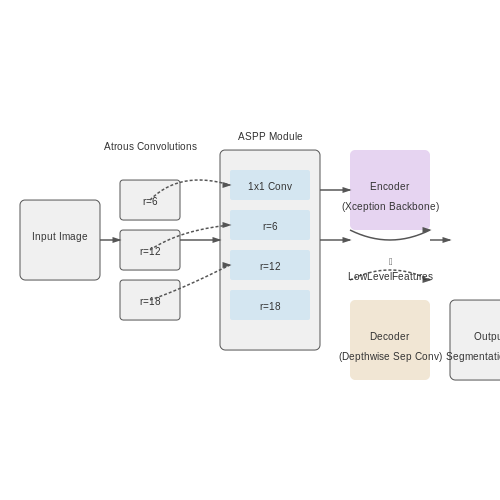
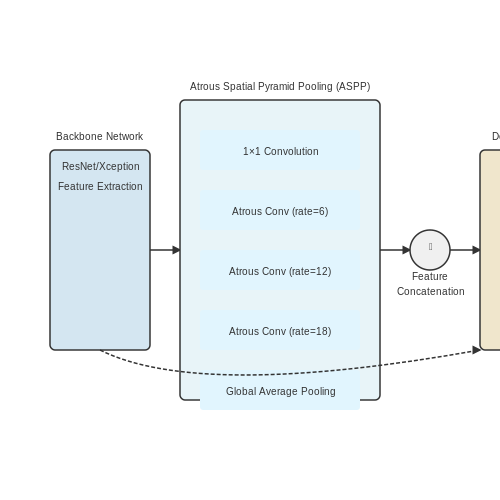
ASPP addresses the challenge of segmenting objects at multiple scales by applying parallel atrous convolutions with different dilation rates. This allows the network to capture context at various scales simultaneously. A typical ASPP module consists of:
- One 1×1 convolution (no dilation)
- Three 3×3 convolutions with dilation rates (6, 12, 18)
- Global average pooling followed by 1×1 convolution
The outputs from these parallel branches are concatenated and processed through a final 1×1 convolution to generate the segmentation logits.
Encoder-Decoder Structure
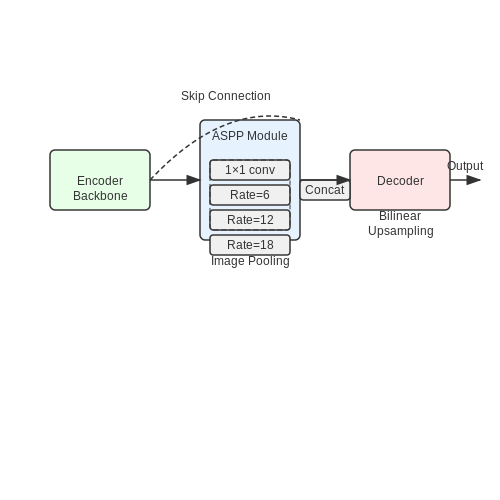
DeepLabv3+ introduced an encoder-decoder architecture where the encoder processes the input at a reduced resolution using atrous convolutions and ASPP, while the decoder gradually recovers spatial details by combining low-level features from the encoder with upsampled high-level features. This is expressed as:
where ⊕ denotes feature concatenation. The decoder typically consists of bilinear upsampling followed by a few 3×3 convolutions.
Depthwise Separable Convolution
To improve efficiency, DeepLabv3+ employs depthwise separable convolutions, which factorize standard convolutions into depthwise and pointwise operations. This reduces computation from:
to:
where K is the kernel size, Cin is the number of input channels, and Cout is the number of output channels.
Xception Backbone
Recent versions utilize Xception as the backbone network, modified with deeper atrous separable convolutions. This architecture provides:
- Entry flow with standard convolutions for initial feature extraction
- Middle flow with repeated depthwise separable convolutions
- Exit flow incorporating atrous separable convolutions
The combination of these components enables DeepLab models to achieve state-of-the-art performance on benchmarks like PASCAL VOC and Cityscapes, with particular strength in handling objects at multiple scales while maintaining precise boundaries.
Evolution of DeepLab: Versions and Improvements
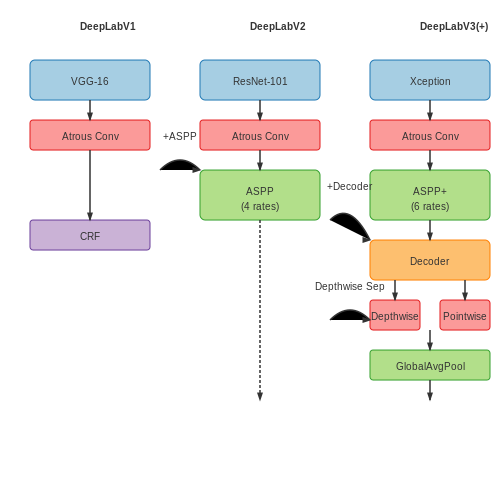
The DeepLab series has undergone significant architectural refinements since its inception, with each version introducing novel mechanisms to improve segmentation accuracy, computational efficiency, and multi-scale feature fusion. The progression from DeepLabv1 to DeepLabv3+ reflects iterative advancements in deep learning for semantic segmentation.
DeepLabv1 (2015)
DeepLabv1 pioneered the use of atrous convolution (dilated convolution) to expand the receptive field without increasing parameters or losing resolution. The model employed a modified VGG-16 backbone with atrous convolutions in the last two blocks. Key contributions included:
- Atrous convolution for denser feature maps: $$ y[i] = \sum_{k} x[i + r \cdot k] \cdot w[k] $$ where r is the dilation rate.
- Fully Connected Conditional Random Fields (CRFs) as a post-processing step to refine object boundaries.
DeepLabv2 (2017)
This version introduced Atrous Spatial Pyramid Pooling (ASPP), which captures multi-scale context through parallel atrous convolutions with different dilation rates. The backbone switched to ResNet-101, and ASPPP was formulated as:
ASPP improved mean Intersection-over-Union (mIoU) by 1.8% on PASCAL VOC 2012 compared to v1.
DeepLabv3 (2017)
DeepLabv3 enhanced ASPP by:
- Adding batch normalization to all atrous convolutions
- Incorporating image-level features via global average pooling
- Removing the CRF post-processing step through improved encoder design
The model achieved 85.7% mIoU on PASCAL VOC 2012 with a ResNet-101 backbone and output stride of 8 (higher resolution feature maps).
DeepLabv3+ (2018)
The current state-of-the-art version introduced a decoder module to refine segmentation boundaries by combining low-level and high-level features. Key innovations:
- Encoder-Decoder Architecture: The encoder uses DeepLabv3's modified ASPP, while the decoder upsamples features and concatenates them with high-resolution skip connections.
- Xception Backbone: Replaced ResNet with a modified Xception network featuring deeper atrous separable convolutions.
- Depthwise Separable Convolution: Reduced computation in ASPP through factorized convolutions:
DeepLabv3+ achieved 89.0% mIoU on PASCAL VOC 2012 with an output stride of 16, demonstrating a 3.3% improvement over v3 while maintaining computational efficiency.
Performance Comparison
The evolution of DeepLab models shows consistent improvements in accuracy and efficiency:
| Version | Backbone | mIoU (PASCAL VOC 2012) | Key Innovation |
|---|---|---|---|
| v1 | VGG-16 | 71.6% | Atrous convolution, CRF |
| v2 | ResNet-101 | 79.7% | ASPP |
| v3 | ResNet-101 | 85.7% | Improved ASPP |
| v3+ | Xception-71 | 89.0% | Encoder-decoder |
Key Components of DeepLab (ASPP, Backbone Networks)
Atrous Spatial Pyramid Pooling (ASPP)
ASPP is a critical module in DeepLab architectures designed to capture multi-scale contextual information by employing parallel atrous convolutions with different dilation rates. The core idea is to process the input feature map at multiple scales simultaneously, enabling the model to recognize objects of varying sizes within the same scene. ASPP consists of:
- Four parallel atrous convolutional layers with dilation rates of 6, 12, 18, and 24.
- One global average pooling branch to incorporate image-level features.
- A 1×1 convolutional layer for pointwise feature refinement.
The output features from all branches are concatenated and processed through a final 1×1 convolution to generate the segmentation logits. Mathematically, the atrous convolution operation can be expressed as:
where r is the dilation rate, x is the input feature map, w is the convolution kernel, and y is the output. Larger dilation rates expand the receptive field without increasing parameters or computational cost.
Backbone Networks
DeepLab variants employ different backbone architectures for feature extraction, each offering distinct advantages in terms of accuracy and efficiency:
ResNet Variants
ResNet-101 and ResNet-50 are commonly used backbones in DeepLabv3 and DeepLabv3+. These networks utilize residual connections to enable training of very deep architectures. The modified versions for segmentation tasks:
- Replace strided convolutions with atrous convolutions in later blocks to maintain spatial resolution.
- Remove the final average pooling and fully-connected layers.
- Employ output stride (ratio of input to output resolution) of 16 or 8 for denser feature maps.
Xception
DeepLabv3+ introduced Xception as a backbone, offering improved computational efficiency through:
- Depthwise separable convolutions that factorize standard convolutions.
- More efficient use of model parameters.
- Enhanced gradient flow through linear residual connections.
MobileNetV2
For mobile and edge device applications, MobileNetV2 provides a lightweight alternative with:
- Inverted residual blocks with linear bottlenecks.
- Depthwise convolutions for spatial filtering.
- Significantly reduced computational cost while maintaining reasonable accuracy.
Architecture Integration
The backbone network extracts hierarchical features which are then processed by the ASPP module. DeepLabv3+ further enhances this by adding a decoder module that combines:
- High-level semantic features from the ASPP output.
- Low-level features from earlier backbone layers.
- Progressive upsampling through bilinear interpolation or learned transposed convolutions.
This integration allows the model to simultaneously leverage both fine-grained spatial details and high-level contextual information, achieving state-of-the-art performance on benchmarks like PASCAL VOC and Cityscapes.
3. Setting Up the Environment for DeepLab
3.1 Setting Up the Environment for DeepLab
Prerequisites
Before configuring the environment for DeepLab, ensure the following dependencies are installed:
- Python 3.7+ – Required for TensorFlow and PyTorch compatibility.
- CUDA 11.x – Necessary for GPU acceleration with NVIDIA GPUs.
- cuDNN 8.x – Optimized deep learning primitives for CUDA.
- TensorFlow 2.6+ or PyTorch 1.10+ – DeepLab supports both frameworks.
Installation Steps
DeepLab can be installed via pip or built from source. For TensorFlow implementation:
pip install tensorflow-gpu==2.6.0
pip install tf-models-official==2.6.0
For PyTorch users, install the torchvision package with CUDA support:
pip install torch==1.10.0+cu113 torchvision==0.11.1+cu113 -f https://download.pytorch.org/whl/torch_stable.htmlVerifying GPU Support
Confirm CUDA and cuDNN are correctly linked by running:
import tensorflow as tf
print(tf.config.list_physical_devices('GPU'))
For PyTorch, verify GPU availability with:
import torch
print(torch.cuda.is_available())
Downloading DeepLab Models
Pre-trained DeepLabv3+ models are available in the TensorFlow Model Garden or PyTorch Hub. For TensorFlow:
git clone https://github.com/tensorflow/models.git
cd models/research/
protoc deeplab/protos/*.proto --python_out=.
For PyTorch, load the model directly:
model = torch.hub.load('pytorch/vision', 'deeplabv3_resnet101', pretrained=True)Dataset Preparation
DeepLab requires annotated datasets in Pascal VOC or COCO format. Use the following structure:
dataset/
├── images/          # Input RGB images
├── annotations/     # Segmentation masks (PNG)
└── train.txt        # List of training samples
Environment Variables
Set the PYTHONPATH to include the TensorFlow research directory:
export PYTHONPATH=$$PYTHONPATH:/path/to/models/research
export PYTHONPATH=$$PYTHONPATH:/path/to/models/research/slim
3.2 Preparing and Preprocessing Datasets
Effective scene segmentation with DeepLab models requires meticulous dataset preparation and preprocessing. The quality of the input data directly impacts the model's ability to generalize and accurately segment complex scenes. Below, we outline the key steps and considerations for preparing datasets for DeepLab-based segmentation.
Dataset Requirements
DeepLab models, particularly DeepLabv3+, are designed to handle high-resolution images with fine-grained segmentation masks. The dataset must include:
- High-resolution RGB images (typically 512x512 or larger) to capture detailed scene information.
- Pixel-level annotations in the form of segmentation masks, where each pixel is labeled with a class ID.
- Class balance to avoid bias toward dominant classes, which can be addressed through sampling or loss weighting.
Data Augmentation Strategies
Data augmentation is critical for improving model robustness and preventing overfitting. Common techniques include:
- Geometric transformations: Random scaling (0.5–2.0x), rotation (±30°), and flipping (horizontal/vertical).
- Photometric distortions: Adjusting brightness (±20%), contrast (±20%), and saturation (±20%) to simulate varying lighting conditions.
- Elastic deformations: Applying small random deformations to simulate real-world distortions.
These augmentations should be applied consistently to both the input image and its corresponding segmentation mask to maintain alignment.
Normalization and Rescaling
DeepLab models typically expect input images to be normalized to a fixed range. The standard practice is to rescale pixel values to the range [-1, 1] or [0, 1] and apply channel-wise normalization using precomputed mean and standard deviation values. For example:
where I is the input image, μ is the mean, and σ is the standard deviation. Common values for pretrained models are μ = [0.485, 0.456, 0.406] and σ = [0.229, 0.224, 0.225] (ImageNet statistics).
Handling Class Imbalance
Scene segmentation datasets often exhibit severe class imbalance, where certain classes (e.g., "sky" or "road") dominate. To address this:
- Class-weighted loss: Assign higher weights to underrepresented classes in the loss function (e.g., inverse frequency weighting).
- Oversampling: Duplicate samples from rare classes during training.
- Label smoothing: Apply a small uniform probability to all classes to prevent overconfidence in dominant classes.
Dataset Splitting
A rigorous split of the dataset into training, validation, and test sets is essential for reliable evaluation. Recommended ratios are:
- 70% training for model learning.
- 15% validation for hyperparameter tuning.
- 15% test for final evaluation.
Stratified sampling ensures each split maintains the original class distribution.
Efficient Data Loading
For large-scale datasets, efficient data loading is crucial to avoid bottlenecks during training. Best practices include:
- Preprocessing offline: Apply computationally heavy augmentations once and save the results.
- Parallel loading: Use multiple worker threads to prefetch batches (e.g., PyTorch's DataLoader with num_workers > 1).
- Memory mapping: Store data in memory-mapped files for fast access.
Below is an example of a PyTorch dataset class for loading and augmenting segmentation data:
import torch
from torchvision import transforms
from PIL import Image

class SegmentationDataset(torch.utils.data.Dataset):
    def __init__(self, image_paths, mask_paths, transform=None):
        self.image_paths = image_paths
        self.mask_paths = mask_paths
        self.transform = transform

    def __getitem__(self, idx):
        image = Image.open(self.image_paths[idx]).convert("RGB")
        mask = Image.open(self.mask_paths[idx]).convert("L")  # Grayscale mask

        if self.transform:
            image, mask = self.transform(image, mask)

        # Normalize image to [-1, 1]
        image = transforms.functional.to_tensor(image)
        image = transforms.functional.normalize(
            image, mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]
        )

        return image, mask.long()

    def __len__(self):
        return len(self.image_paths)
Handling Large-Scale Datasets
For datasets like Cityscapes or COCO, which contain thousands of high-resolution images, consider:
- Patch-based training: Split images into smaller patches (e.g., 512x512) to fit GPU memory.
- Distributed training: Use multi-GPU or multi-node setups with synchronized batch normalization.
- Progressive resizing: Train initially on lower resolutions before fine-tuning on full-resolution images.
3.3 Training DeepLab Models: Best Practices
Optimizing the Loss Function
DeepLab models typically employ a combination of cross-entropy loss and auxiliary loss to handle class imbalance and improve boundary precision. The primary loss function is pixel-wise cross-entropy, defined as:
where H and W are height and width dimensions, C is the number of classes, y is the ground truth one-hot encoded label, and p is the predicted probability. For boundary refinement, DeepLabv3+ adds a multi-scale loss by applying the loss function at different output strides (4×, 8×, 16×) before fusion.
Learning Rate Scheduling
Poly learning rate decay outperforms step decay for semantic segmentation tasks. The learning rate at iteration t follows:
where η0 is the initial learning rate (typically 0.007 for DeepLabv3+), tmax is the maximum iterations, and power is set to 0.9. This gradual decay prevents sudden loss spikes when fine-tuning pretrained backbones like Xception or ResNet.
Data Augmentation Strategies
Effective augmentation for scene segmentation includes:
- Multi-scale cropping: Random crops at scales between 0.5× to 2.0× of the input size
- Color jittering: Adjust brightness (±0.5), contrast (±0.5), saturation (±0.5), and hue (±0.2)
- Left-right flipping: Applied with 50% probability
- Gaussian blurring: Kernel size between 3×3 to 7×7 with σ ∈ [0.1, 2.0]
Batch Normalization Tuning
When using pretrained backbones, batch norm layers should:
- Maintain running statistics during both training and evaluation for stable outputs
- Use synchronized batch norm across GPUs with a batch size ≥ 16 to reduce variance
- Set momentum to 0.9997 for large-scale datasets like Cityscapes or ADE20K
Handling Class Imbalance
Two effective approaches:
- Median frequency balancing: Weight each class by the inverse median frequency:
$$ w_c = \frac{median\_freq}{freq(c)} $$
- Bootstrapped cross-entropy: Focus training on the top K% hardest pixels per batch
Mixed Precision Training
Using FP16 precision with dynamic loss scaling provides:
- 1.5× to 2× faster training with minimal accuracy drop
- Reduced GPU memory consumption enabling larger crops or batch sizes
- Automatic gradient scaling prevents underflow (maintain scale factor > 1e-4)
Validation Protocol
For reliable evaluation:
- Compute mIoU on the validation set every 1000 iterations
- Use sliding window inference on full-resolution images during testing
- Apply multi-scale testing (0.5×, 0.75×, 1.0×, 1.25×, 1.5×, 1.75×) and average predictions
3.4 Fine-Tuning and Transfer Learning with DeepLab
Transfer Learning in Semantic Segmentation
DeepLab models, like other deep neural networks, benefit significantly from transfer learning. Pretrained backbones (e.g., ResNet, Xception) trained on large-scale datasets like ImageNet provide low-level feature extractors that generalize well across tasks. The key idea is to leverage these pretrained weights and adapt them for semantic segmentation by replacing the final classification layers with atrous spatial pyramid pooling (ASPP) and a decoder module.
Where λce and λdice are weighting factors for cross-entropy and Dice loss respectively. This combined loss function helps address class imbalance during fine-tuning.
Fine-Tuning Strategies
When fine-tuning DeepLab models, several strategies prove effective:
- Progressive Unfreezing: Start by training only the decoder and ASPP layers, then gradually unfreeze backbone layers starting from the top.
- Differential Learning Rates: Apply higher learning rates to newly added layers compared to pretrained backbone layers.
- Label Adaptation: For domain shifts, consider adapting label spaces using techniques like label remapping or auxiliary classifiers.
Domain Adaptation Techniques
When applying DeepLab to new domains with limited labeled data, several approaches improve performance:
This adversarial training formulation, where G is the segmentation network and D is a domain discriminator, helps align feature distributions between source (xs) and target (xt) domains.
Practical Implementation Considerations
When implementing fine-tuning in frameworks like TensorFlow or PyTorch:
# PyTorch example: Fine-tuning DeepLabv3+
model = deeplabv3_resnet50(pretrained=True)
# Freeze backbone parameters
for param in model.backbone.parameters():
    param.requires_grad = False

# Modify classifier for new num_classes
model.classifier = DeepLabHead(2048, num_classes)
# Only classifier parameters will be trained initially
optimizer = torch.optim.Adam(model.classifier.parameters(), lr=1e-3)
Performance Optimization
For optimal fine-tuning results:
- Use larger batch sizes when possible to stabilize batch normalization statistics
- Apply strong data augmentation (e.g., random scaling, rotation, color jitter)
- Monitor both source and target domain performance when doing domain adaptation
- Consider using learning rate warmup for the first few epochs
Evaluation Metrics
Beyond standard pixel accuracy, use:
where C is the number of classes, and TP, FP, FN are true positives, false positives, and false negatives respectively. This metric better captures performance across imbalanced classes.
4. Metrics for Scene Segmentation Performance
4.1 Metrics for Scene Segmentation Performance
Evaluating the performance of scene segmentation models like DeepLab requires robust metrics that quantify accuracy, boundary adherence, and semantic consistency. Unlike classification tasks, segmentation demands pixel-level assessment, necessitating specialized measures beyond simple accuracy.
Pixel Accuracy
Pixel accuracy measures the fraction of correctly classified pixels across all classes. Given a confusion matrix C, where Cij denotes pixels of class i predicted as class j, pixel accuracy PA is computed as:
While intuitive, this metric is biased toward dominant classes in imbalanced datasets (e.g., roads occupying 50% of urban scenes). A model ignoring rare classes could still achieve high PA.
Mean Intersection over Union (mIoU)
mIoU, the standard metric for segmentation benchmarks like PASCAL VOC and Cityscapes, calculates the average IoU across all classes. For class k, IoU is:
where TPk, FPk, and FNk are true positives, false positives, and false negatives for class k, respectively. mIoU then averages IoU values over all K classes:
This metric balances precision and recall while penalizing misclassification of small objects. DeepLabv3+ achieves 82.1% mIoU on Cityscapes by leveraging atrous spatial pyramid pooling (ASPP) for multi-scale context.
Boundary F1 Score (BF1)
Standard IoU ignores boundary quality, critical for applications like autonomous driving. BF1 evaluates segmentation edges by:
- Computing a boundary mask using morphological dilation (e.g., 3px width)
- Calculating precision Pbdry and recall Rbdry on this mask
- Deriving the F1 score:
State-of-the-art models employ boundary-aware losses during training to optimize BF1, such as the edge-aware loss in Richer Convolutional Features (RCF) networks.
Frequency Weighted IoU (FW-IoU)
For datasets with extreme class imbalance (e.g., ADE20K), FW-IoU weights each class's IoU by its pixel frequency:
where wk is the pixel count of class k. This prevents rare classes (e.g., traffic signs) from being overshadowed by prevalent ones (e.g., sky).
Panoptic Quality (PQ)
Introduced for panoptic segmentation, PQ decomposes into recognition (RQ) and segmentation quality (SQ):
DeepLab variants adapted for panoptic tasks (e.g., Panoptic-DeepLab) optimize PQ by jointly training instance and semantic heads with a unified loss function.
Implementation Considerations
When benchmarking DeepLab models:
- Use GPU-accelerated metric computation (e.g., PyTorch's torchmetrics) to handle high-resolution outputs
- Normalize metrics across dataset splits, as urban scenes exhibit spatial bias (e.g., more sky pixels in top image halves)
- Report per-class metrics alongside averages to diagnose failure modes (e.g., poor performance on translucent objects)
Common Pitfalls and How to Avoid Them
1. Misalignment Between Feature Resolution and Prediction
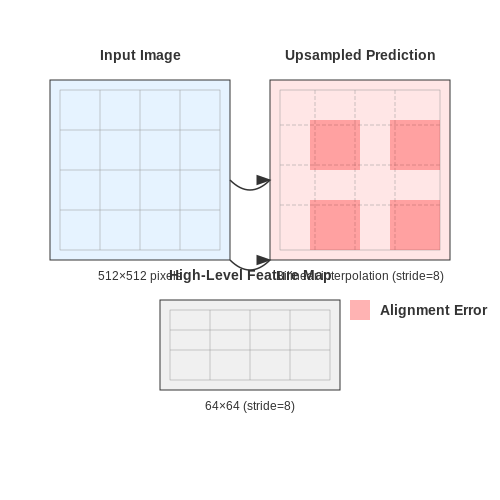
DeepLab's atrous spatial pyramid pooling (ASPP) operates on high-level features with reduced spatial resolution due to pooling and strided convolutions. When these features are upsampled for pixel-wise prediction, misalignment occurs between the predicted mask and input dimensions. The standard bilinear interpolation used in upsampling doesn't account for the positional offsets introduced by previous operations.
To mitigate this, employ transposed convolutions with learnable kernels instead of fixed interpolation. The DeepLabv3+ architecture addresses this by introducing a decoder module that refines segmentation boundaries using low-level features.
2. Class Imbalance in Urban Scene Datasets
Cityscapes and similar datasets exhibit extreme class imbalance - road and building pixels may outnumber traffic signs by 1000:1. The standard cross-entropy loss fails under these conditions:
Where wc is the class weight. Implement either:
- Median frequency balancing: wc = median_freq / freq(c)
- Focal loss: FL(pt) = -(1-pt)γ log(pt) where γ=2 works well in practice
3. Boundary Artifacts from Atrous Rates
The ASPP module's parallel convolutions with different dilation rates (6, 12, 18) create grid artifacts when the rate approaches feature map dimensions. This manifests as checkerboard patterns in predictions. The condition occurs when:
Where r is dilation rate and k is kernel size. Solutions include:
- Limiting maximum dilation rate to min(H,W)/(2k)
- Applying hybrid dilation rates that adapt to feature map size
- Using depthwise separable convolutions in ASPP
4. Memory Overhead from Large Stride Values
DeepLab's output stride (input resolution/output resolution) of 16 or 8 creates memory bottlenecks during training. For a 1024×2048 image batch of 8, the memory consumption follows:
Where S is output stride. Strategies to reduce memory:
- Use gradient checkpointing for the backbone network
- Implement mixed-precision training with AMP (Automatic Mixed Precision)
- Employ progressive resizing during training
5. Overfitting on Small Datasets
When training on limited data (e.g., <500 images), DeepLab's large capacity leads to poor generalization. The validation mIOU plateaus while training mIOU continues improving. Countermeasures include:
- Strong regularization: Dropout (p=0.5) before final layers, weight decay (λ=5e-4)
- Data augmentation: Geometric transforms + photometric distortions
- Pretraining: Initialize backbone on Mapillary Vistas before fine-tuning
6. Inefficient Inference Speed
Real-time deployment suffers from DeepLab's computational complexity. For a 1024×2048 image, latency breaks down as:
| Component | FLOPs | % Total |
|---|---|---|
| Backbone (ResNet-101) | 59.4G | 72% |
| ASPP Module | 14.2G | 17% |
| Decoder | 8.7G | 11% |
Optimization approaches:
- Replace ResNet with MobileNetV3 backbone
- Use TensorRT for layer fusion and INT8 quantization
- Implement model distillation to a lighter variant
4.3 Benchmarking DeepLab Against Other Models
DeepLab's performance is often evaluated against other state-of-the-art segmentation models, such as FCN, U-Net, and PSPNet, across standard datasets like PASCAL VOC, Cityscapes, and ADE20K. Key metrics include mean Intersection-over-Union (mIoU), inference speed (FPS), and memory efficiency. DeepLabv3+ achieves superior boundary precision due to its atrous spatial pyramid pooling (ASPP) and decoder refinement, outperforming FCN by 5-8% mIoU on PASCAL VOC.
Quantitative Comparison on PASCAL VOC
The PASCAL VOC 2012 benchmark highlights DeepLabv3+'s advantage in multi-scale object segmentation. For instance:
where TP, FP, and FN denote true positives, false positives, and false negatives per class. DeepLabv3+ achieves 89.0% mIoU compared to U-Net's 83.5% and PSPNet's 85.4%, attributed to its hybrid encoder-decoder design and Xception backbone.
Computational Efficiency
While DeepLab delivers higher accuracy, its computational cost is non-trivial. On a Titan X GPU, DeepLabv3+ processes 8 FPS at 513×513 resolution, whereas FCN-8s runs at 20 FPS. The trade-off stems from ASPP's parallel atrous convolutions:
Here, L is the number of layers, C denotes channels, and K is the kernel size. DeepLabv3+'s FLOPs (≈45B) exceed U-Net's (≈12B) but remain justified for high-stakes applications like medical imaging.
Boundary-Aware Segmentation
DeepLab's decoder refines object boundaries by combining low-level features with ASPP outputs. This is quantified via the Boundary F1 (BF) score:
On Cityscapes, DeepLabv3+ achieves a BF score of 0.74, surpassing Mask R-CNN (0.68) and BiSeNet (0.71). The decoder's feature fusion reduces artifacts common in FCN-based upsampling.
Real-World Robustness
In adverse conditions (e.g., foggy Cityscapes), DeepLabv3+ maintains a 72.3% mIoU versus PSPNet's 68.1%, owing to ASPP's multi-scale context aggregation. However, models like HRNet+OCR show competitive performance (74.2%) with higher resolution inputs, suggesting context alone isn't sufficient for all edge cases.
5. Handling Small Objects and Fine Details
5.1 Handling Small Objects and Fine Details
DeepLab models, while powerful for semantic segmentation, often struggle with small objects and fine-grained details due to the progressive downsampling in convolutional networks. The primary challenge arises from the loss of spatial resolution in deeper layers, where high-level features are extracted at the expense of precise localization. This section explores architectural and methodological improvements to mitigate this limitation.
Dilated Convolutions and Multi-Scale Context
The core mechanism in DeepLab for preserving spatial information is the use of atrous (dilated) convolutions, which expand the receptive field without reducing resolution. The dilation rate r controls the spacing between kernel weights, effectively increasing the field of view while maintaining the same computational cost. For a 3×3 kernel, the effective receptive field becomes:
However, a single dilation rate is insufficient for capturing objects at multiple scales. DeepLabv3+ employs Atrous Spatial Pyramid Pooling (ASPP), which processes features in parallel with varying dilation rates (e.g., 6, 12, 18) and combines them with global average pooling. This multi-scale approach helps recover fine details while maintaining context awareness.
Encoder-Decoder Refinement
DeepLabv3+ introduces a decoder module that refines segmentation masks by combining high-resolution shallow features from the encoder with semantically rich deep features. The fusion occurs via bilinear upsampling followed by concatenation and 1×1 convolutions:
where Up_4 denotes 4× upsampling, fdeep and fshallow are features from the backbone's final and intermediate layers, and σ is the sigmoid activation. This skip connection mechanism is particularly effective for reconstructing object boundaries and small structures.
Boundary-Aware Loss Functions
Standard cross-entropy loss treats all pixels equally, often leading to blurred edges. Incorporating boundary-weighted loss emphasizes transitions between segments:
where B is the set of boundary pixels identified via morphological operations, and wi is a weight factor (typically 2-5× higher than non-boundary pixels). Advanced variants like the Gradient-Sensitive Loss dynamically adjust weights based on local intensity gradients.
High-Resolution Feature Preservation
Recent variants employ HRNet as a backbone, maintaining high-resolution representations throughout the network via parallel multi-scale branches. Unlike traditional U-Net architectures that downsample and then upsample, HRNet preserves spatial details by continuously fusing features across resolutions. The output stride (ratio of input to output resolution) can be reduced to 4 or even 2 for dense prediction tasks requiring extreme precision.
Practical Considerations
- Input Resolution: Increasing input size (e.g., from 512×512 to 1024×1024) improves small object detection but quadratically grows computational cost.
- Dilation Rate Tradeoffs: Excessively large rates (e.g., >24) may introduce gridding artifacts where local pixel relationships are lost.
- Post-Processing: Conditional Random Fields (CRFs) or learned edge-aware refinement can further sharpen boundaries but add inference latency.
Real-Time Scene Segmentation with DeepLab
Architectural Optimizations for Real-Time Performance
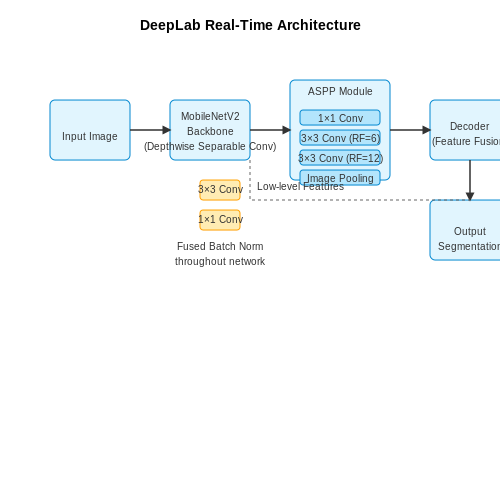
DeepLab models achieve real-time segmentation by leveraging several architectural optimizations. The backbone network, typically a MobileNetV2 or ResNet-18 variant, employs depthwise separable convolutions to reduce computational complexity. The atrous spatial pyramid pooling (ASPP) module is streamlined by reducing the number of parallel branches while maintaining receptive field diversity. Batch normalization layers are fused with preceding convolutions during inference, minimizing memory access overhead.
Where L represents network layers, C denotes channel dimensions, K is kernel size, and H,W are spatial dimensions. The quadratic relationship between kernel size and computation motivates the use of 3×3 depthwise convolutions followed by 1×1 pointwise convolutions.
Quantization and Hardware Acceleration
Post-training quantization converts 32-bit floating-point weights to 8-bit integers (INT8) with minimal accuracy loss. For TensorRT deployment, the model undergoes:
- Layer fusion: Combining consecutive linear operations
- Kernel auto-tuning: Selecting optimal CUDA kernels for target GPU
- Memory optimization: Reducing intermediate tensor allocations
On an NVIDIA Jetson AGX Xavier, this achieves 23 FPS at 512×512 resolution with DeepLabV3+ (MobileNetV2 backbone). The latency breakdown shows 62% spent on backbone feature extraction, 28% on ASPP, and 10% on decoder operations.
Temporal Consistency Techniques
For video segmentation, frame-to-frame consistency is maintained through:
- Feature warping: Using optical flow to propagate previous features
- Temporal regularization: Adding consistency loss during training
- Keyframe scheduling: Processing full resolution only every N frames
The warping operation between consecutive frames It and It+1 is computed as:
where φ represents the flow field estimated by a lightweight flow network. This reduces redundant computation by 40% in static scene regions.
Edge Deployment Considerations
When deploying on edge devices, memory bandwidth becomes the limiting factor. The memory access cost (MAC) is optimized through:
- Channel pruning: Removing redundant filters with L1-norm criteria
- Activation compression: Using 4-bit activations with dynamic scaling
- Tile-based processing: Partitioning large images for memory locality
The tile overlap is calculated based on the network's effective receptive field (ERF):
For a DeepLabV3+ with ERF of 225 pixels, this results in 112-pixel overlaps between 512×512 tiles. On a Qualcomm Snapdragon 865, this approach achieves 18 FPS with 2.1W power consumption.
5.3 Combining DeepLab with Other Techniques (e.g., CRFs)
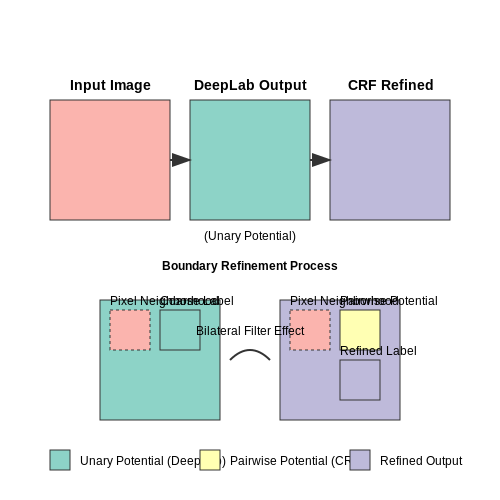
DeepLab models excel at semantic segmentation due to their atrous spatial pyramid pooling (ASPP) and deep convolutional networks, but their outputs can still benefit from post-processing techniques like Conditional Random Fields (CRFs). CRFs refine segmentation maps by incorporating spatial consistency and pairwise pixel relationships, addressing common issues like fragmented predictions or blurry object boundaries.
Mathematical Foundation of CRFs
The energy function in a CRF is defined as:
where ψu(xi) is the unary potential (typically derived from DeepLab's softmax output) and ψp(xi, xj) is the pairwise potential enforcing smoothness. A common pairwise term uses Gaussian kernels:
Here, pi and Ii denote pixel positions and color intensities, while θα, θβ, and θγ control the scale of spatial and color similarity.
Integration with DeepLab
DeepLabv3+ outputs a coarse segmentation map at a reduced resolution (typically 1/8 or 1/16 of the input). CRFs can be applied in two ways:
- DenseCRF: Operates on the full-resolution image, using the coarse DeepLab output as unary potentials. The bilateral filtering effect of the Gaussian kernels sharpens boundaries.
- CRF-as-RNN: An end-to-end trainable variant that integrates CRF inference into the network via recurrent neural network steps, allowing joint optimization.
Implementation Example
The following snippet shows how to apply DenseCRF post-processing to a DeepLab output using the pydensecrf library:
import numpy as np
import pydensecrf.densecrf as dcrf
from pydensecrf.utils import unary_from_softmax

# Assuming `probs` is the softmax output from DeepLab (H × W × C)
probs = np.load("deeplab_output.npy")
h, w, n_classes = probs.shape

# Create CRF and set unary potentials
d = dcrf.DenseCRF2D(w, h, n_classes)
unary = unary_from_softmax(probs.transpose(2, 0, 1))
d.setUnaryEnergy(unary)

# Add pairwise potentials (applying bilateral and spatial kernels)
d.addPairwiseGaussian(sxy=3, compat=3)
d.addPairwiseBilateral(sxy=80, srgb=13, rgbim=input_image, compat=10)

# Inference
q = d.inference(5)
segmentation = np.argmax(q, axis=0).reshape(h, w)
Performance Impact
On datasets like PASCAL VOC, CRF post-processing improves mean Intersection-over-Union (mIoU) by 1.5–2.5 percentage points by:
- Reducing false positives in homogeneous regions.
- Enhancing edge alignment for small objects.
- Suppressing isolated misclassified pixels.
However, CRFs increase inference time by 30–50% due to iterative message passing. For real-time applications, lightweight alternatives like guided filtering or edge-aware pooling may be preferred.
Extensions and Hybrid Approaches
Recent work combines CRFs with attention mechanisms or graph neural networks to model long-range dependencies beyond local pairwise terms. For instance, non-local CRFs replace Gaussian kernels with learned affinity matrices, capturing semantic relationships between distant pixels.
6. Key Research Papers on DeepLab
6.1 Key Research Papers on DeepLab
- Deep gated attention networks for large-scale street-level scene ... — However, scene segmentation requires pixel-exact classification of fine details, which are typically only found in low-level layers. ... [60], which is a universal segmentation model trained on diverse datasets. For fair comparison, ... DeepLab: semantic image segmentation with deep convolutional nets, atrous convolution, and fully connected ...
- Enhancing Road Scene Segmentation With an Optimized DeepLabV3+ — Semantic segmentation, as a dense predictive task, is inevitably affected by various external factor, making common road image semantic segmentation models unable to meet dual demands of high accuracy and real-time performance in unstructured road scenarios. To address these issues, this paper proposes an enhanced road scene segmentation method based on DeepLabV3+ that addresses the common ...
- DeepLab Explained - Papers With Code — DeepLab is a semantic segmentation architecture. First, the input image goes through the network with the use of dilated convolutions. Then the output from the network is bilinearly interpolated and goes through the fully connected CRF to fine tune the result we obtain the final predictions.. Source: Semantic Image Segmentation with Deep Convolutional Nets and Fully Connected CRFs
- open-cv/deeplab-v2: deeplab v2 - GitHub — DeepLab is a state-of-art deep learning system for semantic image segmentation built on top of Caffe.. It combines (1) atrous convolution to explicitly control the resolution at which feature responses are computed within Deep Convolutional Neural Networks, (2) atrous spatial pyramid pooling to robustly segment objects at multiple scales with filters at multiple sampling rates and effective ...
- Semantic scene segmentation in unstructured environment with modified ... — Semantic scene segmentation has become a key application in computer vision and is an essential part of intelligent transportation systems for complete scene understanding of the surrounding environment. ... which contains data from unstructured traffic scenario. In this paper, we propose modifications in the DeepLabV3+ framework by using lower ...
- Based on DeepLab v3+ model to realize the road scene semantic ... — The semantic segmentation of deep learning has a very broad development prospect in the field of computer vision, but many network models with good segmentation effect have problems such as large amount of model calculation and long training time for segmentation in road scenes. In response to these problems, this paper changes the feature extraction network to the lightweight MobileNetV2 ...
- PDF Image Segmentation Using Deep Learning: A Survey — 5) R-CNN based models (for instance segmentation) 6) Dilated convolutional models and DeepLab family 7) Recurrent neural network based models Shervin Minaee is with the Snapchat Machine Learning Research, Venice, CA 90405 USA. E-mail: [email protected]. Yuri Boykov is with the University of Waterloo, Waterloo, ON N2L 3G1, Canada.
- PDF Using Improved DeepLabV3+ for Complex Scene Segmentation — segmentation through the combination of encoder and decoder. The U-Net++ and U-Net+++, which are based on it, are widely used in processing with the advantage of high accuracy. Presented by the Google team in 2016, DeepLab is a model that utilizes atrous convolution to expand the sensory field and
- Deep Learning Models for Image Segmentation - ResearchGate — Based on the DeepLab V3+ semantic segmentation network, the characteristics of the insulator's data are retrieved. ... is one of the most widespread deep neural network models. This paper ...
- (PDF) Image Segmentation Using Deep Learning: A Survey - ResearchGate — Image segmentation is a key topic in image processing and computer vision with applications such as scene understanding, medical image analysis, robotic perception, video surveillance, augmented ...
6.2 Open-Source Implementations and Tools
- DeepLab2: A TensorFlow Library for Deep Labeling - GitHub — 08/16/2022: Support Colab demo for kMaX-DeepLab. 07/12/2022: Open-source k-means Mask Transformer (kMaX-DeepLab) code and model zoo. 07/11/2022: Drop support of Tensorflow 2.5. Please update to 2.6. 04/27/2022: Add ViP-DeepLab demo and update ViP-DeepLab model zoo. 09/07/2021: Add numpy implementation of Segmentation and Tracking Quality. Find ...
- Top 23 semantic-segmentation Open-Source Projects - LibHunt — Which are the best open-source semantic-segmentation projects? This list will help you: label-studio, CVPR2025-Papers-with-Code, Swin-Transformer, labelme, awesome-semantic-segmentation, segmentation_models.pytorch, and Pytorch-UNet. LibHunt. Popularity Index Add a ... Pytorch implementation for Semantic Segmentation/Scene Parsing on MIT ADE20K ...
- Scene Segmentation - Papers With Code — Scene segmentation is the task of splitting a scene into its various object components. ... Use these libraries to find Scene Segmentation models and implementations PaddlePaddle/PaddleSeg ... outperforming the strongest prior model by 3. 3 absolute percentage points and crossing the 70% mIoU threshold for the first time. 24.
- Open-CE | OSU Open Source Lab - IBM Developer — TensorFlow Serving is an open-source library for serving machine learning models: tensorflow-serving-api: 2.14.1: TensorFlow Serving is an open-source library for serving machine learning models: X: tensorflow-text: 2.14.0: TF.Text is a TensorFlow library of text related ops, modules, and subgraphs. tf2onnx: 1.15.1: Tensorflow to ONNX converter ...
- Driving Scene Segmentation steps to run DeepLab semantic scene ... — DeepLab is a state-of-art deep learning model for semantic image segmentation, where the goal is to assign semantic labels (e.g., person, dog, cat and so on) to every pixel in the input image. Some segmentation results on Flickr images: In a scene driving context, we aim to obtain a semantic understanding of the front driving scene throught the camera input.
- Semantic Image Segmentation with DeepLab in TensorFlow - Google Research — Today, we are excited to announce the open source release of our latest and best performing semantic image segmentation model, DeepLab-v3+ [1] *, implemented in TensorFlow.This release includes DeepLab-v3+ models built on top of a powerful convolutional neural network (CNN) backbone architecture [2, 3] for the most accurate results, intended for server-side deployment.
- DeepLab Demo.ipynb - Colab - Google Colab — This notebook is open with private outputs. Outputs will not be saved. ... This colab demonstrates the steps to use the DeepLab model to perform semantic segmentation on a sample input image. ... About DeepLab. The models used in this colab perform semantic segmentation. Semantic segmentation models focus on assigning semantic labels, such as ...
- Based on DeepLab v3+ model to realize the road scene semantic ... — The semantic segmentation of deep learning has a very broad development prospect in the field of computer vision, but many network models with good segmentation effect have problems such as large amount of model calculation and long training time for segmentation in road scenes. In response to these problems, this paper changes the feature extraction network to the lightweight MobileNetV2 ...
- MIT Driving Scene Segmentation — DeepLab is a state-of-art deep learning model for semantic image segmentation, where the goal is to assign semantic labels (e.g., person, dog, cat and so on) to every pixel in the input image. Some segmentation results on Flickr images: In the driving context, we aim to obtain a semantic understanding of the front driving scene throught the camera input.
- ESANet: Efficient RGB-D Semantic Segmentation for Indoor Scene ... - GitHub — Data preparation (training / evaluation / dataset inference): We trained our networks on NYUv2, SUNRGB-D, and Cityscapes.The encoders were pretrained on ImageNet.Furthermore, we also pretrained our best model on the synthetic dataset SceneNet RGB-D. The folder src/datasets contains the code to prepare NYUv2, SunRGB-D, Cityscapes, SceneNet RGB-D for training and evaluation.
6.3 Recommended Courses and Tutorials
- Keras documentation: Semantic Segmentation with KerasHub — Perform semantic segmentation with a pretrained DeepLabv3+ model. The highest level API in the KerasHub semantic segmentation API is the keras_hub.models API. This API includes fully pretrained semantic segmentation models, such as keras_hub.models.DeepLabV3ImageSegmenter.. Let's get started by constructing a DeepLabv3 pretrained on the Pascal VOC dataset.
- Video Panoptic Segmentation Models | google-research/deeplab2 | DeepWiki — These models extend the concept of panoptic segmentation (which unifies semantic and instance segmentation) to the video domain, enabling consistent segmentation across video frames. The DeepLab2 framework implements two approaches for video panoptic segmentation: ViP-DeepLab and Motion-DeepLab.
- Semantic scene segmentation in unstructured environment with modified ... — Semantic scene segmentation has become a key application in computer vision and is an essential part of intelligent transportation systems for complete scene understanding of the surrounding environment. ... 82.6: 3.6: 3.3. ... It can be observed that our proposed model that achieves best performance on IDD results in slightly poor performance ...
- A Guide to Using DeepLabV3 for Semantic Segmentation - Datature — To learn more about semantic segmentation, its advantages, current applications as well as two semantic segmentation models we offer on Nexus (FCNs and U-Nets). Introducing DeepLabV3. DeepLabV3 is a state-of-the-art deep learning architecture best suited for semantic segmentation tasks.
- Driving Scene Segmentation steps to run DeepLab semantic scene ... — DeepLab is a state-of-art deep learning model for semantic image segmentation, where the goal is to assign semantic labels (e.g., person, dog, cat and so on) to every pixel in the input image. Some segmentation results on Flickr images: In a scene driving context, we aim to obtain a semantic understanding of the front driving scene throught the camera input.
- Semantic Image Segmentation with DeepLab in TensorFlow - Google Research — Today, we are excited to announce the open source release of our latest and best performing semantic image segmentation model, DeepLab-v3+ [1] *, implemented in TensorFlow.This release includes DeepLab-v3+ models built on top of a powerful convolutional neural network (CNN) backbone architecture [2, 3] for the most accurate results, intended for server-side deployment.
- Using Improved DeepLabV3+ for Complex Scene Segmentation — This paper presents a lightweight convolutional neural network model based on DeepLabV3+. By collecting and annotating an image dataset, sufficient sample support is provided for the model's training. In order to enhance the model's training speed and applicability, this study proposes replacing the backbone network Xception with MobileNetv2. This successfully reduces the number of model ...
- MIT Driving Scene Segmentation — DeepLab is a state-of-art deep learning model for semantic image segmentation, where the goal is to assign semantic labels (e.g., person, dog, cat and so on) to every pixel in the input image. Some segmentation results on Flickr images: In the driving context, we aim to obtain a semantic understanding of the front driving scene throught the camera input.
- GitHub - heaversm/deeplab-training: Training your own Deeplab Model in ... — TLDR: This tutorial covers how to set up Deeplab within Tensorflow to train your own machine learning model, with a focus on separating humans from the background of a photograph in order to perform background replacement.. If you'd rather watch this on Youtube, see the deeplab training tutorial here, and the openCV visualization / background swapping tutorial here
- models/research/deeplab/README.md at master - GitHub — You signed in with another tab or window. Reload to refresh your session. You signed out in another tab or window. Reload to refresh your session. You switched accounts on another tab or window.