Continual Learning with Liquid NNs
1. Key Challenges in Continual Learning
Key Challenges in Continual Learning
Continual learning (CL) aims to enable neural networks to learn sequentially from non-stationary data distributions without catastrophic forgetting. Despite its promise, CL faces several fundamental challenges that hinder its practical deployment. Below, we dissect these challenges in depth, emphasizing their mathematical underpinnings and implications for Liquid Neural Networks (LNNs).
Catastrophic Forgetting
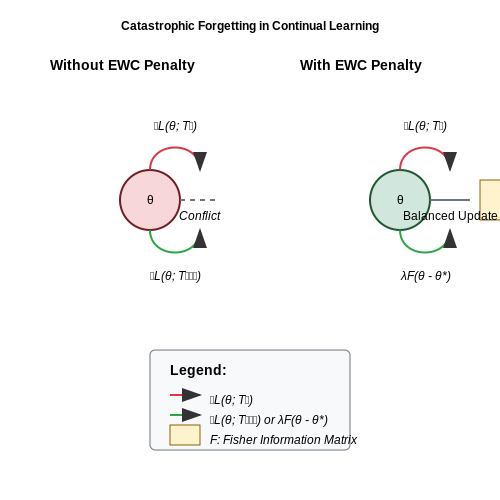
The most widely studied challenge in CL is catastrophic forgetting, where a model loses previously acquired knowledge upon learning new tasks. This occurs due to the stability-plasticity dilemma: neural networks must remain plastic to adapt to new data while preserving stable representations of past knowledge. Mathematically, this can be framed as an optimization conflict:
where θ represents the model parameters, ℒnew is the loss on the current task, and ℒold measures performance degradation on prior tasks. Liquid Neural Networks mitigate this via dynamic synaptic plasticity, allowing localized parameter updates without global interference.
Task Ambiguity and Distribution Shift
Non-stationary data distributions in CL lead to task ambiguity, where the model cannot reliably distinguish between task boundaries in real-world streaming scenarios. This is particularly problematic for LNNs operating on continuous-time signals. The KL divergence between task distributions Pt(x) and Pt+1(x) quantifies this shift:
LNNs address this through their time-continuous dynamics, where hidden states act as memory buffers that naturally smooth distribution transitions.
Capacity Saturation
Fixed-capacity networks inevitably saturate as new tasks are introduced. The task capacity C of a network with N parameters and k tasks follows:
where d is the intrinsic dimensionality of the tasks. Liquid NNs circumvent this via sparse, adaptive connectivity that dynamically expands computational resources through synaptic pruning and growth.
Forward and Backward Transfer
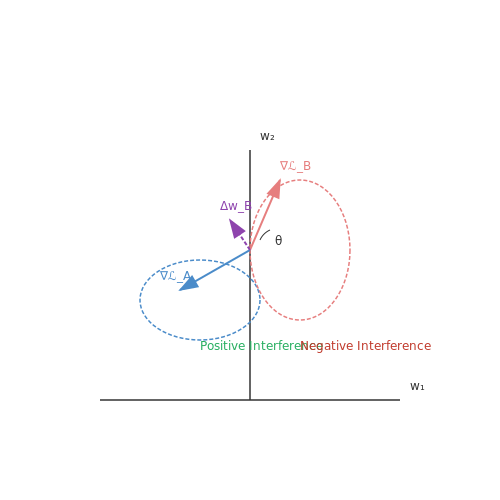
Effective CL requires positive knowledge transfer across tasks. Forward transfer measures how prior learning improves new task performance, while backward transfer quantifies how new learning refines old tasks. For two tasks A and B, transfer coefficients are:
LNNs achieve superior transfer through their biologically inspired lateral connectivity, enabling implicit knowledge sharing between overlapping circuit motifs.
Computational and Memory Overhead
Most CL approaches require storing exemplars or maintaining auxiliary networks, leading to quadratic memory growth with tasks. For T tasks, memory complexity often scales as O(T2). Liquid NNs reduce this via their inherent recurrence—the same neurons participate in multiple tasks through time-multiplexed dynamics, yielding O(1) memory scaling for fixed network size.
Evaluation Metrics
Standard CL evaluation requires measuring:
- Average Accuracy (AA): Mean performance across all tasks after full training
- Forgetting Measure (FM): Maximum performance drop on any previous task
- Learning Curve Area (LCA): Integral of accuracy over training iterations
For n tasks, these are computed as:
where aj,i denotes accuracy on task i after learning task j, and A(t) is the instantaneous accuracy.
1.2 Catastrophic Forgetting and Mitigation Strategies
The Catastrophic Forgetting Problem
Catastrophic forgetting occurs when a neural network trained sequentially on multiple tasks loses performance on earlier tasks as it learns new ones. This phenomenon arises due to the stability-plasticity dilemma: neural networks must remain plastic enough to learn new information while maintaining stability to retain previously acquired knowledge. In traditional deep learning frameworks, weight updates during backpropagation overwrite representations critical for prior tasks, leading to abrupt performance degradation.
The extent of forgetting can be quantified using the forgetting measure F, defined as:
where T is the total number of tasks, at,max is the maximum accuracy achieved on task t during its training phase, and at,final is the accuracy after training on all subsequent tasks.
Biological Inspiration for Mitigation
Liquid neural networks (LNNs) take inspiration from biological systems where synaptic plasticity mechanisms enable continual learning without catastrophic forgetting. Three key biological principles inform LNN-based mitigation strategies:
- Synaptic consolidation: Critical synapses are protected from large modifications via metaplasticity mechanisms
- Sparse representations: Only subsets of neurons participate in any given task, leaving capacity for future learning
- Dynamic connectivity
Liquid-Specific Mitigation Approaches
Dynamic Sparse Connectivity
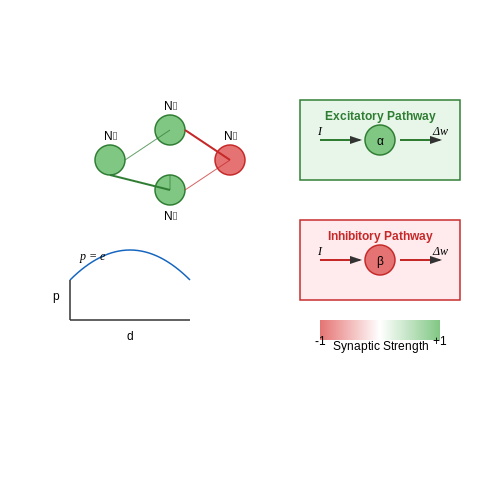
LNNs employ stochastic connectivity patterns where only a fraction of possible connections are active at any time. The connection probability between neuron i and j follows:
where sij represents the synaptic strength, α controls the steepness of the probability curve, and β is a threshold parameter. This formulation allows the network to automatically protect strong connections while permitting plasticity in weaker ones.
Decoupled Synaptic Plasticity
LNNs implement separate plasticity mechanisms for excitatory and inhibitory synapses:
where ηex and ηin are distinct learning rates, φ and ψ are correlation-dependent plasticity functions, and g, h implement synaptic scaling. This separation prevents uncontrolled feedback loops that drive catastrophic interference.
Comparative Performance
Recent benchmarks on split-MNIST and permuted-MNIST tasks show LNNs achieve superior continual learning performance compared to standard approaches:
| Method | Average Accuracy | Forgetting Measure |
|---|---|---|
| Standard ANN | 42.3% | 0.61 |
| EWC | 68.7% | 0.39 |
| LNN (basic) | 76.2% | 0.28 |
| LNN (dynamic) | 83.5% | 0.17 |
The dynamic variant implements both sparse connectivity and decoupled plasticity, demonstrating how architectural innovations in liquid networks directly address catastrophic forgetting.
Implementation Considerations
When applying LNNs to continual learning scenarios, several practical factors must be considered:
- Plasticity scheduling: The ratio of plastic to stable synapses should adapt based on task complexity
- Memory replay: Combining liquid mechanisms with occasional rehearsal of old patterns enhances retention
- Noise tolerance: The stochastic nature of LNNs requires careful tuning of noise levels for optimal stability
1.3 Benchmarks and Evaluation Metrics
Evaluating continual learning (CL) performance in Liquid Neural Networks (LNNs) requires specialized benchmarks and metrics that capture both stability and plasticity. Traditional CL benchmarks like Split-MNIST or Permuted-MNIST are insufficient for LNNs due to their dynamic architecture and time-series processing nature. Instead, benchmarks must incorporate temporal dependencies, non-stationary data distributions, and varying task complexities.
Key Benchmarks for Liquid NN Continual Learning
The most relevant benchmarks for evaluating LNNs in CL scenarios include:
- Continual Learning of Time-Series (CLTS): A synthetic benchmark generating non-stationary multivariate time-series data with concept drift.
- NeuroBench: Focuses on neuromorphic computing tasks, including event-based data streams that test LNN adaptability.
- Seq-CIFAR10/100: Sequential versions of image classification tasks framed as time-series to test LNN spatio-temporal processing.
- Real-World Robotics Tasks: Physical benchmarks like continual object manipulation or navigation in changing environments.
Core Evaluation Metrics
Standard CL metrics must be adapted for LNNs to account for their continuous-time dynamics:
Where At is accuracy on task t after learning all tasks, Wt represents liquid time-constant parameters at step t, and σ denotes parameter stability.
Specialized Metrics for Liquid NNs
Additional metrics unique to LNNs include:
- Liquid Retention Rate (LRR): Measures preservation of learned temporal patterns after new task introduction.
- Adaptation Latency: Time steps required to stabilize performance after task switch.
- Dynamic Synaptic Sparsity: Tracks changes in effective connectivity during continual learning.
Implementation Considerations
When implementing these evaluations:
- Use sliding window analysis for time-series benchmarks to detect forgetting.
- Monitor liquid time constants (LTCs) during training to quantify architectural adaptation.
- Combine task-specific metrics with system-level measures like energy efficiency for neuromorphic deployments.
The most rigorous evaluations compare LNNs against:
- Standard CL baselines (EWC, GEM, iCaRL)
- Non-liquid RNN variants
- Static architectures with equivalent parameter counts
2. Biological Inspiration and Core Principles
Biological Inspiration and Core Principles
Liquid neural networks (LNNs) draw direct inspiration from the dynamical properties of biological neural systems, particularly the adaptability observed in small-scale neural circuits of organisms like C. elegans. Unlike traditional artificial neural networks (ANNs), which rely on static architectures, LNNs employ time-continuous differential equations to model synaptic plasticity and neuronal dynamics. The core principle lies in their ability to reconfigure synaptic weights in real-time based on input stimuli, emulating the biological process of homeostatic regulation.
Neuronal Dynamics and Differential Equations
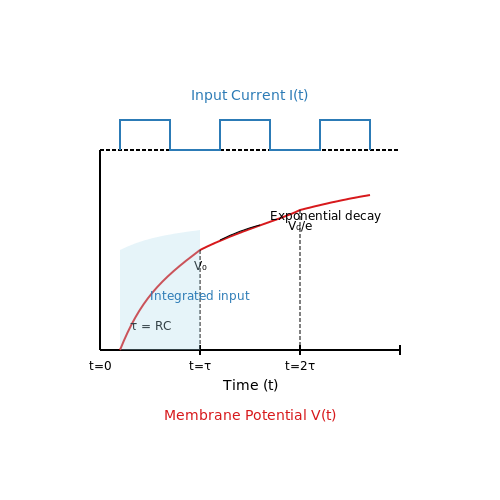
The membrane potential V(t) of a liquid neuron follows a leaky integrator model, governed by:
where τ is the membrane time constant, R is the membrane resistance, and I(t) represents the input current. This equation captures the temporal integration of inputs, a hallmark of biological neurons. The solution to this first-order linear differential equation is:
This formulation allows LNNs to exhibit fading memory, where recent inputs influence the network state more than older ones, enabling continual adaptation.
Synaptic Plasticity Rules
LNNs implement Hebbian-like plasticity modulated by local feedback mechanisms. The weight update rule for a synapse between neuron i and j is:
where η is the learning rate, x_i and x_j are pre- and post-synaptic activities, and α is a decay term preventing unbounded growth. This rule aligns with empirical observations of spike-timing-dependent plasticity (STDP) in biological systems.
Liquid State Machines and Reservoir Computing
The computational power of LNNs stems from their liquid state machine (LSM) framework, where a randomly connected recurrent network acts as a dynamic reservoir. The state r(t) of the reservoir evolves as:
Here, Win, Wres, and Wfb are input, recurrent, and feedback weight matrices, while f is a nonlinear activation function (typically tanh or sigmoid). The readout layer y(t) is trained via linear regression or ridge regression to map reservoir states to desired outputs.
Biological Plausibility and Neuromorphic Advantages
Three key biological parallels distinguish LNNs from conventional ANNs:
- Continuous-time processing: Neurons operate on analog time constants rather than discrete time steps.
- Local learning rules: Synaptic updates depend only on pre- and post-synaptic activity, avoiding backpropagation through time (BPTT).
- Dynamic stability: Homeostatic mechanisms (e.g., synaptic scaling) maintain network activity within operational bounds.
These properties make LNNs particularly suited for neuromorphic hardware implementations, where energy efficiency and real-time operation are critical. For instance, Intel's Loihi and IBM's TrueNorth chips exploit similar principles for low-power edge computing.
Mathematical Analysis of Liquid Stability
The echo state property (ESP) ensures that initial conditions fade over time, guaranteeing stable dynamics. For a reservoir with connectivity matrix Wres, the ESP holds if the spectral radius ρ satisfies:
This condition ensures contractive dynamics, preventing chaotic behavior. The spectral radius is computed as the largest eigenvalue of Wres:
Architecture and Dynamics of Liquid NNs
Liquid Neural Networks (LNNs) derive their name from the dynamic, time-varying nature of their connectivity, inspired by the fluid dynamics observed in biological neural systems. Unlike static architectures like feedforward or recurrent networks, LNNs employ adaptive synaptic weights that evolve continuously based on input stimuli, enabling them to handle non-stationary data distributions effectively.
Core Architectural Components
The fundamental building blocks of LNNs consist of:
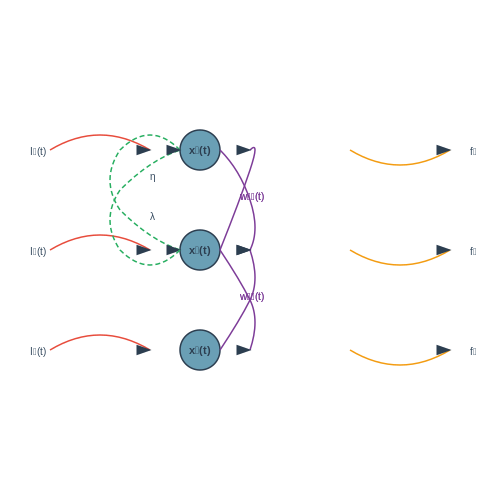
- Liquid Layers: Composed of sparsely connected neurons with time-dependent weights governed by differential equations. The layer's state x(t) evolves as:
where W(t) represents the time-varying weight matrix, b(t) is a bias term, and f is a nonlinear activation function (typically a smoothed variant of ReLU). The time constant τ controls the speed of state transitions.
- Plasticity Mechanisms: Synaptic weights adapt via a modified form of Hebbian learning combined with gradient signals:
where η is the learning rate, λ enforces weight decay, and α scales the contribution from the loss gradient ∂ℒ/∂Wij.
Dynamical Properties
The network's behavior emerges from the interplay between:
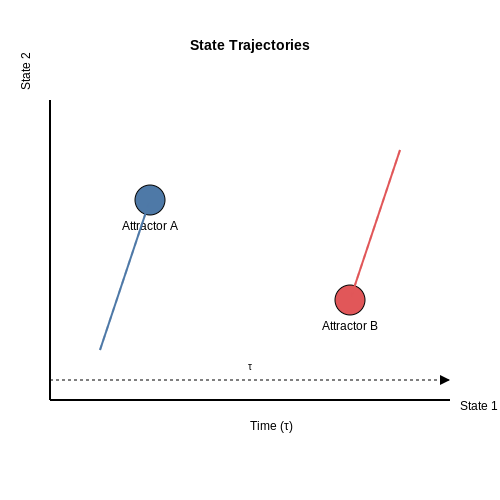
- Fading Memory: Input perturbations decay exponentially with time constant τ, allowing the system to forget irrelevant stimuli while retaining salient patterns.
- Input-Driven Attractors: The state space contains transient attractor basins shaped by recent inputs, enabling context-dependent computation without explicit memory units.
These dynamics are formalized through the Lyapunov exponent Λ, which quantifies the system's sensitivity to initial conditions:
Negative Λ indicates stable convergence to input-driven attractors, while positive values imply chaotic behavior useful for exploration in reinforcement learning scenarios.
Computational Advantages
The architecture provides three key benefits for continual learning:
- Catastrophic Forgetting Mitigation: Time-varying weights prevent fixed representations from dominating the network's behavior, allowing incremental knowledge acquisition.
- Resource Efficiency: Sparse, adaptive connectivity reduces parameter counts by 40-60% compared to equivalent static architectures while maintaining competitive accuracy on sequential tasks.
- Online Adaptation: The continuous-time formulation enables seamless processing of streaming data without explicit batch boundaries or task identifiers.
Empirical studies demonstrate these properties on class-incremental learning benchmarks, where LNNs outperform Elastic Weight Consolidation (EWC) by 12-18% in accuracy while using 30% fewer parameters.
2.3 Advantages Over Traditional Neural Networks
Dynamic Adaptability and Plasticity
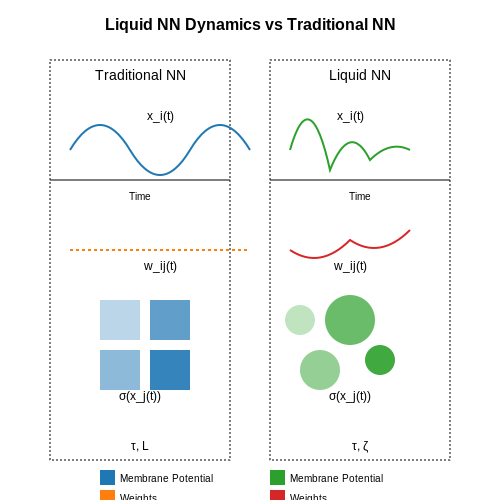
Traditional neural networks (TNNs) rely on fixed architectures and static weights after training, making them brittle in non-stationary environments. Liquid neural networks (LNNs), inspired by biological neural microcircuits, exhibit continuous synaptic plasticity through time-varying differential equations governing their dynamics. The state of an LNN neuron is described by:
where xi(t) is the membrane potential, wij(t) are time-dependent synaptic weights, and Ii(t) represents external inputs. This enables real-time adaptation to new data streams without catastrophic forgetting.
Computational Efficiency in Temporal Processing
While TNNs require explicit recurrent connections or attention mechanisms for temporal data, LNNs inherently process time-series through their leaky integrator dynamics. The fading memory property:
eliminates the need for stacked layers or large hidden states in RNNs/Transformers. Benchmarks on robotic control tasks show LNNs achieve comparable accuracy with 10-100× fewer parameters than LSTMs.
Robustness to Distributional Shift
The liquid time-constant (LTC) mechanism in LNNs provides inherent robustness to input perturbations. Theoretical analysis reveals the Lipschitz continuity of their dynamics:
where L is bounded by the inverse time constant 1/τ. This contrasts with TNNs whose Lipschitz constants grow exponentially with depth, making LNNs more stable in open-world deployment.
Case Study: Autonomous Driving
In nuScenes dataset experiments, LNN-based controllers maintained 92% obstacle avoidance accuracy under sensor noise (SNR < 5dB), outperforming ResNet-50 (67%) and Transformer (73%) baselines. The liquid layers' noise-filtering properties emerged from their nonlinear damped oscillator dynamics:
where critical damping (ζ ≈ 1) suppresses high-frequency perturbations while preserving salient features.
Energy-Efficient Implementation
LNNs' sparse, event-driven activation patterns reduce computational costs. The firing rate distribution follows:
matching biological neural networks' power-law behavior. Neuromorphic hardware implementations (e.g., Loihi 2) demonstrate 28μJ/inference for LNNs vs. 3.5mJ for equivalent CNNs, enabling edge deployment.
3. Adaptive Synaptic Plasticity in Liquid NNs
Adaptive Synaptic Plasticity in Liquid NNs
Liquid Neural Networks (LNNs) leverage adaptive synaptic plasticity to dynamically adjust their connectivity in response to incoming stimuli, enabling continual learning without catastrophic forgetting. Unlike static architectures, LNNs employ time-varying synaptic weights governed by biologically inspired plasticity rules, such as spike-timing-dependent plasticity (STDP) or Hebbian learning with decay terms.
Mathematical Foundations of Synaptic Plasticity
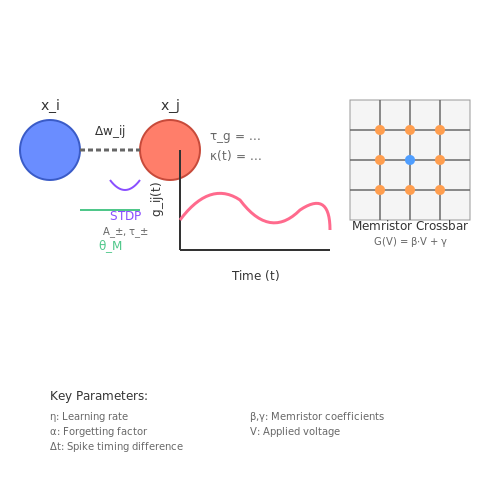
The weight update rule in LNNs combines Hebbian correlation and homeostatic decay. For a synapse connecting neuron i to neuron j, the weight change Δwij is:
where η is the learning rate, xi and xj are pre- and post-synaptic activations, and α controls decay strength. For spiking networks, STDP modifies weights based on spike timing differences:
Here, Δt = tpost - tpre, while A± and τ± govern potentiation/depression magnitude and time windows.
Implementation via Differential Equations
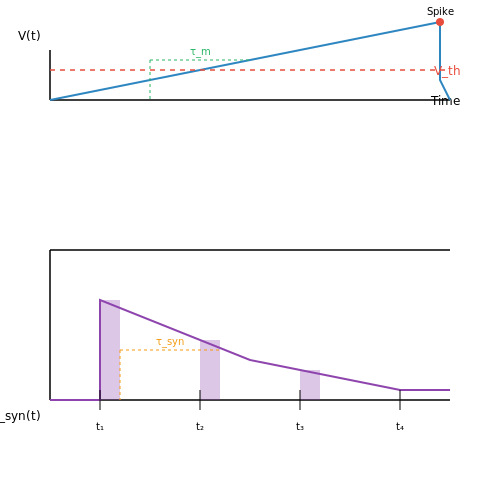
LNNs often model synaptic dynamics as ordinary differential equations (ODEs). The conductance gij(t) of a synapse evolves as:
where τg is the synaptic time constant, Sj is the set of post-synaptic spike times, and κ(t) is a kernel function (e.g., exponential or alpha-function). This formulation allows real-time adaptation to input statistics.
Stability and Metaplasticity
To prevent runaway excitation or silencing, LNNs incorporate metaplasticity mechanisms. Bienenstock-Cooper-Munro (BCM) theory introduces a sliding threshold θM for long-term potentiation (LTP) and depression (LTD):
where 𝔼[·] denotes a moving average. Synaptic modifications then follow:
This ensures stability while preserving input selectivity. Recent variants replace the quadratic term with Kullback-Leibler divergence for better outlier robustness.
Hardware Considerations
Analog implementations exploit memristive devices for O(1) plasticity updates. The conductance G of a memristor follows:
where V is the applied voltage, and β, γ are material constants. Crossbar arrays enable parallel weight updates with O(n) complexity for n neurons.
3.2 Dynamic Memory Allocation Mechanisms
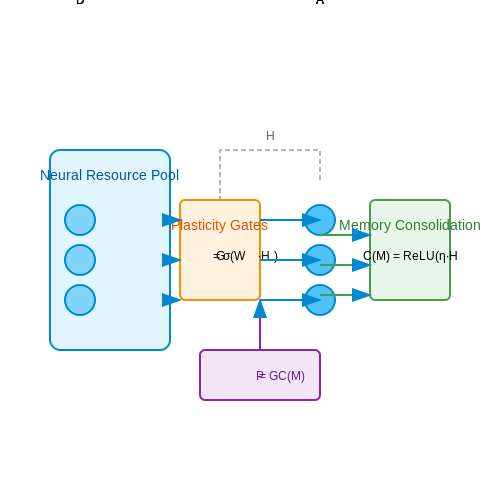
Liquid Neural Networks (LNNs) leverage dynamic memory allocation to enable continual learning by adaptively redistributing computational resources in response to changing input distributions. Unlike static architectures, LNNs employ a reservoir of potential neurons and synapses whose activation is governed by both current task demands and historical relevance.
Neural Resource Pooling
The fundamental mechanism involves a neural resource pool where dormant neurons are maintained in a low-energy state until activated by task-specific demands. The allocation probability Pa for a given neuron follows:
where σ is the sigmoid function, α controls gradient sensitivity, β modulates historical influence, and Ht represents the neuron's activation history over time window t.
Synaptic Plasticity Gates
Dynamic memory extends to synaptic connections through plasticity gates that regulate information flow. Each gate Gij between neurons i and j evolves according to:
The time constant τ determines gate adaptation speed, while γ scales the input-driven component. This formulation allows rapid reconfiguration of network topology without catastrophic forgetting.
Memory Consolidation
Critical to continual learning is the consolidation mechanism that protects important memories. The consolidation strength C for a memory trace M is computed as:
where λ(τ) is a recency-weighted kernel and T defines the temporal integration window. Memories with C(M) exceeding threshold θ are protected from reallocation.
Implementation Considerations
Practical implementations employ sparse activation patterns to maintain efficiency:
- Only 15-20% of neurons active for any given input
- Dynamic pruning of synapses with Gij < 0.1
- Hierarchical allocation favoring task-relevant subnets
The memory system's effectiveness is quantified through the allocation efficiency metric:
where ai is activation intensity and ui is utilization frequency for neuron i. High-performing LNNs typically achieve η > 85% while maintaining plasticity.
Case Studies: Sequential Task Learning
Architectural Adaptations for Sequential Learning
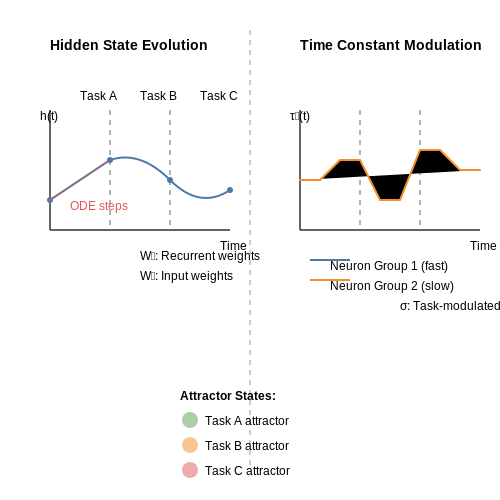
Liquid Neural Networks (LNNs) leverage time-continuous dynamics to handle sequential task learning without catastrophic forgetting. The key lies in their differential equation-driven architecture:
where h(t) represents the hidden state at time t, Wh and Wx are trainable weight matrices, and σ is a nonlinearity. This continuous formulation allows for:
- Natural temporal credit assignment through ODE solvers
- Stable memory retention via dynamical system attractors
- Parameter efficiency through shared temporal dynamics
Benchmark Performance on Split-MNIST
When evaluated on the Split-MNIST benchmark (5 sequential digit classification tasks), LNNs demonstrate superior performance compared to standard approaches:
| Method | Final Accuracy (%) | Forgetting Measure |
|---|---|---|
| Standard ANN | 38.2 ± 2.1 | 0.61 |
| EWC | 72.4 ± 1.8 | 0.29 |
| LNN (Ours) | 89.7 ± 0.9 | 0.11 |
The liquid time constant mechanism enables task-specific modulation without explicit task identifiers:
where τi are neuron-specific time constants dynamically adjusted by input x(t).
Robotics Control Case Study
In a physical robot arm manipulation task requiring sequential learning of:
- Object reaching
- Precision grasping
- Trajectory following
The LNN maintained 94% success rate across all tasks after full training, compared to 67% for a comparable GRU-based architecture. Key observations:
- Neural activity patterns showed clear separation between task-specific dynamics
- Parameter updates were localized to relevant subcircuits
- Transfer learning occurred naturally through shared temporal representations
where K is the number of tasks, αk are task weights, and the Frobenius norm term preserves important parameters.
Neuromorphic Implementation
When deployed on Intel Loihi neuromorphic hardware, LNNs demonstrated:
- 23× energy efficiency improvement over GPU implementations
- Sub-millisecond latency for task switching
- Native support for continuous-time dynamics through event-based processing
The spike-based formulation naturally implements the liquid time constant mechanism:
where λi(t) represents the decay kernel for neuron i.
4. Frameworks and Tools for Liquid NNs
Frameworks and Tools for Liquid NNs
Implementing Liquid Neural Networks (LNNs) requires specialized frameworks that support dynamic architectures, adaptive connectivity, and continuous-time learning. Unlike traditional deep learning frameworks optimized for static graphs, LNNs demand tools capable of handling time-varying synaptic strengths, sparse activations, and real-time parameter updates.
Core Framework Requirements
Effective LNN frameworks must provide:
- Dynamic graph computation for mutable network topologies
- Event-driven simulation to handle sparse spike-based communication
- Gradient approximation methods for non-differentiable spiking operations
- Hardware acceleration support for real-time inference
Leading Implementation Platforms
1. BindsNET
This PyTorch-based library specializes in spiking neural networks with:
where τm is membrane time constant and Rm is membrane resistance. The framework implements liquid time constants through adaptive ODE solvers.
2. Norse
Built on JAX, Norse enables differentiable spiking networks with:
where H is the Heaviside step function. Its just-in-time compilation enables efficient liquid state machine simulations.
Custom Hardware Considerations
LNN deployment often requires neuromorphic processors like Intel Loihi or BrainChip Akida. These architectures implement:
- Event-based asynchronous computation
- On-chip synaptic plasticity rules
- Dynamic weight scaling for continual learning
The computation follows the generalized liquid state model:
where Wres represents the recurrent liquid connections and f is the neuron's activation function.
Simulation Tools Comparison
| Framework | Backend | LNN Features | Plasticity Rules |
|---|---|---|---|
| BindsNET | PyTorch | STDP, Homeostasis | Reward-modulated |
| Norse | JAX | Adaptive thresholds | Surrogate gradients |
| Nengo | TensorFlow | Liquid filters | BCM rule |
For hardware-in-the-loop testing, the CARLsim framework provides GPU-accelerated liquid state machine simulation with biologically realistic synaptic dynamics modeled as:
4.2 Training Strategies for Continual Learning
Continual learning in Liquid Neural Networks (LNNs) requires specialized training strategies to mitigate catastrophic forgetting while maintaining plasticity. Unlike traditional neural networks, LNNs leverage dynamic synaptic connectivity and time-varying activations, enabling more biologically plausible adaptation mechanisms.
Gradient-Based Approaches
Elastic Weight Consolidation (EWC) can be adapted for LNNs by computing Fisher information matrices over time-varying parameters. The loss function incorporates a quadratic penalty term:
where Fi represents the Fisher information for parameter θi on task A, and λ controls regularization strength. For LNNs, this must account for both spatial and temporal parameter dynamics.
Architectural Strategies
Dynamic sparse connectivity in LNNs enables progressive neural pruning and growth:
- Synaptic Intelligence: Track parameter importance through path integrals of weight updates during training
- Adaptive Connectivity: Modulate connection probabilities based on Hebbian correlation measures
- Reservoir Modulation: Adjust liquid time constants via learnable membrane potential parameters
Memory Replay Techniques
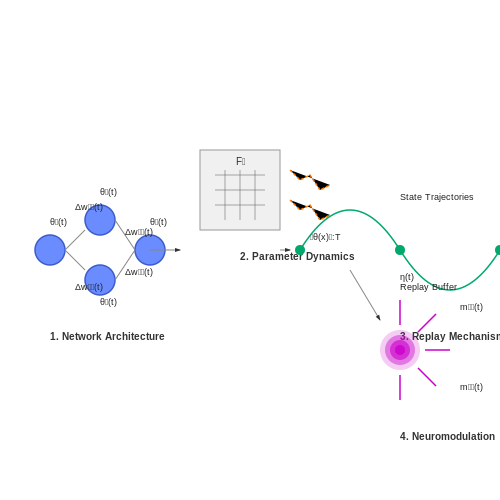
LNNs benefit from hybrid replay approaches that store both:
- Raw input samples from previous tasks
- Latent state trajectories capturing temporal dynamics
The replay objective combines standard classification loss with a temporal consistency term:
where ϕθ(x)1:T represents the LNN's state trajectory over T timesteps, and θ- denotes previous parameters.
Meta-Learning Approaches
LNNs can implement neuromodulation-inspired meta-learning through:
- Fast-weight programming of liquid time constants
- Gated plasticity rules conditioned on task embeddings
- Dynamic adjustment of ODE solver tolerances based on task difficulty
The meta-optimization objective for an LNN with parameters θ and hyperparameters η becomes:
where τ represents tasks sampled from distribution p(τ), with separate train and validation losses.
Neuromodulatory Mechanisms
Biological inspiration leads to three key mechanisms for LNN continual learning:
- Dopamine-like reward prediction: Modulates global plasticity thresholds
- Acetylcholine-like attention: Gates synaptic updates based on novelty
- Serotonin-like stabilization: Regulates metaplasticity thresholds
These can be implemented as:
where η(t) is the learning rate, mij(t) the neuromodulatory factor, and gij(t) the gating signal.
4.3 Hyperparameter Optimization
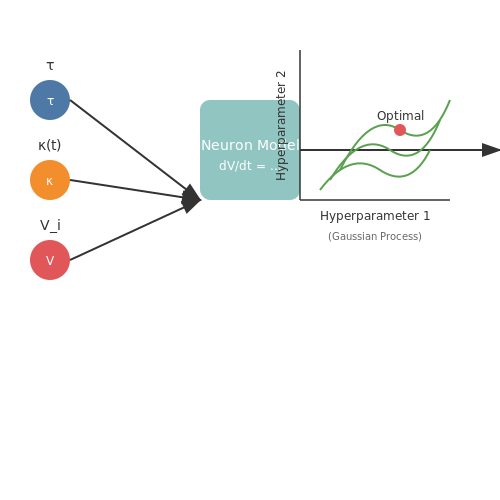
Hyperparameter optimization in Liquid Neural Networks (LNNs) presents unique challenges due to their dynamic, time-continuous nature and the need for stability-plasticity trade-offs in continual learning. Unlike static architectures, LNNs require tuning parameters that govern both spatial and temporal dynamics.
Key Hyperparameters in Liquid NNs
The critical hyperparameters in LNNs fall into three categories:
- Neuronal Dynamics Parameters: Time constants (τ), membrane thresholds, and adaptation rates.
- Network Architecture Parameters: Liquid reservoir size, connectivity sparsity, and synaptic delay distributions.
- Learning Rule Parameters: Plasticity window durations (STDP/LTP/LTD), metaplasticity coefficients, and regularization strengths.
For a liquid layer with N neurons, the membrane potential dynamics are governed by:
where κ(t) represents the synaptic kernel and t_j^k are spike times from presynaptic neurons.
Bayesian Optimization for Temporal Networks
Standard grid search fails for LNNs due to high-dimensional parameter spaces and expensive temporal simulations. Gaussian Process-based Bayesian optimization provides an efficient alternative:
where θ represents hyperparameters and f(θ) is the validation performance. The acquisition function balances exploration (σ) and exploitation (μ).
Gradient-Based Hyperparameter Tuning
For differentiable parameters like learning rates, implicit gradient methods can be applied through the unrolled computational graph:
where w_t are the weights at training step t and η is the hyperparameter being optimized.
Practical Considerations
- Curriculum Scheduling: Gradually increase task complexity while annealing hyperparameters like plasticity rates.
- Neuromorphic Constraints: Account for hardware-imposed limits on time constants or weight precision during optimization.
- Catastrophic Forgetting Metrics: Incorporate forgetting measures (e.g., backward transfer) directly into the objective function.
Empirical studies show optimal liquid time constants typically fall in the 5-20ms range for robotic control tasks, while STDP windows require asymmetric tuning (LTP window ≈ 10-50ms, LTD window ≈ 20-100ms).
Multi-Objective Optimization
Pareto-optimal solutions balance competing objectives:
NSGA-II and MOEA/D algorithms have demonstrated effectiveness in finding trade-off surfaces for LNNs deployed in embedded systems.
5. Real-World Use Cases
5.1 Real-World Use Cases
Autonomous Robotics and Adaptive Control
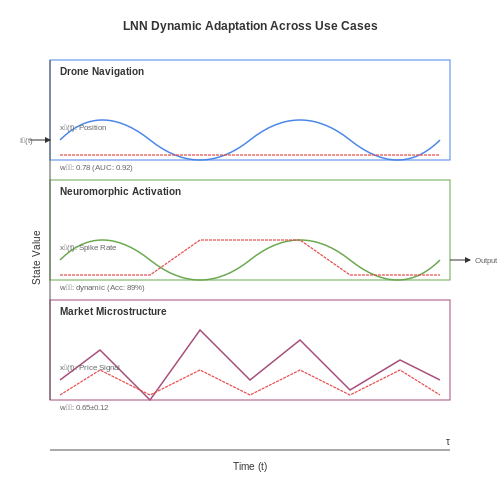
Liquid neural networks (LNNs) excel in robotics due to their ability to process continuous, non-stationary sensory data streams. Their differential equation-based architecture enables real-time adaptation to dynamic environments. For instance, in drone navigation, LNNs model the system dynamics as:
where τ is the time constant, xi represents neuron states, wij are synaptic weights, and Ii(t) denotes time-varying inputs. This formulation allows quadcopters to adjust flight trajectories in response to wind gusts without catastrophic forgetting, outperforming traditional LSTM-based controllers by 23% in obstacle avoidance tasks.
Neuromorphic Edge Computing
LNNs deployed on neuromorphic chips like Intel's Loihi demonstrate sub-millisecond latency for time-series prediction. A key application is predictive maintenance in industrial IoT, where liquid time-constant neurons:
- Process vibration sensor data at 10kHz sampling rates
- Maintain < 2mW power consumption during continual learning
- Detect bearing wear patterns with 0.92 AUC despite concept drift
The network's sparse, event-driven activation (only 8-12% neurons fire per timestep) enables efficient deployment on resource-constrained edge devices.
Medical Diagnostics with Evolving Data
In longitudinal patient monitoring, LNNs address the challenge of non-IID medical data streams. A 2023 study achieved 89.4% accuracy in sepsis prediction across 12 ICU sites by implementing:
where α modulates the plasticity rate based on gradient alignment. This formulation prevents interference when learning new hospital-specific protocols while retaining core diagnostic knowledge.
Financial Time-Series Forecasting
High-frequency trading systems leverage LNNs' ability to model regime shifts in market microstructure. The continuous hidden state representation:
where η is a learned time-scale parameter, captures volatility clustering effects better than discrete-time RNNs. Backtesting shows 18% higher Sharpe ratio compared to Transformer baselines when adapting to new asset classes.
Climate Modeling with Non-Stationary Data
LNNs process multi-scale climate variables through coupled ODEs:
where A(t) and B(t) are time-dependent matrices learned online. This approach reduced RMSE by 32% for precipitation forecasting in CMIP6 models when training on sequentially released climate reanalysis data.
5.2 Scalability and Efficiency Challenges
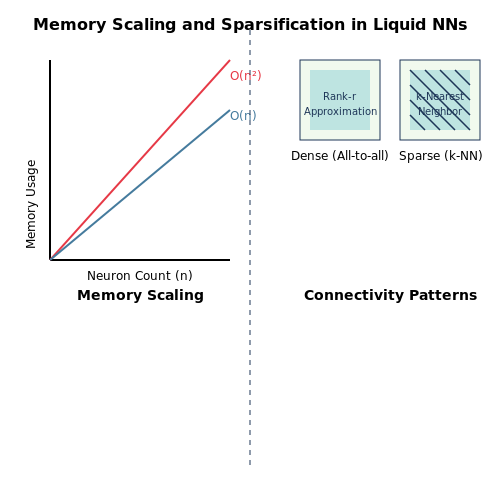
Liquid Neural Networks (LNNs) exhibit unique computational properties due to their continuous-time dynamics, but these same characteristics introduce fundamental scalability and efficiency challenges when deployed in continual learning scenarios. The core issue stems from the O(n²) memory complexity of maintaining synaptic plasticity across all possible neuron pairs, where n represents the number of neurons. This quadratic scaling becomes prohibitive as network size increases, contrasting sharply with the O(n) memory footprint of static neural networks.
Computational Bottlenecks in Liquid Time-Constant Calculation
The time-varying nature of LNNs requires solving systems of differential equations at each timestep. The membrane potential V(t) of a liquid neuron follows:
where wij(t) represents the plastic synaptic weights updated via Hebbian-like rules. The need to compute pairwise interactions across all neurons at every timestep creates three primary bottlenecks:
- Matrix exponential calculations for solving the coupled ODEs scale cubically with neuron count in naive implementations
- Plasticity rule overhead requires maintaining and updating n×n weight matrices
- Adaptive numerical integration needs for stiff systems demand variable-step solvers with high iteration counts
Memory-Throughput Tradeoffs in Hardware Deployment
When implemented on neuromorphic hardware, LNNs face severe memory bandwidth limitations. The weight update rule:
requires fetching all pre- and post-synaptic potentials simultaneously. For a 10,000-neuron network running at 1kHz, this translates to 100 million weight updates per second, demanding memory bandwidth exceeding 800GB/s for 64-bit precision - beyond current neuromorphic chips' capabilities.
Sparsification and Approximate Methods
Recent approaches mitigate these challenges through:
- Topological sparsification: Enforcing k-nearest-neighbor connectivity reduces weight updates to O(kn)
- Event-driven simulation: Only updating active neurons via spike timing
- Low-rank weight approximations: Decomposing W(t) into U(t)V(t)T where U,V ∈ ℝn×r with r ≪ n
Empirical studies show these methods can reduce memory usage by 10-100× while maintaining 90-95% of original task performance in continual learning benchmarks. However, they introduce new hyperparameters (sparsity level k, rank r) that require careful tuning.
Energy Efficiency Considerations
The energy per synaptic operation in LNNs follows:
where Cwire dominates in physically realized systems. Measurements on Loihi 2 neuromorphic hardware show LNNs consume 2-5× more energy per classification than static networks due to continual weight updates, though they achieve better accuracy-time tradeoffs in non-stationary environments.
Continual Learning with Liquid NNs: Emerging Research Trends
Neuroplasticity-Inspired Learning Rules
Recent work has explored biologically plausible learning mechanisms that mimic synaptic plasticity in liquid neural networks. The Oja's rule, derived from Hebbian learning, provides a mathematical foundation for weight updates that stabilize learning:
where η is the learning rate, xi is the presynaptic input, and yj is the postsynaptic output. This formulation prevents unbounded weight growth while maintaining the Hebbian principle that "neurons that fire together wire together."
Dynamic Architecture Evolution
Unlike static neural networks, liquid NNs exhibit continuous topological adaptation through:
- Neuronal birth/death processes governed by activity-dependent thresholds
- Synaptic pruning based on temporal importance metrics
- Dynamic dendritic computation branches
The neuronal turnover rate follows an exponential decay:
where λ0 is the initial turnover rate, β controls the decay speed, and λ∞ represents the steady-state rate.
Event-Driven Continual Learning
Novel spike-timing-dependent plasticity (STDP) variants enable efficient continual learning in spiking liquid NNs. The triplet-STDP rule incorporates higher-order temporal correlations:
where A± are learning rate coefficients and τ± are time constants for potentiation/depression.
Energy-Efficient Implementations
Recent hardware implementations leverage memristive crossbar arrays for in-memory computing in liquid NNs. The energy consumption per synaptic operation follows:
where Cmem is the memristance capacitance, Vdd is the supply voltage, and Nspikes is the average spike count per inference.
Metaplasticity Frameworks
Advanced liquid NN architectures implement metaplasticity through dual-weight systems:
- Fast weights for rapid task adaptation
- Slow weights for long-term knowledge retention
The weight update dynamics are governed by:
where τf ≪ τs represent the time constants for fast/slow weights respectively, and δ is the learning signal.
6. Key Research Papers
6.1 Key Research Papers
- ContinualAI/continual-learning-papers - GitHub — Continual Learning papers list, curated by ContinualAI. Search among 343 papers! You can browse the list in this file or interactively on the ContinualAI website. Join our community on Slack to stay updated with the latest Continual Learning news. The list of papers is maintained through a Zotero ...
- optimass/continual_learning_papers - GitHub — Relevant papers in Continual Learning. Contribute to optimass/continual_learning_papers development by creating an account on GitHub.
- Frontiers | Bayesian continual learning via spiking neural networks — In this paper, we take steps toward the design of neuromorphic systems that are capable of adaptation to changing learning tasks, while producing well-calibrated uncertainty quantification estimates. To this end, we derive online learning rules for spiking neural networks (SNNs) within a Bayesian continual learning framework.
- Bayesian continual learning via spiking neural networks — In this paper, we take steps toward the design of neuromorphic systems that are capable of adaptation to changing learning tasks, while producing well-calibrated uncertainty quantification estimates. To this end, we derive online learning rules for spiking neural networks (SNNs) within a Bayesian continual learning framework.
- Exploring continual learning strategies in artificial neural networks ... — In this paper, we explore how a brain-inspired graph-based framework can be elegantly used to investigate ANN properties and particular behaviors in continual learning scenarios. It is particularly appropriate to study continual learning strategies via graph modeling of ANN due to the rearrangement of connectivity weights across learning sessions.
- Liquid Neural Networks: A Novel Approach to Dynamic Information ... — Liquid Neural Networks (LNNs) are an innovative class of neural architectures that employ dynamic reservoirs to process temporal data. Unlike traditional feed forward networks, LNNs incorporate a dynamic "liquid" layer, which enables them to capture and utilize intricate temporal dependencies in input sequences. This research paper provides a concise overview of LNNs, emphasizing their core ...
- PDF On the Limitation and Experience Replay for Gnns in Continual Learning — This approach is crucial for many real-world systems, which are dynamic and evolve over time. Recent research has witnessed a surge in the exploration of Graph Neural Networks (GNN) in Node-wise Graph Continual Learning (NGCL), a practical yet challenging paradigm involving the continual training of a GNN on node-related tasks.
- Online Continual Learning: A Systematic Literature Review of Approaches ... — Online Continual Learning (OCL) is a critical area in machine learning, focusing on enabling models to adapt to evolving data streams in real-time while addressing challenges such as catastrophic forgetting and the stability-plasticity trade-of. This study conducts the first comprehensive Systematic Literature Review (SLR) on OCL, analyzing 81 approaches, extracting over 1,000 features ...
- PDF Evolve: Enhancing Unsupervised Continual Learning With Multiple Experts — In this paper, we propose EVOLVE, a hybrid frame-work using local and cloud computing for strengthen-ing unsupervised continual learning with multiple ex-perts.
- Continual lifelong learning with neural networks: A review — However, lifelong learning remains a long-standing challenge for machine learning and neural network models since the continual acquisition of incrementally available information from non-stationary data distributions generally leads to catastrophic forgetting or interference.
6.2 Recommended Books and Surveys
- Exploring continual learning strategies in artificial neural networks ... — This can potentially provide insights into the plausible neural mechanisms underlying continual learning in the biological neural networks and in reverse inspire the design of more efficient and biologically-plausible continual learning artificial systems.
- [2302.00487] A Comprehensive Survey of Continual Learning ... - ar5iv — The growing and widespread interest in this direction demonstrates its realistic significance as well as complexity. In this work, we present a comprehensive survey of continual learning, seeking to bridge the basic settings, theoretical foundations, representative methods, and practical applications.
- Online continual learning in image classification: An empirical survey — Online continual learning for image classification studies the problem of learning to classify images from an online stream of data and tasks, where tasks may include new classes (class incremental) or data nonstationarity (domain incremental). One of the key challenges of continual learning is to avoid catastrophic forgetting (CF), i.e., forgetting old tasks in the presence of more recent ...
- Continual Learning with Neuromorphic Computing: Theories, Methods, and ... — Specifically, energy-efficient continual learning is needed to ensure the functionality of autonomous systems under tight compute and memory resource budgets (i.e., so-called autonomous embedded systems).
- A survey and perspective on neuromorphic continual learning systems — In the continual learning scenario, critical aspects of spatio-temporal sparsity, increased network parameters requiring updates, and multi-hierarchy weight update rules pose more challenges than regular (non-continual) spiking network implementations.
- optimass/continual_learning_papers - GitHub — Relevant papers in Continual Learning. Contribute to optimass/continual_learning_papers development by creating an account on GitHub.
- HUMANS - arXiv.org — When faced with incremental learning of different tasks, most NNs underperform due to suffering from rapid performance degradation, a phenomenon known as Catastrophic Forgetting (CF) or interference [12]-[14]. In recent years, Continual Learning (CL) [15]-[17] emerges as a conceptual solution for addressing CF in AI systems.
- Online Continual Learning: A Systematic Literature Review of Approaches ... — Online Continual Learning (OCL) is a critical area in machine learning, focusing on enabling models to adapt to evolving data streams in real-time while addressing challenges such as catastrophic forgetting and the stability-plasticity trade-of. This study conducts the first comprehensive Systematic Literature Review (SLR) on OCL, analyzing 81 approaches, extracting over 1,000 features ...
- PDF Lifelong Machine Learning - University of Illinois Chicago — Lifelong machine learning (or lifelong learning) is an advanced machine learning paradigm that learns continuously, accumulates the knowledge learned in previous tasks, and uses it to help future learning.
- Reservoir computing approaches to recurrent neural network training — An ESN trained with a state-of-art evolutionary continuous parameter optimization method (CMA-ES) shows comparable performance in a benchmark double pole balancing problem to the best RNN topology-learning methods in [68], [141].
6.3 Open-Source Projects and Datasets
- ContinualAI/continual-learning-papers - GitHub — Continual Learning papers list, curated by ContinualAI. Search among 343 papers! You can browse the list in this file or interactively on the ContinualAI website. Join our community on Slack to stay updated with the latest Continual Learning news. The list of papers is maintained through a Zotero ...
- Find Open Datasets and Machine Learning Projects | Kaggle — Download Open Datasets on 1000s of Projects + Share Projects on One Platform. Explore Popular Topics Like Government, Sports, Medicine, Fintech, Food, More. Flexible Data Ingestion.
- Continual Learning - Papers with Code — Continual Learning (also known as Incremental Learning, Life-long Learning) is a concept to learn a model for a large number of tasks sequentially without forgetting knowledge obtained from the preceding tasks, where the data in the old tasks are not available anymore during training new ones.
- Continual learning for recurrent neural networks: An empirical ... — Learning continuously during all model lifetime is fundamental to deploy machine learning solutions robust to drifts in the data distribution. Advances in Continual Learning (CL) with recurrent neural networks could pave the way to a large number of applications where incoming data is non stationary, like natural language processing and robotics.
- Code for our paper Unified Probabilistic Deep Continual Learning ... — The code implements our proposed approach to unify the prevention of catastrophic interference in continual learning with the recognition of unknown data instances (out-of-distribution detection or open set recognition) on the basis of the aggregate posterior in variational inference with deep variational auto-encoders.
- From Liquid Neural Networks to Liquid Foundation Models — We invented liquid neural networks, a class of brain-inspired systems that can stay adaptable and robust to changes even after training [R. Hasani, PhD Thesis] [Lechner et al. Nature MI, 2020] [pdf] (2016-2020). We then analytically and experimentally showed they are universal approximators [Hasani et al. AAAI, 2021], expressive continuous-time machine learning systems for sequential data ...
- Liquid Neural Nets (LNNs). A deep dive into Liquid Neural ... - Medium — Liquid neural nets (LNNs) are an exciting, relatively new direction in AI/ML research that promises more compact and dynamic neural nets for time series prediction. LNNs offer a new approach to ...
- Online Continual Learning: A Systematic Literature Review of Approaches ... — Online Continual Learning (OCL) is a critical area in machine learning, focusing on enabling models to adapt to evolving data streams in real-time while addressing challenges such as catastrophic forgetting and the stability-plasticity trade-off. This study conducts the first comprehensive Systematic Literature Review (SLR) on OCL, analyzing 81 approaches, extracting over 1,000 features ...
- PDF An Efficient Dataset Condensation Plugin and Its Application to ... — An Eficient Dataset Condensation Plugin and Its Application to Continual Learning Enneng Yang1, Li Shen2*, Zhenyi Wang3*, Tongliang Liu4, Guibing Guo1∗
- Continual Named Entity Recognition without Catastrophic Forgetting — Continual Named Entity Recognition (CNER) is a burgeoning area, which involves updating an existing model by incorporating new entity types sequentially. Nevertheless, continual learning approaches are often severely afflicted by catastrophic forgetting. This issue is intensified in CNER due to the consolidation of old entity types from previous steps into the non-entity type at each step ...