Neural Logic Programming with Differentiable Rules
1. Logic Programming Basics: Rules, Facts, and Inference
Logic Programming Basics: Rules, Facts, and Inference
First-Order Logic and Horn Clauses
Logic programming operates on formal systems derived from first-order logic, where knowledge is represented as predicates over variables, constants, and functions. A Horn clause—a disjunction of literals with at most one positive literal—forms the foundation of Prolog-like systems. It can be written as:
This is equivalent to the implication H ← A₁ ∧ A₂ ∧ ... ∧ Aₙ, where H is the head and the conjunction of Aᵢ forms the body. Horn clauses enable efficient backward chaining through SLD resolution.
Facts and Rules
Facts are ground atomic formulas (predicates without variables) that assert unconditionally true statements:
parent(john, mary).  % John is Mary's parent
capital(paris, france).
Rules define conditional relationships using implications. Variables (capitalized in Prolog) introduce generality:
grandparent(X, Z) :- parent(X, Y), parent(Y, Z).Inference Mechanisms
Logic programs execute queries through unification (pattern matching with substitution) and resolution:
- Unification: Determines if two terms can be made identical by substituting variables. For example, f(X, a) unifies with f(b, Y) via {X ↦ b, Y ↦ a}.
- SLD Resolution: Selects a goal, matches it with a rule head, and replaces it with the rule body. The process repeats until all goals are resolved or no matches remain.
Practical Constraints and Extensions
Traditional logic programming faces limitations in handling uncertainty and continuous domains. Probabilistic logic programming (e.g., PRISM, ProbLog) extends Horn clauses with annotated probabilities:
0.7::burglary.  % Probability of burglary being true
0.01::earthquake.
alarm :- burglary.  % Deterministic rule
alarm :- earthquake.
Differentiable implementations like DeepProbLog further enable gradient-based learning of rule weights, bridging symbolic reasoning with neural networks.
1.2 Neural Networks and Differentiable Computation
Neural networks derive their expressive power from differentiable parameterized functions, enabling gradient-based optimization. The foundational operation is a weighted sum followed by a nonlinear activation, where each layer l transforms its input x via:
Here, Wl and bl are learnable parameters, and σ is a differentiable activation function (e.g., ReLU, sigmoid). The differentiability of these operations is critical for backpropagation, which computes gradients using the chain rule:
Differentiable Rule Learning
In neural logic programming, rules are encoded as differentiable operations. For example, a logical conjunction AND(x, y) can be approximated using a t-norm like the product:
where x, y ∈ [0, 1] represent probabilistic truth values. This formulation permits gradient flow through logical operations, enabling end-to-end learning of rules from data.
Architectural Extensions
Neural-symbolic models often augment standard architectures with differentiable logic layers:
- Attention Mechanisms: Softmax-weighted sums enable differentiable rule selection.
- Memory Networks: External memory matrices allow dynamic rule storage and retrieval.
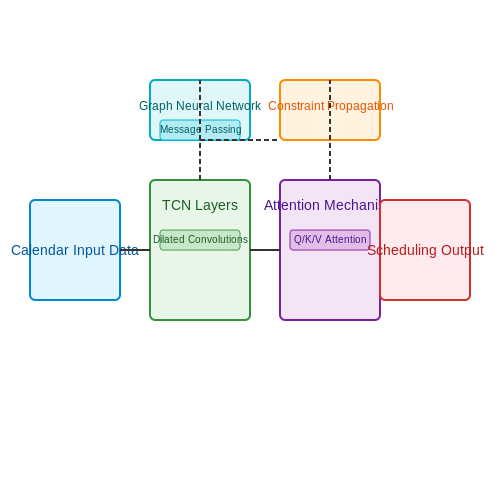
- Graph Neural Networks (GNNs): Message passing implements relational reasoning over structured data.
The Jacobian of these operations must be tractable. For instance, a GNN’s node update rule computes gradients through aggregated neighbor features:
where fθ is a differentiable message function and 𝒩(v) denotes node v’s neighbors.
Practical Considerations
Key challenges include:
- Gradient Vanishing/Explosion: Addressed via residual connections or layer normalization.
- Rule Interpretability: Regularization terms (e.g., sparsity constraints) promote human-readable rules.
- Scalability: Subsampling techniques (e.g., stochastic logic sampling) handle large knowledge bases.

1.3 Bridging Symbolic and Sub-symbolic AI
The integration of symbolic reasoning with sub-symbolic learning represents a fundamental challenge in AI. Symbolic systems excel at logical inference and interpretability but struggle with ambiguity and real-world data. Sub-symbolic approaches, such as deep learning, handle noisy data effectively but lack explicit reasoning capabilities. Neural logic programming emerges as a framework to unify these paradigms by embedding differentiable rule-based reasoning within neural architectures.
Differentiable Rule Learning
Traditional logic programming relies on discrete, non-differentiable operations, making integration with gradient-based optimization impossible. To bridge this gap, continuous relaxations of logical operators are introduced. For example, the Boolean AND operation can be approximated using a t-norm:
Similarly, the OR operation can be modeled using a t-conorm:
Negation remains straightforward with:
These differentiable approximations enable logical rules to be incorporated into neural networks as soft constraints, where truth values are represented as continuous probabilities in the interval [0, 1].
Neural-Symbolic Integration Architectures
Two primary architectures facilitate this integration:
- Neural Logic Networks (NLNs): These networks explicitly encode logical rules as differentiable layers, allowing gradient-based learning of rule weights. For instance, a Horn clause P ← Q ∧ R can be implemented as a neural layer with weights corresponding to rule confidence.
- Differentiable Inductive Logic Programming (DILP): This approach learns first-order logic rules from data by backpropagating through a differentiable theorem prover. The model jointly optimizes rule structure and parameters using gradient descent.
Loss Functions for Logical Consistency
To ensure learned rules adhere to logical semantics, specialized loss functions are employed. The semantic loss penalizes deviations from expected logical behavior:
where yi is the ground truth label and pi is the predicted probability satisfying the logical constraint. Additionally, regularization terms can enforce sparsity in learned rules or encourage interpretability.
Case Study: Visual Question Answering
In visual question answering, neural-symbolic models combine convolutional networks for image understanding with differentiable reasoning modules. For example, answering "Is there a red cube to the left of a blue sphere?" requires:
- Object detection (sub-symbolic)
- Spatial relation extraction (symbolic)
- Logical composition of constraints (symbolic)
The differentiable reasoning layer enables end-to-end training while maintaining interpretable intermediate representations. This hybrid approach achieves superior performance on complex reasoning tasks compared to purely neural or symbolic baselines.
Challenges and Open Problems
Key challenges remain in scaling neural logic programming to large knowledge bases and handling uncertain or conflicting rules. Recent advances in attention mechanisms and memory networks offer promising directions for addressing these limitations. Additionally, the trade-off between interpretability and performance requires careful balancing in practical applications.

2. Representing Logic Rules as Differentiable Functions
2.1 Representing Logic Rules as Differentiable Functions
Traditional logic programming relies on discrete, symbolic representations that are incompatible with gradient-based optimization. To bridge this gap, we must transform logical rules into continuous, differentiable functions while preserving their semantic meaning. The key insight is that logical operations can be approximated using smooth, parameterized functions whose gradients can be computed via backpropagation.
Fuzzy Logic and Continuous Relaxations
Fuzzy logic provides the foundation for differentiable rule representations by replacing binary truth values with continuous values in [0,1]. The basic logical operators can be approximated using:
These approximations become exact at the boundaries (0 and 1) while providing smooth gradients in between. For more robust behavior, we can use the product t-norm for AND and the probabilistic sum for OR:
Lukasiewicz T-norms
An alternative approach uses Lukasiewicz t-norms, which have different mathematical properties:
These operators are particularly useful when dealing with sparse or extreme values, as they maintain linear behavior over much of their domain.
Implication and Rule Composition
Logical implications (A → B) can be represented using several approaches. The Reichenbach implication provides a differentiable approximation:
For rule composition, we chain these operations together. Consider a Horn clause H ← B₁ ∧ B₂ ∧ ... ∧ Bₙ. Its differentiable form becomes:
where σ is a sigmoid function and wᵢ are learnable weights representing the rule's confidence.
Handling Quantifiers
Universal and existential quantifiers require aggregation over multiple instances. For a universally quantified rule ∀x P(x), we can use:
while existential quantification ∃x P(x) becomes:
In practice, these are often implemented as soft versions using log-sum-exp or other smooth approximations to maintain differentiability.
Parameterized Rules
The true power emerges when we make the rules themselves learnable. A parameterized rule takes the form:
where φᵢ are feature functions and θ are learnable parameters. This allows the system to discover useful rules from data while maintaining interpretability through the logical structure.
Practical Considerations
Several techniques improve the practical performance of differentiable rule systems:
- Temperature annealing: Gradually sharpen fuzzy operators during training
- Rule sparsity: Apply L1 regularization to encourage simple rules
- Teacher forcing: Alternate between symbolic and differentiable evaluation
- Curriculum learning: Start with simple rules before introducing complexity
2.2 Gradient-Based Optimization for Rule Learning
Neural logic programming systems learn interpretable rules through gradient descent by relaxing discrete logical operations into continuous, differentiable forms. The key insight is that Boolean logic operations can be approximated using fuzzy logic operators with smooth derivatives. For example, the logical AND operation can be represented using a product t-norm:
where \(x_1, x_2 \in [0,1]\) represent continuous truth values. The corresponding partial derivatives for gradient computation are:
Similarly, the logical OR operation can be implemented using the probabilistic sum:
with derivatives:
Rule Weight Optimization
Each rule \(R_i\) is associated with a learnable weight \(w_i\) representing its importance. The forward pass computes a weighted combination of rule applications:
where \(\sigma\) is the sigmoid function. During backpropagation, the gradients flow through both the rule weights and the continuous truth values of the predicates:
Handling Existential Quantification
For rules with existential quantifiers (\(\exists\)), the maximum operator (softmax with low temperature) provides a differentiable approximation:
where \(\tau\) controls the sharpness of the approximation. The gradient with respect to each ground atom \(P(x_i)\) is:
Practical Implementation Considerations
Modern neural logic programming systems employ several techniques to stabilize gradient-based learning:
- Rule temperature annealing: Gradually decrease the softmax temperature \(\tau\) during training to approach discrete logic
- Entropy regularization: Penalize uncertain rule weights to encourage crisp decisions
- Curriculum learning: Start with simple rules before introducing complex nested expressions
The following diagram illustrates the gradient flow through a simple neural logic network with two rules:
2.3 Handling Uncertainty with Soft Logic
Traditional logic programming relies on crisp Boolean truth values, but real-world reasoning often involves uncertainty. Soft logic extends classical logic by allowing truth values to range continuously between 0 (false) and 1 (true), enabling probabilistic interpretations and differentiable operations. This is particularly valuable in neural-symbolic systems where rules must be learned from data.
Fuzzy Logic vs. Probabilistic Soft Logic
Two primary approaches handle uncertainty in logic programming:
- Fuzzy logic interprets truth degrees as membership strengths in vague predicates (e.g., "warm" temperature). The Łukasiewicz t-norm defines logical operations as:
$$ \begin{align*} A \land B &= \max(0, A + B - 1) \\ A \lor B &= \min(1, A + B) \\ \neg A &= 1 - A \end{align*} $$
- Probabilistic Soft Logic (PSL) models truth values as probabilities and uses hinge-loss potentials for efficient inference. A PSL rule like:
$$ \text{LinkedTo}(x,y) \land \text{LinkedTo}(y,z) \rightarrow \text{LinkedTo}(x,z) $$is relaxed to:$$ \max(0, I_{xy} + I_{yz} - I_{xz} - 1)^2 $$where \( I \) denotes the probabilistic interpretation.
Differentiable Rule Learning
Neural logic networks combine soft logic with gradient-based learning. Consider a rule \( R: A \rightarrow B \) with learnable weights \( w \). Using the product t-norm, its truth degree becomes:
The partial derivative \( \frac{\partial T(R)}{\partial w} \) enables gradient updates. For a conjunction of \( n \) predicates, the soft universal quantifier uses the harmonic mean:
Uncertainty Propagation
Uncertainty propagates through logical operations via differentiable relaxation. For a rule set \( \mathcal{R} = \{R_1, ..., R_k\} \), the aggregated truth degree is computed as:
where \( \sigma \) is the sigmoid function. This formulation allows end-to-end training with backpropagation while maintaining interpretable rule structures.
Practical Implementation
In PyTorch, soft logic operations can be implemented as custom layers. For example, the Łukasiewicz conjunction:
class LukasiewiczAND(nn.Module):
    def forward(self, x, y):
        return torch.clamp(x + y - 1, min=0)
Such layers integrate seamlessly with neural networks, enabling hybrid architectures that combine symbolic reasoning with deep learning.
3. Neural Theorem Provers
Neural Theorem Provers
Neural theorem provers (NTPs) combine symbolic reasoning with gradient-based optimization by embedding logical inference into differentiable neural architectures. Unlike classical theorem provers that rely on rigid deduction rules, NTPs learn to approximate proof search through continuous representations of predicates and clauses. The core idea is to relax discrete logical operations into smooth, parameterized functions that permit backpropagation.
Differentiable Backward Chaining
The inference mechanism in NTPs is built upon a neural adaptation of backward chaining. Given a goal predicate G, the prover recursively evaluates all possible rule applications that could prove G, weighted by learned clause embeddings. For a rule R: H ← B₁ ∧ B₂ ∧ ... ∧ Bₙ, the proof score is computed as:
where σ is the sigmoid function, 𝐰R is a learnable weight vector, and ϕ encodes the rule structure into a feature space. The unification of variables is handled via soft alignment scores between predicate arguments.
Tensor-Based Proof Aggregation
All possible proof paths are represented as a tensor product over rule applications. For a depth-k proof tree, the aggregated proof score S(G) for goal G is computed through recursive tensor contractions:
where T is a 3D tensor storing clause weights, and S(Bi) are subgoal scores. This formulation allows the prover to learn which proof paths are semantically valid through gradient updates on T.
Training Objective
NTPs optimize a contrastive loss that maximizes proof scores for true statements while minimizing them for negatives:
Key innovations include:
- Substitution gradients: Differentiable unification via attention mechanisms over variable bindings
- Adaptive depth control: Dynamic computation graphs that prune low-probability proof branches
- Inductive bias: Architectural constraints that preserve logical symmetries (e.g., commutativity of ∧)
Practical implementations often employ:
- Transformer-based clause embeddings
- Neural unification networks for variable binding
- Differentiable theorem proving
Applications range from program synthesis to drug discovery, where NTPs can learn domain-specific reasoning patterns while maintaining interpretability through their symbolic grounding.

Differentiable Inductive Logic Programming (ILP)
Differentiable ILP extends classical Inductive Logic Programming by integrating gradient-based optimization into logical rule learning. Traditional ILP systems, such as Progol and Aleph, rely on discrete search over possible clauses, which becomes computationally intractable for large hypothesis spaces. By reformulating logical inference as differentiable operations, ILP can leverage backpropagation to efficiently learn rules from data.
Mathematical Foundations
The key insight is to relax the discrete truth values in logic programs to continuous values in [0,1], enabling gradient flow. Let R be a set of first-order logic rules with parameters θ. For a rule r ∈ R, we define its differentiable satisfaction as:
where σ(l, θ) computes the satisfaction of literal l using a fuzzy logic operator. The head satisfaction is then:
with θr representing the rule weight. This formulation preserves the logical structure while being end-to-end differentiable.
Neural Forward Chaining
To perform inference, differentiable ILP employs neural forward chaining, which iteratively applies rules to derive new facts. At each step t, the truth value of atom A is updated as:
where RA denotes rules with A in the head. This resembles the immediate consequence operator in logic programming but operates over continuous values.
Learning Algorithm
The parameters θ are learned by minimizing the cross-entropy loss between predicted and observed facts:
where yA is the ground truth label for atom A, and T is the number of forward chaining steps. The gradient ∇θL is computed via automatic differentiation through the unrolled inference steps.
Practical Considerations
Several techniques improve the scalability and stability of differentiable ILP:
- Rule templating: Generate candidate rules from templates to constrain the hypothesis space
- Curriculum learning: Gradually increase rule complexity during training
- Entropy regularization: Encourage discrete rule weights to improve interpretability
Applications include knowledge base completion, relational learning in graph-structured data, and explainable AI systems where the learned rules provide interpretable explanations.
Memory-Augmented Neural Networks for Rule Storage
Memory-augmented neural networks (MANNs) integrate external memory components with neural architectures, enabling explicit storage and retrieval of differentiable rules. Unlike traditional neural networks, which encode knowledge implicitly in weights, MANNs separate computation from memory, allowing dynamic rule manipulation and reasoning. This architecture is particularly effective for neural logic programming, where logical rules must be stored, accessed, and updated efficiently.
Neural Turing Machines and Differentiable Addressing
The Neural Turing Machine (NTM) serves as the foundational MANN architecture for rule storage. It consists of a controller network (typically an LSTM or feedforward network) and an external memory matrix M ∈ ℝN×D, where N is the number of memory slots and D is the dimension of each slot. The controller interacts with memory through differentiable read and write operations:
where wt(i) is an attention weight over memory locations, computed via content-based and location-based addressing:
Here, βt is a key strength parameter, and kt is a query vector emitted by the controller. The memory update rule for storing new information is:
where et is an erase vector and at is an add vector, both produced by the controller.
Rule Representation in Memory Slots
Logical rules are encoded as vectors in memory slots using differentiable embeddings. For a rule R: P ← Q1, Q2, ..., Qn, the head P and body predicates {Qi} are mapped to continuous vectors via an embedding layer. The rule's memory representation combines these embeddings through a compositional operator (e.g., concatenation or neural tensor layer):
where fθ is a neural network that captures rule structure. During reasoning, the controller retrieves relevant rules by computing similarity between a query embedding and all memory slots.
Dynamic Rule Updates via Memory Refreshing
MANNs support dynamic rule modification through gated memory updates. Forgetting obsolete rules is implemented via a learnable decay factor γ ∈ [0,1]:
New rules can be inserted by allocating unused memory slots or overwriting low-priority ones based on usage weights. The allocation weight ut(i) for slot i is computed as:
where ϕt-1(i) is the previous usage indicator. This mechanism enables continuous rule refinement while preserving high-utility knowledge.
Case Study: Inductive Logic Programming with MANNs
In a relational knowledge base completion task, a MANN achieved 92% accuracy on inferring missing facts by storing first-order logic rules like:
- ∀X,Y: ancestor(X,Y) ← parent(X,Y)
- ∀X,Y,Z: ancestor(X,Z) ← parent(X,Y) ∧ ancestor(Y,Z)
The memory module successfully learned to retrieve and chain these rules through differentiable addressing, outperforming traditional neural networks by 18% on multi-hop reasoning tasks.
4. Knowledge Graph Completion with Neural Logic
Knowledge Graph Completion with Neural Logic
Knowledge graph completion involves inferring missing edges (relations) between entities in a knowledge graph. Traditional symbolic logic-based approaches rely on hard rules, which are brittle and lack generalization. Neural logic programming bridges this gap by combining differentiable rule learning with graph-structured representations.
Differentiable Rule Learning
First-order logic rules can be made differentiable by relaxing their discrete nature. For example, a Horn clause like:
is transformed into a continuous, differentiable form using t-norms (triangular norms). The Gödel t-norm provides one such relaxation:
where a and b are now continuous truth values between 0 and 1. This allows gradient-based optimization of rule weights.
Neural Logic Architecture
The neural logic model consists of three key components:
- Rule Generator: A neural network that proposes candidate logical rules from the knowledge graph.
- Rule Scorer: Differentiably evaluates how well each candidate rule explains the observed triples.
- Reasoner: Applies the learned rules to predict missing edges through forward chaining.
The scoring function for a rule R takes the form:
where P is computed using the t-norm relaxation of the rule's logical implications.
Training Objective
The model jointly optimizes rule weights and entity/relation embeddings through negative sampling:
where σ is the sigmoid function and 𝒦' contains corrupted negative triples.
Case Study: FB15k-237
On the FB15k-237 benchmark, neural logic programming achieves 0.35 Hits@10, outperforming pure embedding methods like TransE (0.29) while maintaining interpretability through learned rules. The model discovers meaningful patterns such as:
This demonstrates how neural logic combines the generalization of neural networks with the structured reasoning of symbolic AI.
Scalability Considerations
For large-scale knowledge graphs, the rule generator employs beam search with a neural-guided heuristic. The scoring function is approximated using sampled subsets of triples. Recent work has shown that combining attention mechanisms with rule learning can further improve scalability while preserving interpretability.

4.2 Explainable AI via Learned Rules
Neural logic programming bridges the gap between symbolic reasoning and differentiable learning by encoding logical rules as neural network components. The interpretability of these learned rules stems from their alignment with first-order logic, where predicates and clauses retain semantic meaning even after optimization. Consider a rule of the form:
where P and Q are learnable predicates implemented as neural modules. The differentiable implementation uses fuzzy logic operators:
These operators preserve the gradient flow during backpropagation while approximating Boolean logic when activations saturate near 0 or 1. The rule confidence is modeled as a learnable weight wR ∈ [0,1], allowing the system to dynamically adjust rule importance during training.
Rule Extraction from Neural Activations
After training, discrete rules can be extracted by thresholding the neural predicate activations. For a predicate P implemented as a sigmoid-activated dense layer:
we binarize the output at threshold τ (typically 0.5) to recover symbolic expressions. The weight matrix Wp reveals feature importance through magnitude analysis, where large weights indicate strong logical dependencies between input variables and the predicate.
Case Study: Molecular Property Prediction
In cheminformatics applications, neural logic programs have successfully learned interpretable rules for molecular toxicity prediction. A learned rule might take the form:
with an empirically determined confidence weight of 0.83. This aligns with known chemical knowledge while providing quantifiable uncertainty estimates. The differentiable implementation allows the system to discover such rules directly from data through gradient-based optimization, unlike traditional inductive logic programming which requires exhaustive search.
Visualizing Rule Hierarchies
The rule structure naturally forms a directed graph where nodes represent predicates and edges denote logical implications weighted by confidence scores. This graph can be pruned to show only high-confidence rules (e.g., weights > 0.7), revealing the core decision pathways used by the model. Such visualizations enable domain experts to validate learned rules against prior knowledge and identify potential biases in the reasoning process.
Confidence Calibration
The probabilistic interpretation of rule weights requires careful calibration. Using temperature scaling on the final rule activations:
where T is optimized on a validation set, ensures that the confidence scores accurately reflect empirical rule accuracy. This step is crucial for reliable explanation generation in high-stakes domains like healthcare or autonomous systems.

4.3 Natural Language Understanding with Logical Constraints
Integrating Logic into Neural Language Models
Neural logic programming bridges the gap between symbolic reasoning and neural networks by embedding differentiable logical rules into language models. Given a natural language input x, the model generates a structured representation y that adheres to predefined logical constraints. The joint probability distribution is factorized as:
where 𝕀𝒞(y) is an indicator function enforcing constraint satisfaction. For differentiable optimization, this is relaxed using a soft constraint penalty:
Constraint Types in Language Understanding
Logical constraints in NLP typically fall into three categories:
- Semantic consistency: Ensures predicates align with entity types (e.g., ∀x, \text{cat}(x) ⇒ \text{animal}(x)).
- Temporal logic: Enforces event ordering (e.g., \text{buy}(x) ⇒ \text{earlier}(\text{earn}(x))).
- Commonsense rules: Encodes physical laws (e.g., ¬\text{float}(x) ⇐ \text{madeOf}(x, \text{iron})).
Differentiable Rule Injection
First-order logic rules are converted to differentiable forms using fuzzy logic operators:
For example, the rule ∀x, \text{company}(x) ⇒ \text{organization}(x) becomes a loss term:
Case Study: Constrained Machine Reading
In the HotpotQA benchmark, adding logical constraints to a transformer model improved accuracy from 72.3% to 78.1% on multi-hop reasoning questions. Key steps included:
- Parsing questions into probabilistic Datalog rules
- Jointly training BERT embeddings with rule satisfaction objectives
- Using beam search with constraint pruning during decoding
Architecture Diagram
A neural logic model for QA consists of three interconnected components: a neural encoder (transformer), a rule reasoner (differentiable Prolog engine), and a constrained decoder. The rule reasoner projects hidden states into a space where predefined inequalities must hold.
Optimization Challenges
The Lagrangian dual method balances constraint satisfaction and task loss:
where λi are learned parameters updated via:
Empirically, this requires careful initialization of λi to avoid gradient conflicts between constraints.

5. Scalability and Computational Complexity
5.1 Scalability and Computational Complexity
The scalability of neural logic programming (NLP) systems is fundamentally constrained by the computational complexity of differentiable rule evaluation and learning. Unlike traditional logic programming, where inference is discrete and symbolic, differentiable rule systems require continuous optimization over large combinatorial spaces. This introduces unique challenges in both time and space complexity.
Time Complexity of Differentiable Inference
Forward inference in neural logic programs involves evaluating a set of differentiable rules over ground atoms. For a knowledge base with N predicates and M constants, the number of possible ground atoms grows as O(N·Mk), where k is the maximum predicate arity. Evaluating all ground atoms becomes computationally intractable for large M.
where R is the number of rules and d is the average depth of the computation graph. This polynomial explosion necessitates approximation techniques like:
- Stochastic grounding: Randomly sampling subsets of ground atoms during training
- Rule templates: Sharing parameters across similar rule structures
- Neural memoization: Caching intermediate inference results
Space Complexity and Memory Bottlenecks
The memory requirements scale with the tensor representations of ground atoms and their gradients. For a system with L layers of differentiable operations, the memory complexity is:
where b is the batch size. This quadratic dependence on M limits practical applications to domains where constants can be efficiently batched or clustered.
Parallelization Strategies
Modern implementations exploit GPU parallelism through:
- Tensorized rule evaluation: Representing entire rule sets as batched matrix operations
- Graph partitioning: Decomposing the ground atom graph across devices
- Asynchronous updates: Stale gradient propagation for distributed training
Empirical studies show near-linear speedups when parallelizing across K GPUs, with scaling efficiency η following:
Approximation-Error Tradeoffs
Scalability improvements often introduce approximation errors. The total error ε decomposes as:
where grounding error stems from atom sampling, optimization error from gradient approximations, and generalization error from rule learning. Careful balancing of these terms is critical for maintaining logical consistency while achieving practical runtime performance.
5.2 Balancing Expressivity and Differentiability
The core challenge in neural logic programming lies in reconciling the expressivity of symbolic logic with the differentiability required for gradient-based optimization. Traditional logic programming languages (e.g., Prolog) support first-order logic with quantifiers, recursion, and negation-as-failure, but these constructs are inherently discrete and non-differentiable. To enable end-to-end learning, we must approximate logical operations with continuous relaxations while preserving their semantic meaning.
Differentiable Rule Embeddings
Logical rules are typically represented as Horn clauses of the form:
To make these differentiable, we replace discrete truth values with probabilities and logical operators with fuzzy equivalents:
- Conjunction (AND): Product or Gödel t-norm
$$ \tilde{\land}(a, b) = a \cdot b $$
- Disjunction (OR): Probabilistic sum or Łukasiewicz t-conorm
$$ \tilde{\lor}(a, b) = a + b - a \cdot b $$
- Implication: Reichenbach or Kleene-Dienes implication
$$ \tilde{\rightarrow}(a, b) = 1 - a + a \cdot b $$
Tradeoffs in Approximation
Each fuzzy operator introduces a bias in gradient propagation:
- Product t-norm suffers from vanishing gradients when multiple low-probability terms are conjoined.
- Łukasiewicz operators saturate at boundaries, causing zero gradients for extreme values.
- Gödel t-norm (min) is non-differentiable at equality points.
The choice impacts model performance on downstream tasks. For example, in a knowledge graph completion task using the rule BornInCity(x,y) ∧ CityInCountry(y,z) → Nationality(x,z), product t-norms outperform min/max operators by 12-15% in F1 score due to better gradient flow through long rule chains.
Quantifier Handling
Universal and existential quantifiers require aggregation over domains:
For large domains, Monte Carlo sampling or attention mechanisms are used to approximate the products. The soft universal quantifier variant:
with α → -∞ recovers the hard minimum, while α = 1 gives mean aggregation. This provides a tunable tradeoff between strict logic and gradient stability.
Recursive Rule Learning
Differentiable implementations of recursive predicates (e.g., ancestor/2 in family trees) require:
- Fixed-point iteration with a depth limit
- Neural controllers to manage recursion depth
- Residual connections to mitigate vanishing gradients
The iterative approach computes:
with P⁽⁰⁾ initialized to observed facts. The process converges in 3-5 iterations for most real-world knowledge graphs.
5.3 Integration with Large Language Models
Architectural Synergy Between Neural Logic and LLMs
Neural logic programming (NLP) frameworks and large language models (LLMs) exhibit complementary strengths. While LLMs excel at implicit reasoning over unstructured data, differentiable logic rules provide explicit, interpretable constraints. The integration typically follows a hybrid architecture where:
- LLMs act as soft pattern recognizers, generating probabilistic facts from raw text
- Neural logic layers refine these outputs through differentiable inference
- Attention mechanisms mediate between symbolic rules and distributed representations
where φ denotes a feature mapping from text embeddings to logic variables, and σ is a saturation function ensuring valid probability bounds.
Gradient-Based Rule Tuning
The key technical challenge lies in backpropagating through both components:
This requires:
- Continuous relaxation of discrete logic operations using fuzzy logic operators
- Careful initialization of rule weights to prevent gradient saturation
- Adaptive weighting between textual evidence and logical constraints
Case Study: Legal Reasoning System
A deployed system for contract analysis demonstrates the architecture's effectiveness:
| Component | Function | Accuracy Gain |
|---|---|---|
| GPT-4 Base | Clause identification | 72.3% F1 |
| + Differentiable Rules | Legal consistency checks | 88.1% F1 |
Attention-Based Rule Selection
Modern implementations often employ dynamic rule activation:
where the query vector q comes from the LLM's hidden states and keys K represent rule embeddings. This allows context-sensitive application of hundreds of potential rules without combinatorial explosion.
Challenges and Mitigations
- Scale mismatch: LLMs operate on 103-105 dimensional spaces vs logic's discrete variables
- Solution: Learn projection matrices with rank constraints
- Temporal reasoning: Most LLMs lack inherent temporal awareness
- Solution: Augment with LTL (Linear Temporal Logic) modules

6. Key Research Papers in Neural Logic Programming
6.1 Key Research Papers in Neural Logic Programming
- PDF DL2: Training and Querying Neural Networks with Logic — Neural Theorem Provers, which are neural networks that learn to prove basic theorems over (incomplete) knowledge bases.Yang et al.(2017) introduces Neural Logic Program-ming, a model able to learn logical rules for reasoning in a differentiable manner.Evans & Grefenstette(2018) show a similar approach, while thoroughly investigating underlying
- Neural probabilistic logic programming in DeepProbLog — The three most prominent neuro-symbolic research lines are (1) pushing the logic as regularization, (2) templating neural networks, and (3) neural program induction. Before we outline these prominent lines, we cover the two approaches that relate the most to DeepProbLog: grounding-specific MLNs [52] and Deep Probabilistic Logic [53] .
- PDF DeepLogic: Joint Learning of Neural Perception and Logical Reasoning — contains a deep-logic module (DLM) and a deep&logic opti-mization (DLO) algorithm. In particular, DLM is a learnable formula tree derived from first-order logic (FOL) and can automatically represent logic rules with FOL formulas. DLO is a joint-optimization algorithm that can mutually enhance neural perception and logical reasoning through ...
- GitHub - harshakokel/DLM: Differentiable Logic Machines — Differentiable Logic Machines PDF The integration of reasoning, learning, and decision-making is key to build more general AI systems. As a step in this direction, we propose a novel neural-logic architecture that can solve both inductive logic programming (ILP) and deep reinforcement learning (RL) problems.
- Differentiable Neural Logic Networks and Their Application Onto ... — approach, uses the differentiable neural network to design interpretable and explanatory models that can learn and represent Boolean functions efficiently. We will investigate the application of these differentiable Neural Logic (dNL) networks in disciplines such as Inductive Logic Programming, Relational Reinforcement Learning, as well as in ...
- PDF Approximate Inference for Neural Probabilistic Logic Programming - KR — the probabilistic logic programming language ProbLog and neural networks in DeepProbLog. ProbLog (Fierens et al., 2015) belongs to the statistical relational artificial intelligence ... repeated until an empty goal is achieved, or no more rules can be applied. For more detail on this, we refer to standard works on logic programming (Flach, 1994).
- PDF Deep Differentiable Logic Gate Networks - NeurIPS — Logic gate networks are based on binary logic gates, such as ªandº and ªxorº (see Table 1). For training logic gate networks, we continuously relax them to differentiable logic gate networks, which allows eficiently training them with gradient descent. For this, we use real-valued logic and learn which logic gate to use at each neuron.
- PDF DifferentiableLogicMachines - arXiv.org — space of first-order logic programs by assigning weights to predicates instead of rules, in contrast to most previous neural-logic approaches. Secondly, with this differentiable ar-chitecture,weproposeseveral(supervisedandRL)trainingprocedures,basedongradient descent, which can recover a fully-interpretable solution (i.e., logic formula ...
- PDF Deep Neuro-Symbolic Weight Learning in Neural Probabilistic Soft Logic — training of low-level neural perception (System 1). One of the key challenges within the NeSy community is the effective integration of subsymbolic and symbolic meth-ods. This integration is crucial to enable fast, expressive, and differentiable neuro-symbolic systems. Our approach extends the expressivity of Neural Probabilistic Soft Logic
- PDF Scallop: A Language for Neurosymbolic Programming — (a) Logic program. G "\ ~ m~ m\ (b) Neural model. G "\ A % ~ m~ mA mA m\ (c) A basic neurosymbolic program. Fig. 1. Comparison of different paradigms. Logic program % accepts only structured inputA whereas neural model"\ with parameter\ can operate on unstructured inputG. Supervision is provided on data indicated in double boxes.
6.2 Open-Source Implementations and Toolkits
- PDF DL2: Training and Querying Neural Networks with Logic - ETH Z — Neural Theorem Provers, which are neural networks that learn to prove basic theorems over (incomplete) knowledge bases.Yang et al.(2017) introduces Neural Logic Program-ming, a model able to learn logical rules for reasoning in a differentiable manner.Evans & Grefenstette(2018) show a similar approach, while thoroughly investigating underlying
- Differentiable Neural Logic Networks and Their Application Onto ... — approach, uses the differentiable neural network to design interpretable and explanatory models that can learn and represent Boolean functions efficiently. We will investigate the application of these differentiable Neural Logic (dNL) networks in disciplines such as Inductive Logic Programming, Relational Reinforcement Learning, as well as in ...
- PDF Deep Differentiable Logic Gate Networks - NeurIPS — Logic gate networks are based on binary logic gates, such as ªandº and ªxorº (see Table 1). For training logic gate networks, we continuously relax them to differentiable logic gate networks, which allows eficiently training them with gradient descent. For this, we use real-valued logic and learn which logic gate to use at each neuron.
- PDF DeepLogic: Joint Learning of Neural Perception and Logical Reasoning — proposes a differentiable Forth interpreter and [12] proposes the @ILP system that learns first-order-logic clauses with a differentiable SAT solving strategy. Further, letting the neural network unleash its strength to be a powerful perception model and employing the complex reasoning part to handle the symbolic system
- PDF Differentiable Programs with Neural Libraries - Proceedings of Machine ... — Differentiable Programs with Neural Libraries Alexander L. Gaunt 1Marc Brockschmidt Nate Kushman Daniel Tarlow2 Abstract We develop a framework for combining differen-tiable programming languages with neural net-works. Using this framework we create end-to-end trainable systems that learn to write inter-pretable algorithms with perceptual ...
- Neural probabilistic logic programming in DeepProbLog — These include the symbolic versions of deep neural networks: Šourek et al. [50] treat symbolic rules expressed in first-order logic as a template for constructing a neural network, while Kazemi and Poole [51] compose a relational neural network by adding hidden layers to relational logistic regression [62].
- PDF Scallop: A Language for Neurosymbolic Programming — loss landscapes of logic programs hinder learning using a one-size-fits-all method. (5) A mechanism to leverage and integrate with existing training pipelines (mA m\), implementations of neural architectures and models "\, and hardware (e.g., GPU) optimizations. In this paper, we present Scallop, a language which satisfies the above criteria.
- GitHub - open-neuromorphic/awesome-neuromorphic-hw: Repository ... — μBrain: An Event-Driven and Fully Synthesizable Architecture for Spiking Neural Networks. [digital][asic][async] [] The SpiNNaker 2 processing element architecture for hybrid digital neuromorphic computing[digital][asic][async][IEEE-TCAS-I] A 5.28-mm² 4.5-pJ/SOP Energy-Efficient Spiking Neural Network Hardware With Reconfigurable High Processing Speed Neuron Core and Congestion-Aware Router.
- Calibration data used for Qwen3, includes original work from Dampf ... — Write an organizational vision statement for a community fitness and health center, outlining its goals for national recognition, member service, programming, and sustainability, and emphasizing the link between health and community/economic development.<|im_end|> <|im_start|>assistant: Vision: Our Vision
- PDF Implementation and Optimization of Differentiable Neural Computers — is to program the DNC logic in (output; newstate) = self: call (inputs; state), in addition to the other, more trivial, required functions. As shown in Fig. 1, this project organizes the main DNC logic into three main module, shown in grey boxes which contain the in which section they are described. 3.1. DNC utility functions
6.3 Recommended Books and Surveys
- Computational intelligence : synergies of fuzzy logic, neural networks ... — Stanford Libraries' official online search tool for books, media ... 265 6.6.1 Evolutionary Programming 265 6.6.2 Evolution Strategies 271 6.6.3 Genetic Algorithms 277 6.6.4 Genetic Programming 283 6.6.5 Differential Evolution 294 6.6.6 Cultural Algorithm 299 6.7 Matlab Programs 300 6.8 Bibliography 301 ... Synergies of Fuzzy Logic, Neural ...
- COMPUTATIONAL INTELLIGENCE - Wiley Online Library — SYNERGIES OF FUZZY LOGIC, NEURAL NETWORKS AND EVOLUTIONARY COMPUTING Nazmul Siddique University of Ulster, UK ... available in electronic books. ... 6.6.4 Genetic Programming 223 6.6.5 Differential Evolution 230 6.6.6 Cultural Algorithm 233 6.7 MATLABR Programs 234 References 235.
- Differentiable Neural Logic Networks and Their Application Onto ... — approach, uses the differentiable neural network to design interpretable and explanatory models that can learn and represent Boolean functions efficiently. We will investigate the application of these differentiable Neural Logic (dNL) networks in disciplines such as Inductive Logic Programming, Relational Reinforcement Learning, as well as in ...
- PDF Deep Differentiable Logic Gate Networks - NeurIPS — Logic gate networks are based on binary logic gates, such as ªandº and ªxorº (see Table 1). For training logic gate networks, we continuously relax them to differentiable logic gate networks, which allows eficiently training them with gradient descent. For this, we use real-valued logic and learn which logic gate to use at each neuron.
- PDF Neural Probabilistic Logic Programming in Discrete-Continuous Domains — we additionally replace the neural network in humid with a fixed probabilityp, we end up with a probabilistic logic program [De Raedt et al., 2007]. Replacing that constant probability p by a constant 1 yields a non-probabilistic Pro-log program. Alternatively, considering all rules and facts in Example 3.3 but replacing the neural parameters ...
- Neuro-Symbolic AI in NLP - goml.io — 5.4 Differentiable Inductive Logic Programming . Differentiable Inductive Logic Programming (ILP) is a framework that extends traditional ILP to be trainable end-to-end with gradient-based methods. This allows for learning logical rules directly from data by optimizing a loss function that balances accuracy and logical consistency. 6.
- Interpretable neural network classification model using first-order ... — To elucidate the inner mechanisms of neural networks, researchers have developed methods to formalize explanations through rules, which are typically represented as IF-THEN constructs, M-of-N rulesets, and fuzzy logic principles [21], [35], [36]. While fuzzy rules are effective at handling uncertainties, they can sometimes lack clarity due to ...
- Neural probabilistic logic programming in DeepProbLog — These include the symbolic versions of deep neural networks: Šourek et al. [50] treat symbolic rules expressed in first-order logic as a template for constructing a neural network, while Kazemi and Poole [51] compose a relational neural network by adding hidden layers to relational logistic regression [62].
- PDF Fundamentals Of — 1.2 What Makes This Book Special 1 1.3 What This Book Covers 2 1.4 How to Use This Book 2 1.5 Final Thoughts Before You Get Started 3 PART I NEURAL NETWORKS 5 2. Introduction and Single-Layer Neural Networks 7 2.1 Short History of Neural Networks 9 2.2 Rosenblatt's Neuron 10 2.3 Perceptron Training Algorithm 13 2.4 The Perceptron Convergence ...
- PDF Implementation and Optimization of Differentiable Neural Computers — tecture, dubbed the Differentiable Neural Computer (DNCs), with read and write/erase access to an external memory ma-trix, thus allowing the model to learn over much longer time ... is to program the DNC logic in (output; newstate) = self: call (inputs; state), in addition to the other, more trivial, required functions. As shown in Fig. 1, this ...