Proximal Policy Optimization (PPO) Explained
1. Key Concepts in Reinforcement Learning
Key Concepts in Reinforcement Learning
Markov Decision Processes (MDPs)
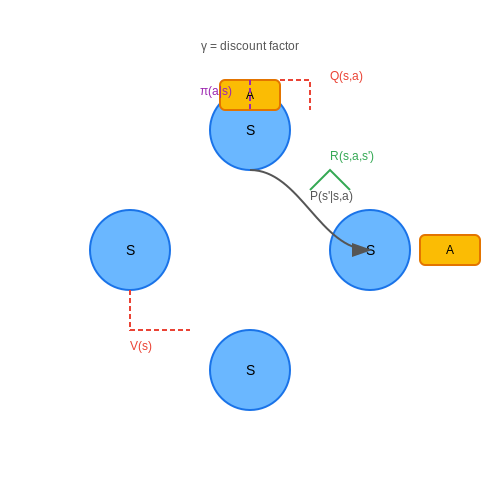
Reinforcement learning (RL) problems are formally modeled as Markov Decision Processes (MDPs), defined by the tuple (S, A, P, R, γ):
- S: State space
- A: Action space
- P(s'|s, a): Transition dynamics
- R(s, a, s'): Reward function
- γ ∈ [0, 1]: Discount factor
The Markov property implies state transitions depend only on the current state and action, not history. This framework enables dynamic programming solutions.
Policy and Value Functions
A policy π(a|s) defines the agent's behavior as a probability distribution over actions given states. Two fundamental value functions evaluate policy quality:
Vπ(s) represents the expected cumulative reward from state s following policy π, while Qπ(s, a) evaluates state-action pairs.
Bellman Equations
Value functions satisfy recursive Bellman equations that form the basis of RL algorithms:
These equations enable iterative policy evaluation and improvement through dynamic programming.
Optimality and Control
The optimal value functions V* and Q* satisfy the Bellman optimality equations:
Model-free RL algorithms like Q-learning approximate these equations through sampling when transition dynamics are unknown.
Policy Gradient Methods
Instead of learning value functions, policy gradient methods directly optimize the policy πθ(a|s) parameterized by θ using gradient ascent:
This expectation is typically estimated via Monte Carlo sampling. The policy gradient theorem provides the theoretical foundation for these methods.
Exploration vs Exploitation
RL agents must balance exploring new actions to discover higher rewards versus exploiting known high-reward actions. Common strategies include:
- ε-greedy: Random exploration with probability ε
- Softmax: Action selection weighted by Q-values
- Upper Confidence Bound (UCB): Optimistic exploration
- Thompson sampling: Bayesian posterior sampling
This exploration-exploitation tradeoff is fundamental to efficient RL, particularly in sparse-reward environments.
1.2 Policy Gradient Methods: An Overview
Foundations of Policy Gradient Methods
Policy gradient methods optimize a parameterized policy πθ(a|s) directly by ascending the gradient of expected reward with respect to the policy parameters θ. Unlike value-based methods, which learn a value function and derive a policy indirectly, policy gradients explicitly represent the policy and adjust its parameters to maximize cumulative reward. The objective function J(θ) is defined as:
where τ denotes a trajectory (s0, a0, r0, ..., sT) and R(τ) is the cumulative reward. The gradient of J(θ) is derived using the log-derivative trick:
Variance Reduction Techniques
The vanilla policy gradient suffers from high variance due to the Monte Carlo estimation of returns. Two common techniques mitigate this:
- Baseline Subtraction: A state-dependent baseline b(st) reduces variance without introducing bias. The gradient becomes:
- Advantage Estimation: Using the advantage function A(st, at) = Q(st, at) - V(st) further refines the update direction. Generalized Advantage Estimation (GAE) combines multi-step returns exponentially weighted by a parameter λ.
Practical Algorithms
REINFORCE and Actor-Critic are two foundational algorithms:
- REINFORCE: A Monte Carlo method using full-trajectory returns. Updates are performed after episode completion.
- Actor-Critic: Combines policy gradients with a learned value function (critic) to provide low-variance updates. The critic estimates V(s) or A(s, a).
Mathematical Derivation of the Policy Gradient
Starting from the objective J(θ), we express its gradient as:
Applying the log-derivative trick ∇θ P(τ|θ) = P(τ|θ) ∇θ log P(τ|θ), we rewrite the gradient as:
Decomposing P(τ|θ) into state transitions and policy terms yields the final policy gradient theorem.
Challenges and Limitations
Policy gradients face three key challenges:
- Sample Efficiency: Requires many trajectories for accurate gradient estimation.
- Credit Assignment: Determining which actions contributed to long-term rewards is non-trivial.
- Local Optima: The non-convex optimization landscape may lead to suboptimal policies.
Connection to PPO
Proximal Policy Optimization (PPO) addresses these limitations by constraining policy updates to prevent destructive large steps. It uses a clipped objective function to ensure stable training while retaining the benefits of policy gradient methods.
1.3 Challenges in Traditional Policy Optimization
Traditional policy gradient methods, such as REINFORCE and Natural Policy Gradient (NPG), suffer from several fundamental limitations that hinder their stability and sample efficiency in complex environments. These challenges stem from the inherent properties of gradient-based optimization in high-dimensional, non-convex policy spaces.
High Variance in Gradient Estimates
The policy gradient theorem expresses the expected reward gradient as:
where Ât is an estimator of the advantage function. Monte Carlo estimation of this expectation leads to high variance because:
- Trajectories τ can diverge significantly due to stochasticity in both policy and environment
- The credit assignment problem makes precise estimation of Ât challenging
- Small changes in action probabilities can exponentially affect trajectory probabilities
Non-Stationary Data Distribution
Unlike supervised learning where data is i.i.d., policy optimization deals with sequential data where:
This creates a moving target problem - as the policy πθ updates, the state visitation distribution pθ(s) changes, making previously collected samples obsolete. This violates the fundamental assumption of stochastic gradient descent that samples come from a fixed distribution.
Step Size Sensitivity
The performance surface in policy space often contains:
- Cliffs where small parameter changes cause large performance drops
- Plateaus with near-zero gradients
This makes learning rates critically important but difficult to set. The Natural Policy Gradient addresses this by using the Fisher information matrix Fθ to normalize updates:
However, computing or approximating Fθ is computationally expensive for large neural network policies.
Sample Inefficiency
Traditional methods require:
- Complete trajectories to compute Monte Carlo returns
- Fresh samples after each policy update due to non-stationarity
- Many iterations to converge due to high-variance gradients
This makes them impractical for real-world applications where environment interactions are expensive. Trust Region Policy Optimization (TRPO) attempted to address this by constraining policy updates, but its complex implementation and computation limited widespread adoption.
Credit Assignment Over Long Horizons
In sparse reward environments, the signal-to-noise ratio for gradient updates becomes extremely low. The variance of the gradient estimate scales with the square of the horizon T:
where σr2 is the variance of rewards. This makes learning in long-horizon tasks particularly challenging without careful reward shaping or advanced variance reduction techniques.
2. Core Idea and Motivation Behind PPO
2.1 Core Idea and Motivation Behind PPO
Proximal Policy Optimization (PPO) addresses key challenges in policy gradient methods, particularly the instability arising from large policy updates. Traditional policy gradient algorithms, such as REINFORCE or Trust Region Policy Optimization (TRPO), either suffer from high variance or computational inefficiency. PPO strikes a balance by introducing a clipped objective function that prevents excessively large policy updates while maintaining sample efficiency.
Policy Gradient Instability
The fundamental issue in policy optimization is the trade-off between exploration and exploitation. Policy gradient methods update the policy parameters θ in the direction of the estimated gradient of the expected return:
where πθ(at|st) is the policy, and Ât is the advantage estimate. Large updates can destabilize learning, causing catastrophic drops in performance. TRPO mitigates this with a constrained optimization problem:
However, TRPO’s second-order optimization is computationally expensive.
PPO’s Clipped Surrogate Objective
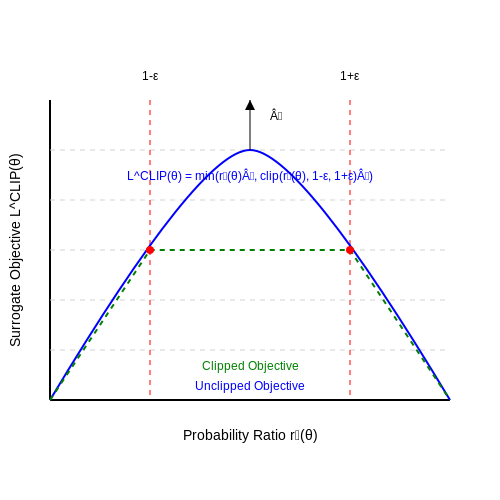
PPO simplifies TRPO by replacing the KL constraint with a clipped objective. The surrogate objective is:
where rt(θ) = πθ(at|st) / πθold(at|st) is the probability ratio, and ϵ is a hyperparameter (typically 0.1–0.2). The clip function restricts rt(θ) to [1 − ϵ, 1 + ϵ], preventing overly aggressive updates.
Advantages Over TRPO
- Computational Efficiency: PPO uses first-order optimization (e.g., Adam), avoiding TRPO’s costly conjugate gradient steps.
- Robustness: The clipped objective empirically performs well across diverse environments without fine-tuning.
- Parallelizability: PPO’s simplicity enables efficient distributed implementations, as seen in OpenAI’s scalable RL frameworks.
Practical Applications
PPO’s stability and efficiency make it a default choice for continuous control (e.g., robotic locomotion) and complex game environments (e.g., Dota 2, StarCraft II). Its clipped objective has influenced subsequent algorithms like SAC and TD3, which adapt similar principles for off-policy settings.
The PPO-Clip Algorithm: Mathematical Formulation
Proximal Policy Optimization (PPO) introduces a clipped objective function to prevent excessively large policy updates while maintaining sample efficiency. The core idea is to constrain the policy update by clipping the probability ratio, ensuring the new policy does not deviate too far from the old policy.
Policy Gradient and Probability Ratio
The foundation of PPO lies in the policy gradient objective, where the goal is to maximize the expected return by adjusting the policy parameters θ. The probability ratio rt(θ) is defined as:
where πθ is the current policy and πθold is the old policy before the update. This ratio measures how much more (or less) likely the current policy is to take action at in state st compared to the old policy.
Clipped Surrogate Objective
The standard policy gradient objective would multiply the advantage estimate Ât by the probability ratio rt(θ):
However, this can lead to excessively large updates when rt(θ) becomes too large or too small. PPO modifies this objective by introducing a clip operation:
where ε is a hyperparameter (typically 0.1 to 0.3) that determines how far the new policy can deviate from the old policy. The clip function restricts rt(θ) to the interval [1 - ε, 1 + ε].
Complete PPO Objective
The full PPO objective combines the clipped surrogate objective with a value function error term and an entropy bonus for exploration:
where:
- LtVF(θ) is the squared error loss for the value function estimate
- S[πθ](st) is the entropy bonus
- c1 and c2 are coefficients controlling the relative importance of each term
Practical Implementation Considerations
In practice, PPO is typically implemented with:
- Parallel actors collecting trajectories
- Multiple epochs of minibatch updates on the collected data
- Generalized Advantage Estimation (GAE) for computing advantages
- Adam optimizer with a learning rate typically between 3×10⁻⁴ and 3×10⁻⁵
The clipping mechanism ensures stable training while still allowing for efficient use of collected samples through multiple update epochs. This balance between stability and sample efficiency has made PPO one of the most widely used policy gradient algorithms in deep reinforcement learning.
2.3 Advantages Over Trust Region Policy Optimization (TRPO)
Computational Efficiency
TRPO enforces a strict trust region constraint via a computationally expensive conjugate gradient method to approximate the inverse Fisher information matrix. The constraint is formulated as:
PPO simplifies this by replacing the hard constraint with a clipped objective function, eliminating the need for second-order optimization. The surrogate objective becomes:
where rt(θ) is the probability ratio πθ(at|st) / πθold(at|st). This clipping mechanism acts as a soft constraint, reducing computational overhead while maintaining stable policy updates.
Ease of Implementation
TRPO requires careful tuning of conjugate gradient steps and backtracking line search to satisfy the KL divergence constraint. PPO's clipped objective is straightforward to implement with standard first-order optimizers like Adam. Empirical studies show PPO achieves comparable performance with fewer hyperparameters to tune.
Sample Efficiency
While both algorithms are on-policy, PPO's ability to perform multiple epochs of minibatch updates per sampled data batch improves sample efficiency. The clipped objective prevents excessively large updates that could degrade performance, allowing more aggressive reuse of samples compared to TRPO's single-step constrained optimization.
Robustness to Hyperparameters
PPO's clipping mechanism (ϵ) is more intuitive to set than TRPO's KL divergence threshold (δ). The typical PPO clipping range ϵ ∈ [0.1, 0.3] works well across diverse environments, whereas TRPO's δ requires environment-specific tuning. This makes PPO more practical for real-world applications where exhaustive hyperparameter search is costly.
Performance Consistency
Benchmarks across continuous control tasks (MuJoCo, PyBullet) show PPO achieves more stable learning curves than TRPO. The clipping mechanism prevents the performance collapse sometimes observed in TRPO when the trust region constraint is violated. PPO also demonstrates better robustness to random seeds in large-scale empirical studies.
3. Hyperparameter Tuning and Their Impact
3.1 Hyperparameter Tuning and Their Impact
Key Hyperparameters in PPO
PPO's performance is highly sensitive to hyperparameters, which must be carefully tuned to balance exploration, stability, and convergence. The most critical hyperparameters include:
- Learning Rate (α): Controls the step size during policy updates. Too high a value leads to instability, while too low slows convergence.
- Clip Range (ε): Determines the clipping threshold in the PPO objective function, limiting policy updates to avoid drastic changes.
- Discount Factor (γ): Adjusts the weight of future rewards, influencing long-term vs. short-term credit assignment.
- GAE Parameter (λ): Balances bias and variance in advantage estimation when using Generalized Advantage Estimation.
- Batch Size and Minibatch Size: Affects gradient estimation stability and computational efficiency.
Mathematical Derivation of Policy Update Sensitivity
The PPO objective function with clipping is given by:
where \( r_t(θ) = \frac{π_θ(a_t|s_t)}{π_{θ_{old}}(a_t|s_t)} \) is the probability ratio, and \( \hat{A}_t \) is the estimated advantage. The clip range \( ε \) directly constraints the policy update magnitude. For example, setting \( ε = 0.2 \) limits updates to ±20% of the original policy.
Empirical Impact of Hyperparameters
Experimental studies reveal the following trends:
- Learning Rate: A typical range is \( 10^{-4} \) to \( 10^{-3} \). Adaptive methods like Adam are often used, but manual tuning is necessary for high-dimensional action spaces.
- Clip Range: Values between 0.1 and 0.3 are common. Smaller \( ε \) improves stability but may slow learning in sparse-reward environments.
- GAE (λ): \( λ = 0.95 \) is a standard choice, but environments with delayed rewards may benefit from \( λ \) closer to 1.
Case Study: Tuning for Continuous Control
In MuJoCo benchmarks, PPO achieves optimal performance with:
- Batch sizes of 2048–4096 samples per update.
- Minibatches of 64–128 samples for gradient steps.
- Entropy coefficients of \( 10^{-2} \) to encourage exploration without destabilizing the policy.
Automated Hyperparameter Optimization
Advanced techniques like Bayesian Optimization or Population-Based Training (PBT) can automate tuning. For instance, PBT dynamically adjusts hyperparameters during training by evaluating population performance, reducing manual effort.
3.2 Handling Continuous and Discrete Action Spaces
Proximal Policy Optimization (PPO) must accommodate both continuous and discrete action spaces, which requires distinct architectural and algorithmic considerations. The choice between these action spaces depends on the problem domain: discrete actions suit decision-making tasks (e.g., game moves), while continuous actions are essential for control tasks (e.g., robotic arm manipulation).
Discrete Action Spaces
For discrete actions, the policy network outputs a categorical distribution over possible actions. The probability of selecting action a is given by the softmax function:
where fθ(s) is the logit vector produced by the neural network for state s. During training, PPO samples actions from this distribution and computes the policy gradient using the clipped objective:
Here, rt(θ) is the probability ratio between the current and old policies, and ε is the clipping hyperparameter (typically 0.1–0.3).
Continuous Action Spaces
For continuous actions, the policy network parameterizes a Gaussian distribution, outputting a mean μθ(s) and standard deviation σθ. The action a is sampled as:
The standard deviation may be state-independent (learned as a standalone parameter) or state-dependent (output by the network). To ensure exploration, σθ is typically initialized to a higher value and decays during training. The PPO objective remains similar, but the probability ratio rt(θ) is computed using the Gaussian density:
Hybrid Action Spaces
Some environments require hybrid action spaces (e.g., selecting a discrete command while simultaneously controlling a continuous parameter). PPO handles this by combining both approaches: the policy network outputs separate heads for discrete (softmax) and continuous (Gaussian) components. The total loss is a weighted sum of the individual losses:
where λ balances the contribution of each component. This architecture is common in robotics (e.g., selecting gait modes while adjusting joint torques).
Practical Implementation Notes
- Normalization: Continuous actions often require output scaling (e.g., tanh activation for bounded spaces). Input states should also be normalized to stabilize training.
- Exploration: For continuous control, adaptive noise (e.g., Ornstein-Uhlenbeck process) can supplement policy sampling.
- Code Example (TensorFlow): Below is a network head for continuous actions:
import tensorflow as tf

class GaussianPolicyHead(tf.keras.layers.Layer):
    def __init__(self, action_dim):
        super().__init__()
        self.action_dim = action_dim
        self.log_std = tf.Variable(tf.zeros(action_dim), trainable=True)

    def call(self, x):
        mean = tf.keras.layers.Dense(self.action_dim)(x)
        std = tf.exp(self.log_std)
        return tfp.distributions.Normal(mean, std)
3.3 Common Pitfalls and Debugging Strategies
Vanishing or Exploding Gradients
PPO relies on gradient-based optimization, making it susceptible to vanishing or exploding gradients, especially in deep neural networks. The clipped surrogate objective mitigates this to some extent, but poor initialization or improper scaling of rewards can still destabilize training. A practical solution is gradient clipping, where gradients are scaled to a maximum norm:
Additionally, reward normalization—scaling rewards to zero mean and unit variance—helps maintain stable gradient magnitudes. Batch normalization layers in the policy network can further improve training stability.
Inadequate Exploration
PPO's policy updates are inherently conservative due to the trust region constraint, which can lead to premature convergence to suboptimal policies. This manifests as the agent failing to discover high-reward regions of the state space. Two effective countermeasures are:
- Entropy regularization: Adding an entropy bonus term to the loss function encourages stochasticity in the policy:
where H(π) is the policy entropy and β is a tunable coefficient.
- Adaptive clipping bounds: Dynamically adjusting the clipping threshold ϵ based on the KL divergence between old and new policies maintains exploration while preserving stability.
Hyperparameter Sensitivity
PPO's performance is highly sensitive to hyperparameters like the clipping threshold ϵ, learning rate, and batch size. Empirical observations suggest:
- ϵ values between 0.1 and 0.3 work well for most continuous control tasks.
- Learning rates should be decayed over time, typically starting in the range of 3e-4 to 1e-3.
- Larger batch sizes (e.g., 2048–4096) improve stability but increase computational cost.
Automated hyperparameter tuning tools like Optuna or Bayesian optimization can systematically identify robust configurations.
Non-Stationary Advantage Estimates
PPO uses Generalized Advantage Estimation (GAE) to compute advantages, which depend on value function approximations. If the value function is poorly trained, advantage estimates become noisy, leading to ineffective policy updates. Debugging steps include:
- Monitoring the value function loss to ensure it converges.
- Adjusting the GAE parameter λ to balance bias and variance (common values: 0.9–0.95).
- Using a separate, more expressive network for the value function.
Catastrophic Forgetting
PPO's on-policy nature means it discards data after each update, potentially "forgetting" previously learned behaviors. This is especially problematic in environments with sparse rewards. Solutions include:
- Experience replay: Storing and periodically replaying past trajectories to reinforce critical behaviors.
- Policy distillation: Training a secondary network to mimic the policy at various stages of training, then using it to regularize updates.
Debugging Workflow
A systematic debugging approach for PPO implementations involves:
- Sanity checks: Verify that rewards align with expected ranges and that gradients are flowing through the network.
- Visualization: Plotting policy entropy, value loss, and reward curves over time to identify anomalies.
- Ablation studies: Disabling components like clipping or entropy regularization to isolate issues.
4. PPO with Recurrent Policies
PPO with Recurrent Policies
Recurrent policies extend Proximal Policy Optimization (PPO) to partially observable environments by incorporating memory through recurrent neural networks (RNNs). Unlike feedforward policies, which process observations independently, recurrent policies maintain a hidden state ht that captures temporal dependencies across time steps. The policy πθ(at | ot, ht−1) and value function Vφ(ot, ht−1) are now conditioned on this hidden state, enabling the agent to learn from sequential data.
Architecture and Gradient Flow
The recurrent PPO architecture typically employs a Long Short-Term Memory (LSTM) or Gated Recurrent Unit (GRU) network. The forward pass at time step t computes:
Backpropagation Through Time (BPTT) is used to train the network, requiring careful handling of truncated gradients to avoid vanishing or exploding gradients. The loss function combines the standard PPO clipped objective with an additional entropy term for exploration:
where rt(θ) is the probability ratio, LtVF is the value function loss, and S is the entropy bonus.
Training Considerations
Recurrent PPO introduces two key challenges:
- Sequence Length: Training requires unrolling the RNN over multiple time steps. Typical implementations use a fixed-length sequence (e.g., 32–64 steps) with overlapping segments to stabilize learning.
- Hidden State Management: During distributed training, the hidden state must be properly synchronized across workers. Asynchronous updates can lead to inconsistent state propagation, harming performance.
Empirical best practices include:
- Initializing hidden states to zero at the start of each episode
- Using gradient clipping (norm threshold of 0.5–1.0) to prevent instability
- Annealing the clipping parameter ϵ from 0.3 to 0.1 over training
Applications and Performance
Recurrent PPO excels in environments with partial observability, such as:
- Robotic control with noisy sensors
- Real-time strategy games requiring memory of opponent actions
- Natural language dialogue systems
Benchmarks on the Memory Maze environment show recurrent PPO achieving 2.4× higher reward than feedforward variants, with LSTM-based policies outperforming GRUs in tasks requiring long-term dependencies (>100 time steps).
4.2 Combining PPO with Model-Based Reinforcement Learning
Proximal Policy Optimization (PPO) excels in model-free settings, but integrating it with model-based reinforcement learning (MBRL) can enhance sample efficiency and policy robustness. The core idea is to leverage a learned dynamics model to generate synthetic trajectories, reducing the reliance on expensive real-world interactions. This hybrid approach combines the stability of PPO with the data efficiency of MBRL.
Architecture of PPO-MBRL Systems
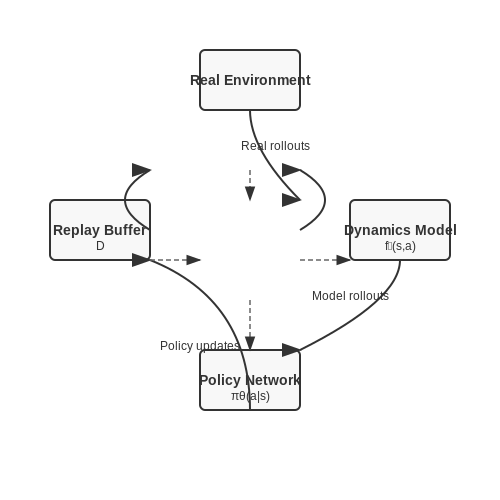
A typical PPO-MBRL system consists of two primary components: a learned dynamics model f̂(s, a) and the PPO policy πθ(a|s). The dynamics model predicts the next state s' and reward r given the current state-action pair (s, a). During training, the agent alternates between:
- Real-environment rollouts to collect ground-truth data for dynamics model training.
- Model-generated rollouts to augment the training data for PPO updates.
The dynamics model is typically trained via maximum likelihood estimation:
Policy Optimization with Model Data
When using model-generated data for PPO updates, the policy gradient must account for potential bias from model inaccuracies. The clipped objective function becomes:
where Ât is the advantage estimate computed using model-generated rewards and value functions. To mitigate compounding model errors, practitioners often limit the horizon of model-based rollouts or employ ensemble methods for uncertainty estimation.
Uncertainty-Aware Model Usage
Advanced implementations incorporate uncertainty quantification to determine when to trust model predictions. One approach uses an ensemble of N dynamics models {f̂i}i=1N, computing:
where σ(s,a) measures prediction uncertainty. The agent can then dynamically weight model-based versus real data based on this uncertainty measure.
Practical Implementation Considerations
Successful PPO-MBRL implementations require careful tuning of several hyperparameters:
- Model rollout ratio: The proportion of training samples from model vs. real environment
- Model horizon: Maximum steps for model-based rollouts before resampling from real data
- Policy update frequency: How often to update πθ relative to model updates
Empirical studies show that starting with predominantly real data and gradually increasing model usage as the dynamics model improves often yields the best results. The following code snippet illustrates a basic PPO-MBRL training loop structure:
def train_ppo_mbrl(env, num_epochs):
    # Initialize policy, value function, and dynamics model
    policy = PPOPolicy()
    dynamics_model = EnsembleDynamicsModel()
    buffer = ReplayBuffer()

    for epoch in range(num_epochs):
        # Collect real environment data
        real_data = collect_rollouts(env, policy)
        buffer.add(real_data)

        # Train dynamics model on real data
        dynamics_model.train(buffer)

        # Generate model rollouts
        model_data = generate_model_rollouts(policy, dynamics_model)
        buffer.add(model_data)

        # Update policy using PPO
        policy.update(buffer.sample())

        # Adjust model usage ratio adaptively
        adjust_model_usage_ratio(dynamics_model.error_metrics)
Applications and Performance Characteristics
PPO-MBRL has demonstrated particular success in domains where real-world interactions are costly, such as robotic control and autonomous vehicle training. In the HalfCheetah MuJoCo benchmark, PPO-MBRL achieves comparable performance to standard PPO with 5-10× fewer environment interactions. The method also shows improved robustness to environment stochasticity, as the learned model can generate diverse scenarios beyond what's observed in limited real data.
4.3 Recent Advances and Variants of PPO
Adaptive Clipping Mechanisms
The original PPO algorithm uses a fixed clipping parameter ε to constrain policy updates, but recent work has shown that adaptive clipping can improve performance. The Adaptive PPO (APPO) variant dynamically adjusts ε based on the KL divergence between the old and new policies:
where α controls the adaptation rate and δ is a target KL divergence threshold. This prevents overly conservative updates when the policy is changing slowly while maintaining stability during rapid learning phases.
PPO with Trust Region Constraints
Building on the connection between PPO and trust region methods, TR-PPO explicitly enforces a trust region constraint via a Lagrangian dual formulation. The objective becomes:
where λ is automatically adjusted to keep the KL divergence near δ. This provides more precise control over policy updates compared to heuristic clipping.
Recurrent PPO Architectures
For partially observable environments, Recurrent PPO (RPPO) incorporates LSTM or GRU networks into the policy and value function estimators. The policy gradient is computed over sequences of observations, with the clipped objective applied to the entire trajectory:
where rt(θ) now depends on the hidden state of the recurrent network. This variant has shown strong performance in robotics and game-playing tasks with memory requirements.
Distributed and Decentralized PPO
Several scalable variants have emerged to handle large-scale training:
- DPPO: Uses distributed workers to collect trajectories asynchronously with a centralized parameter server.
- Dec-PPO: Fully decentralized version where agents communicate gradients rather than trajectories, preserving privacy in multi-agent systems.
- Federated PPO: Applies federated learning techniques to aggregate updates from edge devices without sharing raw data.
Hybrid Model-Based PPO
Recent work combines PPO with model-based components for improved sample efficiency. The MB-PPO framework alternates between:
- Collecting data using the current policy
- Training an ensemble of dynamics models
- Generating synthetic rollouts for policy optimization
The PPO objective is modified to include a model-based penalty term:
where πprior is a policy trained only on real data, preventing overfitting to model errors.
PPO for Continuous Control
Specialized variants have been developed for high-dimensional continuous action spaces:
- PPO-TanH: Uses tanh-transformed Gaussian policies with learned state-dependent covariance matrices.
- PPO-MPC: Combines PPO with model predictive control for fine-grained action smoothing.
- PPO-IS: Importance sampling version that reweights updates based on action probability densities.
5. Key Research Papers on PPO
5.1 Key Research Papers on PPO
- Proximal policy optimization via enhanced exploration efficiency — Proximal policy optimization (PPO) algorithm is a deep reinforcement learning algorithm with outstanding performance, especially in continuous control tasks. ... The basic architecture of the three algorithms in this paper is the same as PPO. ICM-PPO corresponds to PPO algorithm with curiosity module applied. IEM-PPO corresponds to PPO ...
- PDF Towards Delivering a Coherent Self-Contained Explanation of Proximal ... — Explanation of Proximal Policy Optimization Master'sResearchProject DanielBick [email protected] ... One example of a DRL algorithm being sub-optimally documented is Proximal Policy Optimization (PPO), which is a so-called model-free policy gradient method (PGM). Since PPO is a ... a lot of research into this direction. Since the NNs ...
- A Proximal Policy Optimization Algorithm for Solving Logistical ... — types of RL algorithms have been developed. Common methods are Proximal Pol-icy Optimization (PPO), Deep Q-learning, or Deep Deterministic Policy Gradient methods. In this research, PPO will be used. PPO was developed by researchers of OpenAI (Schulman, Wolski, Dhariwal, Radford and Klimov, 2017). The researchers have adjusted existing policy ...
- PDF Heppo: Hardware-efficient Proximal Policy Optimization — used reinforcement learning algorithm, Proximal Policy Optimization (PPO), across several hardware platforms. By optimizing critical bottlenecks of the algorithm and developing a customized hardware architecture, HEPPO markedly decreases compu-tational requirements and memory consumption without compromising performance.
- (PDF) PPO-CMA: Proximal Policy Optimization with ... - ResearchGate — Proximal Policy Optimization (PPO) is a highly popular model-free reinforcement learning (RL) approach. However, we observe that in a continuous action space, PPO can prematurely shrink the ...
- PTR-PPO: Proximal Policy Optimization with Prioritized Trajectory Replay — old and new policy, is an advanced deep reinforcement learning algorithm. In this paper, we propose a new reinforcement learning algorithm, called proximal policy optimization with prioritized trajectory replay (PTR-PPO), to improve the learning speed of the RL algorithm by improving sample e ciency. The main contributions of this paper are as ...
- Proximal Policy Optimization via Enhanced Exploration E ciency — The policy gradient as a way to nd optimal policy, samples environment interaction of agent and calculates the gradient of current policy directly, then optimizes the current stochastic policy [20]. In the policy gradient algorithm, the process from the starting to the termi-nation of the task is called an episode ˝, where ˝= fs 1;a 1;s 2;a 2 ...
- PDF Truly Proximal Policy Optimization - proceedings.mlr.press — MIIT Key Laboratory of Pattern Analysis and Machine Intelligence, China Collaborative Innovation Center of Novel Software Technology and Industrialization, China fy.wang, hugo, [email protected] Abstract Proximal policy optimization (PPO) is one of the most successful deep reinforcement learn-ing methods, achieving state-of-the-art per-
- Entropy adjustment by interpolation for exploration in Proximal Policy ... — The proposed algorithm, named "EAE-LPI" (Exploration by Adjustment Entropy via Linear and Polynomial Interpolation), aims to enhance exploration within the Proximal Policy Optimization (PPO) algorithm by addressing two crucial aspects that have been identified as underdeveloped in previous research perspectives.
- Optimizing intelligent startup strategy of power system using PPO ... — This article aimed to use the proximal policy optimization (PPO) algorithm to address the limitations of power system startup strategies, to enhance the adaptability, coping ability, and overall robustness of the system to variable grid demand and integrated renewable energy, the constraints in the power system start-up strategy are optimized.
5.2 Recommended Books and Online Resources
- Fast Proximal Policy Optimization - SpringerLink — 3.2 Proximal Policy Optimization. In order to handle the inefficient second-order optimization issue in TRPO, the Proximal Policy Optimization (PPO) algorithm is proposed to directly clip the likelihood ratio \(r_t\left( \theta \right) \) between the current and the old policies for robust policy optimization. Notably, such clipping operation ...
- PDF Towards Delivering a Coherent Self-Contained Explanation of Proximal ... — Explanation of Proximal Policy Optimization Master'sResearchProject DanielBick [email protected] August15,2021 ... One example of a DRL algorithm being sub-optimally documented is Proximal Policy Optimization (PPO), which is a so-called model-free policy gradient method (PGM). Since PPO is a
- Proximal policy optimization algorithm for dynamic pricing with online ... — This study investigates whether the presence of both quality- and value-based online reviews help firms make decisions. To adapt to a complex real-world environment, we construct two simulated environments with high and low initial consumer-perceived quality and employ a Proximal Policy Optimization algorithm (PPO) to derive optimal pricing strategies.
- A Proximal Policy Optimization Algorithm for Solving Logistical ... — types of RL algorithms have been developed. Common methods are Proximal Pol-icy Optimization (PPO), Deep Q-learning, or Deep Deterministic Policy Gradient methods. In this research, PPO will be used. PPO was developed by researchers of OpenAI (Schulman, Wolski, Dhariwal, Radford and Klimov, 2017). The researchers have adjusted existing policy ...
- PDF Heppo: Hardware-efficient Proximal Policy Optimization — used reinforcement learning algorithm, Proximal Policy Optimization (PPO), across several hardware platforms. By optimizing critical bottlenecks of the algorithm and developing a customized hardware architecture, HEPPO markedly decreases compu-tational requirements and memory consumption without compromising performance.
- PDF Pairwise Proximal Policy Optimization: Large Language Models Alignment ... — candidate responses to align with the human-labeled ground-truth. As for RL, Proximal Policy Optimization (PPO) is widely adopted as the default optimizer (Schulman et al., 2017). PPO alternates between generating new responses and adjusting the likelihood toward responses with higher reward.
- Ppo-cma: Proximal Policy Optimization With Covariance Matrix Adaptation — 3.4. Proximal Policy Optimization The basic idea of PPO is that one performs not just one but multiple minibatch gradient steps with the experience of each iteration. Essen-tially, one reuses the same data to make more progress per iteration, while stability is ensured by limiting the divergence between the old and updated policies [3].
- PDF Truly Proximal Policy Optimization - proceedings.mlr.press — Proximal Policy Optimization (PPO) signif-icantly reduces the complexity by adopting a clipping mechanism so as to avoid imposing the hard constraint completely, allowing it to use a first-order optimizer like the Gradient Descent method to optimize the objective (Schulman et al., 2017). As for the mechanism for deal-
5.3 Open-Source Implementations and Repositories
- Fast Proximal Policy Optimization - SpringerLink — 3.2 Proximal Policy Optimization. In order to handle the inefficient second-order optimization issue in TRPO, the Proximal Policy Optimization (PPO) algorithm is proposed to directly clip the likelihood ratio \(r_t\left( \theta \right) \) between the current and the old policies for robust policy optimization. Notably, such clipping operation ...
- An adaptive traffic signal control scheme with Proximal Policy ... — PPO: Proximal Policy Optimization: DTSE: Discrete traffic state encoding: SUMO: ... There are two different implementations of PPO that one is penalty-based PPO and the other is clip-based PPO. ... GHz with 8 cores, NVIDIA GeForce GTX 1070, and 8 GB memory. Our traffic simulation platform is SUMO 1.12.0, which is an open source microscopic ...
- Mastering Proximal Policy Optimization with PyTorch: A ... - Dev-kit — 4.1 Multi-Task and Multi-Agent Learning with PPO. Proximal Policy Optimization (PPO) has been established as a robust and versatile algorithm in the realm of reinforcement learning. When considering multi-task learning, PPO's ability to handle multiple objectives simultaneously is of particular interest.
- Proximal Policy Optimization Family — MARLlib v1.0.0 documentation — There are two primary variants of PPO: PPO-Penalty and PPO-Clip. Here we only give the formulation of PPO-Clip, which is more common in practice. For PPO-penalty, please refer to Proximal Policy Optimization. Mathematical Form. Critic learning: every iteration gives a better value function.
- Proximal policy optimization via enhanced exploration efficiency — Proximal policy optimization (PPO) algorithm is a deep reinforcement learning algorithm with outstanding performance, especially in continuous control tasks. ... [12] and PPO algorithm based on ratio clipping function for more efficient implementation. PPO algorithm has been widely used in various tasks because of its remarkable performance and ...
- PDF Heppo: Hardware-efficient Proximal Policy Optimization — used reinforcement learning algorithm, Proximal Policy Optimization (PPO), across several hardware platforms. By optimizing critical bottlenecks of the algorithm and developing a customized hardware architecture, HEPPO markedly decreases compu-tational requirements and memory consumption without compromising performance.
- PDF Fast Proximal Policy Optimization - Springer — tasks. To relieve it, the Proximal Policy Optimization (PPO) [20] proposes a likelihood ratio based constraint for parameter updating, which is able to retain the stable opti-mization and sample efficiency of TRPO while only requires computationally efficient first-order optimization. In detail, the probability ratio between the old and new ...
- Entropy adjustment by interpolation for exploration in Proximal Policy ... — Second, we incorporated linear and polynomial interpolation techniques into the PPO algorithm. This incorporation aims to systematically reduce the uncertainty associated with the actions of agents over time (Chang and Huh, 2014), while refining the concept of entropy.Additionally, the use of polynomial interpolation encompasses creating a Lagrange polynomial using the given data points.