Online Anomaly Detection with Streaming Data
1. Definition and Key Concepts of Anomaly Detection
Definition and Key Concepts of Anomaly Detection
Anomaly detection refers to the identification of rare items, events, or observations that deviate significantly from the majority of data and raise suspicions by differing from established patterns. In streaming data contexts, anomalies are often transient, evolving, or context-dependent, necessitating real-time or near-real-time processing.
Mathematical Formulation
Given a data stream X = {x1, x2, ..., xt}, where each xi ∈ ℝd, an anomaly detection algorithm computes an anomaly score si ∈ ℝ for each observation. A decision function δ then classifies xi as anomalous if si > τ, where τ is a threshold. The score can be derived from distance, density, or probabilistic measures.
where f is a scoring function and ℳ represents the underlying model (e.g., Gaussian distribution, clustering model, or autoencoder). For streaming data, ℳ must adapt over time to concept drift.
Types of Anomalies
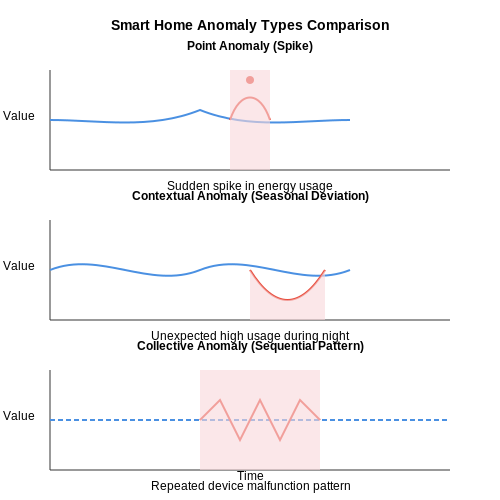
- Point anomalies: Single instances that are anomalous relative to the rest of the data (e.g., a sudden spike in sensor readings).
- Contextual anomalies: Data points that are anomalous only in a specific context (e.g., a temperature reading of 30°C is normal in summer but anomalous in winter).
- Collective anomalies: A sequence of data points that, when occurring together, are anomalous (e.g., a sustained high-frequency signal in a vibration sensor).
Challenges in Streaming Anomaly Detection
Online anomaly detection introduces unique challenges:
- Concept drift: The underlying data distribution may change over time, requiring adaptive models.
- Limited memory: Streaming algorithms must process data in a single pass or with bounded memory.
- Latency constraints: Real-time applications demand low-latency scoring.
- Label scarcity: Anomalies are rare, making supervised learning difficult.
Common Approaches
Key methodologies for streaming anomaly detection include:
- Statistical methods: Assume data follows a known distribution (e.g., Gaussian) and flag deviations.
- Distance-based methods: Use metrics like Euclidean or Mahalanobis distance to identify outliers.
- Density-based methods: Compare local density (e.g., LOF) to detect low-density regions.
- Model-based methods: Autoencoders, LSTMs, or Isolation Forests learn normal patterns and flag deviations.
where Nk denotes the k-nearest neighbors, reach-distk is the reachability distance, and lrdk is the local reachability density.
Practical Considerations
In real-world applications, preprocessing (e.g., normalization, windowing) and postprocessing (e.g., smoothing anomaly scores) are critical. For instance, sliding windows or exponential decay can balance responsiveness and stability in streaming settings.
1.2 Challenges in Streaming Data Environments
Concept Drift and Non-Stationarity
Streaming data environments are inherently non-stationary, meaning their underlying statistical properties evolve over time. This phenomenon, known as concept drift, occurs when the relationship between input features and target variables changes. For instance, in financial fraud detection, fraudsters adapt their strategies, causing the model's assumptions to degrade. Mathematically, concept drift can be expressed as a time-dependent shift in the joint probability distribution:
where X represents the feature space and y the target variable. Handling concept drift requires adaptive algorithms that either detect shifts explicitly (e.g., using the Kolmogorov-Smirnov test) or continuously update the model (e.g., online gradient descent).
Latency and Real-Time Constraints
Unlike batch processing, streaming anomaly detection imposes strict latency constraints. The system must process each data point within a fixed time window, often measured in milliseconds. This demands:
- Lightweight feature extraction (e.g., incremental PCA instead of full SVD)
- Constant-time algorithms (O(1) per sample)
- Efficient memory management (sliding windows, reservoir sampling)
For example, a network intrusion detection system analyzing 1M packets/second cannot afford multi-second model updates without missing critical threats.
Memory and Computational Limits
Streaming algorithms must operate within bounded memory, ruling out traditional approaches that require storing the entire dataset. Techniques like:
- Exponential forgetting: Older samples are downweighted via decay factors (e.g., $$w_t = \lambda w_{t-1}$$ where $$\lambda \in (0,1)$$)
- Sketching: Data structures like Count-Min Sketch approximate statistics in sublinear space
- Micro-clustering: Summarizes dense regions for clustering-based anomaly detection
These methods trade exactness for scalability, introducing approximation errors that must be carefully managed.
Label Scarcity and Delayed Feedback
Supervised learning becomes challenging when labels arrive sporadically or with significant delay (e.g., fraud confirmation takes weeks). Solutions include:
- Semi-supervised approaches using one-class SVM or isolation forests
- Active learning to prioritize uncertain samples for labeling
- Proxy tasks (e.g., predicting reconstruction error in autoencoders)
In industrial IoT systems, less than 0.1% of sensor readings might have verified anomaly labels, making traditional supervised methods impractical.
High-Dimensional Data Streams
Modern sensors generate high-dimensional vectors (e.g., 1000+ features in hyperspectral imaging). The curse of dimensionality exacerbates distance concentration problems, where anomaly scores become indistinguishable. Dimensionality reduction techniques must adapt incrementally:
where W is the projection matrix and η the learning rate. Failure to handle this can lead to inflated false positive rates.
Real-World Applications and Use Cases
Cybersecurity and Network Intrusion Detection
Online anomaly detection is critical in cybersecurity for identifying malicious activities in real-time network traffic. Streaming data from firewalls, routers, and servers generate high-dimensional feature spaces where anomalies often represent Distributed Denial-of-Service (DDoS) attacks, port scanning, or unauthorized access attempts. Algorithms like Isolation Forest and One-Class SVM are deployed in intrusion detection systems (IDS) to flag deviations from normal traffic patterns. For instance, a sudden spike in packet size variance or abnormal TCP flag combinations can trigger alerts.
where E(h(x)) is the average path length of instance x in the isolation tree ensemble, and c(n) is the normalization factor for a dataset of size n.
Industrial IoT and Predictive Maintenance
In manufacturing, sensor streams from equipment (vibration, temperature, pressure) are monitored for early fault detection. A multivariate Gaussian model can detect anomalies in rotating machinery by modeling the joint distribution of sensor readings. For example, deviations in the Mahalanobis distance beyond a threshold τ indicate potential failures:
where μ and Σ are the mean and covariance matrix of normal operation data.
Financial Fraud Detection
Credit card transactions and stock trades are analyzed in real-time using autoencoders or Holt-Winters exponential smoothing. Anomalies manifest as unusual transaction amounts, geographic locations, or timing patterns. The reconstruction error ε of an autoencoder serves as an anomaly score:
Healthcare Monitoring
Wearable devices stream physiological data (heart rate, SpO2) where anomalies may indicate arrhythmias or sepsis onset. Change point detection algorithms like CUSUM (Cumulative Sum) are applied to detect shifts in mean or variance:
where μ0 is the baseline mean and k is the allowable deviation.
Autonomous Systems
Self-driving cars use streaming LIDAR and camera data to detect obstacles or sensor malfunctions. A Kalman filter predicts expected sensor readings, with residuals outside confidence intervals flagged as anomalies:
where zt is the observed measurement and Hx̂t− is the predicted state.
2. Statistical Methods: Moving Averages and Z-Scores
Statistical Methods: Moving Averages and Z-Scores
Moving averages and z-scores form the backbone of many real-time anomaly detection systems due to their computational efficiency and interpretability. These methods leverage statistical properties of streaming data to identify deviations from expected behavior without requiring extensive historical data storage.
Moving Averages for Streaming Data
The exponentially weighted moving average (EWMA) provides an efficient way to track the central tendency of a data stream while giving more weight to recent observations. For a data point xt at time t, the EWMA μt updates as:
where α ∈ (0,1) is the smoothing factor controlling the memory of the system. The choice of α represents a trade-off between responsiveness to changes (high α) and noise suppression (low α). For non-stationary processes, α typically ranges between 0.05 and 0.3 in industrial applications.
The corresponding variance estimate σt2 can be computed similarly:
Z-Score Normalization
The z-score transforms raw observations into dimensionless quantities measuring how many standard deviations an observation deviates from the expected value:
This normalization enables anomaly thresholds to be set consistently across different scales. In practice, thresholds of |zt| > 3 (corresponding to ~0.3% false positives under normality assumptions) provide robust detection for many applications.
Practical Considerations
- Initialization: The first N samples (typically 30-100) should be used to compute initial μ and σ estimates before streaming begins
- Non-stationarity: For trends or seasonality, differencing or adaptive α values may be necessary
- Robustness: Median-based alternatives reduce sensitivity to extreme values in the initialization phase
In high-frequency trading systems, this approach achieves microsecond-level latency while maintaining sub-1% false positive rates. The method's simplicity allows for efficient hardware implementation in FPGA or ASIC designs for ultra-low-latency applications.
Multivariate Extensions
For d-dimensional streams, the Mahalanobis distance generalizes the z-score:
where Σt is the exponentially weighted covariance matrix. The inverse covariance calculation requires regularization techniques when d is large relative to the effective sample size.
2.2 Machine Learning Approaches: Isolation Forests and One-Class SVMs
Isolation Forests for Anomaly Detection
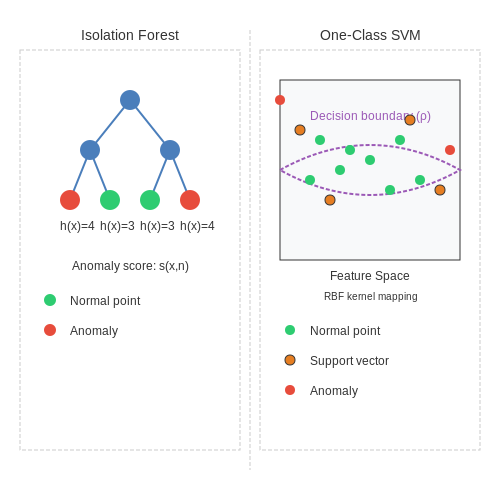
Isolation Forests (iForest) exploit the observation that anomalies are few and different, making them easier to isolate than normal points. The algorithm constructs binary trees by randomly selecting a feature and a split value until instances are isolated. Anomalies require fewer splits due to their dissimilarity, resulting in shorter path lengths in the tree structure.
where h(x) is the path length for instance x, E(h(x)) is the average path length across all trees, and c(n) is the average path length of unsuccessful searches in a binary search tree given n instances. The anomaly score s approaches 1 for anomalies and 0.5 for normal points.
Key advantages for streaming data include:
- Linear time complexity O(n) and low memory usage
- No need for feature scaling or distance metrics
- Natural adaptation to concept drift through tree updates
One-Class Support Vector Machines
One-Class SVMs (OC-SVM) learn a decision boundary that encompasses normal data points while excluding anomalies. The formulation solves:
where ν controls the fraction of outliers, φ is the kernel mapping, and ξ are slack variables. The Gaussian RBF kernel is commonly used:
For streaming applications, incremental OC-SVM variants update the model by:
- Maintaining support vectors in a fixed-size buffer
- Applying budgeted learning to constrain model growth
- Using forgetting mechanisms for concept drift adaptation
Comparative Analysis
Isolation Forests typically outperform OC-SVMs in high-dimensional spaces and when anomalies form small clusters. OC-SVMs show superior performance when the normal class has a clear, dense structure. Computational requirements differ significantly:
| Metric | Isolation Forest | One-Class SVM |
|---|---|---|
| Training Time | O(n) | O(n²) to O(n³) |
| Memory | O(t) | O(nsvd) |
| Update Cost | O(1) per tree | O(nsv) |
Hybrid approaches that combine both methods have shown promise in industrial monitoring systems, using iForest for initial filtering and OC-SVM for precise classification of suspicious instances.
Deep Learning Techniques: LSTMs and Autoencoders
Long Short-Term Memory (LSTM) Networks
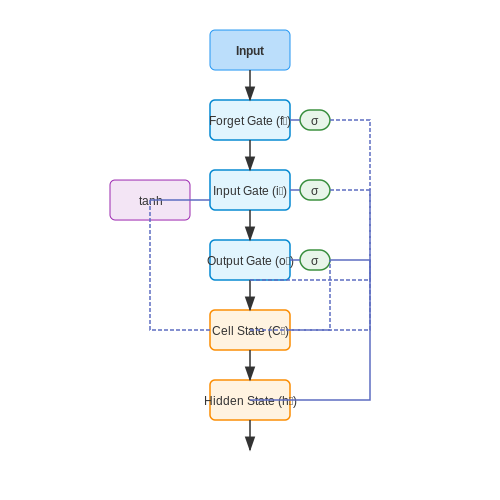
LSTMs are a specialized form of recurrent neural networks (RNNs) designed to capture long-term dependencies in sequential data. Their architecture addresses the vanishing gradient problem through gating mechanisms:
Where ft, it, and ot represent forget, input, and output gates respectively. The cell state Ct maintains memory across time steps, while ht is the hidden state.
For anomaly detection, LSTMs are trained to predict the next expected data point in the sequence. The reconstruction error between predicted and actual values serves as the anomaly score:
Thresholding this error identifies deviations from normal temporal patterns. In streaming applications, LSTMs process fixed-size sliding windows of data with online updates to model parameters via truncated backpropagation through time.
Autoencoder Architectures
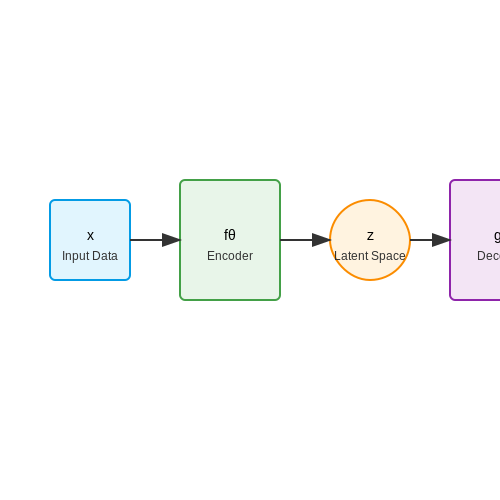
Autoencoders learn compressed representations of input data through an encoder-decoder structure. The encoder ϕ maps input x to latent space z, while the decoder ψ attempts to reconstruct the original input:
The model minimizes reconstruction loss L(x, ψ(ϕ(x))), typically using mean squared error. For multivariate time series, convolutional and recurrent layers can replace dense connections in either the encoder or decoder.
Variational autoencoders (VAEs) introduce probabilistic sampling in the latent space:
This forces the latent space to follow a continuous distribution, improving anomaly detection for novel patterns. The evidence lower bound (ELBO) objective combines reconstruction quality with KL divergence regularization:
Hybrid Approaches
Combining LSTMs with autoencoders leverages both temporal modeling and representation learning. The LSTM-AE architecture processes sequences through recurrent layers before bottleneck compression:
- Input window x1:T passes through LSTM encoder
- Final hidden state hT serves as latent representation
- LSTM decoder reconstructs the sequence from hT
Attention mechanisms can be incorporated to weight important time steps dynamically. The transformer-based anomaly detection variant computes attention scores between all positions in the input window:
Where Q, K, and V are learned linear projections of the input. This architecture excels at capturing long-range dependencies without recurrent connections.
Implementation Considerations
Key hyperparameters for streaming anomaly detection include:
- Window size: Must balance temporal context with computational latency (typically 30-100 samples)
- Latent dimension: 5-20% of input dimensionality preserves essential features while enabling compression
- Threshold selection: Extreme value theory or peak-over-threshold methods adapt to non-Gaussian error distributions
Online learning requires careful handling of model updates. Exponential moving averages of model parameters prevent catastrophic forgetting:
Where α controls the update rate. Gradient clipping and adaptive optimizers (Adam, RMSProp) maintain stability during continuous training.
3. Data Preprocessing for Streaming Pipelines
3.1 Data Preprocessing for Streaming Pipelines
Streaming data introduces unique challenges for anomaly detection due to its high velocity, unbounded nature, and potential for concept drift. Effective preprocessing is critical to ensure robustness in real-time applications. Unlike batch processing, streaming pipelines must handle data incrementally with minimal latency while maintaining statistical consistency.
Windowing Strategies for Temporal Data
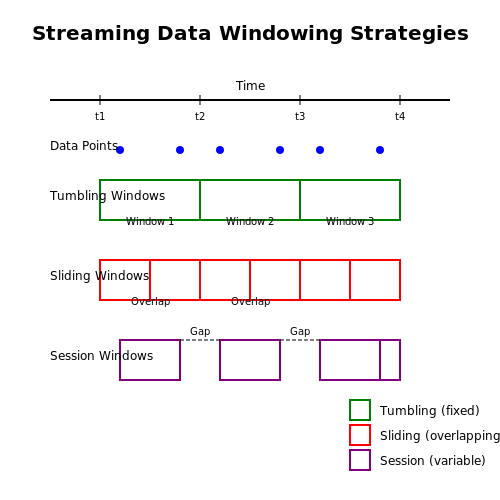
Windowing segments the data stream into finite chunks for processing. The choice of window type impacts detection latency and accuracy:
- Tumbling windows divide the stream into non-overlapping, fixed-size intervals. Simple to implement but may miss anomalies straddling window boundaries.
- Sliding windows overlap by a specified stride, providing finer temporal resolution at increased computational cost.
- Session windows dynamically adjust based on activity gaps, useful for irregular event streams.
where Wt represents the window at time t, Δt is the window size, and ti are timestamps of observations xi.
Adaptive Normalization
Traditional z-score normalization fails in streaming contexts due to evolving data distributions. Exponential moving statistics provide a computationally efficient alternative:
The decay factor α ∈ (0,1) controls the adaptation rate. Smaller values provide stability against noise but slower response to distribution shifts.
Feature Engineering for Non-Stationary Streams
Effective features must capture temporal dynamics while remaining computable in single-pass:
- Difference features: Δxt = xt - xt-k highlight short-term deviations
- Approximate entropy: Computed over sliding windows to quantify signal complexity
- Wavelet coefficients: Provide multi-resolution analysis with O(n) complexity using the à trous algorithm
Handling Missing Data in Real-Time
Streaming systems require imputation methods that don't require future observations:
- Last observation carried forward (LOCF): Simple but propagates errors
- Linear interpolation: Between adjacent points when gaps are small
- Kalman filters: Optimal for systems with known dynamics models
where Ft is the state transition model, Ht the observation model, and Kt the Kalman gain.
Concept Drift Detection
Statistical process control monitors preprocessing outputs for distributional shifts:
where μ0 is the expected mean and δ the allowed drift magnitude. A threshold crossing triggers model adaptation.
Implementation Considerations
State management is critical for distributed streaming systems:
- Checkpointing: Periodic state snapshots enable fault recovery
- Watermarks: Track event-time progress for out-of-order data
- Backpressure handling: Adaptive sampling during overload conditions
  # Python pseudocode for streaming z-score normalization
  class StreamingScaler:
      def __init__(self, alpha=0.01):
          self.alpha = alpha
          self.mean = 0
          self.var = 1

      def update(self, x):
          delta = x - self.mean
          self.mean += self.alpha * delta
          self.var = (1 - self.alpha) * (self.var + self.alpha * delta**2)
          return (x - self.mean) / (np.sqrt(self.var) + 1e-8)
3.2 Choosing the Right Window Size and Sliding Techniques
The effectiveness of online anomaly detection hinges on the selection of an appropriate window size and sliding strategy. These parameters dictate how much historical data is considered at each step and how the model adapts to temporal changes in the data stream.
Window Size Selection
The window size W determines the number of recent data points used for anomaly scoring. A trade-off exists between responsiveness and stability:
- Small windows (W < 100) enable rapid detection of abrupt changes but are susceptible to noise and false positives.
- Large windows (W > 1000) provide stable statistical estimates but may miss short-lived anomalies.
The optimal window size can be derived from the autocorrelation structure of the time series. For a process with autocorrelation time τ, the window should satisfy:
where τ is the lag at which the autocorrelation function falls below 1/e. This ensures sufficient data for reliable estimation while maintaining responsiveness.
Sliding Techniques
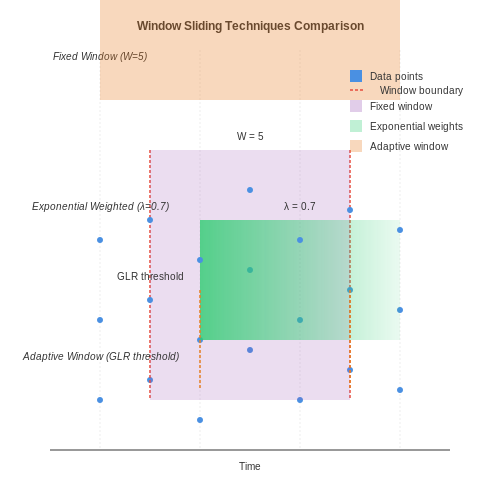
Three primary sliding approaches exist for streaming anomaly detection:
Fixed Sliding Window
The simplest approach where the window moves forward by a fixed step s at each update. The computational complexity is O(W) per update. This method works well for stable processes but can miss anomalies that occur between windows.
Exponentially Weighted Moving Window
Instead of hard cutoffs, this approach applies decaying weights to observations:
where λ ∈ (0,1) is the forgetting factor. This provides smooth transitions between windows but requires careful tuning of λ to balance memory and responsiveness.
Adaptive Window Sizing
More sophisticated approaches dynamically adjust the window size based on change-point detection statistics. The generalized likelihood ratio (GLR) test can be used:
where σ̂², σ̂₁², and σ̂₂² are variance estimates for the full window and two segments. When GLR exceeds a threshold, the window resets to focus on recent data.
Practical Considerations
In real-world deployments, consider these factors:
- Computational constraints: Larger windows require more memory and processing power.
- Data characteristics: High-frequency data may need larger windows to capture meaningful patterns.
- Anomaly duration: The window should be at least as long as typical anomaly durations to ensure detectability.
For multivariate streams, the window size must account for cross-correlations between dimensions. The effective sample size neff can be estimated using:
where ρ(k) is the average cross-correlation at lag k across dimensions.
3.3 Handling Concept Drift in Real-Time Data
Concept drift occurs when the statistical properties of the target variable or input features change over time in unforeseen ways, rendering previously trained models ineffective. In streaming data applications, such as fraud detection, network intrusion monitoring, or industrial sensor analytics, drift can arise due to seasonal trends, adversarial manipulation, or shifts in underlying system behavior. Detecting and adapting to these changes in real-time is critical for maintaining model accuracy.
Mathematical Formulation of Concept Drift
Let X be the input feature space and Y the target variable. At time t, the joint distribution is Pt(X, Y). Concept drift occurs when:
Drift can be categorized into three primary types:
- Covariate Shift: Pt(X) changes while Pt(Y|X) remains stable.
- Prior Probability Shift: Pt(Y) changes while Pt(X|Y) is constant.
- Concept Shift: Pt(Y|X) changes, requiring model re-training.
Real-Time Drift Detection Methods
Statistical Process Control (SPC)
SPC techniques monitor model performance metrics (e.g., error rate, precision) using control charts. The CUSUM (Cumulative Sum) algorithm detects small shifts by accumulating deviations from a reference value:
where εt is the observed error at time t, and δ is a drift threshold. A drift alarm triggers when St exceeds a predefined boundary.
Adaptive Windowing (ADWIN)
ADWIN dynamically adjusts the window size of recent data to maintain stable statistics. It compares means μ1 and μ2 of two sub-windows, triggering drift when:
The cutoff εcut is derived from the Hoeffding bound, ensuring statistical significance.
Model Adaptation Strategies
Ensemble Methods
Weighted ensemble approaches, such as Dynamic Weighted Majority (DWM), maintain multiple models and adjust their voting weights based on recent performance. The weight wi,t for model i at time t updates as:
where β ∈ (0,1) is a decay factor, and 𝕀 is the indicator function.
Incremental Learning
Online gradient descent methods, such as Stochastic Gradient Descent (SGD), adapt model parameters θ continuously:
where ηt is a learning rate schedule. For non-stationary data, adaptive optimizers like AdaGrad or Adam are preferred.
Practical Implementation Considerations
Deploying drift-adaptive systems requires:
- Memory Efficiency: Use reservoir sampling or sliding windows to bound computational overhead.
- Latency Constraints: Optimize detection algorithms for low-latency environments (e.g., FPGAs for high-frequency trading).
- Explainability: Log drift events with statistical evidence to support model updates.
4. Metrics for Imbalanced Data: Precision, Recall, and F1-Score
4.1 Metrics for Imbalanced Data: Precision, Recall, and F1-Score
In anomaly detection, datasets are often highly imbalanced, with anomalies representing a small fraction of observations. Traditional accuracy metrics fail in such scenarios, as a model that always predicts the majority class can achieve high accuracy while being practically useless. Instead, precision, recall, and the F1-score provide more meaningful evaluations by focusing on the model's performance on the minority class.
Precision: The Measure of Exactness
Precision quantifies the proportion of true positives among all predicted positives. In anomaly detection, it answers: When the model flags an observation as anomalous, how often is it correct? The mathematical definition is:
where TP denotes true positives (correctly detected anomalies) and FP denotes false positives (normal instances incorrectly flagged as anomalies). High precision indicates low false alarm rates, crucial in applications where acting on false alarms is costly, such as fraud detection or industrial fault monitoring.
Recall: The Measure of Completeness
Recall, also called sensitivity or true positive rate, measures the proportion of actual anomalies correctly identified by the model. It answers: What fraction of all true anomalies does the model detect? The formula is:
where FN represents false negatives (undetected anomalies). High recall is critical in safety-sensitive domains like medical diagnosis or cybersecurity, where missing an anomaly could have severe consequences.
The Precision-Recall Trade-off
Precision and recall often exhibit an inverse relationship in classification systems. Increasing a model's sensitivity (e.g., by lowering the anomaly detection threshold) typically improves recall but reduces precision, as more false positives are introduced. The optimal balance depends on the application's requirements:
- High-precision regime: Preferred when false positives are expensive (e.g., automated trading systems)
- High-recall regime: Essential when false negatives are dangerous (e.g., cancer screening)
F1-Score: Harmonic Mean of Precision and Recall
The F1-score provides a single metric balancing both concerns through the harmonic mean:
The harmonic mean penalizes extreme values more severely than the arithmetic mean, ensuring neither precision nor recall can be neglected. For multiclass or multilabel anomaly detection, micro-averaged F1 (computing metrics globally across classes) often proves most informative for imbalanced data.
Advanced Variants: Fβ-Score and Matthews Correlation
When precision and recall require asymmetric weighting, the generalized Fβ-score introduces a tunable parameter β:
where β > 1 emphasizes recall, while β < 1 favors precision. For severely imbalanced datasets, the Matthews Correlation Coefficient (MCC) provides a more reliable alternative:
MCC ranges from -1 (perfect inverse prediction) to +1 (perfect prediction), with 0 indicating random performance. Unlike F1-score, MCC accounts for true negatives, making it robust to class imbalance.
Implementation Considerations
In streaming anomaly detection, these metrics must be computed over sliding windows or decaying weighted averages to account for concept drift. Adaptive thresholds that maintain constant precision/recay ratios are particularly effective in non-stationary environments. Libraries like scikit-learn provide efficient incremental computation:
from sklearn.metrics import precision_score, recall_score, f1_score

# For batch evaluation
precision = precision_score(y_true, y_pred, pos_label='anomaly')
recall = recall_score(y_true, y_pred, pos_label='anomaly')
f1 = f1_score(y_true, y_pred, pos_label='anomaly')

# For streaming data (windowed evaluation)
def streaming_metrics(y_true_window, y_pred_window):
    return {
        'precision': precision_score(y_true_window, y_pred_window, pos_label='anomaly'),
        'recall': recall_score(y_true_window, y_pred_window, pos_label='anomaly'),
        'f1': f1_score(y_true_window, y_pred_window, pos_label='anomaly')
    }
4.2 Trade-offs Between Latency and Accuracy
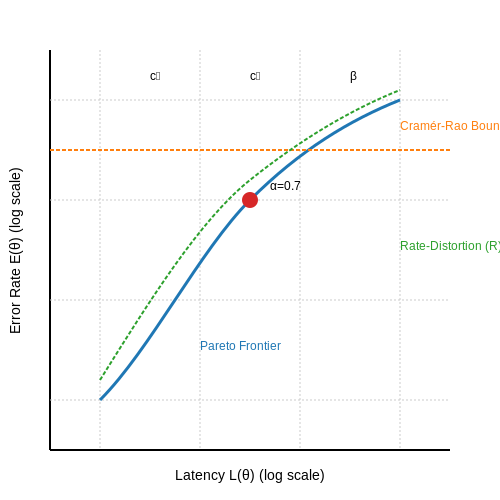
In streaming anomaly detection, the relationship between latency and accuracy is governed by fundamental constraints in computation, data availability, and model complexity. Lower latency often necessitates approximations that degrade accuracy, while higher accuracy demands more computational time, increasing latency. This trade-off is formalized through the Cramér-Rao bound in statistical estimation and the PAC learning framework in computational learning theory.
Mathematical Formalization
The trade-off can be quantified using the following optimization problem, where we minimize a weighted sum of latency (L) and error (E):
Here, θ represents the model parameters, and α ∈ [0,1] controls the relative importance of latency versus accuracy. The latency term L(θ) typically scales with model complexity, such as the number of layers in a neural network or the window size in a sliding-window detector:
where c0 represents fixed overhead and c1 the per-parameter computation cost. The error term E(θ) often follows a power-law relationship with model complexity:
with β typically between 0.5 and 2 for most anomaly detection models.
Practical Implications
Three key strategies emerge for managing this trade-off:
- Approximate Computing: Techniques like quantization, pruning, or sketching reduce model complexity at the cost of minor accuracy degradation. For example, a quantized Isolation Forest may process data 3× faster with only a 5% drop in AUC.
- Adaptive Windowing: Dynamic adjustment of the observation window based on data velocity. The ADWIN algorithm maintains O(log t) latency while providing theoretical guarantees on detection delay.
- Ensemble Methods: Parallel execution of models with varying complexity allows trading off latency and accuracy at runtime. A fast-but-simple model (e.g., z-score detector) handles most cases, while a slower complex model (e.g., LSTM autoencoder) verifies uncertain predictions.
Case Study: Network Intrusion Detection
In Cisco's implementation of streaming anomaly detection for network security, the optimal operating point was found at α = 0.7, prioritizing low latency (50ms threshold) while maintaining 92% detection accuracy. This was achieved through:
- Hardware-optimized feature extraction (reducing c0 by 60%)
- Mixed-precision neural networks (reducing c1 by 4×)
- Early-exit mechanisms that terminate computation once confidence exceeds 99%
Theoretical Limits
The rate-distortion theory of streaming systems establishes a fundamental bound on achievable accuracy for a given latency budget. For a stationary data stream with entropy rate H, the minimum achievable anomaly detection error Emin at latency L satisfies:
where R is the channel capacity between the data source and detector. This explains why high-velocity streams (large H) require proportionally more resources (higher R or L) to maintain detection accuracy.
4.3 Benchmarking Against Static Datasets
Evaluating online anomaly detection algorithms against static datasets provides a controlled environment to measure performance before deployment in streaming scenarios. While static benchmarks lack temporal dynamics, they offer reproducible ground truth for comparing detection accuracy, false positive rates, and computational efficiency.
Dataset Selection Criteria
Effective benchmarking requires datasets with:
- Labeled anomalies for precision/recall calculations
- Diverse feature distributions (multimodal, non-Gaussian)
- Controlled anomaly ratios (typically 1-15%)
- Documented preprocessing to ensure comparability
Common choices include the NAB dataset (real-world metrics), KDD Cup 99 (network intrusion), and MIT-BIH Arrhythmia (medical signals). Synthetic datasets like Mulcross allow parameterized difficulty tuning.
Performance Metrics
For binary anomaly labels, use:
For unsupervised methods, the Area Under the Precision-Recall Curve (AUPRC) better handles class imbalance. Computational metrics should include:
- Latency per data point (μs)
- Memory footprint growth rate
Cross-Validation Strategy
Time-series data requires blocked splits to prevent leakage:
Use TimeSeriesSplit from scikit-learn with 5-10 folds. For concept drift simulation, artificially inject distribution shifts between folds.
Baseline Comparison
Essential baselines include:
- Isolation Forest (non-parametric)
- One-Class SVM (kernel-based)
- LOF (density-based)
Advanced comparisons should incorporate state-of-the-art methods like Deep SVDD or GAN-based detectors. Report statistical significance using paired t-tests or Wilcoxon signed-rank tests.
Practical Considerations
Static benchmarks often overestimate real-world performance due to:
- Absence of temporal correlation
- Perfect feature engineering
- Fixed anomaly definitions
Mitigate this by adding noise perturbations (5-20% Gaussian noise) and evaluating incremental training modes where the model updates parameters during testing.
5. Key Research Papers and Foundational Works
5.1 Key Research Papers and Foundational Works
- PDF Online FDR Controlled Anomaly Detection for Streaming Time Series — There are numerous research in time-series anomaly detection, dating back to [16]. A lot of them has been done in various do- ... most anomaly detection problems in real time streaming data. The seminal work by [34] propose the adaptive z-procedure, ... natural solution for real time anomaly detection. This online streaming setting imposes two ...
- Unsupervised Anomaly Detection in Stream Data with Online Evolving ... — The OeSNN-UAD anomaly detector works in two phases: in the anomaly detection phase and in the learning phase, which are performed for each input value x t of the data stream: 1. In the anomaly detection phase, window W is updated with value x t and GRFs of input neurons are initialized.
- Anomaly detection in streaming data: A comparison and ... - ScienceDirect — Streaming data (aka data streams) refers to the technological challenge in which data are acquired and must be analyzed continuously, resulting in a potentially unlimited and constantly growing dataset (Ramírez-Gallego, Krawczyk, García, Wosfxniak, & Herrera, 2017).Data streams are closely related to multivariate time series, although the latter usually exhibit a stronger time dependence and ...
- Anomaly Detection in Online Data Streams Using Deep Belief ... - Springer — Exploration of the satisfied framework in the unprocessed data is very difficult, as the anomaly occurs rarely in the streaming data [19, 20]. Hence, in this research, the anomaly streaming data are detected by using DBN. The Kafka architecture is utilized to handle the issues related to the high-dimensional data process.
- (PDF) Online Time-series Anomaly Detection: A Survey of ... - ResearchGate — Online anomaly detection, also known as anomaly detection in streaming data, is defined as the process of detecting anomalies within data as it arrives, meaning that only information up to the ...
- Bayes-Optimized Adaptive Growing Neural Gas Method for Online Anomaly ... — Online anomaly detection is critical for industrial safety and security monitoring but is facing challenges due to the complexity of evolving data streams from working conditions and performance degradation. Unfortunately, existing approaches fall short of such challenges, and these models may be disabled, suffering from the evolving data distribution. The paper presents a framework for online ...
- PDF Unsupervised real-time anomaly detection on streaming data for ... - DiVA — The key words in the research question that should be emphasised and targeted in the experiments are seen below, their corresponding interpretations can be found in the footnotes. • fast1 • accurately predict anomalies2 • streaming time series data3 The choice of this research question makes it crucial to evaluate the perfor-
- Scalable and accurate online multivariate anomaly detection — Based on data-window processing [27] and inspired by edge computing solutions such as federated learning [28], [29], 2OD enables the analysis of the efficiency-accuracy trade-off of adopting a distributed online anomaly detection approach, especially for multivariate time series anomaly detection methods. It is applicable to most methods ...
- Review of Anomaly Detection Algorithms for Data Streams - MDPI — With the rapid development of emerging technologies such as self-media, the Internet of Things, and cloud computing, massive data applications are crossing the threshold of the era of real-time analysis and value realization, which makes data streams ubiquitous in all kinds of industries. Therefore, detecting anomalies in such data streams could be very important and full of challenges. For ...
- (PDF) Streaming Anomaly Detection - ResearchGate — makes the problem of streaming anomaly detection more challenging. W e first propose Midas which detects anomalous edges in dynamic graphs in an online manner, using constant time and memory .
5.2 Open-Source Libraries and Tools
- PDF Anomaly detection in streaming data: A comparison and evaluation study — for further discussion of anomaly detection in streaming data. To date, and to the best of our knowledge, perhaps the most relevant comparison of anomaly detection in streaming data is the work byTran, Fan, and Shahabi(2016). Here, the authors focus on k-NN-based al-gorithms and compare them in terms of CPU time and peak memory consumption.
- Revisiting Streaming Anomaly Detection: Benchmark and Evaluation — The anomaly score of a data point is its path length in the random tree, a shorter path length indicates a higher probability of being an outlier. iForest is the basic anomaly detector used in tree-based streaming anomaly detection algorithms IDForest [xiang2022edge] and iForestASD [ding2013anomaly]. However, iForest is not suitable for high ...
- Scalable and accurate online multivariate anomaly detection — In contrast, RCAD employs a real-time collaborative anomaly detection system for network data, utilizing Hierarchical Temporal Memory (HTM) for unsupervised detection. PMUNET [50] is a novel device-level deep learning-based data-driven approach for online anomaly detection, localization, and classification of multivariate streaming data. It ...
- Anomaly detection in streaming data: A comparison and ... - ScienceDirect — Streaming data (aka data streams) refers to the technological challenge in which data are acquired and must be analyzed continuously, resulting in a potentially unlimited and constantly growing dataset (Ramírez-Gallego, Krawczyk, García, Wosfxniak, & Herrera, 2017).Data streams are closely related to multivariate time series, although the latter usually exhibit a stronger time dependence and ...
- Anomaly Detection in Online Data Streams Using Deep Belief ... - Springer — Exploration of the satisfied framework in the unprocessed data is very difficult, as the anomaly occurs rarely in the streaming data [19, 20]. Hence, in this research, the anomaly streaming data are detected by using DBN. The Kafka architecture is utilized to handle the issues related to the high-dimensional data process.
- Online Anomaly Detection System for Mobile Networks — A Streaming Data Anomaly Detection Analytic Engine for Mobile Network Management; Proceedings of the 2016 Intl IEEE Conferences on Ubiquitous Intelligence Computing, Advanced and Trusted Computing, Scalable Computing and Communications, Cloud and Big Data Computing, Internet of People, and Smart World Congress; Toulouse, France. 18-21 July ...
- Online model-based anomaly detection in multivariate time series ... — Based on these key focus points, the survey is structured as follows: first, a novel taxonomy (Section 2) is defined, including anomaly types, approaches to anomaly detection and the various cases that are encompassed in the online anomaly detection domain.Then, work related to this publication (Section 3) is presented.This includes surveys that specialise in time-series anomaly detection and ...
- GitHub - yzhao062/anomaly-detection-resources: Anomaly detection ... — [Python] TODS: TODS is a full-stack automated machine learning system for outlier detection on multivariate time-series data. [Python] skyline: Skyline is a near real time anomaly detection system.[Python] banpei: Banpei is a Python package of the anomaly detection.[Python] telemanom: A framework for using LSTMs to detect anomalies in multivariate time series data.
- anomaly-detection-resources/README.rst at master - GitHub — [Python] TODS: TODS is a full-stack automated machine learning system for outlier detection on multivariate time-series data. [Python] skyline: Skyline is a near real time anomaly detection system.[Python] banpei: Banpei is a Python package of the anomaly detection.[Python] telemanom: A framework for using LSTMs to detect anomalies in multivariate time series data.
- (PDF) Streaming Anomaly Detection - ResearchGate — makes the problem of streaming anomaly detection more challenging. W e first propose Midas which detects anomalous edges in dynamic graphs in an online manner, using constant time and memory .
5.3 Recommended Books and Online Courses
- Online Unsupervised Anomaly Detection in Stream Data with Spiking ... — Unsupervised anomaly discovery in stream data is a challenging task, as it involves detecting unusual patterns in data that is constantly evolving over time. Online data-stream outlier detection can indeed be more difficult and challenging.
- Unsupervised Anomaly Detection in Stream Data with Online Evolving ... — Unsupervised anomaly discovery in stream data is a research topic with many practical applications. However, in many cases, it is not easy to collect enough training data with labeled anomalies for supervised learning of an anomaly detector in order to deploy it later for identification of real anomalies in streaming data.
- Unsupervised anomaly detection in multivariate time series with online ... — With the increasing demand for digital products, processes and services the research area of automatic detection of signal outliers in streaming data has gained a lot of attention. The range of possible applications for this kind of algorithms is versatile and ranges from the monitoring of digital machinery and predictive maintenance up to applications in analyzing big data healthcare sensor ...
- Online model-based anomaly detection in multivariate time series ... — This includes surveys that specialise in time-series anomaly detection and feature, at least partially, content on online detection or detection in streaming data.
- Anomaly Detection in Online Data Streams Using Deep Belief Neural ... — This section elucidates the issues experienced in the anomaly detection techniques. Some of the existing machine learning that depended on anomaly detection techniques requires the proper training to recognize the anomalies in the streaming workloads. The training of the high dimensional data consumes more time and causes a delay in the network. A popular streaming system such as Apache spark ...
- Anomaly detection in streaming data: A comparison and evaluation study — In most applied cases, such factors can be inferred in advance through the use of historical data and domain knowledge. Assuming the viability of the studied methods in terms of time efficiency, this work discloses key findings to achieve optimal designs of streaming data anomaly detection in real-life applications.
- PDF DETECTION AND CHANGE-POINT DETECTION - University of Manchester — dentify and tell what an anomaly is. The anomalies detection in real-time streaming data has significant and practical across many industries such as fault detection, preventative maintenance, fraud prevention, security, IT, medical, e-commerce, a
- (PDF) Online Time-series Anomaly Detection: A Survey of ... - ResearchGate — This survey provides an extensive overview of the state-of-the-art model-based online semi-supervised and unsupervised anomaly detection algorithms used on multivariate time series.
- Bayes-Optimized Adaptive Growing Neural Gas Method for Online Anomaly ... — The paper presents a framework for online anomaly detection of data streams, of which the baseline algorithm is the incremental learning method of Growing Neural Gas (GNG).
- (PDF) Streaming Anomaly Detection - ResearchGate — PDF | Anomaly detection is critical for finding suspicious behavior in innumerable systems. We need to detect anomalies in real-time, i.e. determine if... | Find, read and cite all the research ...