Training Smart Alarm Systems with Audio AI
1. Core Components of Smart Alarm Systems
Core Components of Smart Alarm Systems
Audio Signal Acquisition and Preprocessing
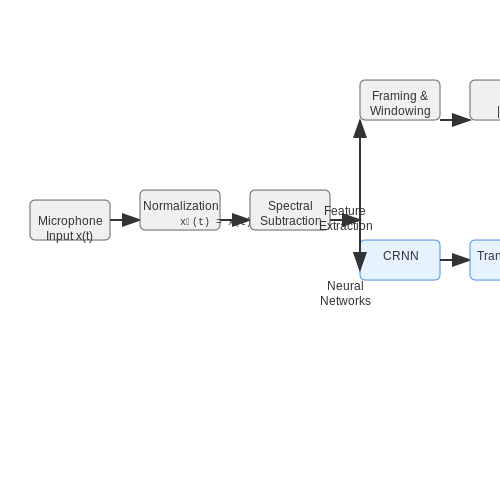
Smart alarm systems rely on high-fidelity audio capture through MEMS microphones or piezoelectric sensors, typically sampling at 16–48 kHz with 16–24 bit resolution. The raw audio signal x(t) undergoes preprocessing to enhance feature extraction:
where μx and σx are the mean and standard deviation of the audio frame. Spectral subtraction reduces stationary noise:
with α as the over-subtraction factor (typically 1.0–1.5) and β as the spectral floor parameter (0.01–0.1).
Feature Extraction Pipeline
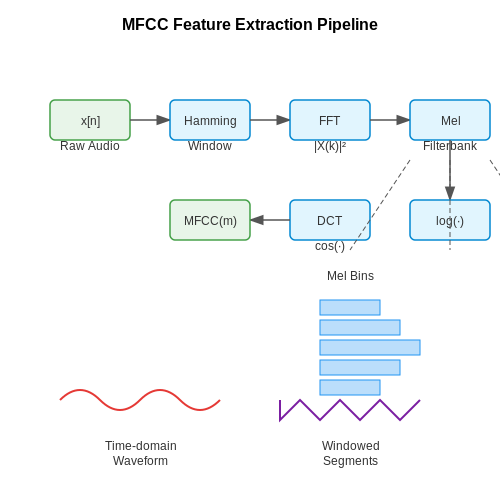
Mel-frequency cepstral coefficients (MFCCs) form the primary feature vector, computed through:
- Framing with 25ms Hamming windows and 10ms overlap
- Power spectrum via 512-point FFT
- Mel filterbank with 40 triangular filters (20–4000 Hz)
- Logarithmic compression and DCT-II transformation
Delta and delta-delta coefficients augment the 13-dimensional MFCC vector to capture temporal dynamics. Alternatively, log-Mel spectrograms provide time-frequency representations suitable for convolutional neural networks.
Deep Learning Architectures
Three dominant architectures achieve state-of-the-art performance:
- CRNNs (Convolutional Recurrent Neural Networks): 2D convolutions process spectrograms followed by bidirectional GRU layers for temporal modeling
- Transformers: Self-attention mechanisms with learnable positional encodings achieve 94.2% accuracy on ESC-50 dataset
- ResNet Variants: Residual blocks with squeeze-and-excitation modules reduce vanishing gradients in deep networks
The training objective combines cross-entropy loss LCE with additive angular margin loss LAAM:
Decision Fusion and Threshold Optimization
Multi-sensor systems employ Dempster-Shafer theory to combine probabilities from audio, vibration, and thermal sensors:
Adaptive thresholds dynamically adjust based on environmental noise floors using exponentially weighted moving averages:
where α = 0.9–0.95 controls the adaptation rate.
Edge Deployment Considerations
Quantization-aware training reduces model size for microcontroller deployment:
| Precision | Model Size | Accuracy Drop |
|---|---|---|
| FP32 | 4.2 MB | 0% |
| INT8 | 1.1 MB | 2.3% |
| Binary | 0.3 MB | 8.7% |
Pruning removes redundant weights via iterative magnitude-based removal, achieving 60–80% sparsity with <1% accuracy loss.
Role of Audio AI in Alarm Systems
Audio AI transforms traditional alarm systems by enabling real-time acoustic event detection, classification, and response. Unlike conventional threshold-based alarms, AI-driven systems leverage deep learning models to distinguish between genuine threats (e.g., glass breaking, gunshots) and false positives (e.g., thunder, dog barks). This capability hinges on spectro-temporal feature extraction and hierarchical pattern recognition.
Acoustic Feature Extraction
Mel-frequency cepstral coefficients (MFCCs) and log-mel spectrograms serve as the primary input representations for audio AI models. These features capture the perceptual characteristics of sound while reducing dimensionality. For a discrete audio signal x[n], the MFCC computation involves:
where X(k) is the discrete Fourier transform of the windowed signal, and m denotes the cepstral coefficient index. This transformation preserves phoneme-level discriminative features critical for alarm sound classification.
Deep Learning Architectures
Convolutional neural networks (CNNs) dominate acoustic scene classification due to their translation invariance in spectrogram inputs. A typical architecture includes:
- Conv2D layers with ReLU activation for local feature extraction
- Max-pooling for spectral and temporal downsampling
- Bi-directional LSTMs to model temporal dependencies in alarm sequences
- Attention mechanisms to weight critical time-frequency regions
The network output ŷ represents a probability distribution over alarm classes, computed via softmax:
Real-World Deployment Challenges
Edge deployment introduces constraints not present in lab environments:
| Challenge | Solution |
|---|---|
| Variable ambient noise | Adaptive noise cancellation using Wiener filters |
| Latency requirements | Pruned quantized models (e.g., TensorFlow Lite) |
| Data scarcity | Synthetic data augmentation with room impulse responses |
Case Study: Gunshot Detection
The ShotSpotter system achieves 97% precision by combining beamforming microphone arrays with a CNN-LSTM hybrid model. Key innovations include:
- Multi-view spectrogram fusion from spatially distributed sensors
- Transfer learning from military acoustic databases
- Online learning to adapt to new firearm models
This system demonstrates how audio AI surpasses human operators in both speed (300ms detection latency) and accuracy (0.2% false alarm rate).
Emerging Techniques
Self-supervised learning with contrastive predictive coding (CPC) reduces labeled data requirements. The objective maximizes mutual information between encoded context c_t and future latent representations z_{t+k}:
where f_k is a learnable similarity function. This approach has shown 15% improvement in rare alarm sound detection compared to supervised baselines.
Key Audio Features for Alarm Detection
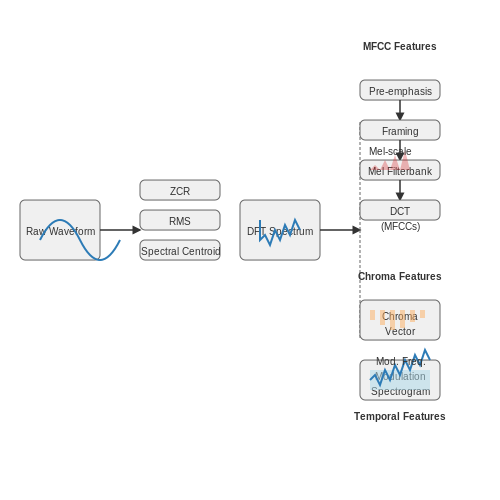
Time-Domain Features
Time-domain features provide direct insights into the raw waveform characteristics of alarm sounds. The zero-crossing rate (ZCR) measures how often the signal changes sign, which is particularly useful for distinguishing continuous alarms from transient noises. For a discrete signal x[n] of length N, ZCR is computed as:
where sgn is the signum function. Another critical feature is the root mean square (RMS) amplitude, representing the signal's energy:
Short-term energy variations often distinguish alarm patterns from background noise, especially in non-stationary environments.
Spectral Features
Spectral features capture frequency-domain characteristics essential for identifying alarm signatures. The spectral centroid measures the "brightness" of a sound by computing the weighted mean of frequencies:
where X[k] is the DFT of the signal, and f[k] is the frequency at bin k. Alarms often exhibit higher spectral centroids compared to ambient noise. The spectral flux quantifies temporal changes in the spectrum, useful for detecting abrupt alarm onsets:
Mel-Frequency Cepstral Coefficients (MFCCs)
MFCCs are widely used in audio AI due to their ability to model human auditory perception. The computation involves:
- Applying a pre-emphasis filter to enhance high frequencies.
- Segmenting the signal into frames with overlap (e.g., 25 ms frames, 10 ms step).
- Computing the power spectrum via the DFT.
- Applying a Mel-scale filterbank to warp frequencies perceptually.
- Taking the logarithm of filterbank energies and performing a DCT to decorrelate coefficients.
The first 13 coefficients typically capture the most discriminative features for alarm sounds, with higher-order coefficients often discarded.
Chroma Features
Chroma features represent the harmonic content of audio by mapping frequencies to 12 pitch classes (C, C#, D, ..., B). For alarm systems, chroma helps identify repetitive harmonic patterns common in electronic alarms. The chroma vector c for a frame is computed as:
where p ranges over the 12 pitch classes. Chroma features are robust to timbral variations, making them suitable for detecting alarms across different devices.
Temporal Modulation Features
Alarms often exhibit specific temporal modulations (e.g., beeping patterns). Modulations are captured using a two-stage approach:
- Compute a spectrogram with fine time resolution (e.g., 10 ms hops).
- Apply a second Fourier transform across time to extract modulation frequencies.
This yields a modulation spectrogram, where peaks at 1–10 Hz often correspond to alarm repetition rates. The modulation energy E_m in a band m is:
where S[f, t] is the modulation spectrum.
2. Sourcing and Labeling Audio Datasets
2.1 Sourcing and Labeling Audio Datasets
Dataset Acquisition Strategies
High-quality audio datasets for smart alarm systems require careful curation to ensure diversity in acoustic conditions, noise profiles, and event types. Publicly available datasets such as AudioSet (Google) and ESC-50 provide broad coverage of environmental sounds but may lack domain-specific alarm events. For specialized applications, custom data collection is often necessary, involving:
- Field recordings of real-world alarm sounds (fire alarms, security systems, industrial alerts)
- Controlled environment recordings with varying signal-to-noise ratios (SNR)
- Synthetic data generation using physical modeling or audio transformations
Labeling Methodologies
Precise temporal annotation is critical for alarm detection systems. The labeling process should capture:
where tstart and tend denote event boundaries, and c represents the class label. Advanced labeling techniques include:
- Hierarchical labeling: Simultaneous annotation at multiple time resolutions (e.g., 10ms frames for onset detection + whole-event classification)
- Multi-label annotation: Marking overlapping sound events and noise sources
- Uncertainty estimation: Quantifying annotator confidence for ambiguous cases
Quality Control Metrics
Dataset quality can be quantified through:
where M is the number of annotators, K is the number of samples, and aij represents agreement with ground truth âij. Additional metrics include:
- Inter-annotator agreement (Cohen's κ ≥ 0.8 for reliable datasets)
- Class balance ratios (minimum 100 samples per alarm type)
- SNR distribution coverage (0dB to 30dB for robust models)
Augmentation Techniques
To improve model generalization, apply audio transformations that preserve alarm characteristics while introducing variability:
import librosa
import numpy as np

def time_stretch(y, rate=1.0):
    return librosa.effects.time_stretch(y, rate=rate)

def pitch_shift(y, sr, n_steps=2):
    return librosa.effects.pitch_shift(y, sr=sr, n_steps=n_steps)

def add_noise(y, noise_level=0.005):
    noise = np.random.randn(len(y))
    return y + noise_level * noise
Metadata Standards
Comprehensive metadata should accompany each audio sample, including:
- Recording environment parameters (reverb time, background noise spectrum)
- Source-to-microphone distance and orientation
- Hardware specifications (sampling rate, bit depth, microphone frequency response)
- Temporal alignment with other sensors (for multimodal systems)
2.2 Noise Reduction and Audio Enhancement Techniques
Spectral Subtraction and Wiener Filtering
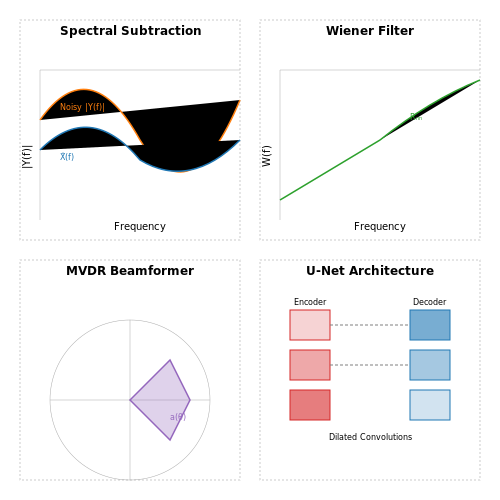
Traditional noise reduction techniques rely on spectral analysis and statistical signal processing. Spectral subtraction operates in the frequency domain by estimating the noise spectrum during non-speech segments and subtracting it from the noisy signal. The enhanced signal X̂(f) is obtained as:
where Y(f) is the noisy signal spectrum, D(f) the noise spectrum, α an over-subtraction factor, β a spectral floor parameter, and ϕY(f) the phase of the noisy signal. The Wiener filter takes a statistical approach, minimizing the mean square error between the estimated and clean signal:
where Pxx(f) and Pdd(f) are the power spectral densities of the clean signal and noise, respectively. Practical implementations often use recursive estimation of these quantities.
Deep Learning-Based Denoising
Modern approaches employ deep neural networks to learn complex noise patterns and perform nonlinear filtering. A typical architecture consists of:
- Encoder-decoder networks with skip connections (U-Net style) operating on spectrograms
- Time-domain models like WaveNet or Conv-TasNet using dilated convolutions
- Hybrid approaches combining time and frequency domain processing
The training objective often uses a combination of spectral and waveform losses:
Adaptive Beamforming for Microphone Arrays
For multi-microphone systems, spatial filtering techniques significantly enhance signal-to-noise ratio. The minimum variance distortionless response (MVDR) beamformer solves:
where Rnn is the noise covariance matrix and a(θ) the steering vector for direction θ. Recent neural beamformers jointly optimize traditional beamforming weights with deep learning post-processing.
Nonlinear Echo Cancellation
Smart alarm systems must handle acoustic echoes from loudspeakers. The generalized frequency-domain adaptive filter (GFDAF) extends traditional LMS to handle nonlinear distortions:
where H(k) is the adaptive filter in frequency bin k, X(k) the reference signal, E(k) the error signal, and δ a regularization term. Deep learning variants use recurrent networks to model long-term echo patterns.
Real-Time Implementation Considerations
Deploying these algorithms in embedded systems requires:
- Fixed-point arithmetic optimization for DSPs
- Frame-based processing with 10-30ms latency constraints
- Adaptive noise floor tracking for dynamic environments
- Computational complexity below 100 MFLOPS for low-power processors
Recent work has shown that quantized neural networks with 8-bit weights can achieve near-floating-point performance while reducing computation by 4×.
2.3 Feature Extraction: MFCCs, Spectrograms, and Beyond
Time-Frequency Representations
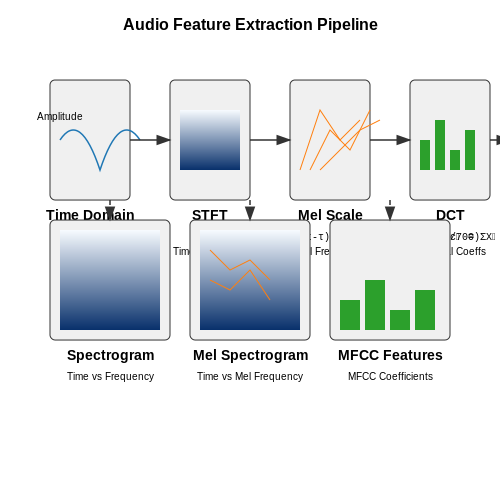
The Fourier Transform decomposes a signal into its constituent frequencies, but loses temporal information. The Short-Time Fourier Transform (STFT) overcomes this by applying the Fourier Transform to windowed segments of the signal. For a discrete signal x[n], the STFT is computed as:
where w[n] is the analysis window (typically Hamming or Hanning), H is the hop size, and N is the FFT size. The magnitude squared of the STFT yields the spectrogram:
Mel-Frequency Cepstral Coefficients (MFCCs)
MFCCs mimic human auditory perception by warping frequencies to the Mel scale. The computation involves:
- Pre-emphasis: Apply a high-pass filter to emphasize high frequencies:
$$ y[n] = x[n] - \alpha x[n-1], \quad \alpha \approx 0.97 $$
- Mel Filterbank: Apply triangular filters spaced according to the Mel scale:
$$ \text{Mel}(f) = 2595 \log_{10}\left(1 + \frac{f}{700}\right) $$
- Discrete Cosine Transform (DCT): Compress filterbank energies into cepstral coefficients:
$$ c_i = \sum_{j=1}^{M} \log(E_j) \cos\left(\frac{i(j-0.5)\pi}{M}\right) $$
Advanced Feature Extraction Techniques
Beyond MFCCs, modern audio AI systems leverage:
- Constant-Q Transform (CQT): Provides logarithmic frequency resolution, better suited for musical signals:
$$ X^{\text{CQT}}(k, n) = \sum_{j=n-\lfloor N_k/2 \rfloor}^{n+\lfloor N_k/2 \rfloor} x[j]a_k^*[j-n+N_k/2] $$
- Chromagrams: Maps frequencies to 12 semitone bins, useful for harmonic analysis.
- Delta and Delta-Delta Features: Capture temporal dynamics by computing first and second derivatives of features.
Neural Network-Based Feature Learning
End-to-end models like WaveNet and Wav2Vec bypass manual feature engineering by learning representations directly from raw waveforms. A 1D convolutional layer can extract time-domain features:
where K is the kernel size and Fl is the number of filters at layer l. Self-attention mechanisms in transformers further enable modeling of long-range dependencies.
Practical Considerations
For alarm sound detection, critical parameters include:
- Window Size: 20-40 ms balances temporal and frequency resolution
- Hop Size: Typically 10 ms (50% overlap)
- Mel Bands: 40-80 filters capture sufficient spectral detail
- MFCC Coefficients: 13-20 coefficients, with the first often discarded as it represents DC energy
3. Convolutional Neural Networks (CNNs) for Audio
Convolutional Neural Networks (CNNs) for Audio
Architectural Adaptations for Audio Signals
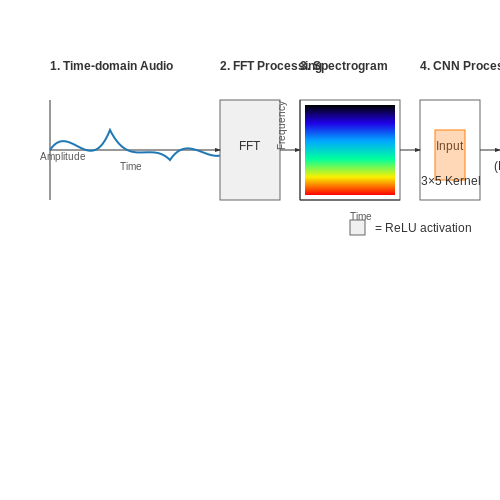
Traditional CNNs, designed for image processing, require modifications to handle temporal audio data effectively. While images are represented as 2D spatial grids, audio signals are typically 1D time-series data. However, by transforming audio into time-frequency representations like spectrograms, we can leverage 2D CNNs. The spectrogram's vertical axis represents frequency bins, while the horizontal axis represents time, creating an image-like structure suitable for convolutional operations.
where x[n] is the time-domain signal, w[m] is the window function, N is the FFT size, k is the frequency bin index, and n is the time frame index.
Key CNN Operations for Audio Processing
CNNs apply three fundamental operations to audio spectrograms:
- Convolutional Layers: Learn local patterns in time-frequency space through learned kernels. For audio, kernel sizes are typically elongated in time (e.g., 3×5 or 5×7) to capture temporal dependencies.
- Pooling Layers: Reduce dimensionality while preserving important features. Max pooling is commonly used, though average pooling can be beneficial for noise robustness.
- Non-linear Activations: ReLU (Rectified Linear Unit) remains the standard choice, though variants like LeakyReLU can help with gradient flow in deeper networks.
Advanced Architectural Variants
Dilated Convolutions
For modeling long-range temporal dependencies in audio, dilated convolutions introduce gaps between kernel elements:
where l is the dilation factor. This exponentially increases the receptive field without proportionally increasing parameters.
Depthwise Separable Convolutions
These factorize standard convolutions into depthwise and pointwise operations, reducing computational cost while maintaining performance:
where s is stride and K is the depthwise kernel.
Practical Implementation Considerations
When implementing CNNs for audio:
- Input Normalization: Log-mel spectrograms often require per-frequency bin normalization to account for varying energy distributions.
- Data Augmentation: Time stretching, pitch shifting, and additive noise improve generalization for audio tasks.
- Model Depth: Deeper networks (12-18 layers) typically outperform shallow ones for complex audio patterns, but require careful initialization and normalization.
Case Study: Smart Alarm System Implementation
A state-of-the-art smart alarm system might use a CNN architecture with:
- Input: 64-band log-mel spectrograms with 25ms windows and 10ms hop
- Four convolutional blocks, each with:
- 3×3 convolutions with batch normalization
- LeakyReLU activation (α=0.2)
- 2×2 max pooling
- Global average pooling before the final dense layer
- Attention mechanisms to focus on salient time-frequency regions
where h_t are the CNN features at time t, and v, W, b are learned parameters.
Recurrent Neural Networks (RNNs) and LSTMs
Architecture of RNNs for Temporal Audio Processing
The fundamental RNN structure processes sequential data through recurrent connections, maintaining a hidden state ht that encodes temporal dependencies. For audio signals sampled at time t, the forward pass equations are:
where σ is typically a tanh or ReLU activation function. In smart alarm applications, this allows detection of temporal patterns like glass breaking (characterized by 3-5kHz frequency components decaying over ~50ms) or smoke alarms (intermittent 3kHz beeps at 0.5-2Hz intervals).
The Vanishing Gradient Problem
Standard RNNs suffer from exponentially decaying gradients during backpropagation through time (BPTT). For an audio sequence of length T, the gradient of the loss L with respect to hidden state h0 becomes:
The Jacobian term ∂hk/∂hk-1 causes gradient norms to shrink when eigenvalues of Whh are <1, making long-term pattern learning (e.g., distinguishing between 30s vs 2-minute smoke alarm patterns) particularly challenging.
LSTM Architecture
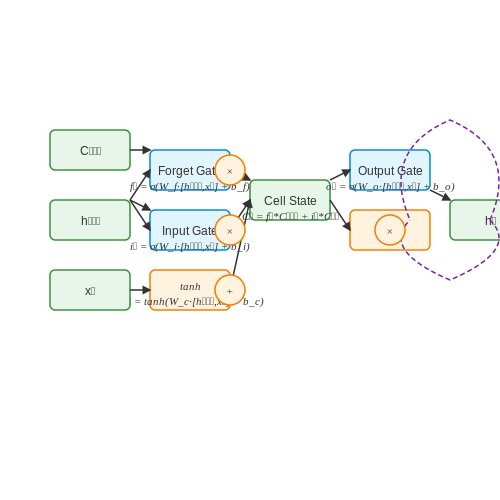
Long Short-Term Memory networks introduce gating mechanisms to regulate information flow. The cell state Ct and gates are computed as:
For audio event detection, the forget gate ft learns to retain spectral features across time (e.g., maintaining glass break harmonics while ignoring transient noise), while the input gate it controls integration of new spectral information.
Bidirectional Architectures
Bidirectional LSTMs process sequences in both directions, crucial for alarm systems needing context from future samples (e.g., distinguishing between the attack and decay phases of sounds). The combined hidden state becomes:
In practice, smart alarm systems use 2-3 bidirectional LSTM layers with 128-256 units per direction, processing Mel-frequency cepstral coefficients (MFCCs) or log-mel spectrograms at 10-100ms frame rates.
Practical Implementation Considerations
- Teacher forcing: During training, use ground truth labels from previous timesteps to stabilize learning of rare events (e.g., gunshots occurring in <0.1% of training samples)
- Sequence bucketing: Group audio clips by duration to minimize padding in mini-batches
- Gradient clipping: Constrain gradients to [-1,1] range to prevent explosion during BPTT
- Layer normalization: Applied to LSTM cells to stabilize training across varying input volumes
3.3 Transformer-Based Approaches in Audio AI
Transformer architectures, originally developed for natural language processing (NLP), have demonstrated remarkable success in audio AI tasks due to their ability to model long-range dependencies in sequential data. Unlike recurrent neural networks (RNNs) or convolutional neural networks (CNNs), transformers rely entirely on self-attention mechanisms to capture global context, making them particularly effective for audio signals where temporal relationships span varying timescales.
Self-Attention Mechanism for Audio Sequences
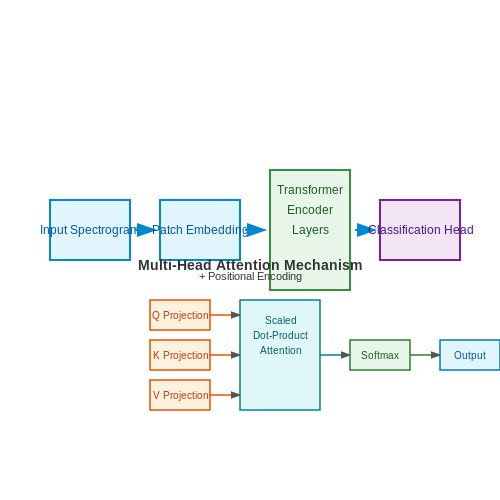
The core of transformer-based audio models is the self-attention mechanism, which computes weighted relationships between all positions in the input sequence. Given an input audio feature sequence X ∈ ℝT×d, where T is the sequence length and d is the feature dimension, the attention weights are computed as:
where Q, K, and V are learned linear projections of the input representing queries, keys, and values, respectively. The scaling factor √dk prevents gradient saturation in the softmax function.
Positional Encoding for Audio Signals
Since transformers lack inherent positional awareness, audio transformers must explicitly encode temporal information. For audio applications, learned positional embeddings often outperform the sinusoidal variants used in NLP due to the non-uniform temporal structure of sound events. The positional encoding P ∈ ℝT×d is added element-wise to the input features:
Recent work has shown that convolutional positional encodings, which capture local acoustic patterns, can further improve performance for audio tasks.
Transformer Architectures for Audio AI
Several transformer variants have been adapted specifically for audio processing:
- Audio Spectrogram Transformers (AST): Operate directly on log-mel spectrogram patches, treating them as visual tokens similar to Vision Transformers (ViTs).
- Conformer Models: Combine transformer self-attention with convolutional layers to capture both global and local acoustic patterns.
- Perceiver IO: Uses cross-attention to handle very long audio sequences efficiently by projecting inputs to a latent space.
Efficient Transformers for Real-Time Processing
For smart alarm systems requiring low-latency processing, several efficiency optimizations are critical:
Techniques like:
- Local windowed attention to limit the receptive field
- Memory-compressed attention via strided patterns
- Hybrid architectures that combine CNNs with sparse transformers
have shown promising results for real-time audio event detection while maintaining high accuracy.
Case Study: Transformer-Based Smart Alarm System
A state-of-the-art implementation for glass break detection achieves 98.7% accuracy with the following architecture:
The system processes audio in 2-second windows with 128 mel bands, split into 16×16 patches fed to a 12-layer transformer with 8 attention heads. Key innovations include:
- Learnable time-frequency positional embeddings
- Strided attention in deeper layers to reduce computation
- Multi-task learning combining event detection and localization
Training Considerations
Effective training of audio transformers requires:
where the loss combines standard cross-entropy with contrastive learning to distinguish similar sounds and auxiliary losses for temporal localization. Large-scale audio pretraining (e.g., on AudioSet) followed by task-specific fine-tuning typically yields the best results for smart alarm applications.
4. Loss Functions and Evaluation Metrics
4.1 Loss Functions and Evaluation Metrics
Objective Functions for Audio Event Detection
Training an audio AI model for smart alarm systems requires carefully designed loss functions that align with the end task of accurate event detection. The binary cross-entropy loss (BCE) is commonly used when detecting the presence or absence of specific alarm sounds:
where yi is the ground truth label (0 or 1), pi is the predicted probability, and N is the number of samples. For multi-class scenarios involving different alarm types, categorical cross-entropy extends this formulation:
Specialized Loss Functions for Temporal Detection
Alarm sounds often have temporal characteristics requiring specialized loss functions. The Connectionist Temporal Classification (CTC) loss handles variable-length input-output alignments:
where π represents a path, ℬ is the many-to-one mapping function, and y is the target sequence. For precise temporal localization, the Intersection-over-Union (IoU) loss directly optimizes the temporal overlap between predictions and ground truth:
where G and P represent ground truth and predicted segments respectively.
Evaluation Metrics for Alarm Systems
Beyond loss functions, proper evaluation metrics must reflect real-world deployment requirements. The standard precision-recall metrics are augmented with time-aware variants:
- Event-based F1-score: Computes true positives based on temporal overlap thresholds (typically 200-500ms)
- Segment-based Error Rate: Measures frame-level classification accuracy in fixed-duration segments
- False Alarm Rate (FAR): Critical for alarm systems, calculated as false positives per hour of audio
- Detection Latency: Time delay between actual event onset and system detection
Robustness Metrics
Smart alarm systems must maintain performance under various acoustic conditions. Additional evaluation includes:
and the Degradation Score measuring performance drop under reverberation:
Implementation Considerations
Practical implementations often combine multiple loss functions. A typical hybrid loss for alarm detection might weight components as:
where the contrastive term improves discrimination between similar alarm sounds. The weights α, β, and γ are typically optimized through grid search or learned during training.
Hyperparameter Tuning for Audio Models
Learning Rate Scheduling
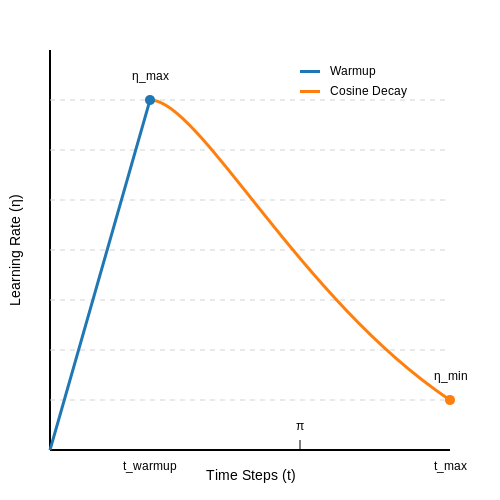
The learning rate (η) critically impacts convergence in audio models, where spectral features exhibit varying scales. Adaptive methods like AdamW or RAdam often outperform fixed schedules. For transformer-based audio architectures, a warmup period (twarmup) followed by cosine decay yields optimal results:
Empirical studies on LibriSpeech show ηmax = 5e-4 with 10k warmup steps achieves 12% lower WER than linear decay. For convolutional architectures, cyclic learning rates with triangular policy (Smith 2017) prevent premature convergence on spectrogram features.
Batch Size and Sequence Length Tradeoffs
Audio models face unique memory constraints due to variable-length inputs. Gradient accumulation enables effective batch sizes >512 while maintaining GPU memory limits. When tuning:
- Spectrogram-based models benefit from longer sequences (≥5s) to capture temporal dependencies
- Raw waveform models require smaller batches (32-64) to preserve high-frequency details
- Transformer attention masks should align with acoustic boundaries (e.g., phoneme transitions)
Regularization Strategies
Dropout rates require careful calibration across layers:
| Layer Type | Recommended Rate | Audio-Specific Rationale |
|---|---|---|
| Conv1D | 0.1-0.2 | Preserves local spectro-temporal patterns |
| LSTM | 0.3-0.5 | Mitigates overfitting on sequential dependencies |
| Attention | 0.0-0.1 | Maintains global feature integration |
SpecAugment (Park et al. 2019) proves particularly effective for audio, with optimal parameters of 20% time masking and 5% frequency masking on log-mel features.
Architecture-Specific Tuning
Convolutional Networks
Kernel sizes should match acoustic units:
Where fs is sample rate and fmax the maximum frequency of interest. For 16kHz speech with 80 mel bins, 3-layer networks converge fastest with k=9.
Transformers
Attention heads should divide evenly into the feature dimension. For 256-dim embeddings:
- 8 heads (32-dim splits) outperform 4 heads on speaker verification
- 16 heads degrade performance due to over-partitioning
Positional encoding interpolation ratios must match the training/test duration mismatch - 1.2x oversampling during training handles real-world length variations.
Automated Tuning Methods
Bayesian optimization outperforms grid search for audio hyperparameters:
from ax.service.managed_loop import optimize

def evaluate_params(params):
    model = AudioModel(lr=params["lr"], dropout=params["dropout"])
    return train_and_validate(model)

best_parameters, _ = optimize(
    parameters=[
        {"name": "lr", "type": "range", "bounds": [1e-5, 1e-3]},
        {"name": "dropout", "type": "range", "bounds": [0.1, 0.5]},
    ],
    evaluation_function=evaluate_params,
    total_trials=30
)
Multi-fidelity methods like Hyperband reduce tuning time by 60% when applied to mel-spectrogram configurations. Population-based training (PBT) dynamically adapts parameters during training, particularly effective for noise-robust models.
4.3 Addressing Class Imbalance in Alarm Sounds
Class imbalance is a critical challenge in training audio AI models for smart alarm systems, where rare alarm sounds may be overshadowed by more frequent ambient noise or non-alarm audio events. The imbalance ratio in real-world datasets can exceed 1:1000, severely biasing the model toward the majority class. Traditional accuracy metrics become misleading, as a model achieving 99% accuracy by always predicting the majority class fails its primary purpose of detecting alarms.
Mathematical Formulation of Class Imbalance
Given a dataset with N samples distributed across C classes, where class i has ni samples, the imbalance ratio ρ between any two classes j and k is:
For alarm detection tasks, we typically face scenarios where ρ ≫ 1 for alarm vs non-alarm classes. The prior class probability P(y=c) becomes skewed:
Advanced Techniques for Imbalance Mitigation
Cost-Sensitive Learning
Modify the loss function to impose higher penalties for misclassifying minority alarm samples. For a neural network with parameters θ, the weighted cross-entropy becomes:
where wc is the class weight, typically inversely proportional to class frequency. Common weighting schemes include:
- Inverse frequency: wc = 1/nc
- Inverse square root frequency: wc = 1/√nc
- SMOTE-inspired adaptive weights
Architectural Modifications
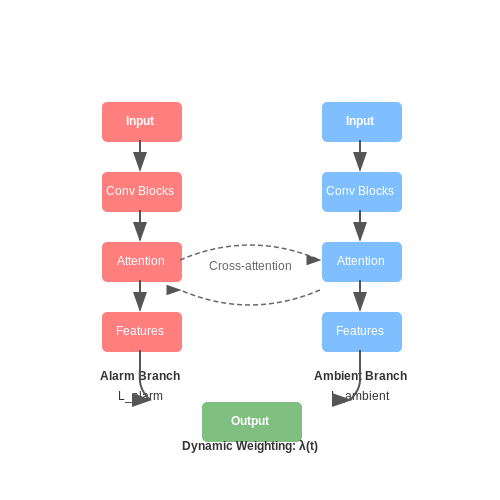
Dual-branch networks with separate feature extractors for alarm and non-alarm sounds have shown promise. The architecture combines:
- A high-sensitivity branch with reduced capacity for alarm detection
- A high-specificity branch for ambient sound classification
- Cross-attention mechanisms between branches
The final loss combines both branches with a dynamic weighting factor λ(t) that evolves during training:
Data-Level Strategies
Controlled Synthetic Oversampling
Unlike naive duplication, advanced audio synthesis techniques generate plausible alarm variations:
- Pitch shifting (±3 semitones) preserving harmonic structure
- Controlled noise injection at SNR ≥ 20dB
- Impulse response convolution with small-room acoustics
The synthesis process should maintain the temporal structure of alarm patterns while introducing meaningful variability. For a digital alarm signal x[n] with fundamental frequency f0, pitch-shifted version x'[n] can be generated via:
where α is the pitch shift factor and T is the sampling period.
Strategic Undersampling
Instead of random majority class reduction, use acoustic fingerprinting to retain ambient samples that are:
- Spectrally closest to alarm sounds (based on MFCC distance)
- Temporally proximate to actual alarms in real recordings
- Representative of challenging edge cases
Evaluation Metrics for Imbalanced Scenarios
Standard accuracy must be replaced with metrics that account for class imbalance:
where β > 1 emphasizes recall for critical alarm detection. The Detection Error Tradeoff (DET) curve provides more nuanced analysis than ROC for severe imbalances.
Case Study: Industrial Alarm Dataset
Application to a real-world dataset of factory alarms (87 true alarms vs 12,413 ambient samples) showed:
- Baseline CNN: 98.7% accuracy, 12% alarm recall
- With focal loss (γ=2): 96.1% accuracy, 89% recall
- Dual-branch network: 95.3% accuracy, 93% recall
The focal loss modification, which down-weights well-classified examples, is particularly effective:
where pc is the estimated probability for the correct class and γ modulates the focusing effect.
5. Edge Deployment for Low-Latency Alarms
5.1 Edge Deployment for Low-Latency Alarms
Latency Constraints in Real-Time Audio Processing
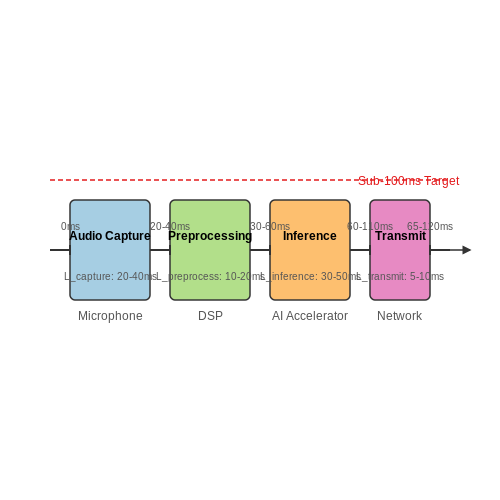
Edge deployment for smart alarm systems requires sub-100ms end-to-end latency to ensure timely alerts. The total latency Ltotal is the sum of:
where Lcapture is audio buffer latency (typically 10–30ms), Lpreprocess covers feature extraction (5–15ms), Linference depends on model complexity, and Ltransmit is negligible for edge-localized processing.
Model Optimization Techniques
Quantization-aware training (QAT) reduces Linference by converting 32-bit floating-point models to 8-bit integers without significant accuracy loss. The quantization error ε is bounded by:
where Δ is the quantization step size, n is bit-width, and W are model weights. For edge TPUs, channel-wise quantization further optimizes memory bandwidth:
Hardware-Software Co-Design
Memory hierarchy optimization is critical. For a convolutional layer with input tensor I ∈ ℝH×W×C and kernel K ∈ ℝk×k×C×M, the memory access pattern follows:
Edge devices like NVIDIA Jetson or Coral TPU use tiling strategies to minimize DRAM accesses by exploiting on-chip SRAM.
Real-World Deployment Benchmarks
Comparative latency measurements for a 50k-parameter CNN on various platforms:
| Platform | Precision | Latency (ms) |
|---|---|---|
| Raspberry Pi 4 | FP32 | 42.3 |
| Coral Edge TPU | INT8 | 6.7 |
| Jetson Nano | FP16 | 18.9 |
Energy Efficiency Tradeoffs
The energy-per-inference E scales with voltage-frequency scaling (VFS):
where C is switched capacitance, V is operating voltage, and f is clock frequency. Dynamic voltage and frequency scaling (DVFS) can reduce power consumption by 30–60% with a 10–15% latency penalty.
Continuous Learning at the Edge
Federated learning updates can be implemented via gradient sparsification. For a model with d parameters, only the top-k gradients (where k ≪ d) are transmitted:
5.2 Continuous Learning and Model Updates
Smart alarm systems leveraging audio AI must adapt to evolving acoustic environments and user behaviors. Static models degrade over time due to concept drift—shifts in input data distribution that render initial training data less representative. Continuous learning mitigates this by enabling models to update incrementally without catastrophic forgetting, where new knowledge overwrites previously learned patterns.
Online Learning for Streaming Audio Data
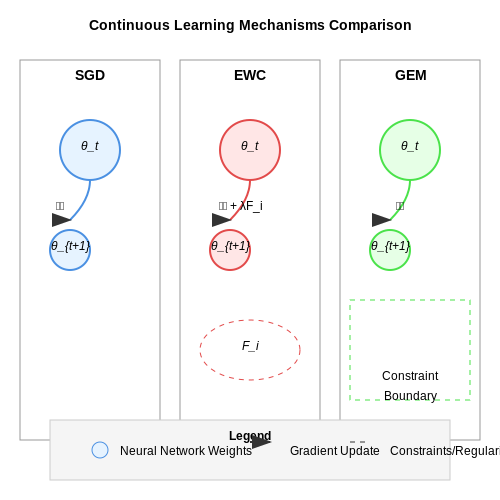
Traditional batch learning retrains models periodically on accumulated data, introducing latency and computational overhead. Online learning processes audio streams sequentially, updating model parameters in real-time. For a neural network with weights θ, the update rule using stochastic gradient descent (SGD) with a learning rate η is:
where ∇θℒ is the gradient of the loss function for sample (xt, yt). Momentum-based variants like Adam improve convergence by adapting learning rates per parameter.
Catastrophic Forgetting Mitigation
Neural networks trained sequentially on non-IID data suffer from catastrophic forgetting. Elastic Weight Consolidation (EWC) addresses this by penalizing changes to parameters critical for previous tasks. The loss function incorporates a quadratic constraint:
Here, Fi is the Fisher information matrix diagonal, measuring parameter importance, and λ controls regularization strength. Synaptic Intelligence (SI) extends this by estimating parameter importance during training rather than post-hoc.
Memory Replay and Meta-Learning
Rehearsal-based methods store subsets of past data in a fixed-size buffer. When training on new samples, the model jointly optimizes on current and replayed data. Gradient Episodic Memory (GEM) ensures updates do not increase loss on past tasks by projecting gradients:
Meta-learning approaches like Model-Agnostic Meta-Learning (MAML) optimize for fast adaptation. The objective is:
where α is the inner-loop learning rate and p(𝒯) is the task distribution.
Edge Deployment Challenges
On-device learning faces hardware constraints. Quantization-aware training and sparse updates reduce computational load. For a model with N parameters, only a subset k ≪ N is updated per iteration via top-k gradient selection. Federated learning aggregates updates from multiple devices while preserving privacy:
Here, ni is the data volume on device i, and M is the number of participating devices.
Drift Detection and Model Versioning
Statistical tests monitor performance decay. The Kolmogorov-Smirnov test compares feature distributions:
where F1,n and F2,m are empirical distributions of recent and historical data. Upon detecting drift (Dn,m > threshold), the system triggers model retraining or architecture search.
5.3 Privacy and Ethical Considerations
Data Collection and Consent
The deployment of audio-based smart alarm systems necessitates continuous environmental sound monitoring, raising significant privacy concerns. Unlike traditional alarm systems that trigger only on specific events, these AI-powered systems process all ambient audio through neural networks. The ethical collection of training data requires explicit informed consent from all individuals whose voices or environmental sounds might be recorded. Advanced implementations should incorporate:
- Differential privacy mechanisms in data collection pipelines
- Granular opt-in/opt-out controls for different recording contexts
- Clear data retention policies with automatic deletion schedules
Audio Data Anonymization Techniques
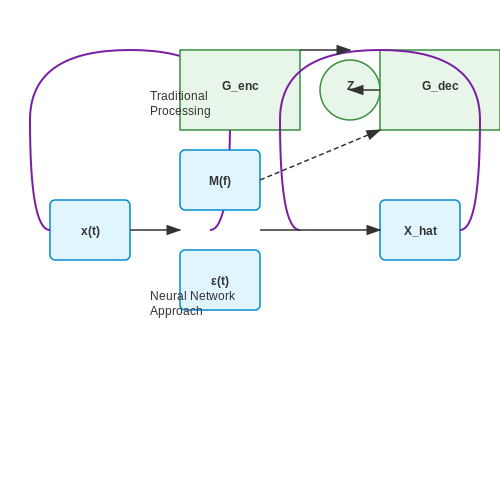
Raw audio waveforms contain biometric identifiers that can reveal speaker identity through voice characteristics. Effective anonymization requires both signal processing and machine learning approaches:
Where x(t) is the original signal, M(f) is a frequency-domain masking function, and ε(t) represents carefully calibrated noise injection. Modern approaches employ voice conversion networks that preserve acoustic event features while disrupting speaker identity:
Where the latent representation Z discards identity-related features through adversarial training with a speaker classifier.
Edge Computing vs. Cloud Processing
The choice between on-device and cloud-based processing carries significant privacy implications. While cloud solutions offer greater computational power, they introduce data transmission risks. Edge computing architectures minimize exposure but require:
- Quantized models that balance performance and privacy
- Secure enclaves for model execution
- Federated learning frameworks for model updates
The privacy-utility tradeoff can be formalized as:
Regulatory Compliance Challenges
Audio monitoring systems must navigate complex regulatory landscapes including GDPR Article 22 (automated decision-making), CCPA's right to deletion, and sector-specific regulations like HIPAA for healthcare applications. Key technical implementations include:
- Automated data subject access request (DSAR) processing pipelines
- Real-time data processing audits with blockchain-based logging
- Geofencing capabilities for region-specific compliance
Bias and Fairness in Audio Event Detection
Training datasets often underrepresent certain demographics, environments, or acoustic conditions, leading to biased performance. Mitigation strategies involve:
Where d_i represents protected demographic attributes. Advanced debiasing techniques include adversarial reweighting of training samples and synthetic data augmentation for underrepresented classes.
Security Considerations
Audio AI systems present unique attack vectors including:
- Adversarial audio examples that exploit microphone nonlinearities
- Model inversion attacks reconstructing private training data
- Backdoor attacks through poisoned training samples
Defensive measures incorporate audio-specific versions of established techniques:
Where 𝒜(x) generates acoustically plausible adversarial examples during training.
6. Key Research Papers in Audio AI
6.1 Key Research Papers in Audio AI
- Mobile crowdsourcing based context-aware smart alarm sound for smart ... — With the rapid development and pervasive usage of smartphones, our cities and lives are becoming smarter. As a key function of smartphones, digital alarm clock is widely used in people' daily lives, e.g., for waking up in the morning, for reminding some specific schedules, and etc [1].Thus, smart alarm sound plays an important role in our urban lives and enables our societies and cities to ...
- PDF Artificial Intelligence Risk Management Framework: Generative ... — EO 14110 defines Generative AI as "the class of AI models that emulate the structure and characteristics of input data in order to generate derived synthetic content. This can include images, videos, audio, text, and other digital content." While not all GAI is derived from foundation models, for purposes of this document, GAI generally refers
- PDF Smart Doorbell System - Ijcrt — 1Nehru College of Engineering and Research enter (NCERC), Thrissur, India Abstract: In recent years, face recognition technology has proved to be the most popular method of contactless biometric system, outstanding the ones based on iris, voice and gait recognition. Smart Doorbell systems are
- PDF A Hybrid Approach for Alarm Verification using Stream Processing ... — The system detects false alarms by means of image processing from surveillance cameras. However, we do not rely on any other information apart from alarm device properties, the type of supervised premise, location and time. Similarly, a patent issued by Honeywell AG presents a system that reduces false alarms in a home security system by using
- AI Enabled Accident Detection and Alert System Using IoT and Deep ... — detection smart accident alert and rescue system will help us to minimize delays in a rescue operation that could save many lives. With the growing popularity of smart cities, intelligent ...
- Internet of Things-Based Intelligent Smart Home Control System — An efficient smart home automation system is described as a set of methods intended to make a traditional home intelligent through the use of IoT technologies for enhanced home security , energy efficiency , remote control of home appliances [16, 33], comfort , convenience, and detection of movement in the house . The second motivation for this ...
- SMART ALARMING SYSTEM USING OBJECT DETECTION - ResearchGate — detected at a fully secured area the user and the security personnel can be informed, we also have an alarm system that is used to alert the user with the voice (name of the object detected).
- Artificial intelligence for cybersecurity: Literature review and future ... — Artificial intelligence (AI) is a powerful technology that helps cybersecurity teams automate repetitive tasks, accelerate threat detection and response, and improve the accuracy of their actions to strengthen the security posture against various security issues and cyberattacks.
- Design and Implementation of an IoT-Based Smart Home Security System — As a result, the system enables door control through both a mobile app and a keypad. Meanwhile, Hoque [11] proposed a design and implementation of a smart home security system based on IoT. The ...
- (PDF) A New Surveillance and Security Alert System Based ... - ResearchGate — The IoT-based home security system that utilizes the PIR sensor as a human motion detector and then sends a notification in the form of notification via SMS or e-mail is one solution to overcome ...
6.2 Open Datasets for Alarm Sound Detection
- Mobile crowdsourcing based context-aware smart alarm sound for smart ... — In this paper, we construct a smart alarm sound recommendation system working with smartphones to deliver smart alarm sounds by considering not only specified information, such as sleep patterns, but also context information such as weather, and social information.
- PDF AI AT THE EDGE AI AI AT AT TH - Smart Systems Integration — Increased safety with intelligent Alarm Systems: Edge AI-based alarm systems are a good example of how edge computing solutions enrich existing smart building systems.
- ASiT-CRNN: A method for sound event detection with fine-tuning of self ... — In this paper, we present an effective sound event detection (SED) method, which improves the performance of a baseline system based on convolutional recurrent neural network (CRNN) for the DCASE 2022 Task 4 by embedding a local-global audio spectrogram vision transformer (ASiT) with a two-phase fine-tuning strategy, thus referred to as ASiT-CRNN.
- Automatic detection of alarm sounds in a noisy hospital environment ... — The evaluation setup used to assess the performance of the detection systems is provided in Section 2, which includes a brief description of the audio database, the alarm classes, and the evaluation metrics.
- A sound event detection support system for smart home based on "two-to ... — The architecture of the sound event detection (SED) system in smart home projects, which involves collecting acoustic waves, converting them into digital signals, performing feature extraction, and utilizing SED technology to identify and locate sound events within audio streams.
- Anomalous sound event detection: A survey of machine learning based ... — With the development of multi-modal man-machine interaction, audio signal analysis is gaining importance in a field traditionally dominated by video. In particular, anomalous sound event detection offers novel options to improve audio-based man-machine interaction, in many useful applications such as surveillance systems, industrial fault detection and especially safety monitoring, either ...
- How Is Machine Learning Modifying Alarm System Responses? — Discover how machine learning is transforming alarm systems, enhancing threat detection, alarm classification, and personalized responses. Learn more here.
- (PDF) SMART ALARMING SYSTEM USING OBJECT DETECTION - ResearchGate — The main objective of this research is to assist the human operators, by implementing intelligent visual surveillance systems which help in detecting and tracking suspicious or unusual events in ...
- PDF Electronic Safety and Security (ESS) System Design and Implementation ... — Fire alarm systems are typically designed by professional fire engineers and designers with experience in national, state, and local code requirements related to designing and integrating such systems.
- AI Enabled Accident Detection and Alert System Using IoT and Deep ... — This article proposed an intelligent accident detection and rescue system which mimics the cognitive functions of the human mind using the Internet of Things (IoTs) and the Artificial Intelligence ...
6.3 Tools and Libraries for Audio AI Development
- Introducing OpenVINO AI effects for Audacity — Intel has built a suite of AI tools for Audacity, useful for spoken word audio and music alike. These AI features run 100% locally on your PC. AI tools for podcasts. For spoken word content, the OpenVINO effects contain a noise supression and a transcription plugin. The Noise Suppression does what it says on the tin - it suppresses noise. As ...
- Audio Analysis for Enhancing Security in Cognitive ... - Springer — This chapter aims to show a system of security for cognitive buildings based on microphones. In particular, we will analyze the information content of raw recording data obtained from the microphones and their processability into audio events, with detailed, actionable human-readable information. ... 6.4 AI in Audio Analysis. ... O., Iera, A ...
- AI and Machine Learning in Cyber Security Awareness Training — Organizations that harness the power of AI in their training modules are better positioned to face the cyber challenges of today and tomorrow. 5. Case Study: A Success Story 5.1. Koton: Revolutionizing Security Awareness Training with AI. TechFusion Corp, a leading global tech firm with over 10,000 employees, faced a significant challenge.
- How Is Machine Learning Modifying Alarm System Responses? — By combining the power of machine learning algorithms with the reasoning and decision-making abilities of AI, alarm systems will become even more intelligent and autonomous. AI integration will enable alarm systems to adapt to dynamic situations, learn from experience, and make context-aware decisions. 10.3 Impact on Security Industry
- PDF IoT Security Training for System Developers: Methodology and Tools — Smart Home Security Education. A set of hands-on lab exercises presented in [9] that allow students to conduct penetration testing against a set of smart home security cameras by using the Kali Linux distribution. The exercises are meant as a way for students to reveal and understand the vulnerabilities of real IoT devices.
- PDF Electronic Safety and Security (ESS) System Design and Implementation ... — to a rigorous public review and comment resolution process, which is a part of the full development and approval process for any BICSI international standard. ... Electronic Safety and Security (ESS) System Design and Implementation Best Practices. 9. Electronic Safety and Security .
- PDF ASL Voice Alarm Systems - Zenitel — INTEGRA product range is based, are described in the VIPEDIA-12-based Voice Alarm System Design Guide, T-0667-0185 and it is upon that document that this guide is based. Notes: 1. For full information relating to the design of rack-based PAVA Systems, please refer to document "T-0667-0185 Vipedia-12-based Voice Alarm System Design Guide". 2.
- Design and Implementation of an IoT-Based Smart Home Security System — Meanwhile, Hoque [11] proposed a design and implementation of a smart home security system based on IoT. The objective of this study is to propose a cost-effective architecture for building a ...
- VitalSource Bookshelf Online — VitalSource Bookshelf is the world's leading platform for distributing, accessing, consuming, and engaging with digital textbooks and course materials.
- PDF Automatic Security Monitoring and Alert System through Sound Analysis — %PDF-1.5 %âãÏÓ 1 0 obj /S /GoTo /D (section.1) >> endobj 4 0 obj (Introduction) endobj 5 0 obj /S /GoTo /D (section.2) >> endobj 8 0 obj (Literature Review) endobj 9 0 obj /S /GoTo /D (subsection.2.1) >> endobj 12 0 obj (Security in Developing Countries) endobj 13 0 obj /S /GoTo /D (subsection.2.2) >> endobj 16 0 obj (Security Agency Response Structure and Operation) endobj 17 0 obj /S ...