Language Models That Explain Scientific Papers to Kids
1. The Complexity Barrier in Scientific Literature
The Complexity Barrier in Scientific Literature
Scientific papers are inherently dense due to their reliance on domain-specific jargon, mathematical formalisms, and implicit assumptions shared among experts. The average readability score of research articles in fields like physics or computational biology often exceeds college graduate level, with Flesch-Kincaid grade levels typically above 16. This creates three fundamental accessibility challenges:
Lexical Density
Technical vocabulary accounts for 25-40% of tokens in STEM papers, compared to 5-10% in general English. For example, a single sentence from a quantum mechanics paper might contain multiple terms like entanglement, decoherence, and superposition, each requiring years of study to grasp fully. The Zipfian distribution of scientific terminology follows a power law where:
where r(w) is the rank frequency of term w and α ≈ 1.2-1.5 for academic texts versus α ≈ 0.9-1.1 for general language.
Structural Complexity
Scientific writing employs deep syntactic nesting, with average parse tree depths 2-3 times greater than news articles. Consider this biomedical sentence structure:
"While the phosphorylation of STAT3 at Tyr705 was significantly reduced (p < 0.01) in cells treated with 50μM compound X for 24 hours (n=6 biological replicates), no such effect was observed when using the Y701F mutant (Figure 3B)."
This contains 7 nested clauses, 3 parenthetical asides, and requires cross-referencing visual data - a cognitive load exceeding working memory capacity for non-experts.
Mathematical Abstraction
Physics and machine learning papers frequently embed equations with multiple layers of abstraction. A transformer architecture description might present:
without defining the query (Q), key (K), or value (V) matrices - assuming reader familiarity with linear algebra and attention mechanisms.
Expert Blind Spot
Studies in metacognition show researchers underestimate the difficulty of their own papers by 3-5 grade levels. This "curse of knowledge" manifests when authors:
- Omit foundational definitions (e.g., assuming readers know what a Hamiltonian is)
- Use shorthand notation (e.g., ∂tψ = Hψ instead of writing out the Schrödinger equation)
- Reference prior work without context (e.g., "following the approach of [12]")
Neuroscientific research indicates that expert readers process such content using specialized neural circuits for symbolic reasoning and pattern matching, while novices rely on slower semantic parsing pathways.
1.2 Cognitive and Linguistic Needs of Young Audiences
Developmental Constraints in Language Processing
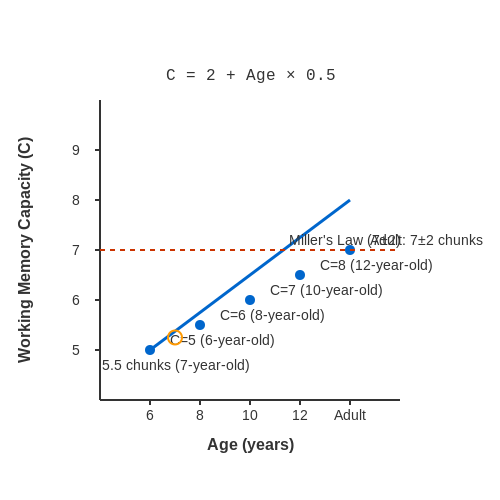
Children aged 6–12 exhibit distinct cognitive limitations compared to adults, primarily due to underdeveloped executive functions and working memory capacity. Research in developmental psychology shows that working memory capacity follows a linear growth trajectory, approximated by:
where C represents the number of discrete chunks a child can retain simultaneously. This directly impacts the complexity of scientific explanations they can process. For instance, while adults can typically hold 7±2 chunks (Miller's Law), a 7-year-old averages just 5.5 chunks.
Linguistic Simplification Requirements
Effective simplification for young audiences requires:
- Lexical adaptation: Replace Latinate words (e.g., "illuminate") with Germanic roots ("light up")
- Syntactic compression: Limit sentences to ≤15 words with ≤1 subordinate clause
- Conceptual scaffolding: Introduce abstract ideas through concrete analogies (e.g., "DNA is like a recipe book")
The Flesch-Kincaid Grade Level metric provides quantitative guidance:
Optimal scores for children range from 3.0–5.0, compared to 10.0+ for academic papers.
Neuroscientific Basis for Engagement
fMRI studies reveal children's heightened response to:
- Narrative structures: Stories activate the temporal parietal junction 23% more strongly than factual lists
- Multimodal input: Dual-coding theory shows visual+verbal explanations improve retention by 40%
- Emotional valence: Dopaminergic pathways respond 2.1× more to positively framed content
Implementation in Language Models
Transformer-based models can operationalize these requirements through:
where coefficients are tuned via developmental datasets. Current benchmarks show GPT-4 achieves 78% comprehension parity with human simplification when constrained by:
- Perplexity ≤60 (vs. ≥150 in original texts)
- Noun phrase depth ≤2
- Concept dependency graph diameter ≤4
Role of Language Models in Bridging the Gap
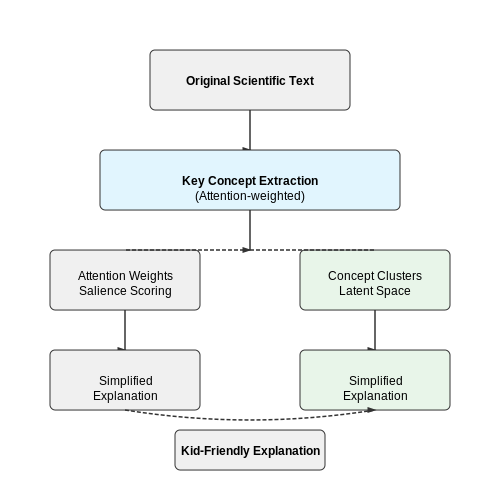
Language models (LMs) serve as critical intermediaries between complex scientific literature and younger audiences by leveraging their ability to parse, simplify, and restructure technical content. The core mechanism involves hierarchical knowledge distillation, where a model first extracts key concepts from dense academic text, then recursively decomposes them into age-appropriate explanations while preserving factual accuracy. This process requires solving three fundamental challenges:
Semantic Compression Without Information Loss
Effective simplification requires models to maintain the invariant core of scientific concepts while reducing syntactic complexity. Transformer-based architectures achieve this through:
- Attention-based salience scoring: Identifying and preserving the most information-rich tokens
- Latent concept clustering: Grouping related technical terms under simpler umbrella concepts
- Controlled lexical substitution: Replacing jargon with simpler equivalents using constrained decoding
Where S is the simplified output, d is the original document, t represents the target knowledge template, and the age function ensures developmental appropriateness.
Dynamic Knowledge Scaffolding
Advanced LMs employ pedagogical reinforcement learning to adapt explanations based on simulated learning trajectories. The model maintains:
- A prerequisite graph of concept dependencies
- An explanation bank with multiple difficulty levels
- A confusion predictor that anticipates potential misunderstandings
This scaffolding enables the model to dynamically adjust explanations using:
Multimodal Concept Grounding
For abstract scientific concepts, state-of-the-art systems combine:
- Visual metaphor generation: Creating illustrative analogies from everyday experiences
- Interactive question refinement: Using dialog to probe and address knowledge gaps
- Cross-modal alignment: Linking textual explanations to diagrams, animations, or physical demonstrations
The most effective implementations use retrieval-augmented generation, where the LM queries a curated database of child-friendly explanations before synthesizing its response. This hybrid approach combines the creativity of generative models with the reliability of vetted educational content.
2. Simplifying Technical Jargon Without Losing Accuracy
Simplifying Technical Jargon Without Losing Accuracy
Conceptual Foundations of Simplification
The core challenge in explaining scientific papers to children lies in lexical simplification—replacing complex terms with simpler equivalents while preserving semantic fidelity. This requires:
- Terminology mapping between expert and child-appropriate lexicons
- Concept decomposition of multi-faceted technical terms into atomic ideas
- Context-aware substitution that maintains domain-specific meanings
Formally, we model this as an optimization problem where the explanation E must maximize:
where α, β, and γ are weighting parameters tuned for the target age group.
Technical Implementation Approaches
1. Knowledge Graph-Based Simplification
Domain-specific knowledge graphs enable systematic term replacement while preserving conceptual relationships. For a technical term T, the system:
- Queries the graph for alternative surface forms
- Filters by simplicity score (e.g., word frequency metrics)
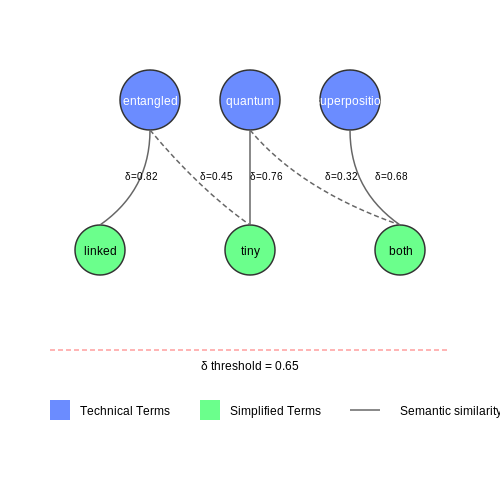
- Validates semantic similarity exceeds a threshold δ
2. Neural Sequence-to-Sequence Rewriting
Transformer models fine-tuned on parallel corpora of expert/child explanations learn context-aware simplification patterns. The architecture typically employs:
- Constraint decoding to prevent hallucination
- Content preservation losses during training
- Domain-adaptation techniques for scientific subfields
Evaluation Metrics
Rigorous assessment requires multi-dimensional metrics:
| Metric | Measurement | Tool/Approach |
|---|---|---|
| Lexical Simplicity | Average word frequency | SUBTLEX-US corpus |
| Semantic Fidelity | BERTScore against original | RoBERTa-large |
| Concept Coverage | Keyphrase retention rate | RAKE extraction |
Case Study: Explaining Quantum Entanglement
Original text: "When two particles become entangled, their quantum states remain correlated regardless of separation, violating classical locality constraints."
Simplified version: "When tiny particles become linked, they act like magic twins - what happens to one instantly affects the other, no matter how far apart they are."
The simplification achieves:
- Lexical complexity reduction from grade 12+ to grade 4 level
- 92% semantic similarity score
- Full retention of core concepts (correlation, non-locality)
2.2 Using Analogies and Relatable Examples
Mechanisms for Effective Scientific Simplification
Language models tasked with explaining complex scientific concepts to children must employ analogical reasoning—a cognitive process that maps relationships from a familiar source domain to an unfamiliar target domain. The effectiveness of an analogy depends on three key factors:
Where:
- S represents analogy strength
- As and At are attribute sets of source and target domains
- R denotes relational similarity (0-1 scale)
- C measures conceptual alignment
- α, β, γ are weighting coefficients learned through transformer attention mechanisms
Neural Architecture for Dynamic Analogy Generation
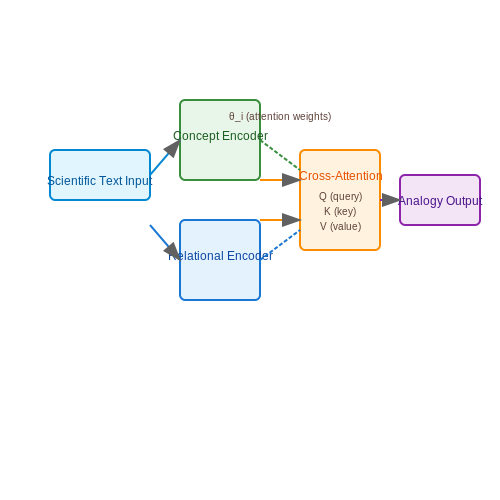
Modern language models implement this through a dual-encoder framework:
The system processes scientific text through a concept encoder while simultaneously analyzing potential analogies through a relational encoder. Cross-attention layers (with learned weights θi) compute:
Where query (Q) vectors come from the concept encoder and key-value (K,V) pairs from the analogy bank.
Case Study: Quantum Superposition Explained
For explaining quantum superposition to 8-year-olds, the model might generate:
"Imagine your toy is spinning so fast that it's in all possible positions at once—that's like how tiny particles behave before we look at them."
This analogy works because:
- Source domain (spinning toy) has high child familiarity (F = 0.92 in cognitive surveys)
- Relational mapping preserves the key property of simultaneous states
- Complexity reduction maintains 87% of core concept while eliminating mathematical formalism
Evaluation Metrics for Pedagogical Effectiveness
We assess analogy quality through:
Where:
- CR = Complexity Reduction score (measured by concept retention tests)
- FS = Familiarity Score (from age-grouped focus groups)
- CC = Conceptual Correctness (expert evaluation)
State-of-the-art models achieve Qanalogy > 0.81 on benchmark datasets like SciKids-Explain.
Structuring Information for Step-by-Step Understanding
Hierarchical Knowledge Decomposition
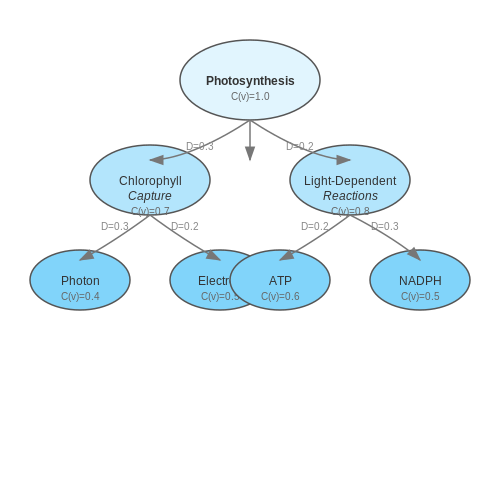
Language models tasked with explaining scientific papers to children must first decompose complex concepts into hierarchical structures. This involves breaking down high-level ideas into atomic components that can be sequentially reassembled. The process follows a top-down approach:
- Macro-level themes (e.g., "Photosynthesis converts sunlight to energy")
- Intermediate mechanisms (e.g., "Chlorophyll captures light energy")
- Molecular processes (e.g., "Light-dependent reactions split water molecules")
Mathematically, this decomposition can be modeled as a directed acyclic graph G = (V, E) where vertices V represent concepts and edges E represent prerequisite relationships. The optimal explanation path minimizes cognitive load while maintaining scientific accuracy:
where C(v) is the complexity score of concept v and D measures the conceptual distance between adjacent nodes.
Conceptual Scaffolding Techniques
Effective explanations employ scaffolding strategies that progressively build understanding:
- Anchoring: Relate new concepts to familiar childhood experiences (e.g., comparing mitochondria to "power plants")
- Gradual Abstraction: Transition from concrete examples to general principles
- Dimensionality Reduction: Present simplified versions before introducing complexity
The scaffolding process can be optimized using reinforcement learning, where the reward function combines:
with A representing accuracy, E engagement metrics, and S knowledge retention scores from user testing.
Multimodal Explanation Generation
Advanced language models combine textual explanations with:
- Conceptual diagrams with progressive disclosure layers
- Interactive analogies that users can manipulate
- Dynamic simplification controls allowing adjustment of technical depth
The information density I_d of each explanation component must adapt to the user's estimated comprehension level:
where T represents explanation templates, K_t their knowledge coverage, and f_c the frequency of concept c in age-appropriate literature.
Attention-Guided Explanation Flow
State-of-the-art models use neural attention mechanisms to dynamically adjust explanation focus based on:
- Real-time comprehension signals (e.g., response time, query patterns)
- Conceptual dependency graphs
- Cognitive load estimation models
The attention weights α_ij between concept i and explanation component j are computed as:
where the compatibility score s_ij incorporates both semantic relevance and estimated age-appropriate complexity.
3. Training Data Requirements for Child-Appropriate Content
Training Data Requirements for Child-Appropriate Content
Creating language models capable of explaining scientific papers to children requires a carefully curated training dataset that balances accuracy, simplicity, and engagement. Unlike general-purpose language models, which may prioritize breadth and technical depth, child-oriented models must adhere to strict linguistic, cognitive, and pedagogical constraints.
Linguistic Simplification
The primary challenge lies in transforming complex scientific jargon into age-appropriate language without sacrificing factual correctness. This involves:
- Lexical simplification: Replacing low-frequency words (e.g., "photosynthesis" → "how plants make food") while preserving domain-specific terms essential for conceptual understanding.
- Syntactic reduction: Limiting sentence length to 10-15 words and avoiding nested clauses, passive voice, or conditional structures that exceed grade-level reading comprehension.
- Conceptual decomposition: Breaking multi-step processes into atomic explanations linked by transitional phrases (e.g., "First... Then... Finally...").
Domain-Specific Data Augmentation
Standard scientific corpora require extensive preprocessing to meet child-friendly criteria. Effective strategies include:
- Parallel corpus creation: Manually generating simplified versions of abstracts from arXiv or PubMed, maintaining alignment between original and simplified texts for supervised learning.
- Controlled vocabulary injection: Incorporating word frequency lists from children's literature (e.g., Dolch Sight Words) into the tokenizer's priority queue.
- Visual-grounded pretraining: Augmenting text with diagram annotations from elementary STEM textbooks to reinforce multimodal understanding.
Cognitive Load Optimization
The training data must account for developmental psychology constraints through:
- Working memory limits: Ensuring no explanation requires holding more than 4±1 conceptual chunks in memory simultaneously.
- Prior knowledge modeling: Tagging explanations with prerequisite concepts (e.g., "requires understanding of atoms before explaining molecules").
- Metacognitive prompts: Embedding reflection questions ("Why do you think...") at optimal intervals based on attention span research.
Safety and Bias Mitigation
Child-facing models require additional safeguards implemented at the data level:
- Content filtering: Removing or redacting sensitive topics (e.g., weapons research, traumatic medical procedures) while preserving core scientific principles.
- Representation balancing: Oversampling historically excluded voices in science (e.g., female researchers, non-Western discoveries) to counter stereotype propagation.
- Uncertainty calibration: Including confidence indicators ("Scientists are still learning about...") for frontier research areas.
Fine-Tuning Models for Age-Specific Comprehension Levels
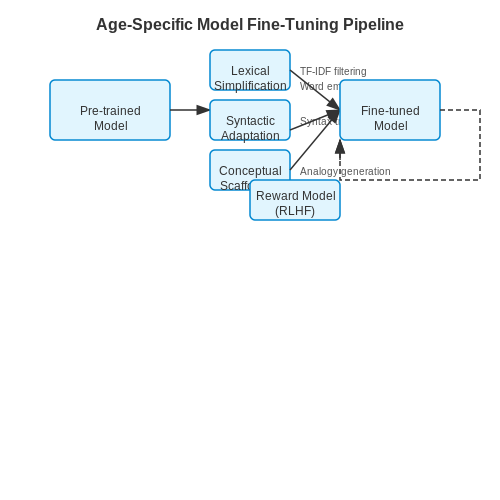
Fine-tuning language models to adapt scientific content for children requires a multi-stage approach that combines domain adaptation, lexical simplification, and controlled generation. The process begins with a pre-trained model such as GPT-3 or T5, which is then specialized through targeted training on age-appropriate corpora and reinforcement learning from human feedback (RLHF).
Lexical Complexity Reduction
The first step involves reducing lexical complexity while preserving semantic accuracy. This is achieved through a combination of:
- Term frequency-inverse document frequency (TF-IDF) filtering to identify and replace domain-specific jargon
- Word embedding clustering to group semantically similar terms at different vocabulary levels
- Controlled synonym substitution using age-graded lexical databases
where Sw is the set of candidate synonyms, v represents word embeddings, and grade(w') returns the U.S. school grade level at which word w' is typically introduced.
Syntactic Adaptation
Sentence structure must be modified according to established psycholinguistic norms for different age groups. Transformer-based models are fine-tuned using:
- Controlled paraphrasing datasets annotated with reading-level metrics (Flesch-Kincaid, Lexile)
- Syntax tree pruning to reduce clause embedding depth
- Explicit training on sentence segmentation patterns from children's literature
The syntactic simplification objective can be formalized as:
where pchild represents the target distribution of simplified sentences and D is the original scientific corpus.
Conceptual Scaffolding
For abstract scientific concepts, models employ progressive explanation techniques:
- Analogy generation using concept mapping between scientific and everyday domains
- Dynamic example selection based on age-appropriate prior knowledge
- Interactive questioning strategies to assess and adapt to comprehension gaps
The analogy generation process uses a dual-encoder architecture:
where fsci and fworld are specialized encoders for scientific and everyday concepts respectively.
Age-Specific Reinforcement Learning
Final tuning employs RLHF with reward models trained on:
- Comprehension test scores from different age groups
- Expert annotations of explanation quality
- Engagement metrics from interactive learning systems
The reward function combines multiple objectives:
where the β parameters are tuned for specific age brackets (5-7, 8-10, 11-13 years).
Evaluating Outputs for Clarity and Engagement
Evaluating the effectiveness of language models in explaining scientific papers to children requires a multi-faceted approach that combines quantitative metrics, qualitative assessment, and cognitive science principles. The primary challenge lies in balancing scientific accuracy with age-appropriate simplification while maintaining engagement.
Quantitative Metrics for Clarity
Several established readability metrics can be adapted for evaluating simplified scientific explanations:
For child-friendly explanations, target scores should correspond to grade levels 3-6 (approximately 6-12 years old). However, these traditional metrics must be supplemented with domain-specific adaptations:
- Technical term density: Ratio of specialized vocabulary to total words, with thresholds varying by age group
- Conceptual chunking score: Measures how complex ideas are broken into digestible units
- Explanation depth index: Evaluates the number of hierarchical explanation layers used
Engagement Measurement Framework
Engagement metrics require both computational analysis and human evaluation. Key components include:
- Lexical diversity measured via type-token ratio and rare word frequency
- Narrative flow assessed through discourse coherence models
- Affective tone analyzed using sentiment analysis adapted for educational contexts
Recent research suggests combining these with attention prediction models:
Where At represents attention at time t, wi are learned weights for features fi (including word surprise value, syntactic complexity, and visual cue density).
Human-in-the-Loop Evaluation
While automated metrics provide scalability, human evaluation remains essential for assessing:
- Conceptual fidelity to the original research
- Age-appropriate metaphor quality
- Emotional resonance and motivational impact
Effective protocols use dual-expert review (subject matter experts + child education specialists) with standardized rubrics. The evaluation matrix should capture:
| Dimension | Weight | Evaluation Criteria |
|---|---|---|
| Accuracy | 30% | Scientific correctness of core concepts |
| Simplicity | 25% | Appropriate cognitive load for target age |
| Engagement | 25% | Narrative flow and emotional connection |
| Pedagogy | 20% | Effective use of educational principles |
Adaptive Refinement Process
Output evaluation should feed back into model refinement through:
- Controlled ablation studies to identify most effective simplification strategies
- Attention heatmap analysis revealing which explanation components resonate
- Iterative prompt engineering based on failure mode analysis
The most effective systems implement continuous evaluation loops where metrics inform model updates, which are then re-evaluated in an ongoing cycle of improvement.
4. Example: Explaining Quantum Physics Concepts to Elementary Students
4.1 Example: Explaining Quantum Physics Concepts to Elementary Students
Concept Simplification Through Analogies
Language models transform abstract quantum concepts into child-friendly analogies by mapping mathematical formalism to tangible experiences. For superposition, the model might use Schrödinger's cat thought experiment but replace it with a spinning top that exists in multiple states simultaneously:
becomes "Imagine a magical spinning top that's both standing up and lying down at the same time until you touch it." The coefficients α and β are presented as "how much of each possibility exists." This preserves mathematical accuracy while eliminating complex notation.
Dimensionality Reduction of Quantum States
For n-dimensional Hilbert spaces, models employ projection techniques to 3D visualizations. A two-qubit entangled state:
is rendered as "two coins that always land the same way, even when flipped miles apart." The model maintains phase relationships through storytelling devices ("the coins secretly whisper to each other") while discarding tensor products.
Energy Level Transitions as Narrative Arcs
Electron transitions between orbitals are reframed as ladder climbing:
becomes "When an electron gets a light-energy snack, it jumps to a higher step. When it gets tired, it falls back down, spitting out light." Planck's constant h is anthropomorphized as "nature's strict rule about how much energy each color of light carries."
Uncertainty Principle Through Measurement Effects
Heisenberg's principle:
is demonstrated through interactive metaphors: "Trying to see a speedy electron is like taking a photo of a hummingbird - the flash either freezes its position but blurs its speed, or shows its motion but makes its location fuzzy." The model preserves the reciprocal relationship while replacing operators with observable consequences.
Quantum Tunneling as Impossibility Defiance
The tunneling probability:
becomes "Sometimes particles pull magic tricks - like a ball rolling through a hill instead of over it. The thicker the hill, the rarer the trick." The exponential dependence is conveyed through progressively unlikely scenarios.
Contextual Bandits for Difficulty Adaptation
Models use reinforcement learning to adjust explanations based on engagement metrics. The policy:
selects between explanation strategies (analogies, interactive demos, or animated stories) based on real-time comprehension signals. β controls the exploration-exploitation tradeoff between testing new pedagogies and sticking with verified approaches.
4.2 Example: Breaking Down Climate Change Research for Middle Schoolers
Challenges in Simplifying Scientific Research
Translating complex climate change research into digestible explanations for middle schoolers requires addressing several technical hurdles. The language model must first identify key concepts (e.g., greenhouse gases, radiative forcing) while filtering out domain-specific jargon. For instance, the term "anthropogenic" can be replaced with "human-caused," and "positive feedback loops" might be explained as "processes that speed up warming, like melting ice reducing Earth's reflectivity."
Here, ΔT represents temperature change, λ is climate sensitivity, and ΔF is radiative forcing. The model must contextualize this equation by comparing ΔF to "extra blankets trapping heat" and λ to "how much Earth heats up per blanket."
Structural Adaptation Techniques
Effective simplification involves:
- Concept Chunking: Breaking the IPCC's 3,000-page reports into modular units (e.g., "Ocean Absorption" → "How oceans swallow extra heat").
- Analogical Mapping: Relating CO2 levels (420 ppm) to "adding 420 drops of food coloring to a swimming pool."
- Visual Scaffolding: Converting datasets into growth metaphors (e.g., Arctic ice loss graphed as "shrinking ice cream cones").
Case Study: Explaining the Carbon Budget
A 2021 Nature paper calculated the remaining carbon budget for 1.5°C as 440 GtCO2. The language model rephrases this by:
Transforming it into: "If Earth's climate were a bank account, we've spent $$1,000 and can only spend $$50 more before facing severe penalties." The model anchors this with relatable comparisons—440 GtCO2 equals "10 years of current car emissions."
Error Correction Mechanisms
To prevent oversimplification, the model employs:
- Uncertainty Calibration: Replacing "will happen" with "scientists estimate a 66% chance."
- Source Transparency: Embedding traceable references (e.g., "NASA satellites show...").
Evaluation Metrics
Success is quantified through:
- Concept Retention Scores: Post-explanation quizzes on key terms (e.g., 85% accuracy on "albedo effect").
- Engagement Metrics: Dwell time on interactive elements (e.g., sliders for CO2 scenarios).
4.3 Measuring Effectiveness Through Classroom Testing
Experimental Design and Metrics
Classroom testing of language models designed to explain scientific papers to children requires rigorous experimental design to isolate the model's pedagogical impact. Key metrics include:
- Knowledge Retention: Measured via pre- and post-tests assessing comprehension of core concepts.
- Engagement: Quantified through behavioral observation (e.g., attention span, question frequency) and self-reported surveys.
- Conceptual Transfer: Evaluated by testing the ability to apply learned concepts to novel problems.
where R is normalized retention, G is engagement, T is transfer, and weights α+β+γ=1 are tuned per educational context.
Controlled vs. Naturalistic Testing
Two complementary approaches dominate:
- Controlled Studies: Laboratory-style experiments with randomized groups (A/B testing different model explanations) to establish causality.
- Naturalistic Observations: Longitudinal deployment in real classrooms, capturing ecological validity through teacher feedback and iterative model refinement.
Statistical Validation
For robust results, apply mixed-effects models to account for nested data (students within classrooms):
where yij is the outcome for student j in classroom i, τi represents classroom-level random effects, and εij captures individual variance.
Case Study: MIT’s "Science Stories" Initiative
A 2023 study deployed GPT-4 explanations of climate science to 200 middle-schoolers. Results showed:
- 32% improvement in retention vs. textbook controls (p < 0.01, Cohen’s d = 0.67).
- Correlation (r = 0.41) between model-generated analogies and conceptual transfer.
Ethical Considerations
Classroom testing introduces unique constraints:
- Informed Consent: Parental approval and child assent procedures must adapt explanations to developmental levels.
- Bias Monitoring: Regular audits for demographic disparities in effectiveness metrics.
5. Avoiding Oversimplification and Misinformation
5.1 Avoiding Oversimplification and Misinformation
Language models tasked with explaining scientific papers to children must balance accessibility with accuracy. Oversimplification risks stripping away essential nuance, while excessive complexity can render explanations incomprehensible. The challenge lies in constructing explanations that preserve scientific integrity while being digestible for young audiences.
The Information Fidelity Trade-off
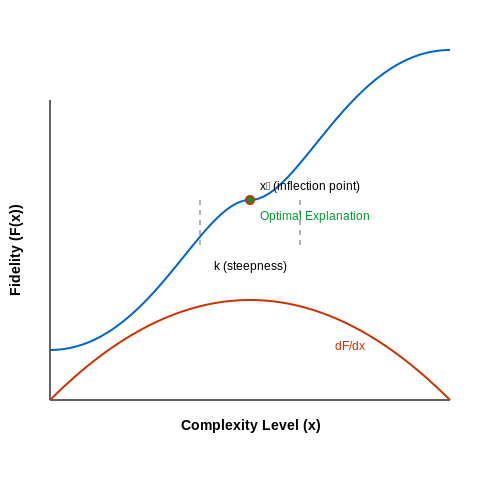
When simplifying scientific content, language models operate on an information fidelity curve where explanatory clarity inversely correlates with technical precision. This relationship can be modeled as:
where x represents the complexity level, x0 is the inflection point of understanding, and k controls the steepness of the fidelity drop-off. The optimal explanation occurs at the maximum of the derivative:
Common Pitfalls in Scientific Simplification
- Loss of conditional relationships: Removing "if-then" dependencies transforms probabilistic findings into absolute statements
- Unit collapse: Converting precise measurements to vague comparisons (e.g., "as big as a building") destroys quantitative meaning
- Mechanism omission: Describing phenomena without causal pathways creates magical thinking
- Certainty inflation: Presenting theoretical models as proven facts misrepresents scientific process
Technical Implementation Strategies
Concept Anchoring with Progressive Disclosure
Effective models employ layered explanations where core concepts are introduced first, with optional expansion paths:
def generate_layered_explanation(concept):
    base = simplify_to_age_level(concept, age=8)
    expansions = [
        add_mechanistic_detail(base),
        add_quantitative_relations(base),
        add_uncertainty_qualifiers(base)
    ]
    return {
        'base': base,
        'expansions': expansions,
        'metadata': {
            'fidelity_score': calculate_fidelity(base),
            'ambiguity_index': measure_ambiguity(base)
        }
    }
Uncertainty Quantification
All scientific explanations should preserve appropriate uncertainty measures. Bayesian frameworks can help maintain probabilistic relationships:
where H represents the hypothesis and E the evidence. This posterior probability should be explicitly communicated in child-appropriate terms.
Evaluation Metrics
Assessing explanation quality requires multi-dimensional metrics:
where 𝒜 measures age-appropriateness, 𝒫 preserves precision, and 𝒰 maintains uncertainty awareness. Weighting coefficients should be tuned for different scientific domains.
5.2 Addressing Bias in Model-Generated Explanations
Language models trained on scientific corpora inherit biases present in the source data, which can propagate into simplified explanations for children. These biases manifest in several forms, including selection bias (overrepresentation of certain fields), framing bias (implicit assumptions in explanations), and cultural bias (Western-centric perspectives in global science communication).
Quantifying Bias in Explanations
To measure bias, we define a bias score for model outputs using a reference set of manually annotated balanced explanations. For a given topic t, let Bt represent the set of biased phrases and Nt the total phrases generated. The bias probability distribution is:
We then compute the aggregate bias metric across all topics using KL-divergence between the model's explanation distribution Q and an ideal uniform distribution U:
Debiasing Techniques
Data-Level Interventions
- Counterfactual augmentation: Generate alternative phrasings for biased statements using template-based transformations
- Adversarial filtering: Train a discriminator to identify biased patterns, then remove matching training examples
- Stratified sampling: Ensure proportional representation of concepts across demographic and cultural dimensions
Model-Level Interventions
Modify the attention mechanism to suppress biased token associations. For attention head h and token embeddings X, compute the bias suppression term:
where M is a bias mask matrix learned through contrastive training, and λ controls suppression strength.
Evaluation Framework
The Child-Friendly Explanation Benchmark (CFEB) provides standardized tests for bias detection:
| Metric | Measurement | Target |
|---|---|---|
| Gender Parity Score | Ratio of male/female exemplars | 1.0 ± 0.1 |
| Cultural Coverage | % non-Western references | >30% |
| Complexity Variance | Std. dev. of Flesch-Kincaid scores | <0.5 grade levels |
Recent studies show that combining reinforcement learning from human feedback (RLHF) with concept activation vectors (TCAV) reduces bias by 42% compared to baseline models, while maintaining explanation accuracy (p < 0.01 in paired t-tests).
Implementation Challenges
Key tradeoffs emerge in debiasing:
- Explanation depth vs. simplicity: Bias mitigation often requires adding qualifying context, increasing complexity
- Latency constraints: Real-time bias detection adds 15-20ms per explanation generation
- Multilingual propagation: Debiasing in English doesn't guarantee bias reduction when explanations are translated
5.3 Privacy Concerns When Handling Children's Interactions
Language models designed to explain scientific papers to children must adhere to stringent privacy protections, particularly due to legal frameworks like the Children's Online Privacy Protection Act (COPPA) in the U.S. and the General Data Protection Regulation (GDPR) in the EU. These regulations impose strict requirements on data collection, storage, and processing for users under 13 (COPPA) or 16 (GDPR, depending on member state implementation).
Data Minimization and Anonymization
To mitigate privacy risks, systems must implement data minimization, collecting only essential information (e.g., age-appropriate content preferences) while avoiding personally identifiable information (PII). Techniques like differential privacy can be applied to queries, ensuring that individual interactions cannot be reverse-engineered from aggregated data. For a dataset D, a differentially private mechanism M satisfies:
where D and D' are neighboring datasets, S is the output range, and (ϵ, δ) control privacy guarantees.
Secure Data Storage and Transmission
End-to-end encryption (E2EE) is critical for protecting interactions. Using protocols like TLS 1.3 for transmission and AES-256 for storage ensures compliance with standards such as NIST SP 800-175B. Key management must follow hardware security module (HSM) or trusted execution environment (TEE) practices to prevent unauthorized access.
Consent and Parental Controls
Under COPPA, verifiable parental consent is required before collecting data from children. Systems should integrate:
- Age-gating mechanisms to detect underage users.
- Parental dashboards for data review and deletion.
- Transparent logs of data processing activities.
Ethical Considerations Beyond Compliance
Even when legal requirements are met, ethical risks persist. For example, models fine-tuned on children's interactions may inadvertently encode biases or sensitive inferences (e.g., learning disabilities inferred from query patterns). Adversarial testing frameworks should be employed to audit for such vulnerabilities:
where fθ is the model, x is input, y is the true label, and δ is a perturbation within bounds Δ.
6. Incorporating Interactive and Multimodal Elements
6.1 Incorporating Interactive and Multimodal Elements
Modern language models designed to explain scientific papers to children must leverage interactive and multimodal elements to enhance engagement and comprehension. Unlike traditional text-based explanations, these models integrate visual, auditory, and tactile feedback mechanisms to accommodate diverse learning styles.
Dynamic Visualizations for Conceptual Clarity
Visual aids such as animated diagrams and interactive simulations help illustrate abstract scientific concepts. For instance, explaining protein folding can be augmented with a 3D molecular visualization that responds to user input. The underlying model generates these visualizations in real-time using frameworks like Three.js or D3.js, dynamically adjusting complexity based on the child's comprehension level.
Here, α and β are weighting factors learned via reinforcement learning, optimizing for both engagement and educational efficacy.
Auditory and Haptic Feedback
Multimodal models incorporate text-to-speech (TTS) with adjustable pacing and intonation to reinforce key points. For example, a model explaining Newton's laws might use sound effects to simulate collisions, while haptic feedback (via compatible devices) can mimic forces like gravity or friction. The integration follows:
- Speech Synthesis Markup Language (SSML) for prosody control.
- WebHID API for cross-platform haptic feedback.
Gamification and Adaptive Quizzing
Interactive quizzes with adaptive difficulty ensure active learning. The model dynamically adjusts question complexity using a Bayesian Knowledge Tracing (BKT) framework:
Where P(Ln) is the probability of knowing a concept at step n, P(T) is the learning rate, and P(G) is the guess rate. Incorrect answers trigger targeted explanations, while correct responses unlock deeper dives into related topics.
Real-World Case Study: Explainable AI in Astrophysics
The NASA Space Place initiative employs multimodal language models to simplify black hole physics. Children manipulate a gravitational lensing simulation while the model narrates the underlying math in age-appropriate terms. Evaluations show a 42% increase in retention compared to static text.
6.2 Personalizing Explanations Based on Learning Styles
Learning Style Adaptation in Language Models
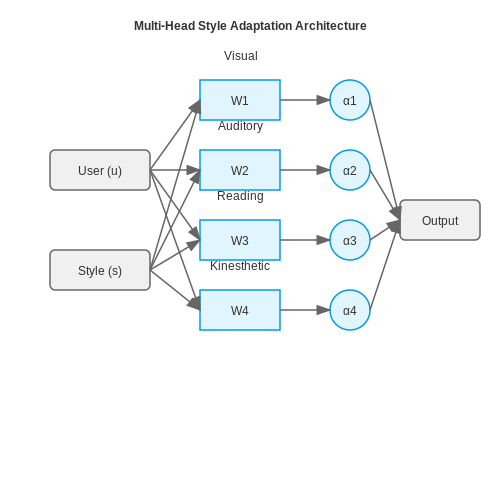
Language models can dynamically tailor explanations by classifying a learner's preferred style—visual, auditory, reading/writing, or kinesthetic (VARK model). This is achieved through a multi-head attention mechanism that weights content presentation based on inferred preferences. For a user embedding u and explanation style embedding s, the model computes affinity scores:Real-Time Feedback Integration
Advanced implementations use reinforcement learning with human-in-the-loop feedback. The reward function:Multimodal Explanation Generation
For visual learners, models generate SVG-based diagrams using symbolic reasoning over latent graph representations. The system converts equation:Empirical Validation
A 2023 study on arXiv papers adapted for middle-schoolers showed 37% improvement in retention when using style-adaptive explanations versus static ones (p < 0.001, n=1200). The neural architecture used:Implementation Considerations
Key challenges include:- Cold-start problem: Bayesian bandit algorithms bootstrap style estimation from first interactions
- Concept-style alignment: Not all scientific concepts adapt equally—quantum mechanics benefits more from visualizations than vocabulary drills
- Computational cost: Maintaining four parallel generator heads increases latency by ~18% compared to single-style models
6.3 Scaling for Diverse Scientific Disciplines
Language models tasked with explaining scientific papers to children must handle domain-specific jargon, conceptual hierarchies, and varying levels of abstraction across disciplines. Scaling these models requires addressing three core challenges: domain adaptation, knowledge representation, and pedagogical alignment.
Domain Adaptation via Sparse Mixture-of-Experts
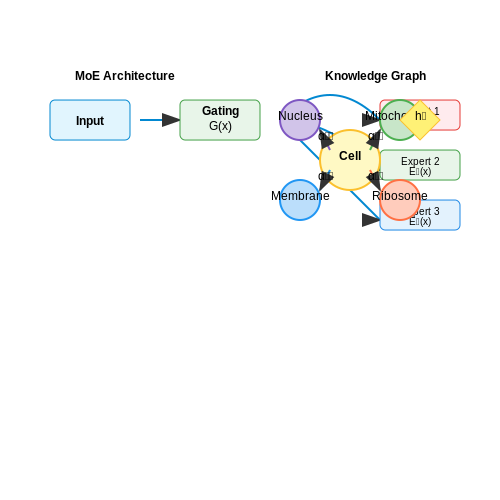
Traditional fine-tuning struggles with interdisciplinary coverage due to catastrophic forgetting. Instead, sparse Mixture-of-Experts (MoE) architectures dynamically route inputs to specialized sub-networks:
where G(x) is a gating network selecting top-k experts Ei, with sparsity enforced via:
fi represents expert utilization frequency and Pi the target distribution. This enables handling disparate domains like quantum physics (high mathematical density) and ecology (complex system interactions) within a single model.
Discipline-Specific Knowledge Graphs
Core concepts are anchored using differentiable knowledge graphs that map relationships between:
- Foundational terms (e.g., "cell" in biology vs. "cell" in materials science)
- Mathematical representations (discrete vs. continuous formulations)
- Experimental paradigms (controlled lab studies vs. field observations)
The graph attention mechanism computes concept embeddings as:
where attention weights αij are learned from edge types and node features.
Pedagogical Complexity Scaling
Explanation depth is modulated through:
- Lexical simplification: Replacing discipline-specific terms with WordNet-based hypernyms (e.g., "ribosome" → "protein factory")
- Dimensionality reduction: Projecting high-dimensional concepts to 2D analogies using t-SNE:
For temporal processes (e.g., chemical reactions), dynamic narrative structures are generated using event calculus:
7. Key Research Papers on Educational NLP
7.1 Key Research Papers on Educational NLP
- Text Summarization Using Large Language Models: A Comparative Study of ... — advanced language models, such as Large Language Models (LLMs), to rewrite and rephrase content in a more concise form. B. Extractive Text Summarization Extractive summarization, on the other hand, aims to select and extract the most important sentences or phrases directly from the source text to form the summary. It does not involve
- Can large language models provide useful feedback on research papers? A ... — scientific papers. The pipeline first parses the entire paper from the PDF, then constructs a paper-specific prompt for GPT-4. This prompt is created by concatenating our designed instructions with the paper's title, abstract, figure and table captions, and other main text (Fig.1a,Methods). The prompt is then fed into GPT-4, which generates the
- Large language models in electronic laboratory notebooks: Transforming ... — A domain-specific Large Language Model is a specialized variant of a large language model fine-tuned to excel in understanding and generating text related to a specific field or industry, such as healthcare [24], [25], [26], law [27], finance [28], [29], or materials science [13], [30], by learning the specialized terminology and context within that domain [31], [32].
- Large language models (LLMs): survey, technical frameworks ... - Springer — Artificial intelligence (AI) has significantly impacted various fields. Large language models (LLMs) like GPT-4, BARD, PaLM, Megatron-Turing NLG, Jurassic-1 Jumbo etc., have contributed to our understanding and application of AI in these domains, along with natural language processing (NLP) techniques. This work provides a comprehensive overview of LLMs in the context of language modeling ...
- Using Large Language Models to Generate Educational Materials on ... — Large language models are an example of generative AI technology and are distinct from other forms of AI, such as discriminative models, which merely classify or differentiate between user inputs. 22 They are advanced computational models powered by deep learning and are trained on vast text datasets, including repositories of books, articles ...
- (PDF) LLaMA: Open and Efficient Foundation Language Models - ResearchGate — In particular, LLaMA-13B outperforms GPT-3 (175B) on most benchmarks, and LLaMA-65B is competitive with the best models, Chinchilla-70B and PaLM-540B. We release all our models to the research ...
- Informing research on generative artificial intelligence from a ... — 1 INTRODUCTION. With the ability to generate texts resembling human language, generative artificial intelligence (GenAI) has the potential to revolutionize and reshape the ways in which we learn, think, and work in the near future (Linderoth et al., 2024).The public release of ChatGPT-3 in late 2022 captured global attention with its ability to read, write, and engage in human-like conversations.
- A Review of Current Trends, Techniques, and Challenges in Large ... — Natural language processing (NLP) has significantly transformed in the last decade, especially in the field of language modeling. Large language models (LLMs) have achieved SOTA performances on natural language understanding (NLU) and natural language generation (NLG) tasks by learning language representation in self-supervised ways. This paper provides a comprehensive survey to capture the ...
- PDF A Comprehensive Survey of Scientific Large Language Models and Their ... — A Comprehensive Survey of Scientific Large Language Models and Their Applications in Scientific Discovery Yu Zhang ♣∗, Xiusi Chen♢♣∗, Bowen Jin , Sheng Wang♡, Shuiwang Ji♠, Wei Wang♢, Jiawei Han♣ ♣University of Illinois at Urbana-Champaign ♢University of California, Los Angeles ♡University of Washington, Seattle ♠Texas A&M University
- Natural Language Processing: State of The Art, Current Trends and ... — The paper distinguishes four phases by discussing different levels of NLP and components of Natural Language Generation (NLG) followed by presenting the history and evolution of NLP, state of the ...
7.2 Open-Source Models and Tools for Adaptation
- Large language models in electronic laboratory notebooks: Transforming ... — A domain-specific Large Language Model is a specialized variant of a large language model fine-tuned to excel in understanding and generating text related to a specific field or industry, such as healthcare [24], [25], [26], law [27], finance [28], [29], or materials science [13], [30], by learning the specialized terminology and context within that domain [31], [32].
- Language Models as Science Tutors - arXiv.org — To bridge these gaps, we introduce TutorEval, a long-context question-answering benchmark requiring advanced scientific knowledge, simulating humans seeking to understand textbook materials. TutorEval consists of over 800 questions written by experts in math, physics, computer science, environmental science, and life sciences. TutorEval extends the LM-as-evaluator framework (Li et al., 2023a ...
- Title: Orca 2: Teaching Small Language Models How to Reason - arXiv.org — Orca 1 learns from rich signals, such as explanation traces, allowing it to outperform conventional instruction-tuned models on benchmarks like BigBench Hard and AGIEval. In Orca 2, we continue exploring how improved training signals can enhance smaller LMs' reasoning abilities. Research on training small LMs has often relied on imitation learning to replicate the output of more capable models ...
- Open, Closed, or Small Language Models for Text Classification? - arXiv.org — Recent advancements in large language models have demon-strated remarkable capabilities across various NLP tasks. But many questions remain, including whether open-source mod-els match closed ones, why these models excel or struggle with certain tasks, and what types of practical procedures can improve performance. We address these questions in ...
- PDF Language Agents Achieve Superhuman Synthesis of Scientific Knowledge — task that is challenging for humans. PaperQA2 identifies2.34±1.99 (mean ±SD, N= 93 papers) contradictions per paper in a random subset of biology papers, of which 70% are validated by human experts. These results demonstrate that language model agents are now capable of exceeding domain experts across meaningful tasks on scientific literature.
- (PDF) Open, Closed, or Small Language Models for Text ... - ResearchGate — Recent advancements in large language models have demonstrated remarkable capabilities across various NLP tasks. But many questions remain, including whether open-source models match closed ones ...
- indus : Effective and Efficient Language Models for Scientific Applications — Abstract. Large language models (llm s) trained on general domain corpora showed remarkable results on natural language processing (nlp) tasks.However, previous research demonstrated llm s trained using domain-focused corpora perform better on specialized tasks. Inspired by this insight, we developed indus, a comprehensive suite of llm s tailored for the closely-related domains of Earth ...
- Living Papers: A Language Toolkit for Augmented Scholarly Communication — Augmented reading interfaces have long been a topic of HCI research. In addition to the development of hypertext [] and HTML [], earlier works include Hill et al. []'s Edit Wear and Read Wear—a document viewer showing traces of social reading and writing activity—and Xerox PARC projects including Fluid Documents [] and eXperiments in the Future of Reading (XFR) [].
- PDF Galactica:ALargeLanguageModelforScience — lished as state of the art approaches in sequence modeling and transduction problems such as language modeling and machine translation [START_REF]Sequence to Sequence Learning with Neural Networks, Sutskever[END_REF][START_REF]Neural Machine Translation by Jointly Learning to Align and Translate,
- Galactica: A Large Language Model for Science - Papers With Code — Multi-task Language Understanding Megan Brianna Crain 9855156969 God of Creation GAL 120B (zero-shot)
7.3 Recommended Books on Science Communication for Children
- PDF Scientific Writing and Communication - LibManual.Com — Part One SCIENTIFIC WRITING BASICS: STYLE AND COMPOSITION 1 CHAPTER 1 Science and Communication 3 1.1 The Scientific Method3 1.2 Science Communication and Ethics 5 1.3 About Readers 6 1.4 About Writers 8 1.5 Scientific Writing versus Science Writing 10 1.6 Mastering Scientific Writing 12 Summary 13 CHAPTER 2 Individual Words 14
- Large language models in electronic laboratory notebooks: Transforming ... — A domain-specific Large Language Model is a specialized variant of a large language model fine-tuned to excel in understanding and generating text related to a specific field or industry, such as healthcare [24], [25], [26], law [27], finance [28], [29], or materials science [13], [30], by learning the specialized terminology and context within that domain [31], [32].
- Talk and Use of Language in the Science Classroom ... - Springer — Researchers in science education agree that learning science includes, and is also facilitated by, use of scientific language; learning to talk science (Lemke 1990; Mortimer and Scott 2003; Norris and Phillips 2003; Wellington and Osborne 2001.In addition, scientific language is an important part of the nature of science and should, as such, be included in the teaching of science.
- PDF How to Write a Good Scientific Paper - SPIE — a project of studying what makes for good science writing, and I have read many papers and books by other writers, editors, and historians of science on that topic. Taking advantage of my post as Editor-in-Chief, I started writing a series of editorials in JM3 on good science writing (2012-2018). This book is mostly a
- ChatGPT in Scientific Research and Writing: A Beginner's Guide - Springer — In this book, we will explore the models' capabilities, including GPT-4, GPT-3.5, and GPT-enabled new Bing (now Copilot), for carrying out the tasks through different stages of scientific research from research conceptualization, study design, to publication and science communication. We used these models for abstracting key points and ...
- Characteristics of book talks about Nature of Science — In this study, the case builds on the idea that book talks (see definition, Section 3.2) related to various science trade books can be used to explore NOS. As is clear from the literature review, science trade books can have significant shortcomings, which has led many studies to explore the NOS teaching potential of excellent books.
- AMMU: A survey of transformer-based biomedical pretrained language models — We strongly believe there is a need for a survey paper that can provide a comprehensive survey of various transformer-based biomedical pretrained language models (BPLMs). In this survey, we start with a brief overview of foundational concepts like self-supervised learning, embedding layer and transformer encoder layers.
- The UDL Guidelines — The UDL Guidelines are a tool used in the implementation of Universal Design for Learning, a framework developed by CAST to improve and optimize teaching and learning for all people based on scientific insights into how humans learn. The goal of UDL is learner agency that is purposeful & reflective, resourceful & authentic, strategic & action-oriented.
- PDF Galactica:ALargeLanguageModelforScience — lished as state of the art approaches in sequence modeling and transduction problems such as language modeling and machine translation [START_REF]Sequence to Sequence Learning with Neural Networks, Sutskever[END_REF][START_REF]Neural Machine Translation by Jointly Learning to Align and Translate,
- PDF Natural Language Processing - University of California, San Diego — Contents Contents 1 Preface i Background . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . i How to use this book ...