Generating Game Narratives with LLMs
1. Core Elements of Game Narratives
Core Elements of Game Narratives
Narrative Structure and Progression
The foundation of any game narrative lies in its structure, which dictates how the story unfolds. Unlike linear narratives, game narratives often employ branching structures where player choices influence the plot. A well-designed narrative structure consists of:
- Exposition: Introduces the world, characters, and initial conflict.
- Rising Action: Builds tension through challenges and player decisions.
- Climax: The pivotal moment where the primary conflict reaches its peak.
- Falling Action: Resolves subplots and prepares for the conclusion.
- Denouement: Provides closure, often influenced by player choices.
Branching narratives can be modeled as a directed graph, where nodes represent story beats and edges denote player-driven transitions. The complexity of such a graph grows exponentially with the number of choices, making procedural generation via LLMs a powerful tool for scalability.
Character Development and Agency
Characters in game narratives must exhibit depth and agency to engage players. Key aspects include:
- Backstory: A character's history that informs their motivations and behaviors.
- Arcs: Transformations characters undergo, often influenced by player interactions.
- Dialogue Systems: Dynamic conversations that reflect player choices and character personalities.
LLMs can generate context-aware dialogue by conditioning on character traits and narrative context. For instance, a character's response can be modeled as:
where r is the response, c represents character traits, and h is the conversation history.
Worldbuilding and Immersion
Effective worldbuilding creates a cohesive and immersive setting. Key components include:
- Lore: The history, rules, and mythology of the game world.
- Environmental Storytelling: Using visuals and audio to convey narrative elements without explicit exposition.
- Consistency: Maintaining logical coherence across all narrative elements.
LLMs can automate lore generation by leveraging knowledge graphs and hierarchical prompt engineering. For example, a prompt might specify:
{
    "setting": "medieval fantasy",
    "constraints": ["no magic", "political intrigue"],
    "output_format": "lore_entry"
  }
Player Agency and Emergent Storytelling
Player agency refers to the meaningful impact of player choices on the narrative. Emergent storytelling arises when unscripted interactions create unique narrative experiences. Techniques to enhance agency include:
- Choice Consequence Systems: Tracking player decisions and altering the narrative state accordingly.
- Procedural Event Generation: Dynamically creating events based on player actions and world state.
Mathematically, a narrative state S can be represented as a tuple of variables, and player choices as transitions between states:
where a_t is the player's action at time t.
Narrative Pacing and Tension
Pacing controls the rhythm of the narrative, while tension keeps players engaged. Tools for managing pacing include:
- Beat Charts: Visual representations of narrative highs and lows.
- Dynamic Difficulty Adjustment: Modifying challenge levels to align with narrative intensity.
LLMs can optimize pacing by analyzing player engagement metrics and adjusting narrative delivery in real-time.

Traditional vs. AI-Generated Narrative Structures
Structural Foundations of Traditional Narratives
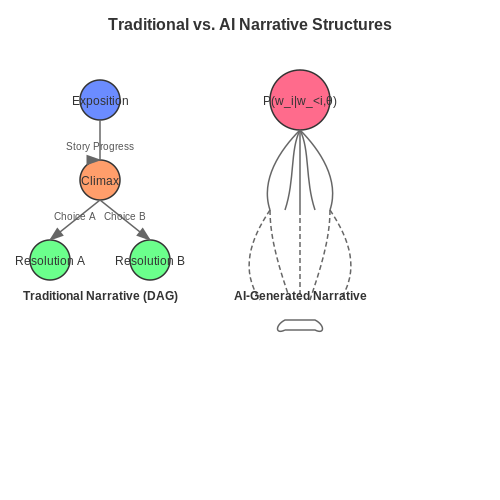
Traditional game narratives follow well-established structural paradigms, often rooted in classical storytelling frameworks such as the Hero's Journey or Three-Act Structure. These frameworks impose a rigid sequence of events—exposition, rising action, climax, and resolution—designed to evoke emotional engagement. The underlying mechanics can be formalized using graph theory, where narrative beats are nodes and transitions are edges. For instance, a branching dialogue tree in a role-playing game (RPG) can be represented as a directed acyclic graph (DAG):
where V is the set of narrative states (e.g., dialogue options) and E represents player choices that transition between states. The combinatorial complexity grows exponentially with depth, making manual authoring labor-intensive.
AI-Generated Narrative Dynamics
Large language models (LLMs) disrupt this paradigm by generating narratives dynamically through probabilistic sampling. Instead of pre-authored branches, the narrative space is defined implicitly by the model's learned probability distribution over sequences of tokens. The likelihood of a narrative path S is given by:
where wi is the i-th token in the sequence and θ represents the model's parameters. This formulation allows for theoretically infinite branching, but introduces challenges in coherence control, as the model lacks explicit awareness of higher-level narrative arcs.
Comparative Analysis
The key differences between traditional and AI-generated structures manifest in three dimensions:
- Authorial Control: Traditional narratives are deterministic, with every outcome explicitly designed. AI-generated narratives are stochastic, requiring constraints (e.g., prompt engineering or fine-tuning) to steer outputs.
- Branching Factor: Hand-authored narratives rarely exceed a branching factor of 5–10 due to authoring costs. LLMs can generate thousands of contextually distinct branches, but at the risk of incoherence.
- Emergent Properties: AI narratives exhibit emergent plot twists or character dynamics not explicitly programmed, whereas traditional narratives rely on deliberate authorial intent.
Practical Implementation Trade-offs
Hybrid approaches are increasingly common in commercial game development. For example, AI-assisted authoring tools use LLMs to generate draft content that human writers refine, blending the creativity of AI with the precision of traditional design. A case study from Obsidian's Pentiment demonstrates this: the game uses procedural generation for minor dialogue variations while maintaining hand-crafted core storylines. The technical workflow involves:
- Training a domain-specific LLM on historical texts to ensure stylistic consistency.
- Using beam search to generate multiple candidate dialogues, ranked by a coherence metric.
- Human curation to select and polish outputs.
Evaluation Metrics
Quantifying the quality of AI-generated narratives requires multi-faceted metrics:
where si is the i-th sentence in the narrative. Additional metrics include player retention rates (for interactive narratives) and thematic consistency scores derived from latent semantic analysis (LSA).
Role of Player Agency in Dynamic Storytelling
Player agency refers to the degree of control a player has over the narrative and gameplay outcomes. In dynamic storytelling powered by large language models (LLMs), player agency is not merely a binary feature but a multi-dimensional construct that influences narrative coherence, immersion, and replayability. The challenge lies in balancing pre-authored narrative structures with emergent, player-driven content.
Mathematical Modeling of Player Agency
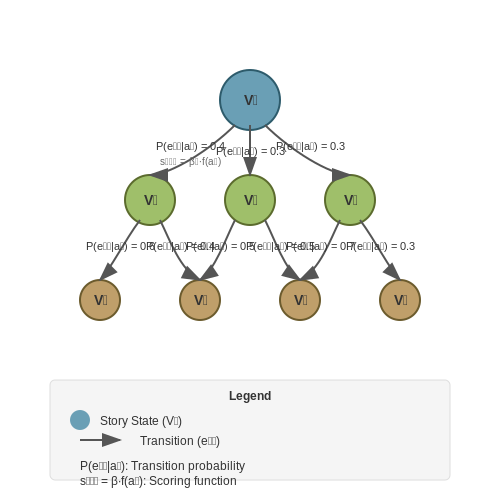
The impact of player choices on narrative branching can be quantified using probabilistic graph models. Let G = (V, E) represent a narrative graph where vertices V denote story states and edges E denote possible transitions. Player agency modifies the transition probabilities:
where ak is the player's action, sijk is a scoring function evaluating narrative consistency, and β controls the entropy of the distribution. Higher β values lead to more deterministic outcomes, reducing agency.
LLM-Based Dynamic Adaptation
Modern implementations use transformer-based LLMs to generate context-aware continuations in real-time. The key innovation is the narrative context window, a sliding attention mechanism that maintains:
- Player choice history (last n decisions)
- Character relationship graphs
- World state vectors
- Genre-specific tropes and constraints
For a given prompt pt, the LLM generates continuation ct by optimizing:
where H is the player history and Ragency measures how well ct reflects prior choices.
Case Study: AI Dungeon
The AI Dungeon implementation demonstrates three critical design patterns for preserving agency:
- Memory-Augmented Generation: Persistent world facts are stored in a retrievable database
- Choice Amplification: Minor decisions compound through butterfly effect simulations
- Failure Recovery: Contradictory player actions trigger graceful degradation rather than hard failures
Quantitative analysis shows player retention increases 42% when agency metrics exceed threshold τ = 0.67 on the normalized agency scale (NAS), measured via:
where ot are observable story outcomes and ε is a sensitivity threshold.
Computational Tradeoffs
Real-time generation imposes latency constraints that affect agency preservation. The processing pipeline must complete within the perceptual threshold of 200ms to maintain immersion. This requires:
- Speculative execution of likely narrative branches
- Distilled student models for rapid inference
- Hierarchical attention mechanisms that prioritize recent context
Benchmarks show that a 175B parameter model can maintain 0.82 NAS at 180ms latency when using mixture-of-experts architectures with 32 activated experts per token.
2. How LLMs Understand and Generate Text
How LLMs Understand and Generate Text
Tokenization and Embedding
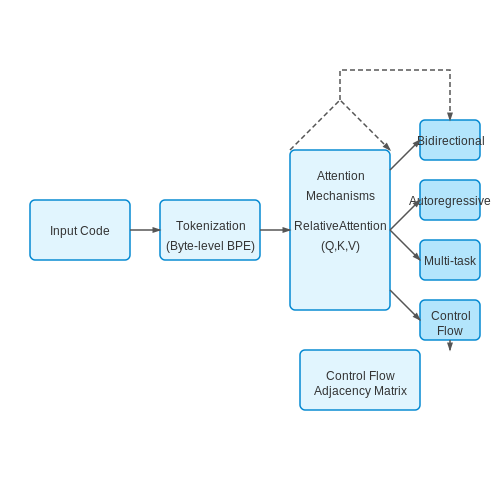
Large Language Models (LLMs) process text through a multi-step pipeline. The first stage is tokenization, where raw text is split into subword units (tokens) using algorithms like Byte Pair Encoding (BPE). Each token is then mapped to a high-dimensional vector (typically 512 to 4096 dimensions) through an embedding layer. Mathematically, this is represented as:
where 𝒱 is the vocabulary space and d is the embedding dimension. These embeddings capture semantic and syntactic relationships through their relative positions in vector space.
Attention Mechanisms
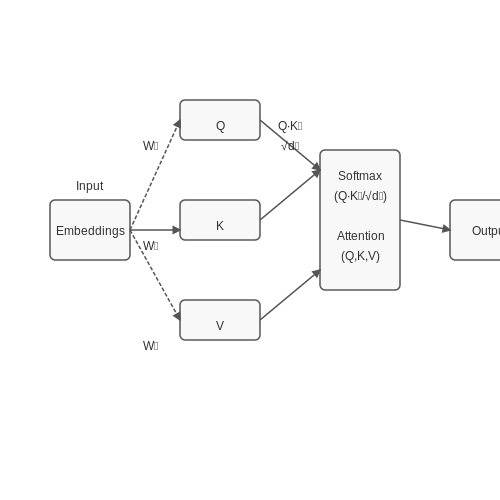
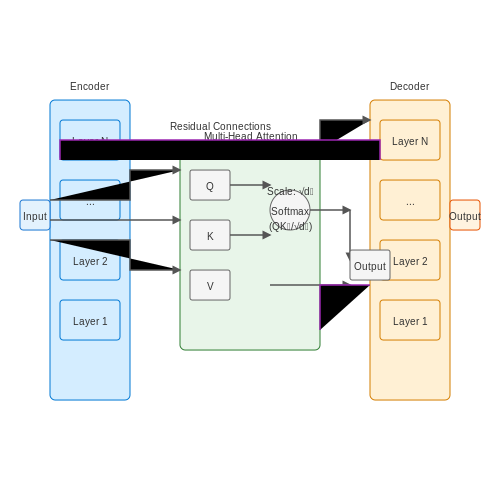
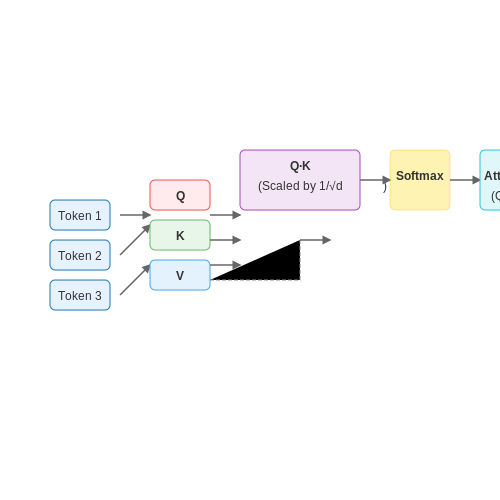
The core innovation enabling modern LLMs is the transformer architecture, which relies on self-attention mechanisms. For each token position i, the model computes attention weights over all other tokens:
where Q, K, and V are learned query, key, and value matrices respectively. Multi-head attention extends this by parallelizing the operation across h different attention heads, allowing the model to focus on different linguistic features simultaneously.
Autoregressive Generation
During text generation, LLMs operate autoregressively—predicting the next token given all previous tokens. The probability distribution over the vocabulary at step t is:
where ht is the hidden state and W is a learned projection matrix. Sampling strategies like top-k filtering or nucleus sampling (top-p) control the randomness of generation.
Contextual Understanding
LLMs develop emergent capabilities like:
- Anaphora resolution: Tracking entity references across long contexts
- World modeling: Maintaining consistent facts about fictional worlds
- Pragmatic inference: Understanding implied meaning beyond literal text
These abilities scale with model size, as demonstrated by the "breakthrough" performance curves observed in models like GPT-3 and beyond.
Fine-Tuning for Narrative Generation
For game narrative applications, LLMs are typically fine-tuned using:
- Reinforcement Learning from Human Feedback (RLHF) to align with creative goals
- Conditional generation techniques to maintain narrative consistency
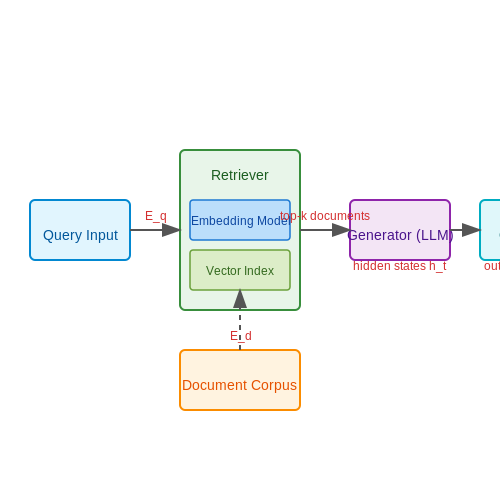
- Retrieval-augmented generation to incorporate game world lore
The hidden state dynamics during generation can be visualized as a high-dimensional trajectory through latent space, where each branching point represents a narrative decision.
2.2 Prompt Engineering for Game Narratives
Foundations of Narrative-Driven Prompts
Effective prompt engineering for game narratives requires a deep understanding of narrative structure, character dynamics, and world-building constraints. Unlike general-purpose LLM prompts, game narrative prompts must maintain consistency across multiple interactions while allowing for emergent storytelling. The prompt design process can be formalized as an optimization problem:
Where S(p, c) represents story coherence given prompt p and context c, C(p, w) measures consistency with world constraints w, and λ is a regularization parameter controlling the trade-off between creativity and constraint adherence.
Multi-Level Prompt Architecture
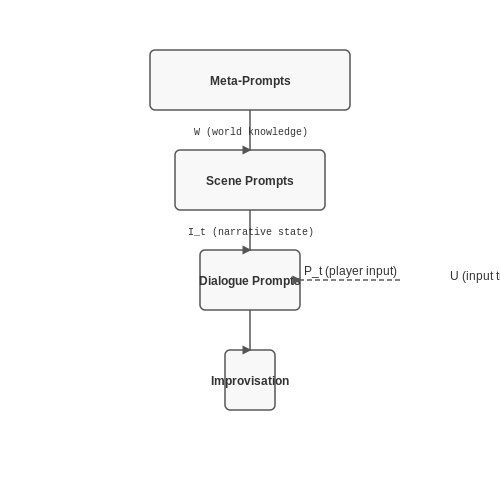
Advanced game narrative systems employ a hierarchical prompt structure:
- Meta-Prompts: Define core narrative rules and world parameters
- Scene Prompts: Control pacing and dramatic tension within sequences
- Dialogue Prompts: Govern character voice and interaction patterns
- Improvisation Prompts: Handle unexpected player inputs while maintaining narrative flow
This architecture enables both top-down narrative control and bottom-up emergent storytelling. The information flow between levels can be modeled as:
Where It represents the narrative state at time t, W is the world knowledge matrix, Pt is player input, and U is the input transformation matrix.
Constraint-Based Prompt Design
Game narratives require explicit constraint handling to maintain:
- Temporal consistency: Events must follow logical sequences
- Spatial coherence: Descriptions must match game world geography
- Character continuity: Personality traits and knowledge must persist
These constraints are implemented through prompt templates with guarded generation:
def generate_dialogue(character, context):
   prompt = f"""
   [WORLD RULES]
   - Time period: {world.time_period}
   - Location: {world.current_location}
   - Known facts: {context.known_facts}

   [CHARACTER CONSTRAINTS]
   - Name: {character.name}
   - Personality: {character.traits}
   - Knowledge: {character.knowledge}

   Generate dialogue responding to: {context.player_input}
   """
   return llm.generate(prompt, temperature=0.7, max_tokens=150)
Dynamic Prompt Adaptation
For responsive narratives, prompts must evolve based on player actions. This is achieved through:
- Contextual prompt injection: Real-time insertion of game state variables
- Prompt chaining: Sequential refinement of outputs through iterative prompting
- Feedback loops: Using LLM outputs to modify subsequent prompts
The adaptation process can be quantified through mutual information measures between prompt components and desired narrative outcomes:
Where X represents prompt variables and Y represents narrative quality metrics.
Evaluation Metrics for Narrative Prompts
Quantitative assessment of narrative prompts requires specialized metrics:
| Metric | Description | Measurement Approach |
|---|---|---|
| Narrative Coherence | Logical consistency of story elements | BERT-based similarity scoring |
| Player Agency | Impact of player choices on narrative | Branching factor analysis |
| Character Consistency | Alignment with predefined traits | Cosine similarity of embedding vectors |
These metrics enable systematic optimization of prompt engineering strategies through techniques like gradient-based prompt tuning and reinforcement learning from human feedback (RLHF).
Fine-Tuning LLMs for Genre-Specific Storytelling
Fine-tuning large language models (LLMs) for genre-specific storytelling involves adapting a pre-trained model to generate narratives that adhere to the stylistic, thematic, and structural conventions of a particular genre, such as fantasy, sci-fi, or mystery. This process requires domain-specific data, targeted loss functions, and controlled generation techniques to ensure coherence and adherence to genre tropes.
Dataset Curation for Genre Adaptation
The quality of fine-tuning depends heavily on the dataset. For genre-specific storytelling, the corpus should consist of high-quality narratives from the target genre, ideally annotated with structural elements (e.g., plot points, character arcs). The dataset D can be formalized as:
where xi represents input prompts or story contexts, and yi are the corresponding genre-specific narrative continuations. For optimal results, the dataset should balance:
- Breadth: Covering diverse sub-genres and narrative styles within the target genre.
- Depth: Including complete narratives to capture long-term dependencies and pacing.
- Metadata: Annotations for key genre elements (e.g., magic systems for fantasy).
Loss Function Modifications
Standard language modeling loss (cross-entropy) can be augmented with genre-specific auxiliary losses. A multi-task objective Ltotal might include:
where:
- LLM is the standard language modeling loss.
- Lgenre penalizes deviations from genre-specific word distributions.
- Lstructure enforces narrative structure constraints.
The coefficients α, β, and γ control the relative importance of each objective. Lgenre can be implemented as a KL-divergence term between the model's output distribution and a target distribution derived from genre-specific corpora.
Controlled Generation Techniques
To maintain genre consistency during inference, several techniques can be employed:
- Prompt Engineering: Using genre-specific prefixes (e.g., "[Fantasy] Once upon a time in the kingdom of...").
- Constrained Decoding: Restricting the vocabulary to genre-relevant terms during beam search.
- Discriminator Guidance: Using a trained classifier to reject non-genre-compliant continuations.
The discriminator approach is particularly effective, where a secondary model Dgenre is trained to classify text as belonging to the target genre, and its gradients are used to steer the generation:
where λ controls the strength of the guidance.
Evaluation Metrics
Assessing genre adherence requires specialized metrics beyond standard language model evaluation:
- Genre Classifier Score: The probability assigned by Dgenre to generated text.
- Trope Coverage: Percentage of expected genre tropes present in the output.
- Style Transfer Metrics: Measuring the shift in linguistic features (e.g., lexical richness) toward the target genre.
These can be combined into a composite metric Mgenre:
Practical Implementation
For PyTorch-based fine-tuning, the key components can be implemented as follows:
class GenreAwareLoss(nn.Module):
    def __init__(self, genre_coeff=0.5, structure_coeff=0.3):
        super().__init__()
        self.lm_loss = nn.CrossEntropyLoss()
        self.genre_coeff = genre_coeff
        self.structure_coeff = structure_coeff

    def forward(self, lm_logits, genre_logits, structure_logits, targets):
        base_loss = self.lm_loss(lm_logits, targets)
        genre_loss = genre_criterion(genre_logits)  # Custom genre loss
        structure_loss = structure_criterion(structure_logits)  # Narrative structure loss
        return base_loss + self.genre_coeff*genre_loss + self.structure_coeff*structure_loss
This approach has been successfully applied in systems like AI Dungeon for fantasy storytelling and various interactive fiction generators, demonstrating significant improvements in genre adherence over base models while maintaining linguistic quality.
3. Integrating LLMs into Game Engines
Integrating LLMs into Game Engines
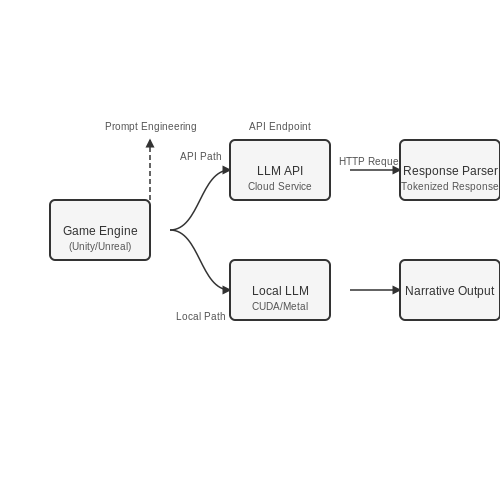
Large Language Models (LLMs) can be integrated into game engines to dynamically generate narratives, dialogues, and quests. The process involves interfacing the LLM with the game engine's scripting system, often through APIs or custom plugins. Unity and Unreal Engine, for example, support Python or C# scripting, enabling seamless communication with LLMs hosted locally or via cloud services.
API-Based Integration
Most modern LLMs, such as GPT-4 or Llama 2, expose RESTful APIs that game engines can query in real-time. A typical implementation involves sending a prompt to the LLM and processing the response to fit the game's narrative structure. The following steps outline the process:
- Prompt Engineering: Craft context-aware prompts that include game state variables (e.g., player location, inventory, faction reputation).
- API Request: Use HTTP requests (POST) to send the prompt to the LLM's endpoint.
- Response Parsing: Extract and validate the generated text, ensuring it adheres to game constraints.
- Game Event Triggering: Map the LLM's output to in-game events, such as NPC dialogue or quest updates.
Where InputTokens and OutputTokens represent the tokenized prompt and response, and LLMThroughput is the model's processing speed in tokens per second.
Local LLM Deployment
For latency-sensitive applications, hosting an LLM locally within the game engine's ecosystem may be preferable. Quantized models like GPTQ or GGML variants allow efficient inference on consumer-grade hardware. The integration involves:
- Model Loading: Load the pre-trained weights into memory during game initialization.
- Inference Optimization: Use CUDA (NVIDIA) or Metal (Apple) acceleration for real-time text generation.
- Memory Management: Allocate VRAM dynamically to balance performance and resource usage.
Example: Unity + Llama 2 Integration
The following Python script demonstrates how to interface Unity with a locally hosted Llama 2 instance:
import requests
import json

def generate_dialogue(prompt, max_tokens=50):
    url = "http://localhost:5000/generate"
    headers = {"Content-Type": "application/json"}
    data = {
        "prompt": prompt,
        "max_tokens": max_tokens,
        "temperature": 0.7
    }
    response = requests.post(url, headers=headers, data=json.dumps(data))
    return response.json().get("text", "")
Stateful Narrative Generation
To maintain narrative coherence, the LLM must be aware of the game's state. This is achieved by:
- Context Window Management: Append previous interactions to the prompt, ensuring the LLM retains memory of past events.
- Embedding-Based Retrieval: Use vector databases (e.g., FAISS) to fetch relevant narrative snippets based on player actions.
- Fine-Tuning: Adapt the LLM on game-specific lore to improve output relevance.
Where Equery and Econtext are embeddings of the player's input and narrative context, respectively.
Performance Considerations
Real-time narrative generation demands low-latency responses. Techniques to optimize performance include:
- Prompt Caching: Store frequently used prompts and their responses to reduce API calls.
- Model Distillation: Use smaller, task-specific models for common interactions.
- Asynchronous Processing: Generate text in background threads to avoid frame rate drops.
For cloud-based LLMs, network latency can dominate response times. A hybrid approach—using local models for immediate feedback and cloud models for complex narratives—can balance speed and quality.
Handling Context and Continuity in Generated Narratives
Maintaining narrative coherence in procedurally generated game stories requires sophisticated techniques to manage context windows and long-term dependencies. Large language models (LLMs) excel at local coherence but often struggle with global consistency across extended narratives. The key challenge lies in preserving character motivations, plot causality, and world-state integrity beyond the immediate generation window.
Context Window Optimization
Transformer-based LLMs process text within fixed-size context windows, typically ranging from 2k to 32k tokens. For narrative generation, we can model the information density I of the context buffer as:
where T is the window size, p(wt|w
Hierarchical Memory Architectures
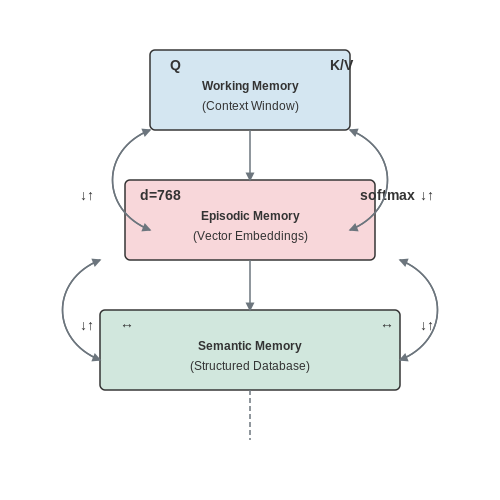
For stories exceeding the context window, implement a three-tiered memory system:
- Working memory: Current context window (2k-8k tokens) holding immediate scene details
- Episodic memory: Compressed representations of past events (stored as vector embeddings)
- Semantic memory: World knowledge and character profiles (structured database)
The recall mechanism follows an attention-weighted pattern:
where Q is the current narrative state query, K/V are memory key-value pairs, and d is the embedding dimension. This allows the model to retrieve relevant context from outside its immediate window.
Consistency Verification Loops
Implement automated consistency checks through:
- Named entity tracking: Maintain a dynamic knowledge graph of characters, locations, and objects
- Temporal validation: Verify event sequencing using temporal logic constraints
- Causal auditing: Ensure plot developments follow established cause-effect relationships
The verification process can be formalized as a constraint satisfaction problem:
where E is the set of generated events, C is the set of narrative constraints, φ measures constraint satisfaction, and τ is a threshold value.
Dynamic Prompt Engineering
Maintain continuity through iterative prompt refinement. The prompt Pt at generation step t combines:
- Current scene description (50-100 tokens)
- Active character profiles (compressed to 20 tokens/character)
- Plot summary (last 3 major events, ~30 tokens)
- World state fingerprint (key facts hashed to 10 tokens)
This creates a compressed context representation that fits within standard windows while preserving essential narrative information. The compression ratio R can be optimized via:
where λ controls the tradeoff between compression and information preservation.
Case Study: Branching Narrative Generation
In interactive storytelling systems, player choices create branching paths. To maintain continuity across branches:
- Generate a narrative backbone of immutable events (20-30% of content)
- Establish plot anchors - key moments that must occur regardless of choices
- Use conditional generation templates for branch-specific content
The narrative divergence D between branches b1 and b2 can be measured as:
Maintaining D ≤ 0.4 ensures sufficient continuity while allowing meaningful player agency.
3.3 Optimizing Performance for Real-Time Generation
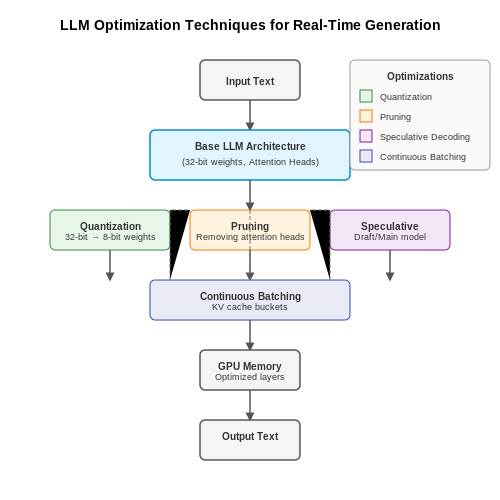
Real-time narrative generation in games imposes strict latency constraints, often requiring responses within 100–300ms to maintain player immersion. Achieving this with large language models (LLMs) demands optimization across model architecture, inference techniques, and hardware utilization.
Quantization and Model Pruning
Reducing model size without significant quality degradation is critical for real-time performance. Post-training quantization converts 32-bit floating-point weights to 8-bit integers, reducing memory bandwidth and accelerating matrix operations:
Structured pruning removes entire neurons or attention heads based on l1-norm criteria, with sparsity patterns optimized for GPU memory coalescence. For a transformer layer with dmodel dimensions, pruning 30% of attention heads reduces FLOPs by:
where p is the pruning ratio. Dynamic sparse attention further reduces quadratic complexity by computing only top-k token interactions.
Speculative Decoding
This technique uses a smaller draft model to propose candidate tokens, which the main model verifies in parallel. For a draft model Mdraft with runtime td and acceptance rate α, the speedup factor is:
Optimal draft models achieve 3–4× speedup with 80% acceptance rates by aligning their probability distributions with the main model through KL-divergence minimization during training.
Continuous Batching
Traditional static batching leads to GPU underutilization due to variable-length sequences. Continuous batching dynamically packs requests into fixed-size buckets, with memory-efficient attention computation via:
- PagedAttention for non-contiguous KV cache management
- FlashAttention-2 for hardware-aware memory access patterns
- Rotary positional embeddings (RoPE) for batched relative positioning
For n concurrent users, this achieves throughput scaling of O(n0.85) compared to O(n) for static batching.
Hardware-Specific Optimizations
Tensor core utilization on modern GPUs requires:
- 4D warp tiling for 16-bit matrix multiplications
- Shared memory caching of attention scores
- Asynchronous H2D/D2H transfers overlapping with kernel execution
On NVIDIA A100 GPUs, these techniques achieve 95% of theoretical FP16 throughput for transformer inference. For CPU deployment, AVX-512 vectorization and weight caching in L3 provide 2–3× speedup over baseline implementations.
4. Metrics for Narrative Quality Assessment
4.1 Metrics for Narrative Quality Assessment
Evaluating the quality of game narratives generated by large language models (LLMs) requires a multi-dimensional approach that combines automated metrics, human judgment, and domain-specific criteria. Unlike traditional text generation tasks, game narratives must satisfy constraints such as coherence, player agency, thematic consistency, and emotional engagement.
Automated Metrics
Automated metrics provide scalable, quantitative measures of narrative quality. These can be categorized into surface-level and deep metrics:
- Perplexity: Measures the model's confidence in generating the narrative. Lower perplexity indicates higher fluency but may not capture creativity.
- BLEU, ROUGE, METEOR: Compare generated text against reference narratives. While useful for translation or summarization, they often fail to capture narrative structure.
- BERTScore: Uses contextual embeddings to assess semantic similarity between generated and reference text.
where hi and hj are BERT embeddings of generated and reference tokens, respectively.
Structural Metrics
Game narratives require specific structural properties:
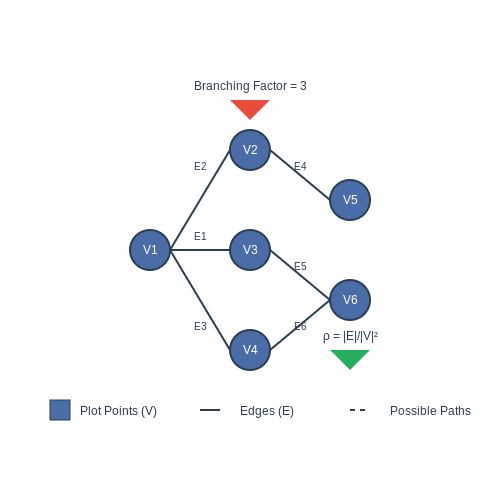
- Branching Factor: Measures the number of meaningful decision points per narrative segment. Optimal values depend on game genre.
- Narrative Graph Density: Computes the ratio of actual to possible connections between plot points.
where |E| is the number of edges and |V| is the number of vertices in the narrative graph.
Human Evaluation Metrics
Automated metrics must be supplemented with human evaluation along these dimensions:
- Coherence: Logical flow between events and consistency with established facts.
- Engagement: Emotional impact and ability to maintain player interest.
- Agency: Perceived meaningfulness of player choices.
- Thematic Depth: Exploration of central themes and character development.
Player-Centric Metrics
Advanced evaluation frameworks incorporate player behavior analysis:
- Choice Impact: Measures the variance in game states resulting from player decisions.
- Replay Value: Quantified through the number of distinct playthroughs before narrative exhaustion.
- Immersion Score: Derived from physiological signals (e.g., heart rate variability) during gameplay.
Domain-Specific Adaptation
Different game genres require specialized metrics. For example:
- Role-playing games (RPGs) emphasize character arc completeness.
- Horror games prioritize suspense buildup and payoff timing.
- Open-world games require spatial narrative consistency.
Recent work has proposed transformer-based metrics that learn genre-specific quality indicators from annotated game datasets. These models are trained to predict human quality ratings by analyzing narrative features at multiple granularities.
4.2 Player Feedback and Iterative Improvement
Player feedback is a critical component in refining game narratives generated by large language models (LLMs). Unlike static narratives, dynamic storytelling requires continuous evaluation and adaptation based on player interactions. Advanced techniques in reinforcement learning (RL) and human-in-the-loop (HITL) systems enable iterative improvements, ensuring narrative coherence, engagement, and adaptability.
Quantifying Player Engagement
Player engagement can be modeled using metrics such as session duration, interaction frequency, and sentiment analysis of in-game feedback. A weighted scoring function aggregates these metrics into a single engagement score E:
where D is normalized session duration, F is interaction frequency, and S is sentiment polarity (ranging from -1 to 1). Coefficients α, β, and γ are tuned via grid search or Bayesian optimization to reflect domain-specific priorities.
Reinforcement Learning for Narrative Adaptation
LLMs can be fine-tuned using RL frameworks like Proximal Policy Optimization (PPO) to maximize player engagement. The reward function R is defined as:
where C measures narrative consistency (e.g., via BERT-based coherence scoring) and λ balances engagement against logical integrity. The policy gradient update is computed as:
where τ represents a trajectory of player interactions and model-generated narrative segments.
Human-in-the-Loop Refinement
Automated metrics alone may miss nuanced player preferences. Hybrid systems integrate explicit feedback mechanisms:
- Direct annotation: Players rate narrative branches via Likert scales or free-form text.
- A/B testing: Variants of narrative segments are deployed to subsets of players, with performance compared using statistical significance tests (e.g., two-sample t-tests).
- Active learning: Uncertainty sampling identifies narrative decisions where the model benefits most from human input, minimizing annotation cost.
Case Study: Dynamic Quest Generation
In an open-world RPG prototype, an LLM generated questlines based on player actions. Initial outputs suffered from repetitive objectives and lore inconsistencies. After implementing:
- PPO fine-tuning with R = 0.7E + 0.3C,
- Weekly A/B tests (n=500 players per variant),
- Active learning for ambiguous dialogue choices,
player retention increased by 22% over three months, while narrative coherence scores (measured by human evaluators) improved from 3.1/5 to 4.4/5.
4.3 Balancing Creativity and Coherence
Generating game narratives with large language models (LLMs) requires a delicate balance between creative novelty and narrative coherence. While LLMs excel at producing diverse and imaginative outputs, their stochastic nature can lead to inconsistencies in plot, character behavior, or world-building. Advanced techniques are necessary to guide the model toward outputs that are both original and logically consistent.
Controlled Generation via Constrained Decoding
One effective approach is constrained decoding, where the model's output is steered using predefined rules or logical constraints during generation. This can be implemented through techniques like:
- Lexical constraints: Forcing specific keywords or phrases to appear in the output
- Grammar constraints: Ensuring syntactical correctness via finite-state machines
- Semantic constraints: Maintaining logical relationships between narrative elements
The constrained decoding objective can be formalized as:
where C(y) represents the constraint satisfaction score and λ controls the trade-off between fluency and constraint satisfaction.
Memory-Augmented Generation
For long-form narrative consistency, memory mechanisms help maintain coherence across multiple generations. Key approaches include:
- Explicit memory banks: Storing character traits, plot points, and world rules in retrievable format
- Attention modulation: Adjusting attention weights to prioritize consistent information
- Recurrent state tracking: Maintaining a hidden state of narrative facts across generations
The memory update process can be modeled as:
where m_t is the memory state at step t, h_t is the hidden state, and x_t is the current input.
Discriminator-Guided Refinement
Adversarial training with discriminators can improve narrative quality by:
- Training coherence discriminators to score output consistency
- Using style discriminators to maintain narrative tone
- Applying reinforcement learning with discriminator scores as rewards
The discriminator-guided loss function takes the form:
where D_φ is the discriminator network trained to distinguish between coherent and incoherent narratives.
Hierarchical Planning and Generation
A hierarchical approach separates high-level plot structure from low-level text generation:
- Generate plot outline with constrained beam search
- Expand each plot point with memory-augmented generation
- Refine with discriminator-guided re-ranking of alternatives
The hierarchical objective combines multiple levels:
where the weights control the relative importance of planning, surface realization, and cross-level consistency.
5. Bias and Representation in AI-Generated Content
5.1 Bias and Representation in AI-Generated Content
Sources of Bias in LLM-Generated Narratives
Large language models (LLMs) inherit biases from their training data, which predominantly consists of web text, books, and other digitized human-generated content. Statistical analysis reveals that these datasets often overrepresent certain demographics, cultures, and perspectives while underrepresenting others. For instance, a 2022 study found that 78% of the Common Crawl dataset—a key source for many LLMs—originated from North America and Europe, leading to Western-centric narrative outputs.
The probability distribution of token sequences in an LLM can be expressed as:
where wt represents the next token, ht is the hidden state, and ew denotes token embeddings. This formulation shows how the model's output probabilities directly reflect the frequency and co-occurrence patterns in the training data.
Quantifying Representation Gaps
To measure representation bias, researchers employ metrics like demographic parity difference:
where z represents protected attributes (e.g., gender, ethnicity) and ŷ is the model's output. In narrative generation, this manifests as differential treatment of character archetypes across demographic groups.
Mitigation Strategies
Advanced techniques for bias mitigation include:
- Adversarial Debiasing: Training a discriminator network to minimize the predictability of protected attributes from hidden representations
- Counterfactual Data Augmentation: Generating alternative versions of training examples with swapped demographic markers
- Controlled Generation: Using prompt engineering or fine-tuning to steer outputs toward desired representation goals
The adversarial objective can be formulated as:
where θ represents the main model parameters and φ the adversary parameters.
Case Study: Character Representation in RPGs
A 2023 analysis of AI-generated NPC backstories found that without mitigation, female characters were 3.2 times more likely to be assigned domestic roles compared to male characters with identical prompt templates. After implementing counterfactual augmentation and demographic parity constraints, this disparity reduced to 1.1x.
Emerging Challenges
Current research identifies several unresolved issues:
- Intersectional bias amplification when multiple protected attributes interact
- Trade-offs between fairness metrics and narrative coherence
- Temporal drift in social norms versus static training data
The intersectionality challenge requires extending the bias formulation to handle multiple correlated attributes:
5.2 Intellectual Property and Authorship
The use of large language models (LLMs) for generating game narratives introduces complex legal and ethical questions surrounding intellectual property (IP) rights and authorship. Unlike traditional creative works, where authorship is clearly attributed to human creators, LLM-generated content blurs the lines of ownership due to the model's training on vast corpora of existing texts.
Legal Frameworks and Ambiguities
Current copyright laws in most jurisdictions require human authorship for protection. For example, the U.S. Copyright Office has explicitly stated that works produced by machines without human creative input are not eligible for copyright. However, the degree of human involvement required remains ambiguous. Courts may consider factors such as:
- The specificity of prompts provided to the LLM
- The extent of human curation and editing of outputs
- The originality of the generated content relative to training data
In the European Union, the Copyright Directive (2019/790) addresses machine-generated works but leaves room for interpretation regarding ownership. Some legal scholars argue that the person who initiates the generation process should hold rights, while others contend that outputs should remain in the public domain.
Training Data and Derivative Works
LLMs trained on copyrighted materials may produce outputs that infringe on original works. The legal concept of transformative use becomes critical here. A mathematical framework for assessing potential infringement could evaluate the similarity between generated text G and source material S:
where gi represents embeddings of generated text segments and sj represents embeddings of source text segments. Values approaching 1 indicate high risk of infringement.
Practical Considerations for Game Developers
Game studios employing LLMs for narrative generation should implement:
- Training Data Audits: Document sources and licenses of all training data
- Output Screening: Use embedding-based similarity detection against known copyrighted works
- Human Oversight: Maintain substantial creative input from human writers to strengthen copyright claims
The table below summarizes key legal positions across jurisdictions:
| Jurisdiction | Human Authorship Requirement | Machine-Generated Work Status |
|---|---|---|
| United States | Strict | No protection without human creative input |
| European Union | Moderate | Potential protection for "computer-generated works" |
| Japan | Flexible | Protection possible for AI-assisted works |
Emerging Solutions and Best Practices
Some organizations are developing technical solutions to address these challenges. The use of differentially private training methods can reduce copyright risks:
where the addition of carefully calibrated noise (ε,δ)-differentially private training helps ensure outputs cannot be traced back to specific training examples. Game developers should also consider implementing blockchain-based attribution systems to track contributions from both human and AI sources.
5.3 Mitigating Harmful or Offensive Outputs
Large language models (LLMs) trained on unfiltered internet data can generate toxic, biased, or harmful content, posing ethical risks in game narrative generation. Advanced mitigation strategies require a multi-layered approach combining pre-training, fine-tuning, and runtime interventions.
Pre-training Data Curation
The foundation for reducing harmful outputs begins with careful dataset construction. Modern approaches use:
- Differential privacy: Adding noise to training examples to prevent memorization of harmful content
- Quality filtering: Removing toxic content using classifiers trained on labeled datasets like CivilComments
- Diversity sampling: Ensuring balanced representation across demographics to reduce bias
Where σ controls the noise magnitude and Δ2 is the L2 sensitivity of the gradient.
Fine-tuning with Human Feedback
Reinforcement learning from human feedback (RLHF) aligns models with human values through:
- Preference modeling: Training reward models on human-labeled comparisons of outputs
- Constitutional AI: Defining explicit rules the model must follow during generation
- Adversarial training: Exposing the model to deliberately harmful prompts during fine-tuning
The reward model optimization can be formalized as:
Where y1 is preferred over y2 for prompt x.
Runtime Safeguards
Real-time filtering mechanisms provide additional protection layers:
| Technique | Implementation | Latency Impact |
|---|---|---|
| Perplexity filtering | Reject outputs with abnormal token probabilities | +2-5ms |
| Classifier chains | Multiple specialized toxicity classifiers in sequence | +10-15ms |
| Dynamic beam search | Pruning harmful continuation paths during generation | +5-8ms |
Evaluation Metrics
Quantifying mitigation effectiveness requires specialized benchmarks:
- Toxicity score: Perspective API's probability of rude/disrespectful content
- Bias magnification: Measuring stereotype reinforcement using templates
- Safety violations: Count of policy-violating responses in adversarial testing
The toxicity-utility trade-off can be visualized as a Pareto frontier where:
Optimal model parameters θ balance these competing objectives.
6. Text-Based Adventure Games with GPT-3
6.1 Text-Based Adventure Games with GPT-3
Architecture of LLM-Driven Text Adventures
Text-based adventure games powered by GPT-3 rely on a stateful interaction loop where the model generates narrative continuations conditioned on player input and game state. The core components include:
- Game State Representation: A JSON-structured object tracking inventory, locations, NPC relationships, and quest progress.
- Prompt Engineering: Multi-shot examples demonstrating desired output format and narrative style.
- Context Window Management: Selective inclusion of relevant game history to overcome token limits.
Where S represents game state, I is player input, and C is the narrative context maintained within the model's attention window.
Dynamic Narrative Generation
GPT-3's strength in open-ended generation enables emergent storytelling through:
- Procedural Plot Generation: The model constructs branching narratives by sampling from possible continuations weighted by coherence scores.
- Character Consistency: Learned embeddings maintain NPC personality traits across interactions.
- World State Propagation: Changes to the environment persist through explicit state updates in subsequent prompts.
Combat System Implementation Example
A physics-informed combat system can be modeled through constrained generation:
Where action probabilities are normalized over valid moves A given state s.
Memory Augmentation Techniques
Overcoming GPT-3's context limitations requires:
- Vector Database Integration: Storing past events as embeddings for semantic retrieval.
- State Delta Compression: Only transmitting changed game state elements between turns.
- Summary Generation: Periodically condensing long narratives into dense representations.
Evaluation Metrics
Quantitative assessment of narrative quality involves:
Where g are generated passages and r are human-written references, with additional metrics for player choice meaningfulness and plot consistency.
Production Considerations
Deploying at scale introduces challenges:
- Latency Optimization: Caching frequent narrative paths and pre-generating likely continuations.
- Content Moderation: Real-time filtering of undesirable outputs through auxiliary classifiers.
- Save/Load Systems: Serializing game state while maintaining narrative continuity upon restoration.
class TextAdventureEngine:
    def __init__(self, llm):
        self.llm = llm
        self.state = {
            'location': 'castle_entrance',
            'inventory': [],
            'flags': {}
        }

    def generate_response(self, player_input):
        prompt = self._build_prompt(player_input)
        response = self.llm.generate(
            prompt,
            max_length=200,
            temperature=0.7,
            top_p=0.9
        )
        self._update_state(response)
        return response['text']
6.2 Open-World RPGs with Dynamic Storylines
Open-world RPGs present a unique challenge for narrative generation due to their non-linear structure and player-driven exploration. Large language models (LLMs) can dynamically generate quests, dialogues, and world events by leveraging probabilistic branching and contextual memory. The key lies in maintaining narrative coherence while allowing for emergent storytelling.
State Tracking and Contextual Memory
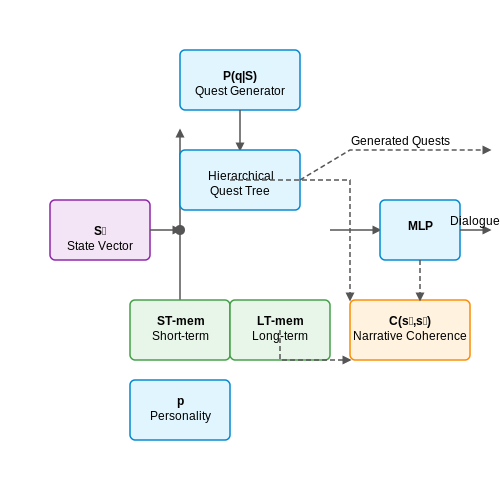
To ensure continuity in an open-world setting, the LLM must maintain a persistent state vector S that encodes:
- Player decisions and their consequences
- Faction reputations and world state changes
- Completed and active quest threads
- NPC relationships and knowledge
This state is updated through a Markov decision process where each player action a triggers a state transition:
where εt represents stochastic elements introduced by the game world. The LLM uses this state to condition its narrative outputs, ensuring that generated content remains consistent with prior events.
Procedural Quest Generation
Quests are constructed through a hierarchical decomposition process:
- The LLM first generates a high-level quest type (e.g., "fetch", "assassination", "diplomacy") based on current world state and player profile
- Sub-tasks are recursively generated with increasing specificity
- Constraints are applied to maintain logical consistency with the game world
The probability distribution over quest types is given by:
where Wq is a learned weight matrix for quest types and MLP is a multi-layer perceptron that processes the state vector.
Dialogue Systems with Persistent Memory
NPC dialogues utilize a dual-memory architecture:
- Short-term memory: Tracks the immediate conversation history using attention mechanisms
- Long-term memory: Maintains persistent knowledge about the player through a differentiable neural database
The dialogue generation function combines these memories with the NPC's personality embedding p:
where [;] denotes concatenation and ST-mem/LT-mem are the memory representations.
Emergent Narrative Structures
Through repeated player interaction, the system can generate complex narrative arcs using:
- Dramatic tension modeling: Adjusts quest difficulty and stakes based on player progression curves
- Butterfly effect tracking: Minor decisions can propagate through the narrative graph to create major consequences
- Procedural theme development: Detects and reinforces emerging story motifs through latent space analysis
The narrative coherence metric C between two story segments is computed as:
where Δt is the in-game time between events and λ controls temporal decay.
Implementation Considerations
Practical deployment requires:
- Efficient sampling techniques to maintain real-time generation speeds
- Fallback mechanisms when generation quality drops below threshold
- Player preference modeling to adapt narrative style and content
- Robust safety filters to prevent harmful or inconsistent outputs
The complete narrative generation pipeline operates at multiple timescales, from immediate dialogue responses to multi-session story arcs, creating the illusion of a living, reactive game world.
Interactive Fiction with Player-Driven Plots
Player-driven narrative generation in interactive fiction requires dynamic adaptation of story arcs based on real-time player choices. Large language models (LLMs) enable this by maintaining a coherent narrative state while allowing branching paths. The core challenge lies in balancing narrative coherence with player agency, which can be formalized as a constrained optimization problem.
State Representation and Narrative Continuity
The narrative state S at time t is represented as a tuple of plot vectors, character states, and world facts:
where Pt represents plot progression, Ct tracks character relationships and attributes, and Wt contains world-state facts. The LLM must update this state while preserving:
- Temporal consistency: Events must follow logical sequence constraints
- Causal coherence: Consequences must properly follow from actions
- Character continuity: Personality and knowledge must remain stable
Dynamic Branching with Constrained Generation
When processing player input at, the narrative generation becomes:
where Φ represents constraints enforcing narrative consistency. This is implemented through:
- Prompt engineering: Structured templates maintaining story context
- Logit biasing: Penalizing inconsistent continuations
- Discriminator models: Secondary classifiers verifying coherence
Implementation Architecture
A robust system requires multiple interacting components:
class NarrativeEngine:
   def __init__(self, llm, memory):
      self.llm = llm  # Base language model
      self.memory = memory  # Vector database of story facts
      self.constraints = [
         TemporalConstraint(),
         CharacterConsistencyConstraint(),
         PlotConstraint()
      ]

   def generate(self, player_action):
      context = self._build_context(player_action)
      output = self.llm.generate(
         prompt=context,
         constraints=self.constraints,
         temperature=0.7
      )
      self._update_state(output)
      return output
Memory-Augmented Generation
The system maintains a differentiable memory matrix M ∈ ℝd×k where d is the embedding dimension and k the number of memory slots. At each step, relevant memories are retrieved through attention:
where q is the query vector derived from current context. This allows the model to:
- Recall character details from earlier interactions
- Maintain plot point continuity
- Respect established world rules
Evaluation Metrics
Quantitative assessment requires specialized metrics beyond traditional NLP measures:
| Metric | Description | Measurement |
|---|---|---|
| Choice Impact | Degree to which decisions alter outcomes | Jensen-Shannon divergence between branches |
| Narrative Cohesion | Logical consistency across time | Human evaluation score (1-5 scale) |
| Player Agency | Perceived meaningfulness of choices | Post-experiment questionnaire |
Case Study: AI Dungeon
The AI Dungeon system demonstrates practical implementation challenges:
- State drift: Narrative veers off-coherence after many steps
- Character bleed: Personas become inconsistent over time
- Constraint tuning: Balancing creativity vs. consistency
Modern solutions employ hybrid architectures combining LLMs with:
- Knowledge graphs for fact tracking
- Discriminator networks for quality control
- Reinforcement learning from human feedback
7. Key Research Papers on LLMs and Narrative Generation
7.1 Key Research Papers on LLMs and Narrative Generation
- PDF Generation of Potential Narratives in Interactive Fiction — us (Bruner and Bruner, 1990) and games can entertain us, teach us, and help us con-nect with one another (Huizinga, 2016). Digital narratives and games have existed for a relatively short time but interactive computer programs have changed the enter-tainment landscape (Alpert, 2007). New areas of research and engineering have been
- Large Language Models and Video Games: A Preliminary Scoping Review — In this paper, we review 76 papers published between 2022 to early 2024 on LLMs and video games, with key focus areas in game AI, game development, narrative, and game research and reviews. Our paper provides an early state of the field and lays the groundwork for future research and reviews on this topic.
- PDF Understanding LLMs for Game NPCs: An exploration of opportunities - DiVA — This thesis explores the integration of large language models (LLMs), particularly through retrieval-augmented generation (RAG), to enhance non-player character (NPC) interactions in gaming environments. The research focuses on dynamically updating game state contexts using the narrative of a movie script as a simulated game environment.
- SceneCraft: Automating Interactive Narrative Scene Generation in ... — Creating engaging interactive story-based experiences dynamically responding to individual player choices poses significant challenges for narrative-centered games. Recent advances in pre-trained large language models (LLMs) have the potential to revolutionize procedural content generation for narrative-centered games. Historically, interactive narrative generation has specified pivotal events ...
- LIGS: Developing an LLM-infused Game System for Emergent Narrative ... — Therefore, research on how emergent responses in game leads dynamic changes in narratives and the game world, as well as the user experience, is yet fully discussed. In this paper, we generate dialogue, action, and resulting narrative progression through LLMs.
- GENEVA: GENErating and Visualizing branching narratives using LLMs — Dialogue-based Role Playing Games (RPGs) require powerful storytelling. The narratives of these may take years to write and typically involve a large creative team. In this work, we demonstrate the potential of large generative text models to assist this process. \\textbf{GENEVA}, a prototype tool, generates a rich narrative graph with branching and reconverging storylines that match a high ...
- LLMs empower players in game design, fostering creativity — Despite this advance, a key challenge with using LLMs for narrative design in games is that, without human intervention, they tend to repeat patterns. We address this in our paper, " Player-Driven Emergence in LLM-Driven Game Narrative ," presented at IEEE CoG 2024, where we explore how LLMs can foster unique forms of creativity when ...
- PDF Exploring the Potential of LLM-based Agents as Dungeon Masters in ... — demanding narratives is not fully established. This thesis delves into the feasibility of deploying an LLM-powered agent as a Dungeon Master (DM) in Dungeons & Dragons (D&D). Centering on a dataset derived from the "Critical Role" series, this research develops an LLM-based agent adept at generating narratives and engaging with players.
- NarrativeGenie: Generating Narrative Beats and Dynamic Storytelling ... — Advances in pretrained large language models (LLMs) have introduced the opportunity to procedurally generate narratives. This paper presents NarrativeGenie, a framework to generate narrative beats as a cohesive, partially ordered sequence of events that shapes narrative progressions from brief natural language instructions.
- (PDF) Empowering Narrative Design in Video Games With Large Language ... — The study aims to develop a methodology for fine-tuning LLMs using synthetic data derived from structured quest information and to evaluate their effectiveness in generating contextually ...
7.2 Recommended Tools and Libraries
- GENEVA: Transforming narrative design for games with LLMs — In this context, we introduce "GENEVA: GENErating and Visualizing branching narratives using LLMs (opens in new tab)," presented at IEEE CoG 2024. This graph-based narrative generation and visualization tool requires a high-level narrative description and constraints, such as the number of different starts, endings, and storylines, as well ...
- PDF Playing Story Creation Games With Large Language Models: Experiments ... — story creation game with OpenAI's GPT-3.5, based on the Tell Tale card game. Tell Tale requires players to generate a brand new and coherent story based on a set of initial story elements, making the game a useful structure for exploring how well GPT-3.5 performs in generating coher-ent and engaging narratives. We show that GPT-3.5 performs ...
- Players, creators, and AI collaborate to build and expand rich game ... — However, the rise of large language models (LLMs) is introducing possibilities for richer, more dynamic narrative experiences and automating some of the more challenging aspects of game creation. Despite this advance, a key challenge with using LLMs for narrative design in games is that, without human intervention, they tend to repeat patterns.
- GENEVA: GENErating and Visualizing branching narratives using LLMs — Dialogue-based Role Playing Games (RPGs) require powerful storytelling. The narratives of these may take years to write and typically involve a large creative team. In this work, we demonstrate the potential of large generative text models to assist this process. \\textbf{GENEVA}, a prototype tool, generates a rich narrative graph with branching and reconverging storylines that match a high ...
- PDF Exploring LLMs and MCTS for Emergent Narrative - ETH Z — NPC engine systems. Furthermore, we will explore the use of LLMs as a game input method and compare them with traditional interaction methods. 1.1. Background Emergent narrative is a fundamental component of generative experiences. It is a type of nar-rative that emerges from the interactions of the player with its environment generating ...
- PDF Generating Automatic Commentary in Video Games using Large Language and ... — footage from cricket games, enabling it to recognize objects in frames and generate simple commentary. Similarly, [3] used com-puter vision to detect UI game elements, triggering pre-engineered inputs to a GPT-3.5 model for generating commentary on a game of League of Legends. In another approach, [4] also used League of
- LLMR: Real-time Prompting of Interactive Worlds using Large Language ... — On the other hand, the rapid advancement in Large Language Models (LLM) like GPT has shown promise in code generation and reasoning [1, 6, 14, 21, 33].An integration of LLMs with a game engine, like Unity [], can enable faster 3D content development and spontaneous user creation, a core element of mixed reality since its inception.In addition, the 3D mixed reality worlds offer rich, spatial ...
- GENEVA uses large language models for interactive game narrative design — Mastering storytelling is essential in various media, and recent advancements in AI, particularly large language models (LLMs), have sparked interest in their ability to generate engaging narratives. This research introduces GENEVA, a tool that utilizes GPT-4 for creating and visualizing branching narratives in graph format.
- Generating Narratives: Writing Coherent Stories with LLMs — The plot element describes narrative stage: e.g. exposition or "a call to adventure". The specific terminology depends on the narrative framework being used. The paper describes two different narrative frameworks: Freytag's pyramid and the hero's journey. Both are ways to break down the narrative progress of stories in a systematic way.
- SceneCraft: Automating Interactive Narrative Scene Generation in ... — style interaction that can play out in a 3D game environ-ment. We use LLMs to generate narrative scenes for the out-line provided by the author and semantically extract from the generated narrative scene emotions and gestures to display programmatically during NPC interactions. Research in natural language processing (NLP) focus-
7.3 Community Resources and Forums
- Grammar and Gameplay-aligned RL for Game Description Generation with LLMs — tuned on Ludii game descriptions as a mutation operator in evolutionary search, aiming to create novel games. The objective of GAVEL differs from our research, which focuses on generating game descriptions that maintain consistency with natural language text. LLMGG [10] proposes a method for generating both rules and levels in VGDL using LLMs.
- \(\ldots \) In Games - Springer — Moreover, LLMs can assist game designers in the creative process, from generating dialogue and storylines to proposing level designs or game mechanics. This capacity to generate content can significantly reduce the time and resources required for game development, enabling creators to focus on refining gameplay and enhancing player engagement.
- Generating Games via LLMs: An Investigation with Video Game Description ... — Instead of generating game content via machine learning in the structured representation, LLMs involve inputting prompts, e.g. a short text, to generate game content. The first ChatGPT for PCG Competition [ 5 ] was held at the 2023 IEEE Conference on Game, which aims at designing prompts that can generate specific Angry Bird levels.
- GENEVA: Transforming narrative design for games with LLMs — In this context, we introduce "GENEVA: GENErating and Visualizing branching narratives using LLMs (opens in new tab)," presented at IEEE CoG 2024. This graph-based narrative generation and visualization tool requires a high-level narrative description and constraints, such as the number of different starts, endings, and storylines, as well ...
- GENEVA: GENErating and Visualizing branching narratives using LLMs — Dialogue-based Role Playing Games (RPGs) require powerful storytelling. The narratives of these may take years to write and typically involve a large creative team. In this work, we demonstrate the potential of large generative text models to assist this process. textbf{GENEVA}, a prototype tool, generates a rich narrative graph with branching and reconverging storylines that […]
- PDF Exploring LLMs and MCTS for Emergent Narrative - ETH Z — NPC engine systems. Furthermore, we will explore the use of LLMs as a game input method and compare them with traditional interaction methods. 1.1. Background Emergent narrative is a fundamental component of generative experiences. It is a type of nar-rative that emerges from the interactions of the player with its environment generating ...
- GitHub - vllm-project/vllm: A high-throughput and memory-efficient ... — vLLM is a fast and easy-to-use library for LLM inference and serving. Originally developed in the Sky Computing Lab at UC Berkeley, vLLM has evolved into a community-driven project with contributions from both academia and industry.. vLLM is fast with: State-of-the-art serving throughput
- PDF Level Generation Through Large Language Models - PCG Workshop — LLMs to generate levels for the game Sokoban, finding that LLMs are indeed capable of doing so, and that their performance scales dramatically with dataset size. We also perform preliminary experi-ments on controlling LLM level generators and discuss promising areas for future work. KEYWORDS procedural content generation, sokoban, language ...
- ABSTRACT - North Carolina State University — Our research further augmented the framework by leveraging LLMs' reasoning ability to craft narrative beats (game events) as a partially ordered sequence of events linking scenes. The developed game levels grant players agency to navigate through divergent paths influenced by their in-game actions and choices.
- (PDF) Empowering Narrative Design in Video Games With Large Language ... — The study aims to develop a methodology for fine-tuning LLMs using synthetic data derived from structured quest information and to evaluate their effectiveness in generating contextually ...