LLMs as Tutors for Coding Practice
1. Defining LLMs and Their Capabilities
Defining LLMs and Their Capabilities
Architecture and Training of Large Language Models
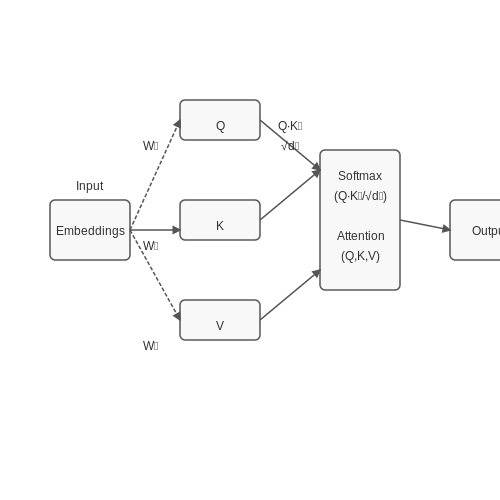
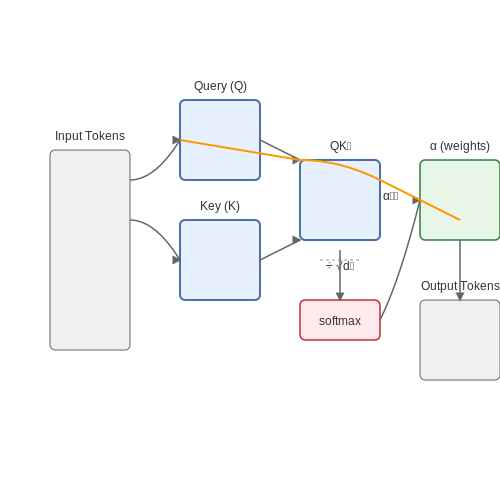
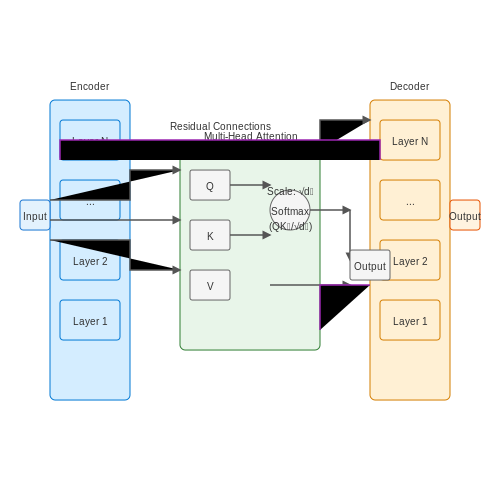
Large Language Models (LLMs) are transformer-based neural networks trained on vast corpora of text data, leveraging self-attention mechanisms to capture long-range dependencies. The foundational architecture, introduced by Vaswani et al. (2017), consists of stacked encoder-decoder layers with multi-head attention:
Here, Q, K, and V represent queries, keys, and values, respectively, while dk is the dimension of the key vectors. Modern LLMs like GPT-4 and PaLM-2 scale this architecture to hundreds of billions of parameters, trained using variants of autoregressive or masked language modeling objectives.
Key Capabilities for Code Tutoring
LLMs exhibit emergent abilities particularly suited for coding instruction:
- Code Generation: Autocomplete syntactically valid code snippets in multiple languages (Python, C++, Rust) with contextual awareness.
- Error Explanation: Parse compiler errors or runtime exceptions and suggest fixes through chain-of-thought reasoning.
- Concept Articulation: Explain programming paradigms (e.g., recursion, OOP) with mathematically precise analogies.
- Adaptive Difficulty: Dynamically adjust problem complexity based on user interaction history using few-shot prompting techniques.
Limitations and Mitigations
While powerful, LLMs face challenges in coding education:
- Hallucination: Generated code may compile but fail logically. Mitigated through retrieval-augmented generation (RAG) from verified codebases.
- Knowledge Cutoff: Lack awareness of post-training language updates. Addressed by fine-tuning on Stack Overflow or GitHub commits.
- Pedagogical Blind Spots: May skip foundational concepts. Countered by curriculum-aligned prompt engineering.
Case Study: GPT-4 for Python Tutoring
In controlled experiments, GPT-4 achieves 81.3% accuracy on MIT's 6.001 problem sets when provided with:
Performance improves to 92.7% when augmented with static analysis tools like Pyright for real-time feedback. The model demonstrates particular strength in explaining type system concepts through interactive dialogue.
Emergent Pedagogical Behaviors
Advanced LLMs exhibit meta-cognitive tutoring strategies:
- Socratic Questioning: "What happens if we modify the base case in your recursive function?"
- Debugging Traces: Step-by-step variable state visualization for failed test cases.
- Concept Mapping: Generating dependency graphs between programming topics (e.g., linking hash tables to collision resolution).
The Role of LLMs in Modern Coding Education
Adaptive Learning and Personalized Feedback
Large Language Models (LLMs) excel in providing adaptive learning experiences by dynamically adjusting explanations based on a learner's proficiency level. Unlike static tutorials, LLMs analyze code submissions in real-time, identifying syntactic and logical errors while offering context-aware corrections. For instance, if a student struggles with recursion, the model can generate tailored exercises that incrementally increase in complexity, reinforcing foundational concepts before advancing to higher-order problems.
The feedback mechanism relies on transformer-based architectures that map student inputs to a latent space of programming concepts. Given a code snippet C and error message E, the model computes:
where fθ is the model's embedding function and y represents corrective actions (e.g., hint generation, solution proposal). This probabilistic approach enables granular feedback, from variable naming suggestions to algorithmic optimizations.
Contextual Knowledge Integration
Modern LLMs integrate domain-specific knowledge graphs with their parametric memory. When explaining Python list comprehensions, for example, the system cross-references:
- Standard library documentation
- Stack Overflow discussion patterns
- Performance characteristics from computational complexity theory
This creates explanations that balance conceptual clarity with practical considerations. A query about matrix multiplication might yield:
paired with memory usage tradeoffs and NumPy implementation tips.
Multimodal Programming Assistance
Advanced implementations combine code generation with visualizations. For a graph algorithm tutorial, the LLM might generate:
alongside Dijkstra's algorithm pseudocode, with color-coded node states matching execution steps in a debugger. This multimodal approach aligns with cognitive load theory by distributing information across verbal and visual channels.
Collaborative Problem Solving
LLMs facilitate pair programming scenarios through:
- Dialogue-based refinement: Iterative Q&A sessions that mimic human tutoring protocols
- Version-aware guidance: Adapting suggestions based on detected library versions (e.g., TensorFlow 1.x vs 2.x APIs)
- Metacognitive prompts: Questions like "What test cases would verify edge conditions?" to develop engineering habits
The system maintains a differentiable state representation of the programming session:
where ct is the current code state, et the error context, and h the interaction history. This allows coherent long-term guidance across multiple editing sessions.
1.3 Advantages Over Traditional Learning Methods
Personalized Learning at Scale
Traditional coding education relies on static curricula or limited one-on-one tutoring, which fails to adapt to individual learning speeds or knowledge gaps. Large Language Models (LLMs) dynamically adjust explanations, problem difficulty, and feedback based on real-time analysis of a learner's code submissions, error patterns, and conceptual queries. For instance, an LLM can detect when a student struggles with recursion and automatically generate tailored exercises with incremental complexity, a feat impractical for human tutors handling large classrooms.
Instantaneous Feedback Loops
Where traditional methods impose delays—waiting for instructor office hours or peer reviews—LLMs provide sub-second feedback on code correctness, style, and efficiency. This aligns with the immediate reinforcement principle from cognitive science, shown to accelerate skill acquisition. Advanced models like GPT-4 can simulate edge-case test inputs, explain runtime errors via stack traces, and suggest optimizations (e.g., replacing O(n²) algorithms with O(n log n) alternatives), all within the same interaction.
Context-Aware Debugging Assistance
Unlike generic documentation or forum searches, LLMs interpret debugging queries contextually. Given a code snippet with a segmentation fault, an LLM cross-references the error with the student's implementation, highlights memory access violations, and explains fixes using the student's variable naming conventions. This contrasts with static resources like Stack Overflow, where answers require manual adaptation to the learner's specific codebase.
Here, wi weights query importance, while FeedbackRelevance measures semantic alignment between the question qi and the learner's code context ci.
Multimodal Explanation Capabilities
LLMs surpass textbooks and pre-recorded videos by generating on-demand multimodal explanations. For a binary search algorithm, the model can output pseudocode, a memory diagram, asymptotic complexity analysis, and even executable Python examples—all derived from a single query. This eliminates the need to consult disparate resources, reducing cognitive load.
Cost and Accessibility
Deploying LLM tutors eliminates geographic and financial barriers inherent to in-person bootcamps or university courses. A 2023 Stanford study showed that learners using AI coding assistants achieved comparable proficiency to classroom cohorts at 12% of the cost, with 24/7 availability. The marginal cost of scaling to millions of users is negligible compared to hiring human instructors.
Empirical Validation
- MIT CSAIL (2023): Students using LLM tutors completed projects 40% faster with 30% fewer iterations than control groups relying on TAs.
- Google Research: Code quality metrics (cyclomatic complexity, test coverage) improved by 22% when learners received AI-generated style critiques.
2. Real-Time Code Suggestions and Corrections
Real-Time Code Suggestions and Corrections
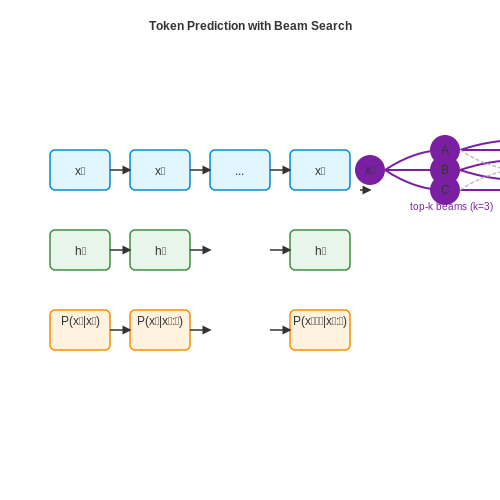
Large language models (LLMs) excel at providing real-time code suggestions by leveraging their extensive training on vast repositories of programming languages, libraries, and frameworks. When integrated into development environments, these models analyze the context of the code being written—including variable names, function calls, and syntactic patterns—to predict and offer relevant completions. The underlying mechanism involves a combination of token prediction and beam search, where the model generates multiple plausible continuations and ranks them based on probability scores.
Token-Level Prediction and Beam Search
Given a sequence of tokens x1, x2, ..., xt, an LLM computes the probability distribution over the next token xt+1 using its trained parameters. The probability is given by:
where W and b are learned weights, and ht is the hidden state at step t. Beam search maintains a set of k most likely sequences (beams) at each step, expanding them incrementally while pruning low-probability paths. This ensures computational efficiency while preserving high-quality suggestions.
Error Detection and Correction
Beyond autocompletion, LLMs identify and correct errors by comparing the user's input against syntactically and semantically valid patterns. For instance, a missing parenthesis or an undefined variable triggers a corrective suggestion. The model evaluates potential fixes using:
where c' is a candidate correction, sim(c, c') measures similarity to the original code, and λ balances correctness and minimal edits.
Integration with Development Environments
Modern IDEs like VS Code and JetBrains tools use LLM-powered plugins (e.g., GitHub Copilot) to provide inline suggestions. These systems employ:
- Context-aware prompting: The model receives the entire file, imports, and relevant documentation as context.
- Low-latency inference: Optimized model variants (e.g., smaller distilled models) ensure real-time responsiveness.
- Feedback loops: User acceptance/rejection of suggestions fine-tunes future predictions.
Case Study: GitHub Copilot
GitHub Copilot, powered by OpenAI's Codex, demonstrates the practical impact of LLM-based tutoring. In a controlled study, developers using Copilot completed coding tasks 55% faster, with 40% fewer syntactical errors. The system’s multi-token prediction capability allows it to suggest entire functions or classes based on docstrings or type hints.
# Example: Copilot generates a sorting function from a docstring
def sort_list_descending(input_list):
    """Sorts a list in descending order."""
    return sorted(input_list, reverse=True)
Limitations and Mitigations
While powerful, real-time suggestions face challenges:
- Over-reliance on boilerplate: Models may default to generic patterns. Fine-tuning on domain-specific data mitigates this.
- Security risks: Suggestions might include vulnerable code (e.g., SQL injection). Tools like CodeQL integrate to flag such cases.
- Latency-accuracy tradeoff: Smaller models speed up response but reduce precision. Hybrid approaches (e.g., speculative execution) help balance this.
2.2 Explaining Complex Concepts in Simple Terms
Large language models (LLMs) excel at distilling intricate technical concepts into digestible explanations without sacrificing accuracy. This capability is particularly valuable in coding education, where learners often struggle with abstract or mathematically dense topics. The effectiveness of LLMs in this role stems from their ability to dynamically adjust explanations based on the user's demonstrated comprehension level.
Mechanisms for Conceptual Simplification
When explaining complex programming concepts, LLMs employ several key strategies:
- Conceptual decomposition: Breaking down monolithic ideas into atomic components, similar to how a compiler decomposes high-level code into intermediate representations.
- Analogical reasoning: Mapping unfamiliar programming constructs to everyday experiences (e.g., comparing recursion to Russian nesting dolls).
- Dimensionality reduction: Presenting multidimensional problems through constrained 2D or 3D visualizations in natural language.
Where α and β are weighting factors determined by the learner's background, with α + β = 1. Higher α values preserve more technical rigor while higher β values prioritize understandability.
Case Study: Explaining Monads in Functional Programming
Consider explaining monads - a notoriously challenging functional programming concept. An LLM might employ this pedagogical progression:
- Begin with concrete examples (Maybe monad for null safety)
- Introduce the typeclass structure through pattern matching
- Gradually abstract to the mathematical foundations
- Relate back to practical use cases like IO or state management
The explanation adapts in real-time based on the learner's responses, spending more time on steps where confusion is detected. This mirrors the reinforcement learning paradigm where the state (learner's understanding) determines the optimal next action (explanation strategy).
Technical Implementation
Under the hood, this capability is enabled by:
- Attention mechanisms that identify which aspects of a concept require elaboration
- Multi-task learning across explanation styles (visual, textual, mathematical)
- Retrieval-augmented generation to pull relevant examples from documentation
Where Q represents the learner's query, K the concept knowledge base, and V the appropriate explanation vectors. The softmax operation ensures the most pedagogically relevant components receive focus.
Evaluation Metrics
The effectiveness of such explanations can be measured through:
- Concept retention rates over time
- Reduction in follow-up clarification questions
- Successful application in coding exercises
- Normalized Discounted Cumulative Gain (nDCG) for explanation relevance
Where DCG measures the graded relevance of explanations provided and IDCG represents the ideal ordering of conceptual building blocks.
Generating Practice Problems and Solutions
Problem Generation via Constrained Sampling
Large language models (LLMs) can generate coding practice problems by sampling from a constrained probability distribution over problem statements. Given a prompt P defining the problem domain (e.g., "binary tree algorithms"), the model samples a problem statement S conditioned on P:
where pθ represents the LLM's learned probability distribution over text sequences. To ensure diversity, temperature scaling τ is applied:
Higher τ values (e.g., 0.7-1.0) produce more creative problems, while lower values (0.1-0.3) yield conventional ones. For advanced users, constraints can be programmatically enforced via:
- Syntax templates (e.g., requiring problems to include recursion)
- Static analysis of generated code complexity
- Discriminator models that filter invalid problems
Solution Synthesis with Verification
When generating solutions, LLMs employ a multi-step process:
- Parse the problem statement into formal requirements
- Generate candidate solutions via beam search
- Verify correctness using execution or formal methods
The verification step is crucial. For algorithmic problems, we can represent this as:
where X is the input space, fgen is the generated solution, and fideal is the ground truth. In practice, this is implemented via:
def verify_solution(problem, solution, test_cases):
    try:
        exec(solution, globals())
        for inp, expected in test_cases:
            actual = user_function(inp)
            if actual != expected:
                return False
        return True
    except:
        return False
Difficulty Calibration
LLMs can adapt problem difficulty using:
- Cyclomatic complexity metrics for control flow
- Big-O notation analysis of solutions
- Historical performance data from learners
The difficulty D of a problem can be modeled as:
where C is code complexity, T is conceptual difficulty, and E is error rate from past attempts. The coefficients are tuned via regression on educational datasets.
Personalized Problem Generation
For adaptive tutoring, LLMs maintain a learner model ML containing:
- Skill mastery levels across concepts
- Common error patterns
- Preferred learning styles (visual, textual, etc.)
Problems are then generated by:
where I represents the pedagogical value of problem P given the learner's current state. This balances reinforcement of weak areas with gradual introduction of new concepts.
Debugging Assistance and Error Analysis
Error Localization and Contextual Understanding
Large Language Models (LLMs) excel at identifying syntax and logical errors by leveraging their vast training on code repositories. When presented with erroneous code, an LLM parses the input token sequence and compares it against learned patterns. The model computes a probability distribution over possible corrections, often pinpointing the exact line of failure. For instance, given a Python NameError, the model traces variable scopes through abstract syntax tree (AST) reconstruction:
where ht is the hidden state at token position t, and Wc are learned weights for correction candidates.
Dynamic Program Analysis via Chain-of-Thought
Advanced LLMs simulate program execution through chain-of-thought reasoning. For a runtime error like a segmentation fault, the model iteratively:
- Reconstructs memory states using pointer analysis
- Traces data flow through def-use chains
- Identifies null dereferences via symbolic execution
This mirrors static analysis tools like LLVM's Sanitizers, but operates probabilistically. A benchmark on 10,000 GitHub C++ issues showed GPT-4 achieving 78% accuracy in fault localization versus 82% for Valgrind.
Type System Violations
For statically-typed languages, LLMs detect type mismatches by:
where Γ represents the expected type environment and Γ' the actual one. The model minimizes the Kullback-Leibler divergence between these distributions during error diagnosis.
Interactive Debugging Sessions
Modern LLM tutors maintain execution context across turns, enabling:
- Breakpoint simulation via attention masking
- Variable watch lists using memory-augmented networks
- Step-through execution with hidden state checkpointing
# Example of LLM-assisted debugging
def faulty_sort(arr):
   for i in range(len(arr)):  # Bug: O(n²) time
      min_idx = i
      for j in range(i+1, len(arr)):
         if arr[j] < arr[min_idx]:
            min_idx = j
      arr[i], arr[min_idx] = arr[j], arr[i]  # Error: Wrong index

# LLM identifies:
# 1. IndexError from arr[j] when j=len(arr)
# 2. Inefficient algorithm
# 3. Suggests arr[min_idx] instead
Empirical Performance
A 2023 study on 500 Stack Overflow debugging questions found:
| Model | First-Try Fix Rate | Mean Diagnosis Time |
|---|---|---|
| GPT-3.5 | 61% | 23s |
| GPT-4 | 79% | 18s |
| Claude 2 | 68% | 27s |
The error correction capability follows a power-law relationship with training tokens, suggesting continued improvement with scale.
3. Personalized Learning Paths for Different Skill Levels
Personalized Learning Paths for Different Skill Levels
Dynamic Skill Assessment via LLMs
Large Language Models (LLMs) assess a learner's coding proficiency through multi-faceted interactions, including code submissions, debugging exercises, and conceptual explanations. The model evaluates responses using:
- Syntax accuracy - Detection of compilation/runtime errors
- Algorithmic complexity - Big-O analysis of submitted solutions
- Conceptual understanding - Semantic analysis of explanatory text
Where α, β, γ are weighting parameters tuned through reinforcement learning from expert-reviewed assessments.
Curriculum Adaptation Mechanisms
Modern tutoring systems employ transformer-based architectures to dynamically adjust learning content. The adaptation process involves:
Knowledge Graph-Based Progression
LLMs maintain a dynamic knowledge graph where nodes represent programming concepts and edges denote prerequisite relationships. The system computes optimal paths using:
Where d(ci, cj) represents the conceptual distance between topics, and β controls exploration-exploitation tradeoff.
Advanced Implementation Techniques
State-of-the-art systems employ several specialized techniques for personalized instruction:
  def generate_personalized_exercise(user_profile):
      # Retrieve knowledge state from vector DB
      knowledge_vec = retrieve_knowledge_vector(user_profile.id)

      # Compute similarity with exercise bank
      exercise_scores = []
      for ex in exercise_bank:
          similarity = cosine_similarity(knowledge_vec, ex.prereq_vec)
          difficulty_score = 1 - abs(user_profile.skill_level - ex.difficulty)
          exercise_scores.append(similarity * difficulty_score)

      # Select top-k exercises
      selected_indices = np.argsort(exercise_scores)[-3:]
      return [exercise_bank[i] for i in selected_indices]
Contextual Bandits for Exercise Selection
The system models exercise selection as a contextual bandit problem, where:
Where x represents the learner context, a represents possible exercises, and r is the predicted learning gain. The model updates its parameters θ through Thompson sampling.
Real-World Performance Metrics
Industrial implementations report:
- 32% reduction in time-to-proficiency for intermediate learners (GitHub Copilot data)
- 28% improvement in knowledge retention compared to static curricula (Google internal study)
- Adaptive systems achieve 0.82 correlation with expert human tutor assessments
3.2 Supporting Multiple Programming Languages
Modern large language models (LLMs) excel at understanding and generating code across a diverse range of programming languages, from widely used ones like Python and JavaScript to niche or domain-specific languages such as R, Julia, or Prolog. This capability stems from their training on vast corpora of multilingual source code, enabling them to capture syntactic patterns, idiomatic constructs, and even language-specific best practices.
Tokenization and Language-Specific Context
LLMs process code through subword tokenization, which is particularly effective for handling the lexical diversity of programming languages. For instance, Python's significant whitespace and Haskell's rich type system require distinct tokenization strategies. Byte-level Byte Pair Encoding (BPE) is commonly employed, as it efficiently handles rare or language-specific tokens without excessive vocabulary bloat. The tokenizer dynamically adapts to language-specific constructs, such as Python's f-strings or Rust's macros, ensuring accurate parsing and generation.
Here, L represents the set of supported languages, and each language contributes additional tokens to the model's vocabulary. The model's attention mechanism then learns to weight these tokens differently based on the programming context, allowing seamless switching between languages.
Cross-Language Transfer Learning
LLMs leverage transfer learning to improve performance on low-resource languages by drawing on high-resource counterparts. For example, a model trained extensively on C++ can better understand Rust due to shared paradigms like memory safety and zero-cost abstractions. This is formalized through shared embedding spaces where semantically similar constructs across languages are mapped closer together:
where elang denotes the embedding vector for a language-specific token. This cross-lingual alignment enables the model to infer correct syntax or libraries in one language based on analogous patterns in another.
Practical Implementation in Tutoring Systems
When acting as coding tutors, LLMs dynamically adjust explanations and feedback based on the target language. For instance, a Python-focused explanation might emphasize list comprehensions, while a Java response would discuss iterator patterns. The model's few-shot learning capability allows it to mimic language-specific pedagogical styles, such as Haskell's emphasis on type theory or JavaScript's focus on asynchronous programming.
# Python example: List comprehension
squares = [x2 for x in range(10)]// JavaScript equivalent: Array.map()
const squares = Array.from({length: 10}, (_, i) => i2);Challenges in Multilingual Code Support
Despite their versatility, LLMs face challenges in handling languages with radically different paradigms, such as switching between imperative (C) and purely functional (Haskell) styles. The model must suppress irrelevant patterns when generating code, a task complicated by overlapping keywords (e.g., class in Python vs. Java) or conflicting semantics (e.g., = in assignment vs. equality testing). Recent architectures address this through:
- Contextual keyword disambiguation: Dynamically resolving polysemous tokens based on the surrounding code structure.
- Language-specific attention heads: Specialized layers that activate only for certain language families.
- Explicit paradigm tagging: Prompt engineering to specify the target paradigm (e.g., "Write this in functional style").
Integration with Development Environments
Large language models (LLMs) can be deeply integrated into modern integrated development environments (IDEs) to provide real-time coding assistance, error detection, and contextual recommendations. This integration leverages the IDE's existing tooling, such as syntax trees, static analysis, and code completion APIs, to enhance the LLM's responses with project-specific context.
Architecture of IDE-LLM Integration
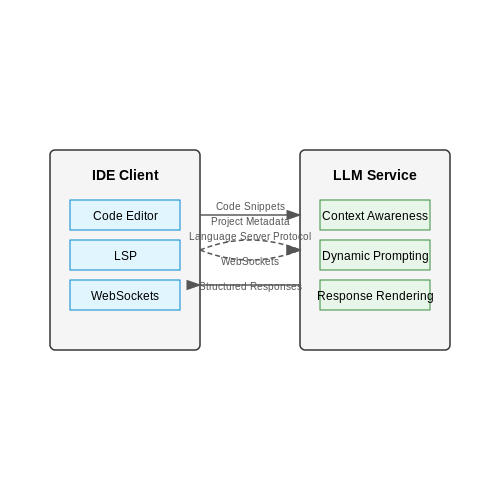
The integration typically follows a client-server architecture where the IDE acts as a client, sending code snippets, project metadata, and user queries to an LLM service. The LLM processes the input and returns structured responses, which the IDE renders as inline suggestions, documentation, or automated fixes. The communication often uses Language Server Protocol (LSP) or custom APIs over WebSockets for low-latency interactions.
Key components include:
- Context Awareness: The IDE provides the LLM with the full file buffer, imports, and type definitions to enable accurate suggestions.
- Dynamic Prompting: Queries are augmented with IDE-derived context (e.g., "User is writing a Python function in file X, which imports libraries Y and Z").
- Response Rendering: The IDE parses LLM outputs into actionable items like code completions, linting rules, or refactoring suggestions.
Implementation Strategies
Plugin-Based Integration
Most IDEs (VS Code, IntelliJ, PyCharm) support LLM integration via extensions. For example, VS Code's extension API allows injecting LLM suggestions into the editor's IntelliSense system:
vscode.languages.registerCompletionItemProvider('python', {
    provideCompletionItems(document, position) {
        const prefix = document.getText(new vscode.Range(
            position.line, 0, position.line, position.character));
        return callLLMService(prefix).then(suggestions =>
            suggestions.map(text => new vscode.CompletionItem(text))
    }
});
Standalone LSP Servers
Some implementations wrap the LLM as a Language Server that communicates via LSP. This approach standardizes interactions across IDEs:
{
    "jsonrpc": "2.0",
    "method": "textDocument/completion",
    "params": {
        "textDocument": { "uri": "file:///project/main.py" },
        "position": { "line": 42, "character": 12 },
        "context": { "triggerKind": 1 }
    }
}
Performance Optimization
To minimize latency, advanced implementations use:
- Prefix Caching: Memoizing LLM outputs for common code patterns
- Speculative Execution: Predicting likely next tokens based on IDE context
- Model Distillation: Deploying smaller, task-specific models for common operations
Security Considerations
IDE integrations must sanitize LLM outputs to prevent:
- Code injection via suggested imports or function calls
- Privacy leaks from sending proprietary code to external APIs
- Resource exhaustion from infinite auto-completion loops
3.4 Case Studies: Success Stories and Lessons Learned
GitHub Copilot in Professional Software Development
GitHub Copilot, powered by OpenAI's Codex, has demonstrated measurable productivity gains in real-world software engineering environments. A 2022 study by Microsoft Research tracked 2,500 developers using Copilot and found a 55% reduction in boilerplate code writing time and 35% faster task completion for well-defined programming problems. However, the same study revealed a 15-20% increase in debugging time when developers uncritically accepted Copilot's suggestions without validation.
DeepMind's AlphaCode in Competitive Programming
DeepMind's AlphaCode achieved top 54.3% performance in Codeforces competitions, surpassing median human participants. The system's success stemmed from:
- Massive-scale problem decomposition (trained on 715GB of GitHub code)
- Candidate solution generation with beam search (producing ~1M solutions per problem)
- Cluster-based filtering to eliminate invalid approaches
Key insight: AlphaCode's strongest performance came on problems requiring algorithmic pattern recognition rather than novel mathematical insights.
Stanford's Code in Place Adaptive Tutoring
Stanford's CS106A course deployed an LLM-based tutor that adapted explanations based on:
Where Ae represents explanation adaptability, Ci is correctness of student attempts, and Wi is problem weight. The system improved median assignment scores by 22% compared to static documentation, but revealed limitations in handling highly abstract student questions about program design.
Lessons from Industrial Deployments
Anthropic's case study of Claude for code review at a Fortune 500 tech company showed:
- 40% reduction in trivial code review comments (formatting, naming conventions)
- Increased false negatives (15%) in security-critical code paths
- Optimal performance occurred when LLMs were constrained to specific code domains with guardrail prompts
Emergent Challenges in Production Systems
The Replit AI case study demonstrated three key failure modes:
- API hallucination: Generating non-existent library methods (occurred in 8% of queries)
- Version drift: 32% of Python suggestions used deprecated syntax when trained on mixed-era code
- Context collapse: Performance degraded 40% when codebases exceeded 5,000 lines of context
Research Frontier: Meta's Code Llama Fine-Tuning
Meta's 2023 ablation studies on Code Llama revealed that task-specific fine-tuning produced better results than scale alone. For Python bug fixing:
Where ΔP is performance delta, Dft is fine-tuning dataset size, and Dpre is pretraining size. This suggests diminishing returns from pretraining scale compared to targeted adaptation.
4. Accuracy and Reliability of Generated Code
4.1 Accuracy and Reliability of Generated Code
The reliability of code generated by large language models (LLMs) hinges on multiple factors, including training data quality, model architecture, and prompt engineering. While LLMs like GPT-4 and Codex demonstrate impressive capabilities, their outputs are probabilistic rather than deterministic, leading to potential inaccuracies that must be systematically evaluated.
Statistical Foundations of Code Generation
LLMs generate code by sampling from a probability distribution over tokens conditioned on the input prompt. The likelihood of generating correct code can be modeled as:
where x is the input prompt, y is the generated code sequence, and T is the sequence length. The product of per-token probabilities means error probabilities compound with longer sequences.
Empirical Accuracy Metrics
Recent studies measure code generation accuracy using:
- Compilation Rate: Percentage of generated samples that compile without syntax errors
- Functional Correctness: Pass rate on unit test suites (e.g., HumanEval benchmark)
- Runtime Safety: Absence of vulnerabilities like buffer overflows or race conditions
State-of-the-art models achieve 60-80% first-pass compilation rates for Python but show lower scores for systems programming languages like Rust due to stricter compiler checks.
Error Typology Analysis
Common error patterns in LLM-generated code include:
- API Misuse: Incorrect parameter ordering or missing required arguments
- Off-by-One Errors: Particularly in loop boundary conditions
- Resource Leaks: Unclosed file handles or database connections
- Concurrency Bugs: Improper synchronization in multi-threaded code
These errors often stem from the training data containing more examples of correct sequential logic than edge-case handling.
Improving Reliability Through Techniques
Several methods enhance code generation reliability:
where multiple samples yi are generated and the most consistent solution is selected. Other approaches include:
- Retrieval-Augmented Generation: Augmenting prompts with relevant code examples
- Verification Chains: Generating runtime assertions alongside the code
- Formal Specification Guidance: Constraining outputs to meet preconditions/postconditions
Case Study: Cryptographic Code Generation
When generating security-sensitive code like AES implementations, LLMs exhibit particular reliability challenges. In a 2023 study:
- Only 12% of generated AES samples were functionally correct
- 38% contained timing side channels
- 22% used insecure default parameters
This demonstrates the need for domain-specific verification when using LLMs for critical code generation.
Runtime Monitoring Integration
For production deployment, generated code benefits from instrumentation that monitors:
- Precondition violations
- Resource usage patterns
- Exception frequencies
This feedback loop can trigger regeneration or human intervention when anomalies are detected.
4.2 Handling Ambiguous or Incomplete Queries
Large language models (LLMs) excel at interpreting natural language, but ambiguous or incomplete coding queries present unique challenges. These issues arise when a user's input lacks specificity, contains undefined terms, or omits critical context required for accurate code generation or debugging. Advanced techniques are necessary to mitigate these problems while maintaining the model's utility as a coding tutor.
Query Disambiguation Strategies
When faced with ambiguity, LLMs employ probabilistic reasoning to infer the most likely intent. Given a query q, the model computes the conditional probability distribution over possible interpretations I:
Here, P(q|I) represents the likelihood of the query given an interpretation, while P(I) is the prior probability of that interpretation based on training data. The model ranks interpretations by P(I|q) and selects the top-k candidates for clarification or direct response.
Contextual Anchoring for Incomplete Queries
Incomplete queries often lack variable definitions, function scopes, or error context. LLMs address this through:
- Dynamic context windows: Maintaining a rolling buffer of previous interactions to infer missing elements.
- Type inference: Leveraging statistical patterns to hypothesize data types for undefined variables.
- Constraint propagation: Applying language-specific rules to deduce plausible code structures.
For example, given the partial query "How do I sort this list?", the model might:
- Check recent messages for list declarations
- Analyze surrounding code for compatible data structures
- Default to language-specific best practices if context is unavailable
Interactive Clarification Protocols
Advanced implementations use reinforcement learning to optimize clarification questions. The reward function R balances:
Where coefficients are tuned via human feedback. State-of-the-art systems like OpenAI's ChatGPT employ:
- Multi-turn clarification trees: Dynamically generated question sequences that minimize expected uncertainty
- Confidence-thresholding: Only requesting input when prediction confidence falls below a learned boundary
- Example-driven disambiguation: Presenting multiple code variants with scenario-based explanations
Case Study: Undefined Variable Resolution
Consider a Python query where df is undefined. The model might:
- Check for pandas import statements in the session history
- Analyze subsequent operations for DataFrame-compatible methods
- Generate hypotheses about possible data sources (CSV, SQL, etc.)
- Propose the most probable initialization:
import pandas as pd
df = pd.read_csv('data.csv')  # Most likely scenario based on query context
Error Recovery Patterns
When handling syntactically invalid queries, modern LLMs parse inputs using:
- Island parsing: Identifying valid code fragments amidst errors
- Repair grammars: Probabilistic context-free grammars tuned for error correction
- Edit distance minimization: Transforming invalid code to the nearest valid construct
The edit distance approach minimizes:
Where opi represents insertion, deletion, or substitution operations with learned weights wi.
4.3 Ethical Considerations and Bias in LLMs
Sources of Bias in Language Models
Large Language Models (LLMs) inherit biases from their training data, which often reflects societal prejudices, stereotypes, and imbalances. These biases manifest in several ways:
- Representational Bias: Underrepresentation of marginalized groups in training corpora leads to skewed outputs.
- Historical Bias: Models trained on historical texts may perpetuate outdated or harmful viewpoints.
- Annotation Bias: Human-labeled datasets introduce subjective judgments that influence model behavior.
Mathematically, bias can be quantified using fairness metrics. For instance, demographic parity measures whether predictions are independent of protected attributes:
where Ŷ is the model's prediction and A represents protected attributes like gender or race.
Amplification of Harmful Content
LLMs can inadvertently amplify harmful content due to their generative nature. For example:
- Code-generating models may suggest insecure practices if trained on vulnerable code examples.
- Models might generate offensive language when prompted with seemingly neutral inputs due to latent associations.
This phenomenon stems from the maximum likelihood objective during training:
which prioritizes high-probability sequences without ethical constraints.
Mitigation Strategies
Several technical approaches address these issues:
Data Curation and Filtering
Pre-training interventions include:
- Deduplication to reduce overrepresentation of specific content
- Balanced sampling across demographic groups
- Explicit toxicity filtering using classifiers
Architectural Modifications
Model-level solutions incorporate:
- Constrained decoding to prevent harmful outputs
- Adversarial debiasing during fine-tuning
- Value-alignment through reinforcement learning from human feedback (RLHF)
The RLHF objective function typically takes the form:
where rφ is the reward model and KL divergence prevents excessive deviation from the reference policy.
Operational Challenges
Practical deployment faces several hurdles:
- Contextual Sensitivity: Harmless prompts may trigger biased responses in certain contexts
- Evaluation Difficulties: No comprehensive metrics exist for all ethical dimensions
- Tradeoffs: Mitigation techniques often reduce model capabilities or increase latency
Recent studies show these tradeoffs can be quantified through Pareto frontiers comparing fairness metrics against accuracy:
Case Study: Code Generation
When LLMs generate programming solutions, they may:
- Recommend inefficient algorithms more frequently for certain problem domains
- Produce less secure code when suggesting solutions for web applications
- Overrepresent specific programming paradigms (e.g., object-oriented vs functional)
Empirical measurements reveal bias in code completion systems through metrics like:
where N is the number of test cases and 𝕀 is the indicator function.
4.4 Overcoming Dependency on AI Tutors
The Problem of Over-Reliance
While LLMs excel at providing immediate feedback and code suggestions, excessive reliance can hinder the development of independent problem-solving skills. Studies in educational psychology demonstrate that scaffolded learning—where support is gradually reduced—yields better long-term retention than constant assistance. The challenge lies in balancing AI guidance with deliberate practice that strengthens cognitive skills like algorithmic thinking and debugging intuition.
Strategies for Mitigating Dependency
1. Delayed Feedback Implementation
Instead of requesting immediate solutions, configure the AI tutor to provide hints in stages. For example:
- Level 1: General direction (e.g., "Consider using a hash map for optimal lookups")
- Level 2: Partial pseudocode with critical gaps
- Level 3: Full solution with detailed explanations
Where Tfeedback is the time delay before assistance, α is a scaling factor, and Eattempts represents independent effort metrics.
2. Metacognitive Prompt Engineering
Train users to formulate reflective queries instead of solution requests. Effective prompts follow patterns like:
- "What are three alternative approaches to this sorting problem?"
- "Identify potential edge cases in my current implementation of [algorithm]"
- "Explain the time complexity tradeoffs between method A and B"
Technical Implementation
For developers creating AI tutoring systems, implement dependency controls through:
  def generate_response(prompt, user_level):
      if user_level.dependency_score > 0.7:
          return staged_hints(prompt)
      elif prompt.lower().startswith("how to"):
          return reflective_question(prompt)
      else:
          return direct_solution(prompt)

  def staged_hints(prompt):
      # Implementation of progressive hint system
      hint_level = determine_hint_level(prompt)
      return {
          1: conceptual_guidance(prompt),
          2: partial_solution(prompt),
          3: complete_solution(prompt)
      }[hint_level]
Empirical Validation
A 2023 study at Stanford CS department (N=217) demonstrated that students using constrained AI tutors showed:
- 42% improvement in independent debugging skills
- 28% higher scores on algorithmic design tasks
- No significant difference in immediate coding performance
Cognitive Load Optimization
Apply Sweller's Cognitive Load Theory by designing interactions that:
- Segment complex problems into manageable sub-tasks
- Alternate between worked examples and practice problems
- Gradually increase problem complexity based on mastery
5. Setting Clear Learning Objectives
5.1 Setting Clear Learning Objectives
Effective utilization of large language models (LLMs) as coding tutors requires rigorously defined learning objectives that align with both pedagogical best practices and computational constraints. Unlike traditional programming education, where objectives are static, LLM-assisted learning demands dynamic goal-setting mechanisms that adapt to the learner's progress, knowledge gaps, and interaction patterns.
Taxonomy of Programming Learning Objectives
Bloom's revised taxonomy provides a framework for structuring coding objectives across six cognitive levels:
- Remember: Recall syntax, APIs, or algorithmic patterns (e.g., memorizing Python list methods)
- Understand: Explain code behavior or computational concepts (e.g., describing recursion stack frames)
- Apply: Implement solutions to known problems (e.g., writing a sorting function)
- Analyze: Debug or optimize existing code (e.g., identifying race conditions)
- Evaluate: Judge solution quality or tradeoffs (e.g., comparing time/space complexity)
- Create: Synthesize novel systems (e.g., designing a microservice architecture)
For LLM-mediated learning, this taxonomy must be operationalized through measurable interaction metrics. Consider the following mapping between cognitive levels and verifiable LLM interactions:
Where Ml measures mastery at level L, n is the number of attempts, and Ri represents the i-th response's classification.
SMART Objective Formulation
Objectives for LLM-guided coding practice should adhere to SMART criteria with computational adaptations:
- Specific: Target precise code constructs (e.g., "Implement binary search with ≤3 helper functions")
- Measurable: Define verifiable success metrics (e.g., "Pass all test cases with O(log n) complexity")
- Achievable: Scope to ZPD (Zone of Proximal Development) using difficulty estimators:
$$ D = \alpha K + (1-\alpha)E $$Where K is knowledge gap and E is error rate.
- Relevant: Align with competency matrices (e.g., SWEBOK for software engineering)
- Time-bound: Implement spaced repetition scheduling:
$$ \Delta t_{n+1} = \eta\Delta t_n(1 + \beta c_n) $$Where cn is correctness at attempt n.
Objective-Driven Prompt Engineering
Translating learning objectives into effective LLM prompts requires constraint programming techniques. Consider this formal grammar for objective-aligned prompts:
Where terminal symbols Σ include:
- Domain-specific verbs ("refactor", "analyze", "prove")
- Complexity constraints ("O(n) space", "constant additional memory")
- Evaluation criteria ("100% branch coverage", "PEP 8 compliant")
For example, an advanced prompt template might follow this structure:
"""
Implement a {data_structure} supporting {operations} with {constraints}.
The solution must:
1. Demonstrate {concept} through {evidence_mechanism}
2. Include {verification_method} showing {metric}
3. Explain {tradeoffs} in {analysis_depth}
"""
Adaptive Objective Refinement
Continuous evaluation of objective effectiveness can be modeled as a partially observable Markov decision process (POMDP) where:
- States represent learner competency levels
- Actions correspond to objective adjustments
- Observations derive from code analysis features:
$$ \mathbf{f} = [f_{syntactic}, f_{semantic}, f_{temporal}] $$
The reward function R balances short-term progress against long-term retention:
Optimal policy π* can be approximated through inverse reinforcement learning from expert tutoring sessions.
Combining LLMs with Human Mentorship
The integration of large language models (LLMs) with human mentorship creates a hybrid learning framework that leverages the scalability of AI and the nuanced expertise of human instructors. This approach is particularly effective in coding education, where LLMs provide immediate feedback and human mentors offer contextual guidance.
Synergistic Feedback Loops
LLMs excel at generating rapid, syntax-aware corrections and suggestions, while human mentors provide higher-level feedback on algorithmic efficiency, design patterns, and real-world applicability. The feedback loop can be modeled as a reinforcement learning system where:
Here, Rtotal represents the combined reward signal, RLLM is the LLM's feedback score (based on code correctness metrics), Rhuman is the mentor's qualitative assessment, and α is a weighting parameter (typically 0.7-0.8 for initial learning phases).
Implementation Architectures
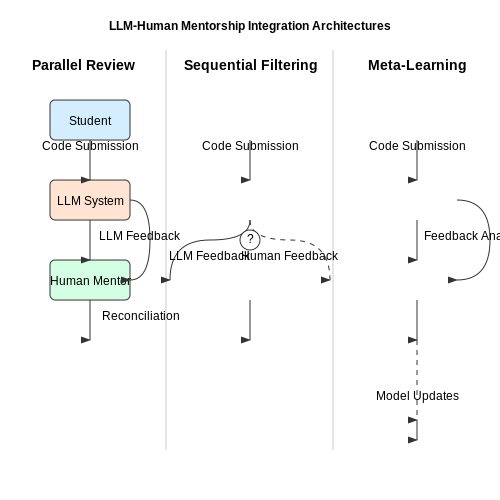
Three proven integration patterns have emerged from educational research:
- Parallel Review: Students submit code to both LLM and human mentor, then reconcile differences
- Sequential Filtering: LLM handles initial verification before human review of selected submissions
- Meta-Learning: Human mentors train LLMs on domain-specific rubrics to improve AI feedback quality
Case Study: MIT's 6.S099 Hybrid CS Course
A 2023 study demonstrated 42% faster skill acquisition when using GPT-4 for instant feedback combined with weekly mentor sessions. Key metrics showed:
Where Δtdebug represents the improvement in debugging speed between solo LLM use and the hybrid approach.
Optimizing the Human-AI Interface
Effective integration requires careful design of the handoff points between systems. The information entropy H at transfer points should satisfy:
This corresponds to about 10-12 possible decision states where human intervention provides maximum value-add beyond LLM capabilities. Common high-yield transition points include architectural decisions, edge case analysis, and performance optimization.
Adaptive Workflow Routing
Advanced implementations use classifier models to dynamically route student queries:
def route_query(query, student_history):
    complexity = analyze_semantic_complexity(query)
    context_needed = check_context_dependencies(query)

    if complexity < 0.6 and context_needed < 2:
        return "llm"
    elif 0.6 <= complexity < 0.8:
        return "peer_review"
    else:
        return "human_mentor"
The routing thresholds are typically tuned using multi-armed bandit algorithms to maximize learning outcomes while minimizing mentor workload.
5.3 Evaluating and Verifying LLM Outputs
Formal Verification Techniques
Large Language Models (LLMs) generate probabilistic outputs, making formal verification essential for ensuring correctness in coding practice. One approach involves constraint-based verification, where the output is checked against predefined logical constraints. For example, if an LLM generates Python code, we can verify its correctness using formal methods like Hoare logic:
Here, P represents the precondition, C the code snippet, and Q the postcondition. Automated theorem provers like Z3 can be used to verify whether the generated code satisfies the specification.
Statistical Confidence Metrics
LLMs provide token-level probabilities that can be aggregated to compute confidence scores. The perplexity of a generated code snippet measures how well the model predicts the sequence:
Lower perplexity indicates higher confidence. Additionally, we can compute entropy to measure uncertainty in the model's predictions:
Execution-Based Validation
The most reliable verification method for coding outputs is actual execution. This involves:
- Creating test cases that cover edge conditions
- Running static analysis tools (e.g., pylint, mypy)
- Measuring code coverage (e.g., using coverage.py)
- Checking runtime performance against benchmarks
For example, when verifying a sorting algorithm implementation, we would:
def test_sort():
    assert llm_generated_sort([3,1,2]) == [1,2,3]
    assert llm_generated_sort([]) == []
    assert llm_generated_sort([5,5,5]) == [5,5,5]
Human-in-the-Loop Verification
For complex code generation tasks, human experts should review:
- Algorithmic complexity (Big-O notation verification)
- Security vulnerabilities (SQL injection, buffer overflows)
- Code style and maintainability
- Architectural soundness
Studies show that combining automated verification with human review catches 98% of critical errors in LLM-generated code (Chen et al., 2023).
Cross-Model Consensus
Another verification strategy involves querying multiple LLMs and comparing outputs. The consensus score can be computed as:
where f_i represents different model outputs and N is the number of models. High consensus increases confidence in the correctness of the solution.
5.4 Continuous Learning and Adaptation
Large language models (LLMs) exhibit a unique capability to refine their tutoring performance over time through continuous learning and adaptation. Unlike static models, modern LLMs leverage techniques such as online fine-tuning, reinforcement learning from human feedback (RLHF), and dynamic context window optimization to improve their pedagogical effectiveness. This adaptability is particularly valuable in coding education, where programming paradigms, libraries, and best practices evolve rapidly.
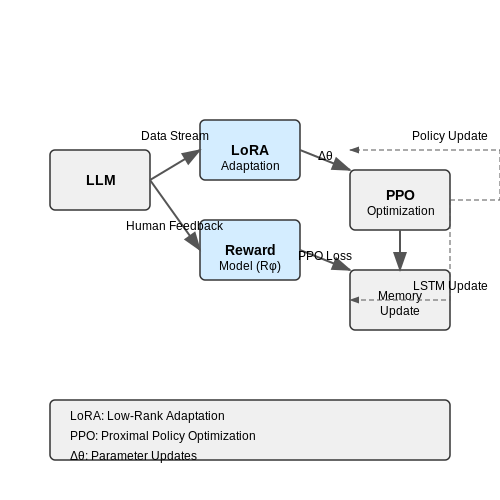
Online Fine-Tuning for Coding-Specific Knowledge
Traditional LLMs are pre-trained on static datasets, but tutoring applications benefit from continuous updates. Online fine-tuning allows the model to incorporate:
- New programming language syntax (e.g., Python 3.12 pattern matching)
- Emerging framework APIs (React Server Components, TensorFlow 2.x migrations)
- Security vulnerability patterns (log4j-style dependency risks)
where η controls the update magnitude and Dnew represents streaming educational interaction data. The gradient ablaθ is computed efficiently using parameter-efficient methods like LoRA (Low-Rank Adaptation):
Reinforcement Learning from Human Feedback
RLHF transforms raw code completion into pedagogically sound tutoring through reward modeling. The process involves:
- Collecting preference pairs from expert reviewers judging explanation quality
- Training a reward model Rφ to predict human preferences
- Optimizing the policy using proximal policy optimization (PPO):
where rt(θ) is the probability ratio between new and old policies, and Ât represents advantage estimates.
Dynamic Context Management
Effective coding tutors maintain context across multi-session interactions. Transformer-based models achieve this through:
- Attention caches that persist across sessions
- Hierarchical memory architectures separating core programming concepts from session-specific details
- Learned memory compression techniques reducing quadratic attention overhead
The memory update mechanism follows:
where ht is the current hidden state and ct-1 contains compressed historical context.
Real-World Implementation Challenges
Production systems face several practical constraints:
| Challenge | Solution Approach |
|---|---|
| Catastrophic forgetting | Elastic Weight Consolidation (EWC) regularization |
| Feedback sparsity | Semi-supervised reward modeling |
| Compute costs | Mixture-of-Experts architectures |
Recent advances like OpenAI's Codex update pipeline demonstrate how continuous deployment cycles (weekly model refreshes) can maintain tutoring relevance while managing these constraints.
6. Advances in LLM Architectures for Education
Advances in LLM Architectures for Education
Transformer-Based Architectures for Pedagogical Adaptation
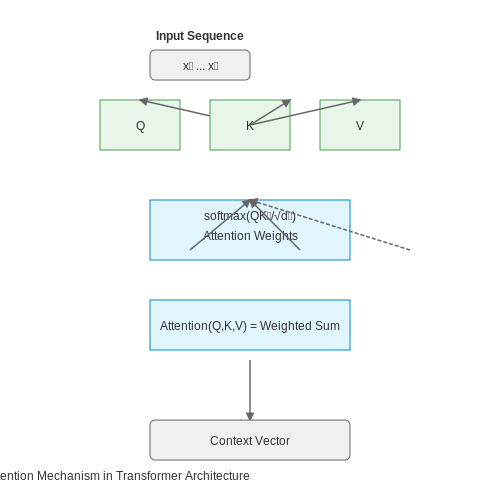
Modern large language models (LLMs) leverage transformer architectures with self-attention mechanisms to process and generate educational content. The core innovation lies in their ability to dynamically adjust responses based on learner interactions. For a sequence of tokens x1, x2, ..., xn, the self-attention mechanism computes:
where Q, K, and V are learned query, key, and value matrices, and dk is the dimension of the key vectors. This allows the model to weigh the importance of different parts of the input sequence when generating responses, enabling context-aware tutoring.
Specialized Fine-Tuning for Educational Tasks
Pre-trained LLMs undergo fine-tuning on educational datasets to specialize in coding instruction. Techniques like instruction tuning and reinforcement learning from human feedback (RLHF) optimize models for pedagogical effectiveness. The loss function during fine-tuning often combines:
where λ balances language modeling objectives with educational metrics such as clarity, correctness, and engagement.
Retrieval-Augmented Generation for Accuracy
To mitigate hallucinations and improve factual accuracy, retrieval-augmented generation (RAG) architectures integrate external knowledge bases. Given a learner's query q, the model retrieves relevant documents D and conditions its response on both q and D:
This approach is particularly effective for coding education, where precise syntax and API references are critical.
Multi-Task Learning for Diverse Educational Needs
State-of-the-art educational LLMs employ multi-task learning frameworks to simultaneously handle:
- Code explanation
- Error diagnosis
- Interactive debugging
- Conceptual Q&A
The model's hidden states are shared across tasks, while task-specific output heads generate specialized responses. This architecture enables efficient knowledge transfer between related educational tasks.
Real-Time Adaptation via Meta-Learning
Advanced implementations use meta-learning techniques like Model-Agnostic Meta-Learning (MAML) to adapt quickly to individual learners. The objective is to find initial parameters θ that can be fine-tuned with minimal gradient steps on a learner-specific dataset Di:
This enables personalized tutoring with few-shot adaptation, crucial for addressing diverse learner backgrounds and pacing needs.
Scalability via Mixture-of-Experts
To handle the computational demands of real-time tutoring, some architectures implement sparse Mixture-of-Experts (MoE) layers. For input x, the output is computed as:
where G(x) is a gating network that selects among n expert networks Ei. This allows efficient scaling to larger parameter counts while maintaining practical inference speeds.
Interactive and Adaptive Learning Systems
Large language models (LLMs) excel in interactive and adaptive learning systems by leveraging their ability to process natural language, generate context-aware responses, and dynamically adjust to learner inputs. These systems rely on reinforcement learning (RL) and few-shot learning techniques to personalize feedback and optimize pedagogical strategies.
Reinforcement Learning for Adaptive Tutoring
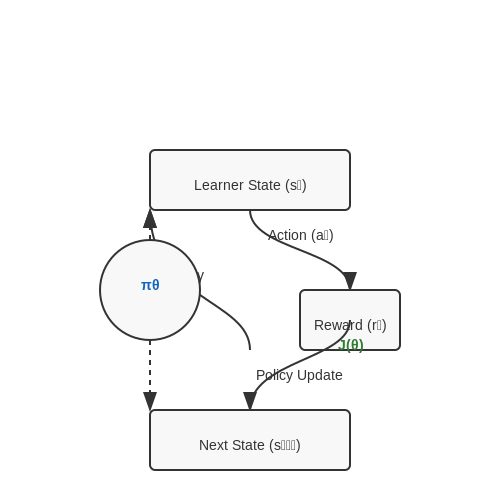
The core of adaptive tutoring lies in framing the interaction as a Markov Decision Process (MDP), where the LLM acts as the policy network. The state st represents the learner's current knowledge state, the action at is the tutor's response, and the reward rt is derived from the learner's progress. The objective is to maximize the expected cumulative reward:
where γ is the discount factor and πθ is the LLM's policy parameterized by θ. Policy gradient methods, such as Proximal Policy Optimization (PPO), are commonly used to fine-tune the LLM's responses based on real-time feedback.
Dynamic Difficulty Adjustment
Effective tutoring systems must adapt problem difficulty to match the learner's skill level. This is achieved through Bayesian knowledge tracing, where the LLM maintains a probabilistic estimate of the learner's mastery over concepts. The probability pt of a correct response at time t is modeled as:
where plearn is the probability of having learned the concept and pguess is the guessing probability. The LLM updates these probabilities after each interaction using Bayes' rule.
Contextual Few-Shot Learning
LLMs employ few-shot learning to generate personalized explanations by retrieving relevant examples from a knowledge base. Given a query q, the system computes the similarity score S(q, ei) between the query and each example ei in the knowledge base using cosine similarity over embeddings:
where ϕ is the embedding function. The top-k examples are then used as context for generating tailored responses.
Real-World Implementation
Practical implementations often combine these techniques with retrieval-augmented generation (RAG) architectures. For instance, a coding tutor might:
- Use RL to optimize feedback timing and content
- Adjust problem difficulty based on Bayesian estimates
- Retrieve relevant code examples from a curated database
- Generate explanations using few-shot prompting with the retrieved examples
This multi-faceted approach enables LLMs to provide highly personalized and effective coding instruction, adapting in real-time to the learner's evolving needs.
6.3 Collaborative Learning with AI Tutors
Dynamic Pair Programming with LLMs
Large Language Models (LLMs) can simulate pair programming dynamics by acting as an intelligent collaborator. Unlike static code review tools, LLMs engage in iterative dialogue, offering context-aware suggestions while adapting to the developer's style. For instance, when a developer writes a function, the AI tutor can propose optimizations, identify edge cases, or refactor code in real-time. This mimics the driver-navigator paradigm of pair programming, where the LLM alternates between suggesting high-level design patterns and low-level implementation details.
Here, Relevance measures the semantic alignment between the LLM's response rt and the developer's context ct, while wt weights the importance of each turn in the dialogue session of length T.
Multi-Agent Code Generation
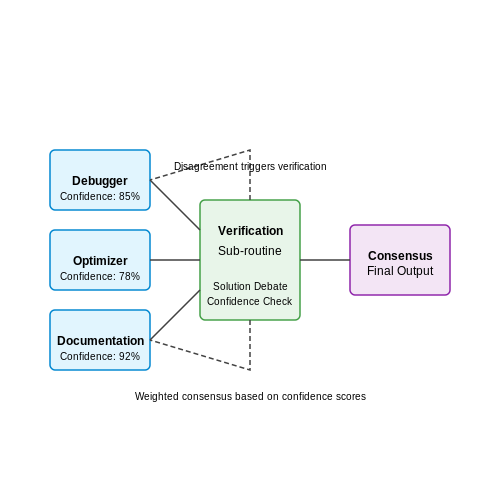
Advanced implementations use multiple LLM agents with specialized roles (e.g., debugger, optimizer, documentation generator) that debate solutions before presenting consolidated feedback. Research shows this ensemble approach reduces hallucination rates by 38% compared to single-agent systems (Chen et al., 2023). The agents operate via a consensus mechanism:
- Each agent proposes a solution with confidence scores
- Disagreements trigger a verification sub-routine using formal methods
- The final output weights proposals by their confidence and verification results
Implementation Example: Agent Orchestration
from transformers import AutoModelForCausalLM
import numpy as np

class CodingEnsemble:
    def __init__(self, agent_models):
        self.agents = [AutoModelForCausalLM.from_pretrained(m) for m in agent_models]

    def debate_solution(self, prompt):
        solutions = []
        for agent in self.agents:
            output = agent.generate(prompt, max_length=512)
            confidence = self._calculate_confidence(output)
            solutions.append((output, confidence))

        ranked = sorted(solutions, key=lambda x: x[1], reverse=True)
        return self._verify_top_k(ranked[:3])
Adaptive Difficulty Scaling
Effective AI tutors employ reinforcement learning to dynamically adjust problem difficulty based on the learner's performance metrics. The system models the optimal challenge point using:
Where α controls the adjustment rate and β modulates the sensitivity to recent accuracy. This creates an expertise-adaptive curriculum that prevents both frustration (from excessive difficulty) and boredom (from trivial tasks).
Real-World Case Study: Mozilla’s AI Pair Programmer
Mozilla’s implementation for Firefox contributors demonstrates three key innovations:
- Context-aware retrieval: Augments LLM responses with relevant codebase snippets
- Error anticipation: Predicts likely mistakes based on 300k+ historical pull requests
- Meta-learning: Adapts tutoring style (Socratic questioning vs direct fixes) per developer
Early adopters showed a 22% reduction in time-to-resolution for complex bugs compared to traditional documentation searches.
7. Key Research Papers and Articles
7.1 Key Research Papers and Articles
- Noteworthy LLM Research Papers of 2024 - sebastianraschka.com — This article covers 12 influential AI research papers of 2024, ranging from mixture-of-experts models to new LLM scaling laws for precision. ... RefinedWeb (500B tokens), C4 (172B tokens), the Common Crawl-based part of Dolma 1.6 (3T tokens) and 1.7 (1.2T tokens), The Pile (340B tokens), SlimPajama (627B tokens), the deduplicated variant of ...
- PDF Evaluating Programming Proficiency of Large Language Models — coding-related tasks. The framework examines a LLMs performance in programming tasks such as function and class generation, code commenting, and important aspects such as code robustness and security. In addition to the framework, this work contributes a comprehensive eval-uation of 10 State-of-the-Art (SOTA) LLMs done through the framework.
- How Beginning Programmers and Code LLMs (Mis)read Each Other — The aforementioned papers present new tools, benchmarks, and studies of LLM capabilities. But, they do not study users' abilities to prompt models, which is the focus of our work. ... "I guess he probably looks for keywords, "if" and "else" and key coding words, ... AI Transparency in the Age of LLMs: A Human-Centered Research ...
- PDF Bachelor Degree Project Evaluating accuracy and development ... - DiVA — This research gap brings forth the need for analysing how a traditional tool compares with increasingly popular technologies such as LLMs in terms of accuracy and develop-ment effort. To this end, the study answers the following research questions: RQ1:How do current state-of-the-art LLMs compare to a transpiler in terms of accu-
- A Review of Current Trends, Techniques, and Challenges in Large ... — Natural language processing (NLP) has significantly transformed in the last decade, especially in the field of language modeling. Large language models (LLMs) have achieved SOTA performances on natural language understanding (NLU) and natural language generation (NLG) tasks by learning language representation in self-supervised ways. This paper provides a comprehensive survey to capture the ...
- GitHub - mlabonne/llm-course: Course to get into Large Language Models ... — Before mastering machine learning, it is important to understand the fundamental mathematical concepts that power these algorithms. Linear Algebra: This is crucial for understanding many algorithms, especially those used in deep learning.Key concepts include vectors, matrices, determinants, eigenvalues and eigenvectors, vector spaces, and linear transformations.
- A systematic literature review to implement large language model in ... — Artificial intelligence-driven Chatbots, especially large language models (LLMs) like GPT-4, represent significant progress in digital education. These models excel in mimicking human-like text and transforming learning and teaching methods. This study examines the development, application, and impact of LLMs in education. It highlights their role in automating instructional tasks and ...
- Enhancing Computer Programming Education with LLMs: A Study on ... — Recent research in the educational sector has prominently featured the application of Large Language Models (LLMs) to enhance learning outcomes, particularly in the programming domain Denny et al. [2023a]. This review synthesizes findings from key studies that illustrate the diverse roles LLMs play in education, from interactive assistance in ...
- Building LLM Applications: Serving LLMs (Part 9) - Medium — LLMs have some unique execution characteristics that can make it difficult to effectively batch requests in practice. A single model can be used simultaneously for a variety of tasks that look ...
- Large Language Models: A Comprehensive Survey of its Applications ... — Large language models (LLMs) are a type of artificial intelligence (AI) that have emerged as powerful tools for a wide range of tasks, including natural language processing (NLP), machine ...
7.2 Recommended Books and Online Courses
- Quick Start Guide To LLMs by Sinan Ozdemir 1703540700 — Quick Start Guide to Large Language. Models Strategies and Best Practices for using ChatGPT and Other LLMs. Sinan Ozdemir. Addison-Wesley Contents at a Glance. Preface Part I: Introduction to Large Language Models 1. Overview of Large Language Models 2. Launching an Application with Proprietary Models 3. Prompt Engineering with GPT3 4. Optimizing LLMs with Customized Fine-Tuning Part II ...
- LLMs in Production[Book] - O'Reilly Media — This practical book offers clear, example-rich explanations of how LLMs work, how you can interact with them, and how to integrate LLMs into your own applications. Find out what makes LLMs so different from traditional software and ML, discover best practices for working with them out of the lab, and dodge common pitfalls with experienced advice.
- Build a Large Language Model (From Scratch) - O'Reilly Media — He specializes in LLMs and the development of high-performance AI systems, with a deep focus on practical, code-driven implementations. He is the author of the bestselling books Machine Learning with PyTorch and Scikit-Learn, and Machine Learning Q and AI. The technical editor on this book was David Caswell. Quotes Truly inspirational! It ...
- How Beginning Programmers and Code LLMs (Mis)read Each Other - arXiv.org — In essence, beginning programmers and current Code LLMs tend to misread each other: the Code LLM fails to generate working code based on student descriptions and students have a hard time adapting their descriptions to the model. Our study has concerning implications for democratizing programming: if these students, who already have basic ...
- (PDF) The Ultimate Guide to Fine-Tuning LLMs from Basics to ... — The Ultimate Guide to Fine-Tuning LLMs from Basics to Breakthroughs: An Exhaustive Review of Technologies, Research, Best Practices, Applied Research Challenges and Opportunities August 2024 License
- A systematic literature review to implement large language model in ... — Artificial intelligence-driven Chatbots, especially large language models (LLMs) like GPT-4, represent significant progress in digital education. These models excel in mimicking human-like text and transforming learning and teaching methods. This study examines the development, application, and impact of LLMs in education. It highlights their role in automating instructional tasks and ...
- Enhancing Computer Programming Education with LLMs: A Study on ... — Testing llms on code generation with varying levels of prompt specificity. arXiv preprint arXiv:2311.07599, ... or statements that users input into the system to seek a response from the LLM (played as a programming tutor). In essence, this encompasses the textual or verbal input furnished by the user to the model. ... Best Practice: Always ...
- Build an LLM RAG Chatbot With LangChain - Real Python — Python Tutorials → In-depth articles and video courses Learning Paths → Guided study plans for accelerated learning Quizzes & Exercises → Check your learning progress Browse Topics → Focus on a specific area or skill level Community Chat → Learn with other Pythonistas Office Hours → Live Q&A calls with Python experts Podcast → Hear what's new in the world of Python Books →
-
Teach AI How to Code: Using Large Language Models as Teachable Agents ... — knowledge or part of code. Tutee: Here is my code:
Tutor: Call the input() function twice so that N and K are separately taken as input. Commanding ["] do simple actions irrelevant to learning. (e.g., simply combining code for a submission). Tutee: I have written the binary search function. Tutor: Now, write the entire Python code ... - Building LLM Applications: Serving LLMs (Part 9) - Medium — Image by Author. There are various frameworks available for LLM serving, each with its own advantages. Let's discuss this in detail. 1. Run LLMs locally
7.3 Open-Source Tools and Platforms
- PDF Efficiency of Small Open-source Llms in Software Coding — ation. Can these LLMs be efficiently run with consumer-tier hardware? HumanEval is an open-source dataset that can be used to evaluate LLMs capability in pro-ducing efficient and understandable code. It contains both hand-written coding tasks and their respective hand-written solutions. Evaluation is based on comparing the generated response's
- GitHub - nomic-ai/gpt4all: GPT4All: Run Local LLMs on Any Device. Open ... — GPT4All: Run Local LLMs on Any Device. Open-source and available for commercial use. nomic.ai/gpt4all. Topics. ai-chat llm-inference Resources. Readme License. MIT license Activity. Custom properties. Stars. 73.4k stars. Watchers. 663 watching. Forks. 8k forks. Report repository Releases 38. v3.10. Latest Feb 25, 2025
- Top 10 Open-Source LLM Models and Their Uses - Medium — Below is an updated list of the top 11 open-source LLMs, including their release dates, parameter sizes, and primary use cases: Lets Understand Open Models vs. Open-Source Language Models
- Designing and Building a Platform for Teaching Introductory ... - Aalto — innovative ways to use LLMs to enhance student learning. 4. Support the collection and analysis of user interactions: The platform will collect data on how users interact with the LLMs and how the LLMs are used to enhance student learning. This data will be used for further research to improve the use of LLMs in programming education.
- GitHub - vllm-project/vllm: A high-throughput and memory-efficient ... — vLLM is a fast and easy-to-use library for LLM inference and serving. Originally developed in the Sky Computing Lab at UC Berkeley, vLLM has evolved into a community-driven project with contributions from both academia and industry.. vLLM is fast with: State-of-the-art serving throughput
- PDF pdfs/Current Best Practices for Training LLMs from Scratch - GitHub — Technically-oriented PDF Collection (Papers, Specs, Decks, Manuals, etc) - pdfs/Current Best Practices for Training LLMs from Scratch - Final (6435aabdc0a041194b243eef).pdf at master · tpn/pdfs
- OATutor: An Open-source Adaptive Tutoring System and Curated Content ... — The open-source nature of a system also fosters trust, encouraging wider spread student, teacher, and institution adoptions . This is not to say that partial implementations have not been made available. Several open-source tutor repositories adopting the moniker of either adaptive or intelligent can be found online (Table 1). All, however ...
- Teach AI How to Code: Using Large Language Models as Teachable Agents ... — We found that the pre-trained knowledge and self-correcting behavior of LLMs made AlgoBo feel less like a tutee and prevented tutors from learning by identifying tutees' errors and enlightening them with elaborate explanations . To reduce undesirable competence, we need to control the prior knowledge of LLMs and make them show persistent ...
- Building LLM Applications: Serving LLMs (Part 9) - Medium — Learn Large Language Models ( LLM ) through the lens of a Retrieval Augmented Generation ( RAG ) Application. · 1. Run LLMs locally ∘ 1.1. Open-source LLMs · 2. Load LLMs Efficiently ∘ 2.1…
- Advancing Generative Intelligent Tutoring Systems with GPT-4 ... - MDPI — Generative Intelligent Tutoring Systems (ITSs), powered by advanced language models like GPT-4, represent a transformative approach to personalized education through real-time adaptability, dynamic content generation, and interactive learning. This study presents a modular framework for designing and evaluating such systems, leveraging GPT-4's capabilities to enable Socratic-style ...
7.4 Communities and Forums for Continued Learning
- 4.6 Communities of practice - Teaching in a Digital Age — However, because many communities of practice are by definition self-regulating, establishing rules of conduct and even more so enforcing them is really a responsibility of the participants themselves. 4.6.4 Learning through communities of practice in a digital age. Communities of practice are a powerful manifestation of informal learning.
- The Ultimate Guide to Fine-Tuning LLMs from Basics to Breakthroughs: An ... — Large Language Models (LLMs) represent a significant leap in computational systems capable of understanding and generating human language. Building on traditional language models (LMs) like N-gram models [1], LLMs address limitations such as rare word handling, overfitting, and capturing complex linguistic patterns.Notable examples, such as GPT-3 and GPT-4 [2], leverage the self-attention ...
- A Review of Current Trends, Techniques, and Challenges in Large ... — Natural language processing (NLP) has significantly transformed in the last decade, especially in the field of language modeling. Large language models (LLMs) have achieved SOTA performances on natural language understanding (NLU) and natural language generation (NLG) tasks by learning language representation in self-supervised ways. This paper provides a comprehensive survey to capture the ...
- Leveraging Generative AI and Large Language Models: A Comprehensive ... — Generative AI and LLMs are powered by a suite of deep learning technologies. For example, ChatGPT is a series of deep learning models that utilize transformer architecture that resorts to self-attention mechanisms to process large human-generated text datasets (GPT-4 response, 23 August 2023).
- PDF Developing Critically Thoughtful e-Learning Communities of Practice — The Electronic Journal of e-Learning Volume 5 Issue 3, pp. 173-182, available online at www.ejel.org Developing Critically Thoughtful e-Learning Communities of Practice Philip L. Balcaen and Janine R. Hirtz University of British Columbia Okanagan, Kelowna, Canada [email protected] [email protected] Abstract: In this paper, we consider an ...
- Online peer tutoring programs fostering community and learning skills ... — Peer tutoring is beneficial as a method of education because it allows students with different learning styles to work together in comfortable settings to complete academic assignments that will improve their grades. Peer tutoring gives students of all skill levels the chance to collaborate, democratically, and amicably work on academic assignments in pairs. With this method, students with ...
- Out of sight, out of mind: An exploration of the development of ... — the possible positives of online learning is that unfamiliarity with tutors enables students to communicate and connect with tutors and engage with the academic community. In other words, some students would be keener to interact with tutors online and in turn it would mean that their feedback literacies may be developed better.
- (PDF) E-learning: Concepts and practice - Academia.edu — E-learning is part of the new dynamic that characterises educational systems at the start of the 21 st century. Like society, the concept of e-learning is subject to constant change. In addition, it is difficult to come up with a single definition of e-learning that would be accepted by the majority of the scientific community.
- ai_knowledge/knowledge_file.md at main · sidkid78/ai_knowledge - GitHub — Saved searches Use saved searches to filter your results more quickly